Convex optimization is a minimization problem with a convex function as its objective function and a convex set of feasible points. For a finite-valued , the problem is to find with for every . The displayed infimum describes its value even when no minimizing point exists. The two convexity requirements concern different objects: the allowed decisions and the scores assigned to them.
A convex set contains the whole line segment between any two of its points:A convex function lies below the interpolation of its endpoint values:Thus mixing two allowed decisions preserves feasibility, and the mixed score is no worse than the same mixture of endpoint scores. The objective function may have flat regions or corners. For a strictly convex function, the second inequality is strict when and .
A useful constraint representation iswhere are convex functions on a common convex set , and the equalities are affine functions. Each inequality defines a convex sublevel set; their intersection with and the equality set is a convex set. An equality involving a general convex function need not preserve this geometry: allows and but excludes their midpoint . See Boyd and Vandenberghe, Convex Optimization (2004), §4.2.1 for the standard problem form.
Why local information can certify a global answer. Every local minimum of a convex optimization problem is a global minimum, including minima on the boundary. If a feasible point had , points would remain feasible and have value strictly below for every . Taking arbitrarily small contradicts a local minimum at . This argument explains the special power of convexity: a better distant decision would reveal an improving direction immediately nearby.
If a minimizer exists and the objective function is strictly convex on , it is unique. Two distinct minimizers of value would have a feasible midpoint with value strictly below . Existence is a separate question: the exponential function is strictly convex on , but its infimum is approached only as . Even a bounded convex set need not suffice: on also has unattained infimum . A continuous function on a nonempty compact set attains its minimum by the extreme value theorem.
Nor does strict convexity imply differentiability. For , the squared term gives the strict inequality while the triangle inequality gives the weak inequality for the absolute value. At zero the left and right derivatives are and , so no derivative exists there, although zero is the unique minimizer. Such objectives require subgradients or proximal operators rather than an ordinary gradient at every point.
For a differentiable convex function on an open convex set containing , the constrained first-order condition isIndeed, the subgradient inequality makes this sufficient; taking the one-sided derivative along feasible line segments makes it necessary. At an interior minimizer, both directions are feasible and the gradient must vanish. At a boundary minimizer it can be nonzero: it only needs to make every feasible direction nondecreasing. See Boyd and Vandenberghe, §§3.1.3 and 4.2.3.
A fully computed nearest-point problem. Project onto the half-space by minimizing half the squared Euclidean distance:The Hessian matrix is the identity matrix, so the objective function is strictly convex. The unconstrained minimizer violates the inequality. With the convention , the optimization Lagrangian is , where the Lagrange multiplier satisfies . Its Karush-Kuhn-Tucker conditions areThe last two equations give , . The choice is infeasible, so complementary slackness forces . Consequently , giving , and . The Euclidean distance is , rather than the objective function value . The gradient at the answer balances ; the displacement from to is a normal vector to the boundary.
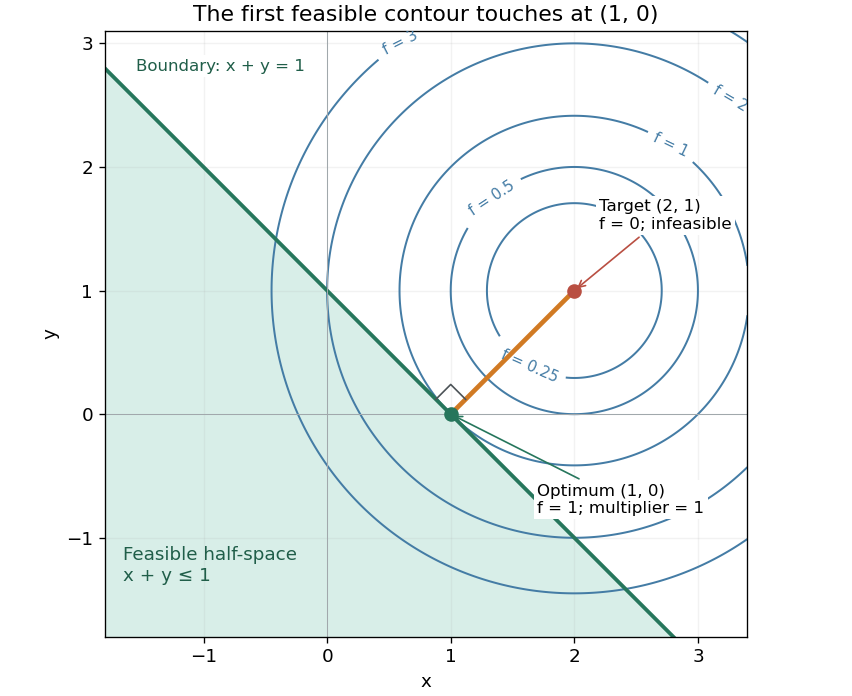

There is an exact certificate independent of numerical search. Completing squares givesFor every feasible point, implies . Thus every feasible objective is at least , and attains this bound. More generally the Lagrangian dual problem has objective for . Its maximum is also , illustrating strong duality through matching computed bounds. This makes the example a model for Euclidean projection onto a convex set and the projection step in projected gradient descent.
What the multiplier conditions require. For differentiable convex functions on an open convex set and equalities defined by affine functions, the KKT conditions combine feasibility, , complementary slackness , and stationaritywith unrestricted equality Lagrange multipliers . They suffice to certify a global minimum without an additional regularity assumption: the optimization Lagrangian is convex, stationarity minimizes it, and feasibility with complementary slackness gives the same certificate as above. To guarantee their necessity at an attained finite optimum, a regularity hypothesis suffices: Slater's condition requires some with and . The projection example has the strictly feasible point . See Boyd and Vandenberghe, §§5.2.3 and 5.5.3. This hypothesis guarantees suitable multipliers, not existence of a primal minimizer.
Without regularity, necessity can fail even for convex functions: minimize subject to . The sole feasible point is optimal, but stationarity would require . No Lagrange multiplier works. There is no strictly feasible point, and the gradient of the constraint vanishes at the answer.
The nonconvex contrast. The polynomial has derivative and second derivative . Numerically solving the cubic gives stationary points , , and . Their objective values are respectively , , and , with second derivatives , , and . Hence both outer points are local minima, and the middle point is a local maximum. Since at both ends, its global minimum exists and must be one of the stationary minima: it is the left one. A method stopping at the right local minimum misses a better value by approximately .
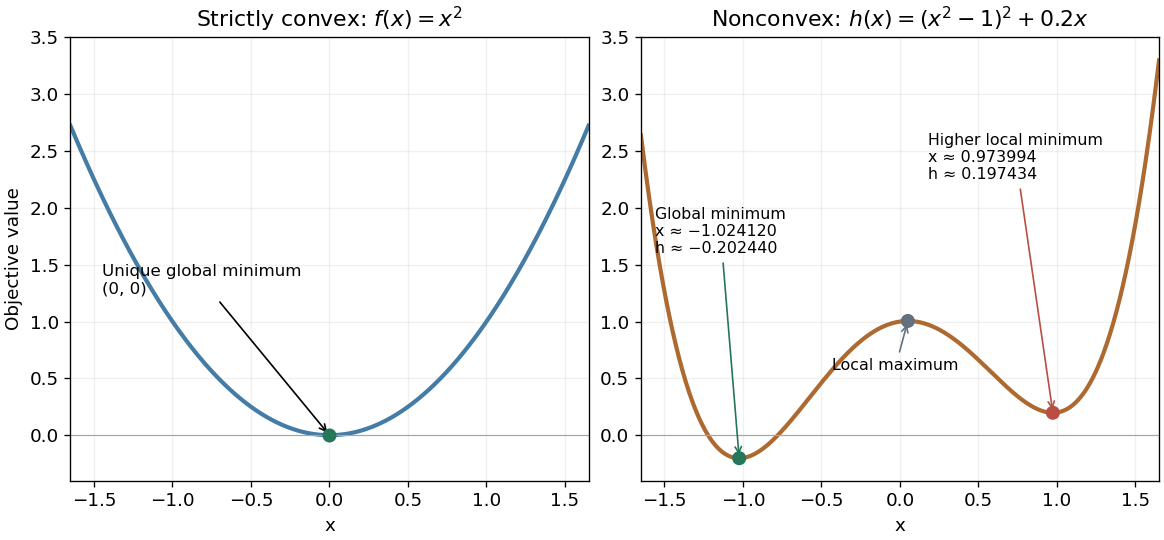
A strictly convex quadratic has one minimum; a tilted quartic has two local minima with different values
. Details. 
The practical appeal of convex optimization is the ability to check an answer globally using geometry and matching Lagrangian duality bounds. The projection certificate certifies every feasible alternative at once; the tilted quartic shows why a zero gradient alone cannot do that for general nonlinear optimization.
Historically, an early landmark is Kuhn and Tucker's [ref]
https://digicoll.lib.berkeley.edu/record/112776/files/math_s2_article-35.pdf. Nonlinear Programming, Second Berkeley Symposium (1951), pp. 481–492
. Its §3 explicitly states a regularity hypothesis for inequality-constrained Lagrange multipliers; its discussion of saddle points explains how concave functions support global conclusions for maximization. This documents an early formulation of the multiplier approach; it does not establish sole discovery of today's KKT conditions or of convex optimization as a whole.For positive existing stakes and budget , maximizing is equivalent to minimizing . A positive multiplier chosen so that gives the displayed allocation. Each coordinate minimizes on , which proves global optimality by Lagrangian sufficiency theorem. Its active set is ordered by . Zero existing stakes require a separate payoff convention and can cause nonattainment; the positive-stake formula should not be extended through undefined ratios.
A separation oracle either certifies that a supplied point belongs to a convex feasible set or returns a violated linear inequality whose half-space contains the whole feasible set. Its running time can be small even when the set has exponentially many defining inequalities. Together with rational encoding bounds and an outer bound, this permits polynomial time ellipsoid method feasibility and optimization.
After testing nonnegative edge coordinates and any explicit box or budget inequalities, treat those coordinates as lengths. A shortest path of length below one supplies a violated path inequality; a minimum length at least one certifies all path inequalities. If no source-to-target path exists, all those inequalities are vacuous. Thus a polynomial time shortest path problem calculation separates an exponentially constrained linear program.
For a saddle point problem , one update ordering isThe proximal operators treat both nonsmooth convex terms, while the extrapolation couples the primal and dual variables. The primal objective is , with the convex conjugate. A dual-first ordering is obtained by exchanging roles; consistent indexing is needed when comparing the formulas.
For proper lower semicontinuous convex functions on finite-dimensional Hilbert spaces, a nonempty saddle point set, and constant positive steps satisfying the displayed inequality, the primal-dual hybrid gradient method with extrapolation parameter one converges to a saddle point. The strict condition controls the bilinear coupling by the operator norm. It does not remove the need for existence of a saddle point. The fixed-step theorem and assumptions are recalled in Malitsky and Pock, A first-order primal-dual algorithm with linesearch, Section 1.
This is a proper convex function that has degree-one positive homogeneity, with . It need not be even or nonnegative; linear functionals are examples. Its subdifferential satisfiesThe two tests and prove equality; the subgradient inequality then gives the global upper bound. Conversely that bound and equality prove the subgradient condition. Hence a subgradient at also supports every nonnegative multiple of . Requiring gives an absolutely one-homogeneous functional.
A nonzero satisfying this relation, with , generalizes the eigenfunction of an absolutely one-homogeneous functional to the quadratic geometry induced by the forward map. Pairing with yields . With unit data norm it is a generalized singular vector. If , and the exact data are , the vector minimizes the quadratic variational regularization objective. Substitute its raywise subgradient into the subgradient optimality condition. Every minimizing branch has the same predicted data, and injectivity of gives equality of vectors. The Bregman distance along this ray is zero even though the reconstruction is shrunk. For nonnegative the branch continues as ; nonnegativity supplies for the threshold argument.
Background on these generalized singular vectors: Benning and Burger, Ground States and Singular Vectors of Convex Variational Regularization Methods.
Optimization of a linear function subject to affine constraints and membership in a closed convex cone. Choosing the positive semidefinite cone gives semidefinite programming; other choices include copositive optimization and completely positive optimization. Dual cones produce scalar-product bounds on feasible objectives.
For a real matrix and a vector , exactly one of the following systems has a solution:The linear inequalities here are componentwise. In the first system is nonnegative; in the second system is unrestricted in sign. The second system is a certificate that the first has no feasible point. This nonnegative-equations alternative is developed in Boyd and Vandenberghe, Convex Optimization slides, §5.34.
Build the target, or separate it. Write the columns of as . Then is a conic combination: its coefficients must be nonnegative, but need not sum to one. The obtainable targets form the finitely generated coneA solution explains how to build from those columns. A certificate instead defines a linear functional . The condition says that its dot product with every generating column is nonnegative, and hence with every point of . But places the target strictly on the other side of the hyperplane . Thus belongs to the dual cone of and rules out every allowed conic combination at once.
A certificate that can be checked by eye. Take the identity matrixHere is the nonnegative orthant. The equation forces , violating . The certificate givesThe linear functional simply reads the first coordinate: all allowed column combinations have a nonnegative first coordinate, while has first coordinate . For comparison, the target is obtained with .
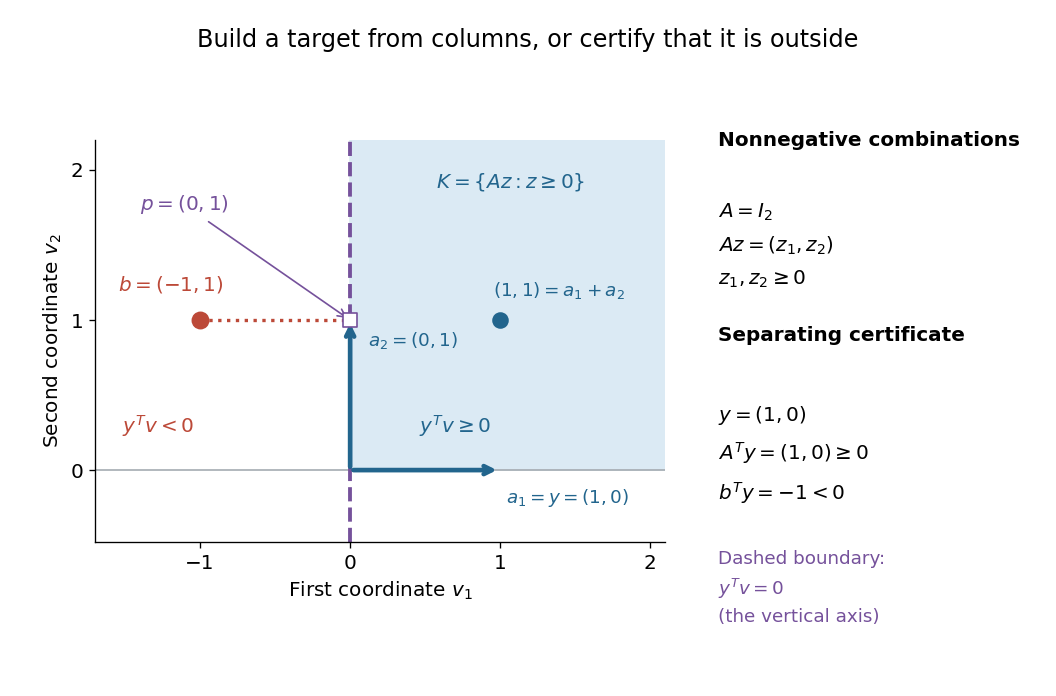

Why this is useful and striking. A successful search can exhibit one feasible point; an unsuccessful search alone cannot explain why every candidate fails. Farkas' lemma guarantees an equally concrete witness of impossibility for this finite linear problem. Once is supplied, verification needs only matrix multiplication, sign tests and one dot product. The same idea gives a Farkas certificate for linear inequalities and underlies linear programming duality.
Brief geometric proof. The two systems cannot both hold, because they would implyFor existence of a certificate when , closedness of finitely generated cones makes a closed convex cone, so separation from a closed convex cone supplies and for every . Testing each column gives . Concretely, let be the Euclidean projection onto a convex set of onto and set . The projection inequality gives for . Testing and gives , whence . In the example, and . Alternatively, the Fenchel-Moreau theorem applied to the cone's indicator functional proves the same separation through its polar cone.
An original historical source is Julius Farkas's [ref]
https://geodesic.mathdoc.fr/item/JRAM_1902__124_149129/. Theorie der einfachen Ungleichungen, Journal für die reine und angewandte Mathematik 124 (1902), pp. 1–27
. The linked archival record verifies the author, title and publication details.Suppose a linear program has a Farkas' lemma certificate , , . A purported feasible point of , would imply . Hence every relaxation below the displayed positive threshold remains infeasible. For rational inputs, bounds on the encoding length of a certificate supply the precision gap used by the ellipsoid method.
Let and . For unrestricted , the system of linear inequalities has no feasible point if and only if there is a vector withThe entries are nonnegative Lagrange multipliers for the rows. Multiplying inequalities by them preserves their direction; the condition cancels every variable, leaving the contradictionThis is a Farkas' lemma alternative for non-strict inequalities; no strict-feasibility assumption is needed. See Boyd and Vandenberghe, Convex Optimization (2004), §5.8.3, pp. 261–262.
Three individually possible requirements, jointly impossible. Suppose two unrestricted real coordinates , drawn as in the diagram, must satisfyWrite every row in the same direction:Then and . The nonnegative weighted sum, with Lagrange multipliers , is visiblyEach individual requirement defines a half-space in the plane. Even every pair has a feasible point: satisfies the first two, the first and third, and the second and third. Their common intersection is empty, because the first two force , while the third demands at most .
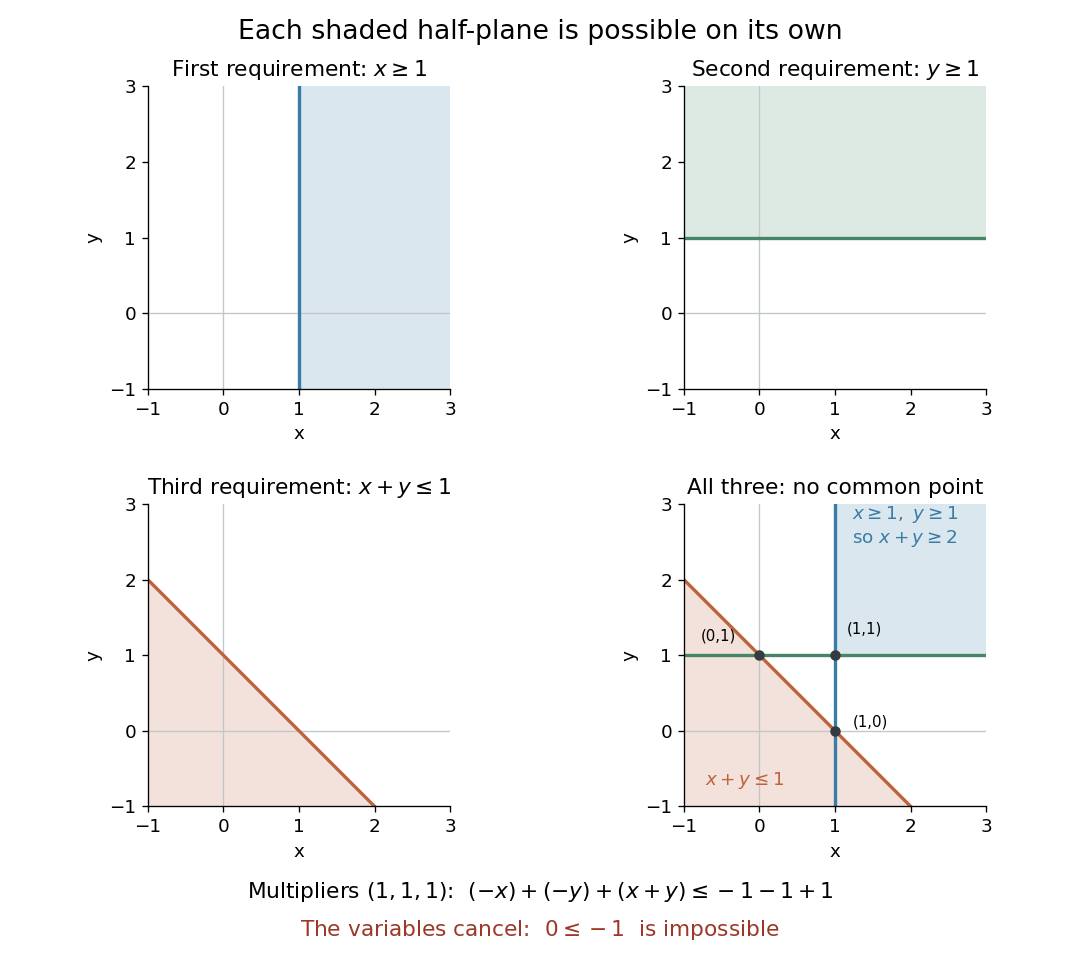

Why cancellation is necessary for unrestricted variables. A nonzero linear functional can be made arbitrarily positive or negative by varying unrestricted , so alone would not yield a contradiction. Equality is essential here. If is also imposed, the sufficient certificate becomes , , , because then . This is the sign convention used in robust infeasibility under uniform constraint relaxation. One can instead append the rows and use the equality certificate on the enlarged system. Reversing all constraints to reverses the scalar sign to , as in the normalized integer Farkas infeasibility gap.
Checking a solver's infeasibility claim. A returned Farkas certificate for linear inequalities gives a short verification procedure: compute and , and check the three displayed conditions against the original constraints. Any positive multiple is another certificate; division by normalizes to . With rational numbers as data and certificate, the tests can be exact. With floating-point arithmetic, a small residual is a diagnostic rather than an exact cancellation: unrestricted can amplify a nonzero residual without bound. A rigorous certificate therefore needs exact cancellation or justified error bounds and additional bounds on the variables. The strict negative scalar is the margin of contradiction.
The same weighted sums give dual bounds. For the linear program maximizing over unrestricted with , any satisfying givesfor every feasible point. Minimizing over these multipliers is the dual linear program; the bound itself is weak duality. For example, maximize subject to , , . The multipliers give the upper bound , attained at . The infeasibility example above uses the same row directions, but lower bounds of on both coordinates. Its multipliers cancel the objective function as well as the variables: with would bound zero by a negative number. Thus impossibility and linear programming optimality certificates use the same arithmetic. See Boyd and Vandenberghe, Convex Optimization slides, §§5.32–5.35 for infeasibility as a dual alternative.
Why every inconsistent system has such a certificate. Introduce a slack variable vector and write . Split the unrestricted vector as with . Applying Farkas' lemma to the column matrix gives , , and . The first two conditions together are exactly . This reduction explains both the equality and the nonnegative row multipliers.
Suppose have integer entries of absolute value at most , has columns, and is infeasible. A Farkas certificate for linear inequalities can be chosen with , , and the displayed lower bound. Normalize an infeasibility certificate to obtain the last equality, then maximize over the resulting compact linear polyhedron. A maximizing extreme point has at most positive entries: otherwise the augmented columns on its support would be dependent, allowing feasible perturbations in both directions. For its independent supported columns, select independent equations. Cramer's rule expresses the supported entries with a common nonzero integer determinant denominator. That determinant has absolute value at most . The positive value therefore has a positive integer numerator over a denominator of at most this size, proving the bound.
An interior-point method solves constrained mathematical optimization problems by maintaining variables in the interiors of their feasible cones or inequality domains. Barrier derivatives are defined there, and damped Newton methods keep subsequent iterates in their domains. A central path gives a family of barrier-regularized optima whose duality gap approaches zero; a conic phase-I problem can supply a strict feasible starting point.
A primal-dual interior-point method solves perturbed KKT conditions while updating both the primal variables and Lagrange multipliers. For inequalities written as , a logarithmic-barrier path has positive and perturbed complementarity . A Newton system for these coupled equations gives primal and dual corrections together, with damping to preserve positivity. This can avoid explicitly forming the most ill-conditioned eliminated barrier Hessian, although scaling and regularity still matter.
A barrier function penalizes approaching the boundary of a feasible set from its interior, typically diverging to there. An interior-point method minimizes the original objective function plus a positive multiple of this penalty, then reduces that multiple. The logarithmic barrier is the basic example for smooth inequality optimization constraints.
For optimization constraints and , the logarithmic barrier objective is on . Its derivatives are defined only on this strictly feasible open subset. One may extend its value to off to formulate an extended-real convex function. The penalty alone is , while includes the original objective function.
When is convex and each is concave, is a convex set andEvery term of this Hessian matrix is a positive semidefinite matrix, so is convex. Its critical point satisfies the stationarity part of the Karush-Kuhn-Tucker conditions with estimates and perturbed complementary slackness .
For symmetric , every nonzero stationary point of this barrier lies in a negative-eigenvalue eigenspace: , , . The origin is also stationary for every positive and must be considered separately. On a fixed nonzero branch, the Hessian has radial eigenvalue and transverse eigenvalues . A simple lowest negative eigenvalue gives a minimizing branch with a condition number growing as ; repeated lowest eigenvalues produce zero transverse curvature instead. Nevertheless the minimizing radius tends to one and the limiting vectors solve the constrained quadratic problem. The condition number measures numerical difficulty, not failure of the approximation principle.
Suppose strictly feasible stationary points of form a bounded sequence. Every cluster point satisfying the linear independence constraint qualification is a KKT point. Inactive multipliers tend to zero. The active gradients near the limit have uniformly bounded dual vectors, so pairing barrier stationarity with those vectors bounds the active multipliers. A convergent multiplier subsequence then gives stationarity, nonnegative multipliers and complementary slackness, since . A stationarity residual tending to zero is also allowed.
This conclusion is stationarity, not global optimality. If the subproblems are globally minimized and strictly feasible points are dense in the feasible set, any cluster point is instead a global minimizer. Compare each barrier minimum with a fixed strictly feasible point; boundedness near the cluster point bounds above. Taking the limit gives the objective comparison on strictly feasible points, then continuity and density extend it to all feasible points.
Let be concave and continuously differentiable, and let a strict feasible point satisfy . Suppose , , , and the logarithmic barrier residuals tend to zero, where . By concavity,The right-hand side is bounded when is continuous near . Thus the nonnegative Lagrange multiplier estimates are bounded. A convergent subsequence gives ; passing to the limit in stationarity and proves the Karush-Kuhn-Tucker conditions at . An inactive optimization constraint has and hence even without selecting a subsequence. With a convex objective function, these conditions certify a global minimum. This result is conditional on the stated residual and primal convergence assumptions; it does not assert that every barrier subproblem has a minimizer.
Near an active constraint with limiting Lagrange multiplier , a convergent barrier sequence has . Its Hessian matrix therefore contains the termFor a nonzero constraint gradient, this gives large curvature in a direction normal to the boundary. If a nonzero common tangent direction retains positive curvature of order one, while the remaining terms stay bounded, the condition number typically grows like . This is a mechanism rather than a universal rate: there may be no tangent direction, all curvatures may grow together, or an active constraint may have zero limiting Lagrange multiplier.
For a linear program and its dual linear program, write , , , and . Introduce , , and a free multiplier satisfyingThe point , , is strictly positive in all constrained coordinates. Multiplying the first three equations by respectively and adding gives the displayed identity. Minimizing has value zero: primal-dual optimal solutions or certificates from Farkas' lemma give zero- solutions after selecting positive and scaling. At , gives an optimal primal-dual pair by division by , while gives a primal infeasibility or dual infeasibility certificate. A point with is not decisive; choosing a relative interior point of the optimal face of a linear program avoids that degeneracy because the face contains a point with .
An auxiliary conic optimization problem searches for strict feasibility before following a central path. Given , minimizing subject to and has a strict feasible start for sufficiently large . Any feasible solution with certifies . If the original problem is strictly feasible, a small negative is feasible. Equality constraints and dual feasibility require their corresponding auxiliary procedures.
A convex three-times differentiable barrier is self-concordant whenA barrier of parameter additionally satisfies and diverges at the domain boundary. Logarithmically homogeneous cone barriers satisfy . The orthant barrier has parameter equal to the dimension, while the Lorentz-cone barrier on has parameter two. Their Hessians define Dikin ellipsoids and control interior Newton steps.
A cone barrier with this scaling law satisfies and . Therefore a central path with has primal-dual gap . A product of orthant and Lorentz cone canonical barriers adds their parameters.
For a logarithmically homogeneous barrier on a proper cone, the convex conjugate with reversed argument defines a barrier on the interior dual cone. The inverse gradient relation makes equivalent to . This gives a joint primal-dual central path without assuming the barrier is identical on a self-dual cone.
For a nondegenerate self-concordant barrier, the open local Hessian ballis contained in its barrier domain. This is the Dikin ellipsoid. It supplies a quantitative way to ensure that a damped Newton method stays interior, without relying on Euclidean distance to a possibly curved boundary.
For a strictly feasible primal-dual conic optimization problem and a logarithmically homogeneous barrier, the central path consists of solutionsThe primal-dual gap is . Existence requires appropriate feasibility and boundedness hypotheses, rather than merely a full-rank constraint matrix. Linearizing these equations gives a central-path Newton system.
At a target barrier parameter , let , , . The Newton direction solvesFull column rank of and a positive-definite barrier Hessian give a positive-definite reduced matrix. Backtracking must keep both cone variables interior; solving the linear equations alone does not guarantee that a full step stays inside the cones.
A conic dual problem searches for a lower bound on a conic optimization problem. A feasible point exhibits an attainable cost; a feasible dual variable explains why every allowed decision costs at least a specified amount. If the two costs agree, the pair certifies a global minimum without relying on how the points were found.
Fix a real matrix , vectors , , and a closed convex cone . With unrestricted , use the conventionwhere the dual cone is . The conic dual problem uses because it must turn every allowed slack variable into a nonnegative dot product. Taking gives componentwise linear inequalities; taking a second-order cone gives a Euclidean norm constraint. A self-dual cone has , but this equality does not guarantee a feasible point or strong duality.
The Lagrangian supplies a short derivation. For ,Its infimum over unrestricted is when , and otherwise. Maximizing the resulting Lagrange dual function gives the stated conic dual problem. The minus sign matches the convention .
Consider the original linear programOne unit of costs twice as much as one unit of , so is a plausible answer. To certify it, multiply the three linear inequalities by , respectively, and add:The proposed feasible point attains , so its cost is the global minimum.
In the conic dual problem convention, the data and certificate areDirect matrix multiplication gives and . At , the slack variable is , so . The first linear inequality has positive slack and zero multiplier; the two positively weighted linear inequalities are tight. This is complementary slackness.
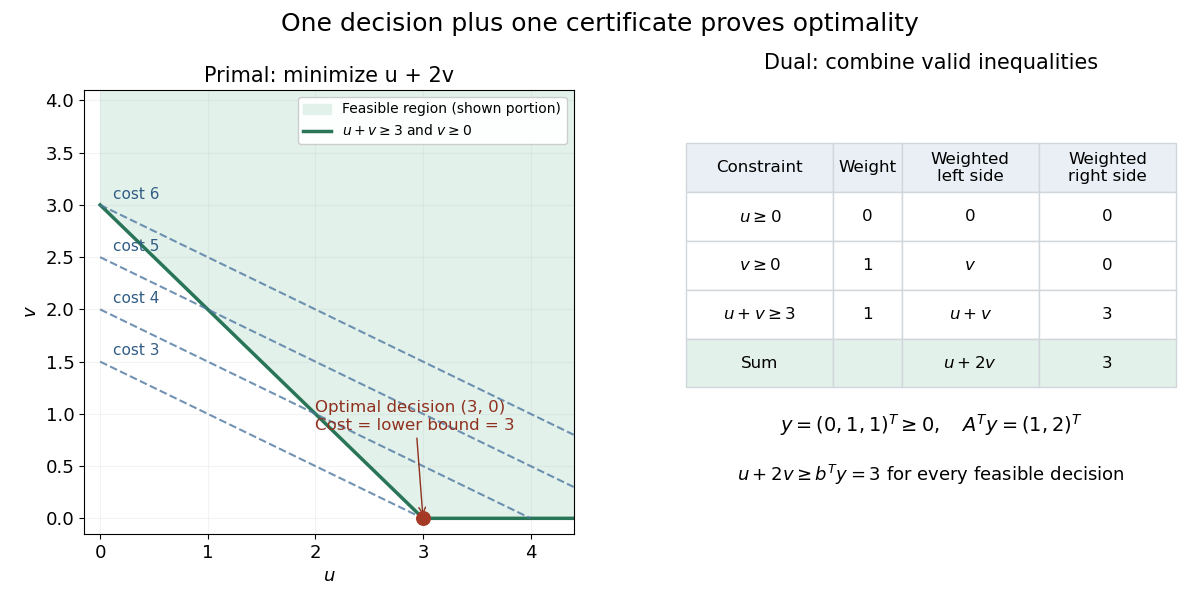

The entire dual feasible set can also be read off: write with . Then and . Maximizing this lower bound gives . A point such as is still a valid certificate of the weaker bound .
A curved feasible set can have the same certificate structure. ConsiderWrite and use the second-order cone . In this coordinate ordering,Self-duality of a second-order cone makes . The equality forces and , leaving . Its dual objective function is , maximized at . Thus every feasible point satisfies , and attains that bound: .
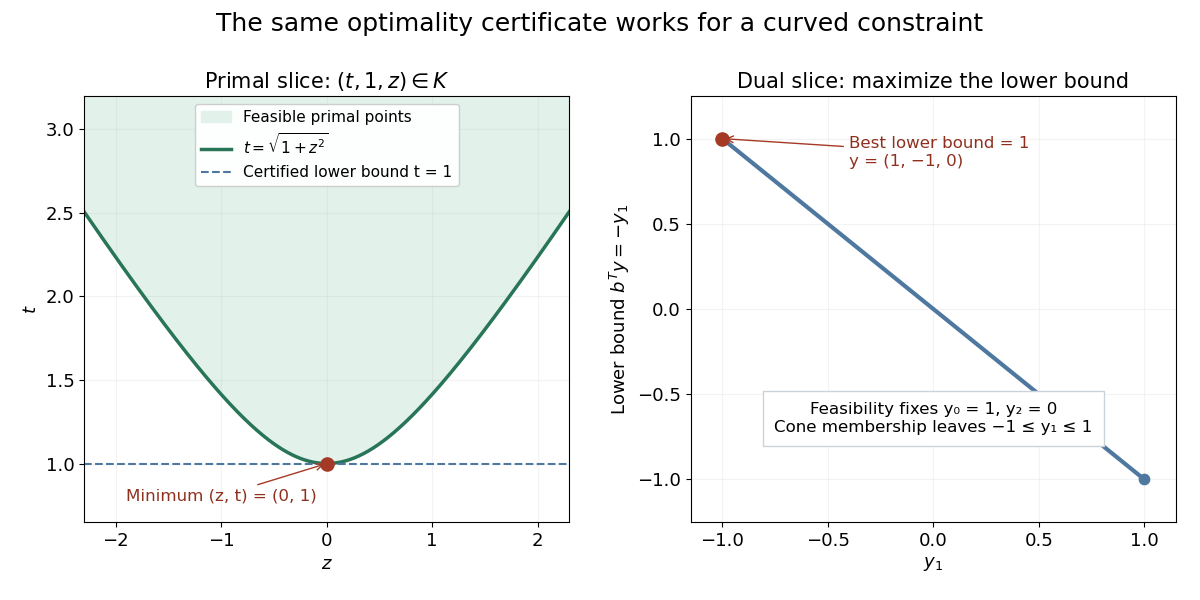
A curved primal constraint and an interval of dual certificates
. The left panel is the slice of the second-order cone, so its boundary is . The right panel is the dual slice , : admissible form , and reaches at . The optimal slack variable and dual variable lie on different cone boundary rays with zero dot product. Details.
The zero dot product is . Individual coordinate products need not be nonnegative here: the cancellation occurs across coordinates. The valid complementary slackness condition is cone-level orthogonality, rather than the coordinatewise interpretation of the nonnegative orthant.
For a feasible point and a feasible dual variable , weak duality follows from one identity:The inequality is the defining property of the dual cone. Every feasible pair therefore encloses the optimal objective function value:Both optima are finite when such a pair exists. Consequently,These are absolute cost bounds, rather than bounds on distance to an optimizing vector. Zero gap certifies both optima immediately. A small positive gap bounds the remaining improvement even if no strong duality theorem has been invoked.
For the nonnegative-orthant optimality certificate example, is feasible and costs . Pairing it with gives , so its cost exceeds the optimum by at most . Here the optimum is known to be , and the bound is exact. Pairing the same with the weaker certificate gives : a valid but less informative guarantee.
The identity assumes exact primal and dual feasibility. With a dual linear-system residual , it becomesThe second term has no guaranteed sign. Checking only a small linear-system residual and the cone dot product is insufficient when is large; a separate bound follows from the Cauchy-Schwarz inequality. Approximate cone membership likewise needs a quantified correction before claiming a certificate.
For an exact arithmetic example, minimize subject to . The point is optimal. A proposed multiplier is nonnegative and gives zero cone dot product because the slack is zero, but violates by . Its purported lower bound is , exceeding the optimum. The missing term explains the failure.
For a proper cone , suppose a point satisfies and is finite. This generalized Slater condition gives strong duality and attainment of the conic dual problem's optimum. It does not by itself assert primal attainment.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §5.9.1, printed p. 265: generalized Slater condition, strong duality and dual attainment
The two worked examples have strict primal points: has slack in the interior of the nonnegative orthant, and has slack in the interior of the second-order cone. Both optima were already certified by explicit feasible pairs. Slater's condition explains why a matching optimal dual variable can be expected under these hypotheses; checking a supplied zero-gap pair needs only weak duality.
Changing cone geometry preserves the bound mechanism. For a positive semidefinite cone, the dual cone pairing is the Frobenius inner product of two matrices. This connects the same certificate idea to semidefinite programming, while the central path uses strictly interior primal and dual points to approach vanishing gap.
In 1995, Lieven Vandenberghe and Stephen Boyd presented a primal-dual interior-point method for convex optimization with matrix inequalities. Their algorithmic study included exploiting problem structure and allowing incomplete conjugate gradient method solves within an iteration. This illustrates how the primal-dual viewpoint guides computation as well as checking a final answer.[ref]
A Primal-Dual Potential Reduction Method for Problems Involving Matrix Inequalities by Lieven Vandenberghe and Stephen Boyd. Publication record and authored abstract: A Primal-Dual Potential Reduction Method for Problems Involving Matrix Inequalities, Mathematical Programming, Series B, 69(1), 205–236 (1995)
Conic optimization using the completely positive cone. For a real symmetric matrix , the trace-normalized program minimizes a weighted average of nonnegative-unit-vector Rayleigh quotients. The weights are the squared norms of the factors in . Hence a minimizing rank-one factor attains the same value as the original orthant minimum.
Conic optimization using the copositive cone. The constraint supplies an exact reformulation of a Rayleigh quotient minimum on the nonnegative orthant. Exact conic formulation does not itself provide an efficient membership algorithm.
Let for a real symmetric matrix . Compactness gives attainment. Homogeneity shows is a copositive matrix exactly when , provingIts conic program dual is the trace-normalized completely positive optimization problem. A minimizing vector gives , which certifies equality and dual attainment directly. In general differs from the unrestricted smallest eigenvalue.
Robust optimization chooses a decision while accounting for every parameter in a prescribed uncertainty set. A worst-case maximization takes the form with the decision chosen before the uncertain parameter. With affine dependence on the uncertainty, the support function and linear programming duality often replace the inner optimization by explicit constraints.
Worst-case linear revenue over a polyhedral uncertainty set is optimized by the linear programHere is the probability simplex. Finite decisions are exactly its intersection with . If this intersection is empty, all decisions have worst-case value and the displayed linear program is infeasible; its supremum over the empty feasible set is also . Full column rank of suffices to make all simplex decisions finite.
A polyhedral uncertainty set is specified by finitely many linear inequalities. The displayed centered example is the inverse image of a box under a linear map. It is nonempty because it contains , and contains every line with . Consequently it need not be bounded when is rank deficient. Its supremum norm constraint is equivalent to .
Convex analysis studies convex sets and convex functions, including epigraphs, convex conjugates and subdifferentials.
An infimal convolution is the cheapest way to split a prescribed total between two costs. Suppose two activities contribute and to a required total , costing and . Their combined cost is optimized over all splits , rather than charging both activities for the entire total.
For proper extended-real functions on a real vector space , defineThe definition does not require convexity. An infinite cost forbids that contribution, as with an indicator functional of a constraint set. If no split has two finite costs, set ; if the costs of admissible splits are unbounded below, . Thus proper inputs need not produce a proper extended-real function. The notation denotes the same operation. See Parikh and Boyd, Proximal Algorithms, §3.1 for the standard convex analysis definition and its connection to the Moreau envelope.
An infimum is a best lower bound, whereas a minimum is a value realized by some split. Writing in place of requires an attaining pair . For convex functions, mixing two nearly optimal splits and applying convexity to each cost proves that their infimal convolution is convex whenever it is proper; one must use nearly optimal splits because exact minimizers need not exist. Its convex conjugate is whenever the extended real number arithmetic is well defined; see conjugate of an infimal convolution for the precise identity. This turns the optimization over splits into addition in the conjugate variables.
Two quadratic costs: share the load according to its price. Let and let the convex quadratic functions beFor fixed , eliminate . The derivative of the total cost is , so equal marginal costs giveThe cheaper activity receives more of a positive total: when and , . Completing the square gives an exact certificate for every competing split:Consequently the infimum is a unique minimum, andThe effective quadratic coefficient is , with . It is smaller than either or : allowing both activities reduces the cost compared with assigning everything to either one. If , each receives half the total and . This is a simple quadratic optimization problem whose answer preserves the form of the original costs.
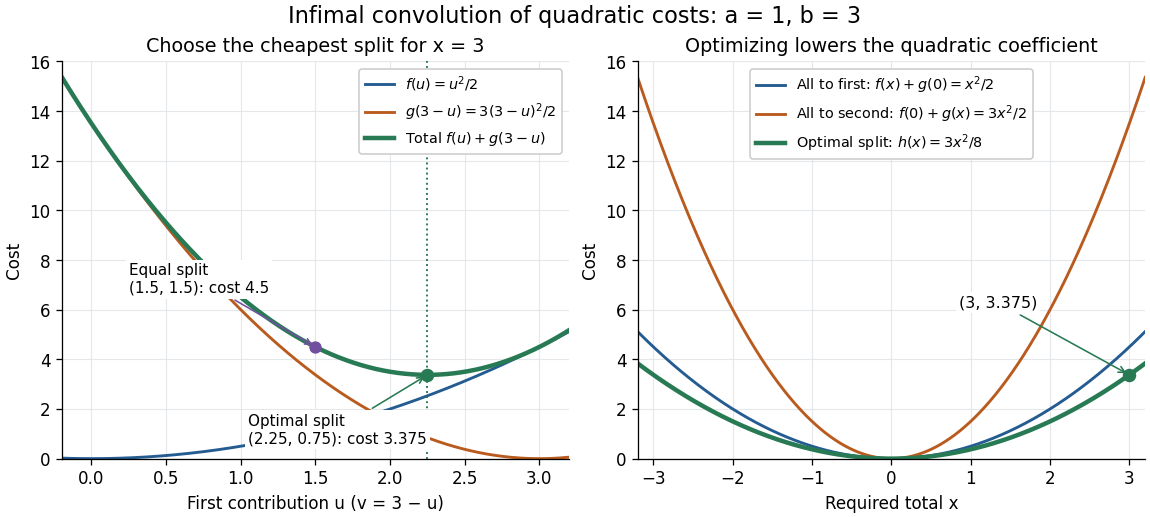
Optimizing the split of two quadratic costs gives a cheaper quadratic total cost
. An exact illustrative calculation, not measured data: , and give and cost , compared with cost for an equal split. The right panel compares the optimized cost with assigning the whole total to either activity. Details.
Smoothing a corner by splitting its cost. Take the absolute value function and the convex quadratic function , with . This infimal convolution is the Moreau envelope of the absolute value function:Here is the sign function, with . The optimal is soft thresholding. In the central region, the quadratic function carries the whole total; outside it, stays at and the absolute value function carries the excess. At the result is the Huber loss in the normalization near zero and outside. Its derivative is for and outside, so the corner becomes a continuous change of slope. Parikh and Boyd's [ref]
https://web.stanford.edu/~boyd/papers/pdf/prox_algs.pdf#page=18. §3.1 discussion of Moreau smoothing
uses twice this normalization for the Huber loss; the explicit formula here fixes the convention. This is also the one-dimensional case of the existing Moreau envelope of the Euclidean norm.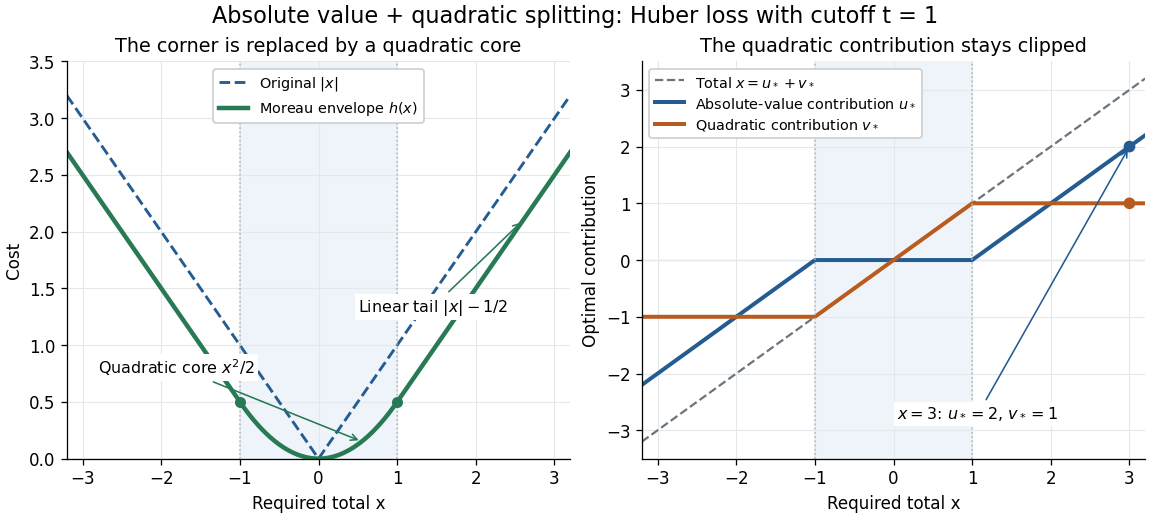

If two nonnegative finite-valued convex functions are defined on all of a finite-dimensional space, their infimal convolution is finite, convex and continuous everywhere. Convex perturbation duality then gives strong duality and dual attainment at every argument. It does not require or imply attainment of the primal decomposition infimum.
More precisely, let be finite everywhere and write . Nonnegativity supplies a lower bound, while the two trial splits and giveMixing nearly optimal splits proves convexity, and continuity of a convex function applies because the effective domain is the entire finite-dimensional vector space. These statements concern the optimized value, rather than existence of an optimal split. For the continuity theorem and dual attainment under the equality constraint , see Bertsekas, Convex Optimization Theory: A Summary, Propositions 1.3.11 and 5.3.3(a). The equality has a feasible point in the whole space for every , and the displayed bound makes its optimal value finite.
A finite value without any optimal split. On , take the convex functions and . Both are nonnegative and finite everywhere, butfor every . The splits have costs , yet the exponential function is strictly positive at every finite . No split attains the infimum. The value function is even constant and differentiable; regularity of the value function does not prevent optimizing splits from escaping to infinity. For example, gives costs approximately , and .
A sufficient extra condition for attainment at a fixed is that be a coercive function, meaning it tends to as . Under the finite-valued assumptions it is a continuous function, so a sufficiently large closed ball contains a global minimum by the extreme value theorem. If this cost is also a strictly convex function, the optimal split is unique. The quadratic example above satisfies both conditions; the exponential function example does not satisfy coercivity.
Nonnegativity is sufficient, not necessary: finite lower bounds , would give by the same argument. Removing all lower-bound control can lose finiteness even for finite convex functions: and give , hence . Nor does finiteness alone guarantee differentiability: choosing gives by the triangle inequality and the split .
Under the finite-valued assumptions, subgradients of an infimal convolution are obtained as its attained dual optimizers. Equivalently . Splitting the latter subdifferential into two separate ones needs a subdifferential sum rule qualification; solving the aggregate dual objective avoids that extra assumption.
For proper convex functions whose infimal convolution is well defined, . The proof separates a supremum over independent variables after writing . No attainment of the infimum is needed.
A rate allocation is proportionally fair when the sum of proportional changes toward any feasible competitor is nonpositive. If route has identical active flows, this condition is and is equivalent to maximizing weighted logarithmic utility subject to capacity constraints.
When a route has zero active flows, its term is absent from weighted logarithmic utility. Its aggregate allocation is taken to be zero; a per-flow rate on it has no operational meaning and need not be uniquely determined. One must not divide by its zero population. Empty-network and empty-group cases can therefore be treated separately while preserving uniqueness of active-flow rates.
For the four routes consisting of adjacent pairs of a unit-capacity four-cycle, put , , and . Every active route in the first group has total service , and every active route in the second has total service . Its per-flow rate is this total divided by its active flow count.
Write for aggregate route service. The four resource constraints are all sums of one odd and one even route service, so they are equivalent to the displayed maximum constraint. For fixed maxima, increasing each active service to its group's maximum improves weighted logarithmic utility. Maximizing with gives and , where , . Inactive routes are omitted; the same formula covers states where one group is empty.
The utility sums logarithmic utilities over individual flows. Its first-order condition gives proportional fairness. Its negative is a strictly convex function on active flow rates, giving uniqueness of those rates on a convex set of feasible allocations.
A semidefinite program optimizes a linear function subject to equalities between affine functions and positive semidefinite matrix inequalities. It generalizes linear programming: a diagonal matrix is a positive semidefinite matrix exactly when its diagonal entries are nonnegative. Matrix trace expresses the objective as for real symmetric matrices.
For real symmetric , replace sign-vector lifts by all matrices in the elliptope:Every sign vector gives a feasible rank-one matrix with the same objective, so the relaxed maximum is an upper bound. The omitted rank-one condition is substantive: an arbitrary feasible Gram matrix need not come from signs.
Replacing by a general positive semidefinite matrix relaxes maximization of subject to . The relaxed value is an upper bound because has trace and satisfies the same quadratic constraints. Both problems are unbounded if the fail to span the ambient space. If they span it, is positive definite and , proving boundedness and attainment of the relaxation.
Use an orthogonal eigendecomposition and a vector of independent Rademacher random variables. Because is diagonal and , every sign vector gives , without taking an expectation. If the scaling denominator is positive, then satisfies every slab constraint and . Under spanning constraints and positive trace, automatically. A nonzero with instead certifies an unbounded direction.
For spanning slab normals, apply the maximum of finitely many Rademacher linear forms bound to , whose squared norms are . Some sign vector has scaling denominator squared at most . Rademacher rounding for a semidefinite relaxation then produces a feasible vector of squared norm at least the displayed fraction of the SDP optimum. This is an existence guarantee from the probabilistic method.
A water-filling algorithm allocates a fixed resource among concave-return channels by choosing one Lagrange multiplier and setting each allocation to a thresholded expression. The multiplier is adjusted until the allocations sum to the resource budget.
To maximize for positive baselines, nonnegative allocations and a positive budget , the KKT conditions equalize the shifted values on allocated coordinates. The unique water level solves . Inactive coordinates have baselines at least the water level. Strict convexity of the negative objective ensures uniqueness, and sorting the baselines gives an efficient water-filling algorithm.
Coordinate descent minimizes an objective by repeatedly optimizing one coordinate, or one block of coordinates, while holding all others fixed. Exact coordinate minimization is especially simple for separable penalties and quadratic objectives.
A coordinate descent method that randomly selects a block and updates only its coordinates. Suppose each coordinate is selected with probability , every block has Lipschitz constant at most , and the objective function is a strongly convex function with modulus . The block descent lemma and the strong convexity gradient inequality giveFor uniform blocks of size in coordinates, updates constitute an optimization epoch, and the epoch complexity is . Here is the initial objective function gap, and the target is its expected gap at most . A coordinate-based common bound is ; actual constants can improve it.
Target: gradient-descent.bigb, under Gradient descent.The orthogonal projection of the gradient onto the coordinate subspace indexed by . It is kept as a vector in the original Euclidean space, with zero coordinates outside the block. For a singleton block it is ; for the full block it is .
Target: gradient-descent.bigb, under Lipschitz gradient.The convex conjugate records a function using slopes rather than input positions. Let be a proper extended-real function: it is finite somewhere and never takes . Its convex conjugate iswhere is the dot product and is the effective domain. An infinite value of excludes that input from the supremum. The value can be , but cannot be because an input with finite supplies a finite lower bound.
The convex conjugate is automatically a convex function, even when is not convex: each fixed input gives an affine function , and their supremum is convex. It is also lower semicontinuous. It need not be proper: for on , is unbounded above for every . The definition and the automatic convexity are discussed in Boyd and Vandenberghe, Convex Optimization (2004), §3.3.1.
The best lower bound with a prescribed slope. Whenever is finite, the affine functionis an affine minorant of . Indeed, an affine function lies below everywhere exactly when . Thus is the largest possible intercept at slope . The convex conjugate trades positions for slopes: specifies where to inspect , whereas specifies which global affine minorant to use. Taking the supremum over all these affine minorants produces the biconjugate; the Fenchel-Moreau theorem says this recovers a proper convex function when it is lower semicontinuous.
A quadratic, computed by completing the square. For the convex quadratic function ,Consequently , and the unique maximizing input is . The affine minorant is the tangent line at : its slope is and its intercept is . For example, gives and the tangent line , touching at . This is the same curve described either by its point values or by the intercepts of its tangent lines.
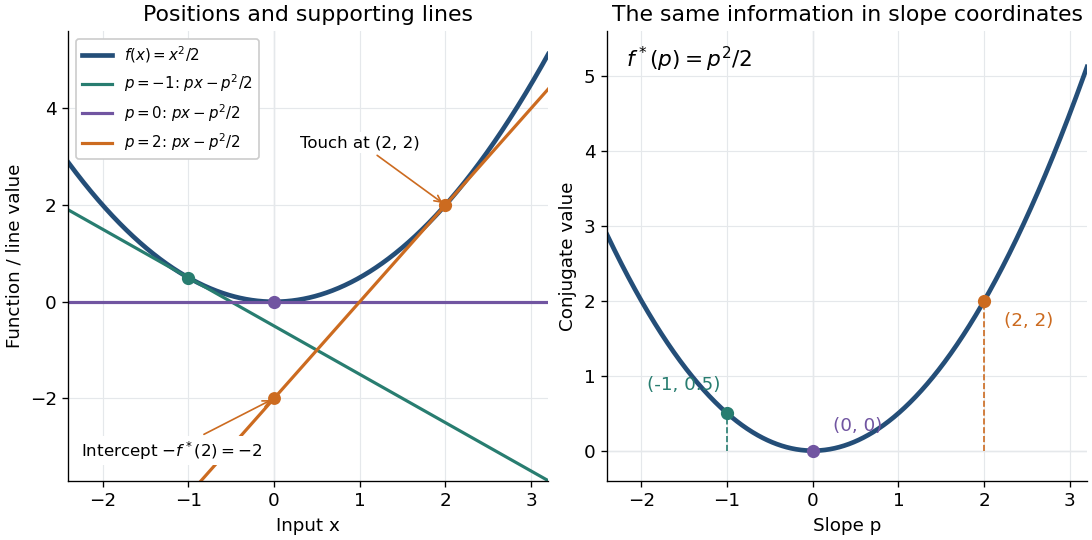

A corner turns into a constraint on slopes. For the absolute value , if then , with value zero at . If , taking makes ; if , taking does the same. Therefore its convex conjugate is zero on and outside: it is the indicator functional of a constraint set for this interval. For the unique maximizing input is zero; for every maximizes, and for every maximizes. The corner's many supporting slopes are exactly the subdifferential .
A supremum need not be attained. For a differentiable convex function finite on all of , an input maximizes exactly when . If is strictly convex, there is at most one such input; existence is a separate issue. For the exponential function , the derivative is positive. At , solving gives and . At , the supremum of is zero as , with no maximizing input. At , as . Thus a strictly convex differentiable function can have both unattained finite conjugate values and infinite conjugate values.
For an increasing concave utility on positive wealth, its utility conjugate uses the indicated supremum and is a convex function of the positive price variable. If on positive , extended by infinity elsewhere, then . Under the Inada conditions its optimizer is the inverse marginal utility, and its derivative is the negative of that optimizer. The sign convention is part of the definition.
For an increasing strictly concave differentiable utility satisfying Inada conditions, its utility conjugate has a unique optimizer and derivative . The dual is strictly decreasing and strictly convex. Twice differentiability of the dual additionally follows when exists and is strictly negative everywhere. Strict concavity alone allows to vanish and does not imply this additional assertion.
For on , strict convexity and the stationary condition give the displayed convex conjugate for every real . Biconjugation recovers on its original positive domain. Its closed extended-real extension has value zero at zero and infinity on negative arguments.
The biconjugate of is the convex conjugate of its convex conjugate:It is the supremum of all affine minorants. For a proper function with an affine minorant, the Fenchel-Moreau theorem identifies it with the closed convex envelope; a proper lower semicontinuous convex function equals its biconjugate.
If with , substitution into the supremum defining the convex conjugate givesThe positivity of allows it to pass through the supremum without reversing it. Negative scaling need not obey this rule for the convex conjugate, even when a formal stationary-value transform does.
For a differentiable strictly concave function whose derivative is a bijection of , defineThe unique minimizing point is , and follows by comparing minimizers at adjacent arguments, even when is not differentiable. This dual is concave and equals in terms of the convex conjugate. If , then . For , .
The lower conjugate uses an infimum, unlike the supremum defining a convex conjugate. For any , and . The inequality is informative only when the lower conjugate is finite. If the infimum is attained uniquely and the dual is differentiable, is its minimizing argument. This sign convention is useful for upper comparison-energy bounds.
The concave biconjugate is an upper envelope of , and equals for a proper closed concave function under the usual duality hypotheses. It equals in terms of the ordinary biconjugate. If , differentiability and concavity of imply . For a finite differentiable dual the equality follows because minimizes .
Suppose , , is differentiable, and . Then for the concave Legendre dual , andIntegrate the derivative bounds from to , then integrate . Multiplying the first inequality by a negative reverses both comparisons. A bound valid without cases is .
Maximize over . The maximizer is , giving the displayed Huber loss. The indicator functional of a constraint set is zero on the interval and infinity outside; it is not the zero-one indicator used in measure theory.
A proper lower-semicontinuous convex functional on a real Banach space equals its biconjugate, with the canonical embedding in the bidual understood. One inequality follows from the Fenchel–Young inequality; separation of a point below the closed convex epigraph gives the opposite inequality. This is the closed-convex analogue of recovering a function from all its affine supporting functions.
For a proper extended-real function with an affine minorant, biconjugate gives its greatest lower-semicontinuous convex minorant. Geometric separation of its epigraph turns containing closed half-spaces into affine lower bounds. Vertical half-spaces are recovered by adding multiples of a domain-separating inequality to one fixed affine minorant.
The Fenchel–Young inequality says that every input and every slope obeywhere is any proper extended-real function and is its convex conjugate. No convexity assumption on is needed for this inequality: the defining supremum is at least the particular value . If either term on the left is , the inequality still holds, but cannot be an equality because the dot product on the right is finite.
For a proper convex function, equality is equivalent to the subgradient conditionTo see this, with finite, equality says that attains the supremum defining , so for every . Rearranging gives the subgradient inequality . Geometrically, the affine minorant touches at .
If the proper convex function is also closed, meaning its epigraph is a closed set, or equivalently it is lower semicontinuous, thenThe forward implication holds without closedness; the reverse one requires the additional hypothesis in general. Applying the equality criterion to relates to , and the Fenchel-Moreau theorem supplies when is closed. See Bertsekas, Convex Optimization Theory: A Summary, §5.4.1, Proposition 5.4.3 for precisely this distinction.
A concrete failure of the reverse implication occurs for the indicator functional of a constraint set of the open interval . Its convex conjugate is : the endpoint gives the supremum, even though it is excluded from the interval. At , , but , so equality fails and is empty. Closing the interval changes the endpoint value and restores equality there.
For the convex quadratic function , the Fenchel–Young inequality is , and equality holds exactly when . For the absolute value , finite equality requires at , where is the sign function; at every gives equality. These are exactly the subgradients of the absolute value, including its entire interval of slopes at the corner.
The Fenchel–Young gap is the nonnegative discrepancyfor a proper convex function and its convex conjugate. It can be . When is finite, it is the vertical distance between and its affine minorant . The Fenchel–Young gap vanishes exactly when , so it measures whether an input and a slope satisfy the subgradient relation.
For the convex quadratic function , completing the square givesAt and , the function value is and the tangent line has value , giving a Fenchel–Young gap of . In , the same calculation for gives and , half the squared Euclidean norm of the mismatch.
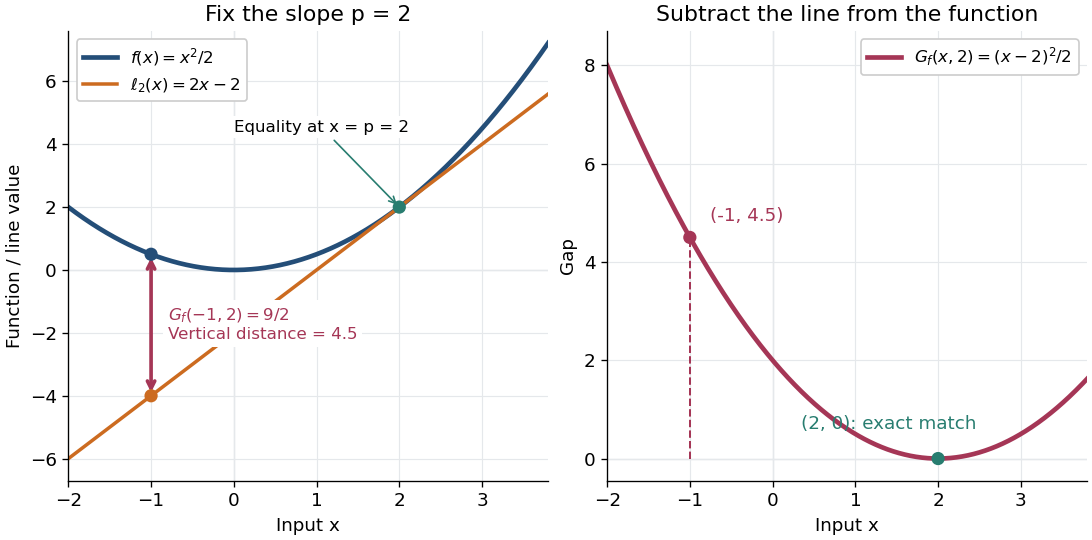

An exact optimization error certificate. Fix a slope with and minimize the linearly tilted objective function . By the definition of the convex conjugate, , soThis identity holds even when the infimum is not attained. Thus a computed finite Fenchel–Young gap is exactly the error in objective value for this minimization problem. For the convex quadratic function, implies . A general proper convex function need not convert a small gap into a small distance: the absolute value has zero gap at for every .
The Fenchel–Young gap also connects convex analysis to optimal transport. For a proper convex function , define Kantorovich potentials and . The half-squared Euclidean distance cost satisfies . For a transport plan with finite integrated cost and integrable Kantorovich potentials, integrating this identity gives the difference between transport cost and the potentials' bound. This is the same local subgradient mismatch summed over transported pairs.
For a proper convex function finite at , global minimality is equivalent to . This follows immediately from the defining subgradient inequality. Combined with a subdifferential sum rule, it converts a convex minimization problem into an inclusion, for example the equation defining a proximal operator.
Adding the two subgradient inequalities for and givesThus the subdifferential is a monotone operator. This inequality proves uniqueness of its resolvent: two solutions of must coincide when .
For a convex function and , the forward step is the set-valued explicit update . It reduces to the usual gradient step when differentiable. In contrast, a backward step uses a subgradient at the new point and is the proximal operator for a proper closed convex function.
For a convex scalar function , the partial subdifferential means the subdifferential of at . It is not differentiation of a set-valued subdifferential. If this section is differentiable, the partial subdifferential is the singleton containing .
For a proper lower-semicontinuous convex functional on a real Hilbert space, means for all . Taking the supremum gives equality in the Fenchel–Young inequality: . Apply the same argument to and use the Fenchel-Moreau theorem to obtain the reciprocal subgradient condition.
For a finite convex function , the function is convex. The subgradient inequality gives , where . Conversely, every subgradient of annihilates , because is constant on lines in those directions. For , write and test the subgradient inequality at ; this proves . For , is constant and both sides are since a finite convex function on the real line has a nonempty subdifferential everywhere.
The subdifferential of the L1 norm consists of vectors with when and when . These coordinate conditions give the Karush-Kuhn-Tucker conditions for Lasso and Square-root Lasso.
For proper convex functions under a standard relative-interior qualification,In particular, if is differentiable at , then .
Let be a bounded linear operator from a real Banach space to a real Hilbert space, and let be a proper lower-semicontinuous convex absolutely one-homogeneous functional on . The normalization and source relation imply by the Euler identity for a convex one-homogeneous functional. For the norm penalty on a Hilbert space, its nonzero-point subgradient is . Hence : is a right singular vector with singular value , and is the corresponding left singular vector. Thus the definition recovers the ordinary operator singular-vector relation using the one-homogeneous norm penalty. Uniqueness of the vector from its data requires extra hypotheses on and .
For an absolutely one-homogeneous functional that is convex and ,The subgradient inequality at zero gives , and at gives the reverse inequality. This is an Euler identity that needs no differentiability.
A nonzero vector is an eigenfunction of an absolutely one-homogeneous convex functional with eigenvalue when . This nonlinear analogue of an eigenvector underlies exact shrinkage formulas for several variational flows and proximal maps.
For a real matrix , exactly one of the following holds: there is with and , or there is with . Separating from the standard simplex proves the result; may then be normalized to sum to one.
This is an alternative related to Farkas' lemma. It is not the strict-primal Gordan alternative: for the column matrix , a nonnegative nonzero primal vector exists, while a componentwise strictly positive one does not.
This is the proximal gradient method when the nonsmooth term is the indicator of the feasible convex set, whose proximal operator is the metric projection.
The projected subgradient method minimizes a possibly nonsmooth convex function over a closed convex set by iterating with . Nonexpansiveness of Euclidean projection onto a convex set and the subgradient inequality give its basic convergence bound.
If and , thenIt follows by expanding the squared distance after each projected step, using nonexpansiveness of projection, summing the resulting inequalities, and applying convexity.
The step size of an iterative optimization algorithm controls the distance moved in one update. Convergence conditions balance sufficient progress against instability from steps that are too large.
For a proper lower-semicontinuous convex function , the proximal operator is . Its optimality condition is .
The proximal map of sends to , with zero assigned at . This removes vectors inside the radius- ball and shortens all larger vectors by a fixed radial distance. It is useful for groupwise sparsity.
On a Banach space one can define the set of minimizers of , but existence and uniqueness need additional geometry or coercivity hypotheses. The optimality condition is , with the duality mapping . The Hilbert completion-of-square shift by a dual vector does not generalize unchanged. On with and , every with is a minimizer; the vector is not one.
For a real Hilbert space, , and , identify with its vector by the Riesz representation theorem. Completing the square in shifts the input to . Substitute and multiply by to obtain the displayed formula, valid also for negative . If and , the answer is ; if , the objective is identically infinite and no proper proximal problem remains.
The Moreau envelope of a proper closed convex function isIt is differentiable even when is not, with and -Lipschitz gradient.
For , the Moreau envelope of the Euclidean norm is when and otherwise. Its gradient is in the core and outside. The approximation error is between zero and .
For proper lower semicontinuous convex functions, the Moreau envelope has gradient . This follows by subgradient inversion under convex conjugacy and the quadratic conjugate. Firm nonexpansiveness of the proximal residual makes the gradient -Lipschitz continuous.
For a proper convex function with sequential lower semicontinuity , form with . The Moreau envelope theorem gives . If is integrable, it defines a smooth surrogate probability density function. Infimizing the logarithm of a probability density function with a positive quadratic penalty has the opposite sign and does not generally smooth it. For the Laplace distribution, that incorrect operation leaves , which is not differentiable at zero.
Articles were limited to the first 100 out of 142 total.
Articles by others on the same topic
There are currently no matching articles.