Two square matrices over the same field are similar if for an invertible matrix . They can describe one linear operator using two different ordered bases, with the same basis used for input and output in each description. Fix the convention : is the old coordinate vector, the new coordinate vector, and the columns of are the new basis vectors in old coordinates. This is the convention of the change-of-basis matrix.[ref]
Linear Algebra Done Right by Sheldon Axler (4th edition). §3D, Theorem 3.84, printed p. 93: change-of-basis formula; the matrix there converts in the opposite direction to our
For a concrete linear operator on the physical plane, let double horizontal components and multiply vertical components by five. In the old standard basis , its matrix of a linear map is . Choose the new ordered basis with , . ThenThe second column of says . Its off-diagonal entry records how the chosen basis vectors describe the output; the physical linear operator still stretches along the old horizontal and vertical directions.
Take the physical vector . Its two coordinate vectors, and the two descriptions of , areReconstruction gives . The output coordinate vectors differ, but the endpoint in the physical plane is the same.
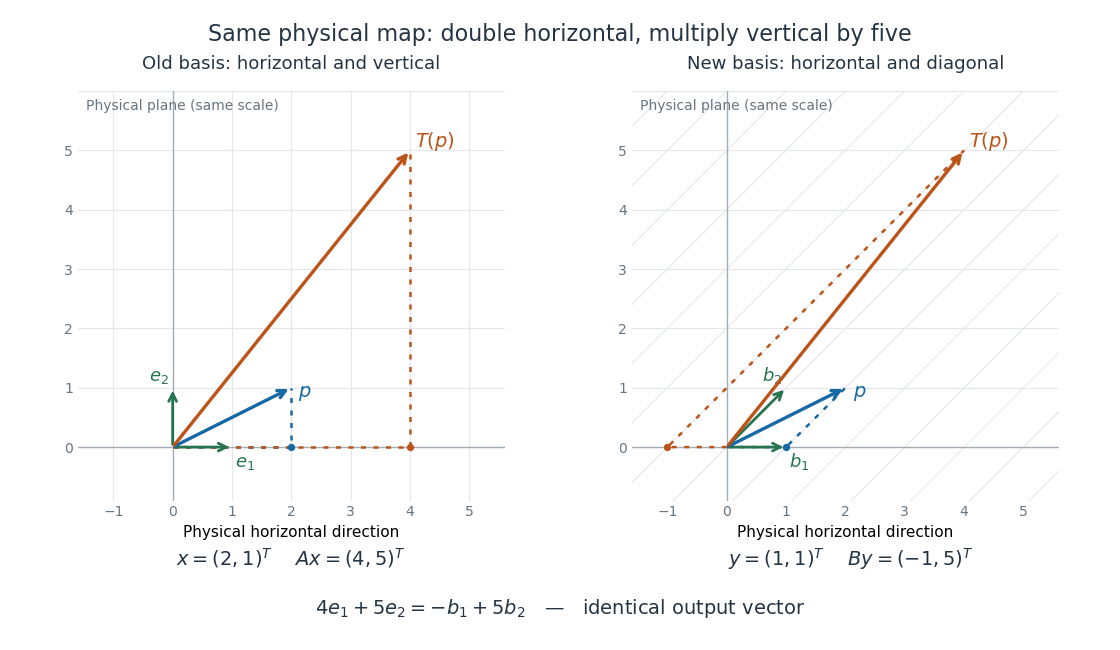
One linear operator and the same two physical vectors described in a standard basis and an oblique basis
. Both panels use the same physical plane and scale. The blue arrow is , and the orange arrow is . Dotted paths reconstruct them from their respective basis vectors; the right grid follows , . Details.This is why matrix similarity is useful: a convenient basis can simplify calculations without changing the linear operator. A diagonalizable matrix can be replaced by a diagonal matrix, making repeated application a calculation with powers of its eigenvalues. In the example, makes the two independent stretch factors visible, while expresses the same action in directions chosen for another purpose. Matrix similarity invariants separate properties of the linear operator from features of its address system.
Matrix similarity invariants are quantities unchanged by replacing with . Important examples are the characteristic polynomial, trace, determinant, matrix rank, and eigenvalues with their algebraic multiplicities. The characteristic polynomial convention here is , where is the identity matrix.[ref]
Linear Algebra Done Right by Sheldon Axler (4th edition). §9C, Definition 9.63, printed p. 363; Theorem 9.65, printed p. 364: characteristic polynomial, trace, and determinant
The short determinant proof works over any field: because , multiplicativity of the determinant givesThus its roots, the eigenvalues, retain their algebraic multiplicities in any field extension where the polynomial splits. Also . The cyclic property of the trace gives ; equivalently, the trace is determined by the coefficient of in the characteristic polynomial for an -by- matrix.[ref]
Linear Algebra Done Right by Sheldon Axler (4th edition). §8D, Theorems 8.49–8.50, printed pp. 326–327: cyclic trace identity and basis independence
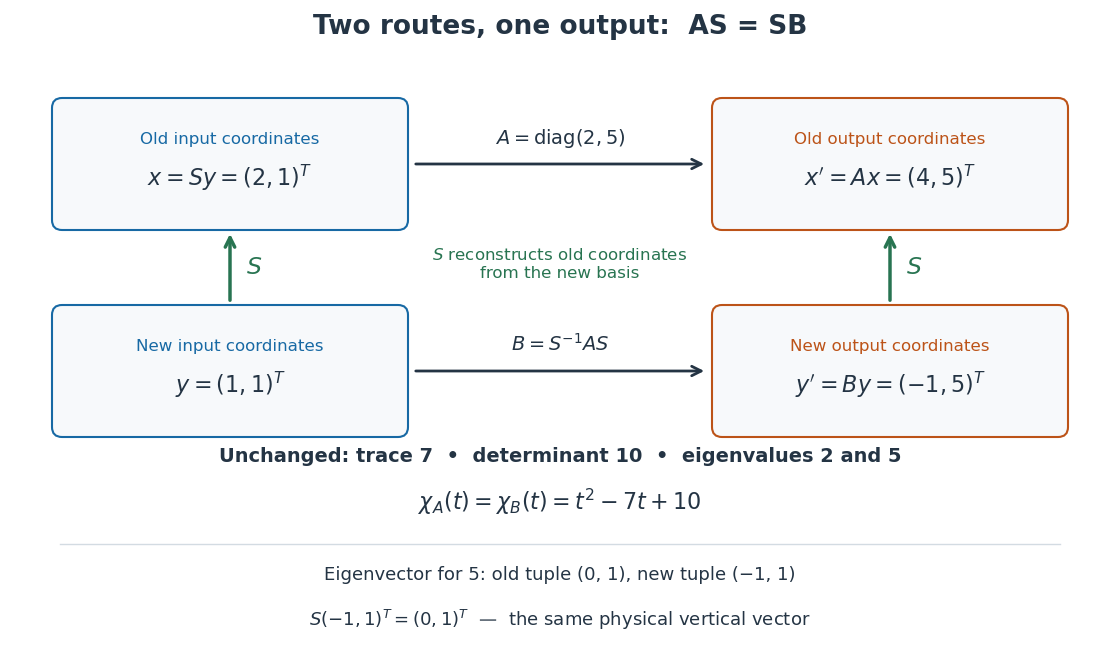
For the two matrices in the opening example,Their entries differ, yet these quantities agree. Agreement is a useful necessary test for matrix similarity; it is not sufficient in general, as same eigenvalues do not imply similarity illustrates.
The relation also preserves repeated application. Adjacent factors cancel to giveFor the opening example, matrix powers therefore have the explicit formAt , this is . Acting on gives , which reconstructs as . More generally for every polynomial , so the minimal polynomial is also unchanged. Multiplication by invertible matrices preserves matrix rank, giving another invariant without finding eigenvalues.
Under , an eigenvector in old coordinates becomes in new coordinates. Indeed,Since is an invertible matrix, the new coordinate vector is nonzero. The inverse conversion proves that the two eigenspaces have the same dimension, hence the same geometric multiplicity.
For , the eigenvector has eigenvalue . In the oblique basis of the opening example, its coordinate vector isThe tuple changes from to , but reconstruction gives : the physical vertical direction is unchanged. Calling the eigenvectors unchanged is accurate only for the underlying vectors, not for their coordinate vectors.
Consider the diagonal matrix and a Jordan blockBoth have characteristic polynomial , trace , determinant , and eigenvalue with algebraic multiplicity two. But is the whole plane, whereas vanishes only when . Their eigenspaces have different dimensions, so eigenvectors under similarity rules out matrix similarity. There is an even shorter proof: for every invertible matrix .
The missing information is how the linear operator acts beyond its eigenvectors. Here , while but . Their minimal polynomials are respectively and . Over a field where the characteristic polynomial splits, the full sizes of the Jordan blocks, encoded by the Jordan normal form, determine the matrix similarity class.
A similarity transformation replaces a square matrix by a similar matrix. With the change-of-basis matrix convention , it sends to : reconstruct the input in old coordinates, apply , then extract the output's new coordinates. These three operations explain the order of the factors.
The equivalent formula uses as the conversion from old to new coordinates, reversing the role assigned to above. For the opening example's numerical , this opposite conversion gives . If the old basis is , the new basis vectors in that convention are the columns of , namely and . Both formulas are similarity transformations; the direction of the coordinate conversion decides which one describes a specified basis.
An especially useful form is the intertwining operator equationIt says that applying before reconstruction by gives the same physical output as reconstructing first and applying . Given an invertible matrix , multiplying this equation by proves matrix similarity. Without invertibility, the equation alone does not prove matrix similarity.
For real matrices, orthogonal similarity is the special case with an orthogonal matrix. Then a symmetric matrix remains symmetric, because . The expression describes the reverse conversion and has the same property. An orthonormal basis retains the ordinary dot product formula for its coordinate vectors.
An arbitrary change of basis need not preserve entrywise symmetry. In the opening example, is a symmetric matrix but is not. The geometric inner product has not disappeared: in the new coordinates it is represented by the Gram matrixFor with new coordinate vector , the squared Euclidean norm is , agreeing with . The naive coordinate sum would use the wrong inner product.
If , direct multiplication givesThis is self-adjointness expressed in the new inner product, rather than entrywise symmetry relative to the identity matrix. For the example, both products equal . Thus arbitrary matrix similarity preserves the linear operator, while its geometric interpretation requires transforming the Gram matrix as well. Matrix congruence supplies the corresponding rule for a bilinear form and should be distinguished from matrix similarity.
If a real matrix has a positive diagonal matrix such that is a symmetric matrix, then is a symmetric matrix related to by a similarity transformation: gives . Thus is a diagonalizable matrix with real eigenvalues. If for all real vectors , its eigenvalues are nonpositive. This converts symmetry in a weighted inner product into Euclidean symmetry.
Every unital algebra automorphism has the form for some invertible . One proof transports the matrix units through , chooses compatible bases for their rank-one images, and reconstructs the common similarity transformation.
If real matrices satisfy for an invertible complex , then , so both real matrices intertwine and . Since is a nonzero real polynomial, some real makes invertible and supplies a real similarity.
Articles by others on the same topic

Matrix similarity is an important concept in linear algebra that describes a relationship between two square matrices. Two matrices \( A \) and \( B \) are said to be similar if there exists an invertible matrix \( P \) such that: \[ B = P^{-1} A P \] In this expression: - \( A \) is the original matrix. - \( B \) is the matrix that is similar to \( A \).


