For a nonnegative survival time , the survival function iswhere is the cumulative distribution function. Thus is the probability that the chosen occurrence is still in the future at time . We consistently use the strict inequality : a probability mass at has already left the survival function at itself. With this convention is a right-continuous function and a nonincreasing function taking values in . If , then ; if is finite with probability one, then as .
For and , conditional probability givesFor example, and mean that of those still event-free at year two remain event-free through year five. Their intervening event probability is , whereas the original population's probability of an occurrence in is . Conditioning changes the denominator.
The area under the survival function up to a horizon gives the restricted mean survival time. A positive terminal plateau in a plotted Kaplan–Meier estimator does not establish that the occurrence will never happen: terminal censoring and survival-mean identifiability explains why the unobserved tail remains undetermined.
For a nonnegative random variable with finite expected value and , its mean residual life is the remaining conditional expected value after surviving past . The tail integral formula for moments gives . The exponential distribution has constant mean residual life, equal to its original mean. In excess of loss reinsurance, the total variance stationary condition for excess of loss sets a candidate retention equal to this quantity.
The restricted mean survival time to a fixed cutoff is for a nonnegative event time. This follows by the tail integral formula for moments. Unlike the unrestricted mean, it uses no tail beyond ; under independent censoring it can be estimated by integrating a Kaplan–Meier estimator over adequately observed follow-up.
For a survival time with an absolutely continuous probability distribution, probability density function , and survival function , the hazard function iswhere , with the derivative identity holding almost everywhere. At points where the local limit exists, equivalentlyThe hazard function measures an instantaneous conditional rate. If time is in years, its units are inverse years, and its value can exceed one. A probability for a short interval is approximately , not ; for an absolutely continuous probability distribution, the probability of an occurrence at the single exact time is zero. The discrete hazard, by contrast, is a conditional probability at a possible event time.
The factorization distinguishes a probability density function for the original population from a hazard function for those still event-free. With an exponential distribution of rate per year, per year but per year: the latter also accounts for the probability of reaching year five. The exponential survival risk over an interval example computes finite-horizon probabilities from this rate.
Upper records of iid observations with a continuous distribution have transition density above the latest record . Consequently the cumulative hazard transforms consecutive record increments into independent unit exponentials. Record counts below a level with are therefore Poisson with mean . Set the count to zero if the first record exceeds the level. At a finite upper endpoint with , the count is infinite instead of a finite-mean Poisson variable.
At ordered possible failure times , the discrete hazard is . Its survival function satisfies , and hence . Estimating by the observed number of failures divided by the risk set size under independent censoring yields the Kaplan–Meier estimator. Unlike a continuous-time hazard rate, a discrete hazard is a probability between zero and one.
For an equally weighted mixture of individual survivor functions , the population hazard function is . Thus the weights are the surviving proportions, and the cumulative hazard function is , not generally the mean individual integrated hazard.
For a nonnegative random constant individual hazard , write . The population survivor function is and its hazard is . Under the integrability needed to differentiate, , soThe conditional distribution is weighted by . This proves decreasing population hazard without any decrease in individual hazards and explains survival selection in a heterogeneous population.
In a population mixture with initial component probabilities , conditioning on survival to time changes them to the displayed probabilities by Bayes' theorem. Components with larger survivor functions receive greater relative weight among survivors. The population hazard function is the weighted mean of the component hazards with these time-dependent weights. This selection can change the population hazard even when all component hazards are constant, as shown by the hazard derivative for a mixture of exponential distributions.
For a finite mixture with positive weights and rates , the survivor function is and the hazard function is the surviving-population mean of the component rates. Write . Differentiation gives and therefore . The hazard is decreasing, strictly so when distinct rates have positive weights. For finitely many rates it tends to the smallest rate with positive weight. This is survival selection even though each individual component has a constant hazard.
Suppose has an absolutely continuous probability distribution, with survival function . On an interval where , its cumulative hazard isHere is the hazard function; its integral is dimensionless because the units of rate and time cancel. The identity follows by integrating the derivative of , so mere continuity of the survival function is not enough: the absolute continuity assumption supplies a probability density function. If reaches zero, interpret as . The normalization also matters; an initial probability mass at zero would require an initial term .
Accumulating hazard functions adds on the scale and multiplies survival factors on the scale. For and ,For instance, a cumulative hazard increment of gives event probability , rather than a probability of . With per year, and . With the increasing hazard function per year when is expressed in years, , so gives . Its coefficient has units of inverse years squared.
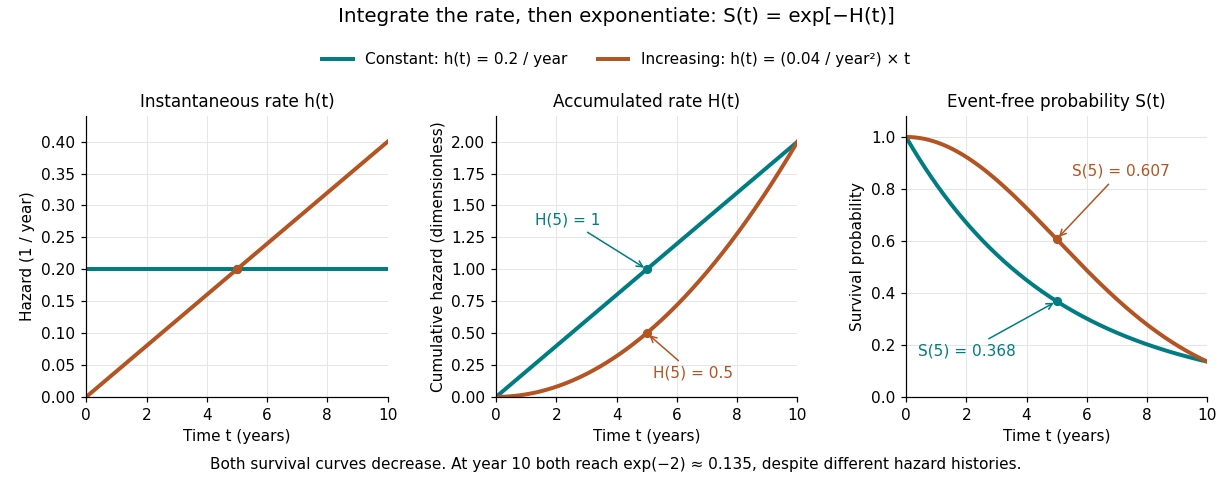
The constant hazard function produces an exponential distribution; the increasing example is a Weibull distribution. Their survival functions both decrease, although one hazard function stays constant and the other increases. At year ten both have and despite different earlier histories. The accumulation identity is described in Lu Tian's Stanford notes, Section 1.1.
For a discrete hazard at each possible event time , the exact counterpart is . Taking its negative logarithm sums , rather than . Therefore exponentiating a Nelson–Aalen estimator does not give exactly the Kaplan–Meier estimator; small-jump comparison of cumulative hazard estimators quantifies the difference.
Let , , and suppose and are independent, with continuous failure density . Then the Tonelli theorem givesThus has mean zero. The identity also holds conditionally on covariates when censoring is independent conditionally on them. For an estimated hazard, the mean error is controlled by , not by pointwise fit alone.
// Target: survival-analysis.bigb
For a nonnegative continuous event time with survival function S, hazard function h and H the cumulative hazard, split the expectation at c. The censored contribution is S(c)H(c). The event contribution is by integration by parts, since and . Adding gives the displayed identity. Linearity extends it to the expected observed event count in a cohort, without requiring independence between subjects.
For a proper continuous event time and invertible cumulative hazard function , the survivor function identity gives .
A hazard ratio compares two hazard functions at the same time. Under proportional hazards it is constant in time.
Articles by others on the same topic


The **survival function**, often denoted as \( S(t) \), is a fundamental concept in survival analysis and statistics, particularly in the context of time-to-event data. It describes the probability that a subject or an individual survives beyond a certain time \( t \).