Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

For a fixed cohort with individuals at risk just after , no censoring or entry inside , and events in , the Kaplan–Meier estimator factors telescope to the displayed ratio. A tied group of events contributes , the same product as any sequential ordering without intervening censoring. Events at are counted before censoring at the same time under the usual convention.
The Kaplan–Meier estimator constrained to have survivor function value at maximizes the right-censoring log-likelihood subject to the displayed constraint. Here is the discrete hazard, the event count and the risk set size. In an interior event-time solution, a Lagrange multiplier gives before the constrained time, with afterwards. The multiplier is chosen to satisfy the product constraint. It is essential to allow a zero-event jump at the constrained time or another relevant cell boundary: a constraint can require mass outside observed event times. A general implementation instead maximizes the concave probability-mass log-likelihood with total mass one and mass above equal to , allowing all relevant cells and a terminal tail. This also handles unobserved tails and boundary solutions without imposing unjustified event-only support.
The median survival estimate is the first event time at which the Kaplan–Meier estimator reaches or falls below one half. It is not identified beyond the observed follow-up if the curve never reaches that level. A few reported survival probabilities bound the crossing time but do not determine an exact median. Confidence intervals can be constructed by inverting confidence bands for the survivor function.
Consider six subjects observed from time zero. Recorded survival data are , , , , , and , with each pair giving in years. Thus have observed events, while are right-censored. The letters label subjects, not treatment groups. Here are all exit times, including rows without events:
| Time (years) | Risk set just before | At risk | Events | Right censoring count | Survival factor | Kaplan–Meier estimator |
|---|---|---|---|---|---|---|
At year one, . Removing at year two leaves the Kaplan–Meier estimator unchanged. Immediately before year three, are still in the risk set: the two events give . Only afterwards do leave, leaving alone. Removing before counting the tied events would incorrectly use and give . The event-first convention is part of the recorded-time interpretation; coarsely rounded timestamps do not reveal a hidden ordering within that time bin.
The exact Kaplan–Meier estimator is on , on , and on . The three right censoring ticks are , , and ; at a shared event time the tick is on the post-event step. Beyond year five the risk set is empty, so the horizontal endpoint does not determine later survival. The Kaplan–Meier median survival time is three years, since this is the first step at or below .
Now separate the tied events by changing only 's recorded event time from year three to year four. At year three the risk set still has four subjects, but , so . After the event and 's right censoring, only remain. At year four , giving . The intervening right censoring prevents the factors from telescoping to the original tied-event factor. If instead remained observed past year four, the factors would be , giving the original after both events. This is Kaplan–Meier telescoping across a censor-free interval in numbers.
Incorrectly counting every right-censored exit as an event estimates the distribution of observation-ending times , rather than survival times . For the original tied cohort, the spurious curve is at year one, at year two, at year three, and zero at year five. That zero asserts a failure for , whose only known information is .
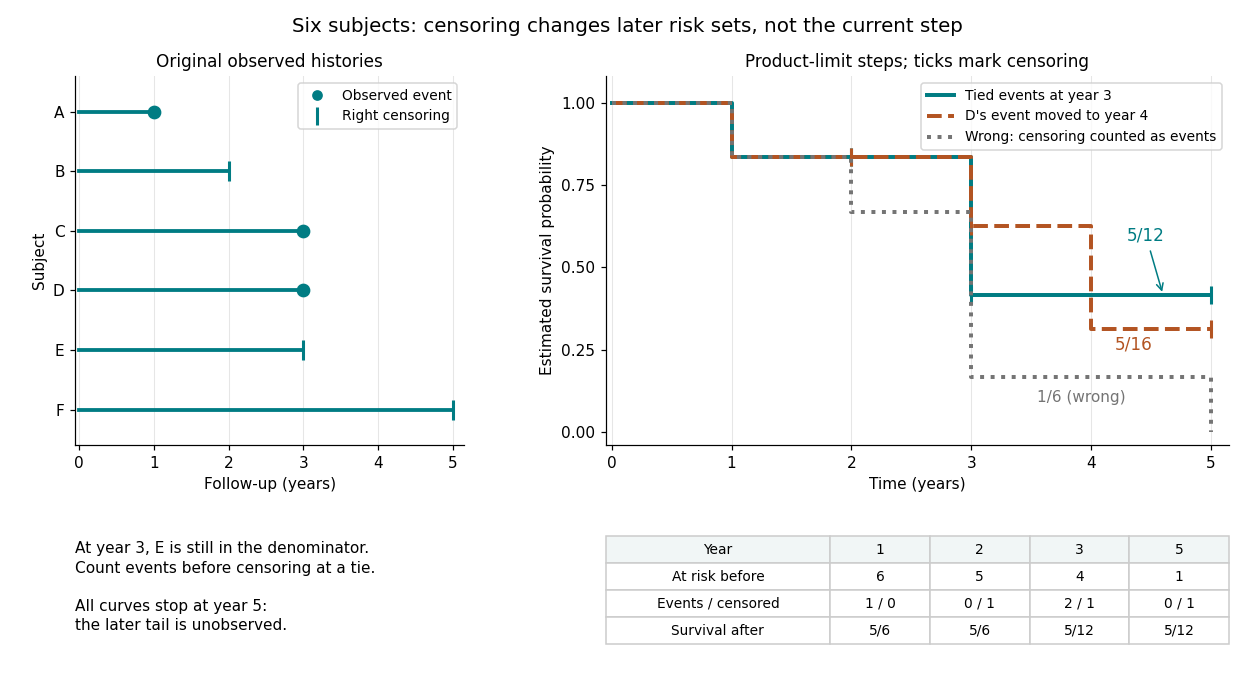
Six observed histories and the effect of ties and right censoring on Kaplan–Meier steps
. Details. The computation uses the risk set and event-before-censoring convention in Lu Tian's STAT331 notes, Unit 3, pages 2–6; this six-subject example supplies its own exact counts.
The compactification scale is the first nonzero internal-mode mass. On a circle it equals for a higher-dimensional massless field. A zero-mode dimensional reduction applies at energies well below it. Warping, nontrivial geometry and boundary conditions can change the relation between the first mass and a geometric radius.
For with -independent coefficients, the geodesic Lagrangian makes constant. Its remaining Euler-Lagrange equations give the displayed Lorentz force, where and uses the Levi-Civita connection of . For a particle of five-dimensional mass with proper-time parameter , the conserved momentum is and the four-dimensional rest mass is . Reparametrizing by four-dimensional proper time gives .
Consider a local-level state-space model , , with mutually independent centered Gaussian noises of variances and . Start with , independently of these noises. Before the first observation, the Kalman prediction step gives , . If , the Kalman gain is , and the posterior mean and posterior variance becomeThe next Kalman prediction step keeps the mean but adds fresh process noise variance, giving . If , thenThus new uncertainty is introduced at each transition and reduced by each measurement. It does not shrink to zero merely because many measurements have arrived: the state continues to change.
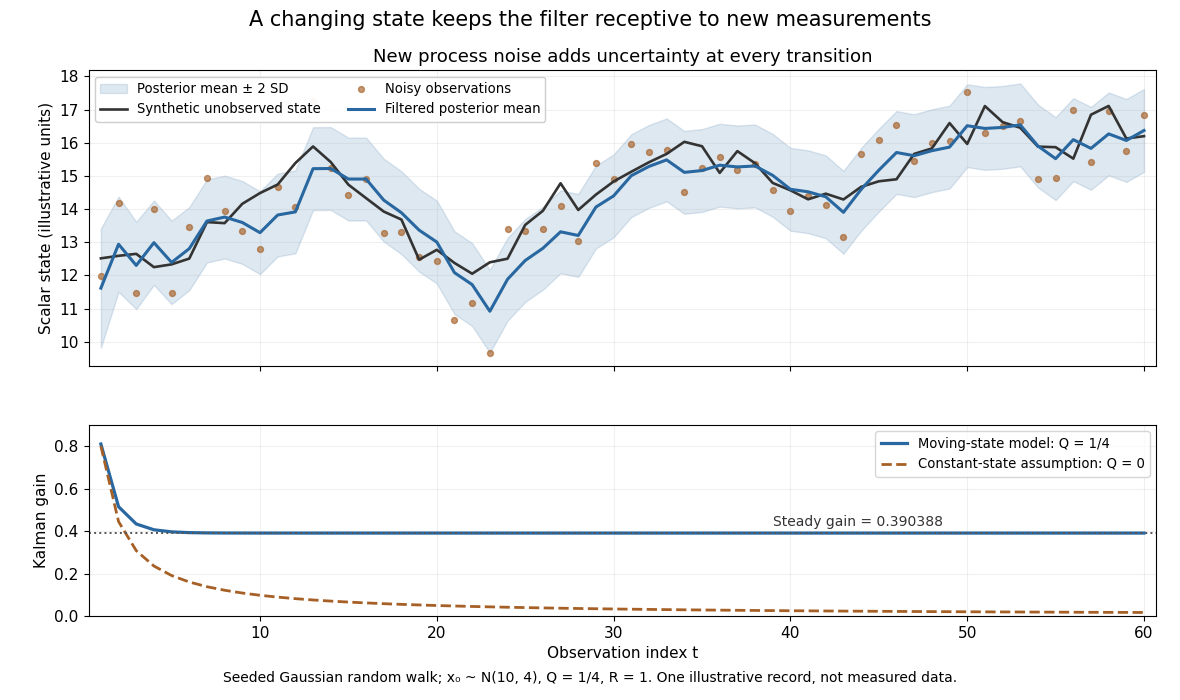
The steady-state local-level Kalman gain here isWith , the limiting posterior variance has the same numerical value. By contrast, the static-state model with gives and . That decreasing gain is appropriate for a state that truly remains constant. Applied to the changing random walk, it builds confidence in the wrong model. The choice of process noise is therefore a statement about state evolution, rather than just an instruction to make a plot look smoother.
For the state-space model , , assume independent Gaussian process noise and measurement noise of variances , independent of the prior state and previous observations. A normal distribution for the filtered state, with mean and variance , predicts mean and variance . Here denotes predicted state variance, rather than the observation-noise covariance notation used in the vector equations above. Gaussian conditional expectation then gives posterior mean and posterior variance , where the Kalman gain is .
Mere weak white noise assumptions do not imply normal posterior distributions: independent process noise with a Rademacher distribution makes the next state a mixture of two shifted normal distributions. The Kalman filter can still describe a best affine state estimate under appropriate second-order assumptions, but that is distinct from an exact Gaussian conditional law.
In a linear Gaussian state-space model with process noise covariance and exact scalar observation , the predictive state covariance includes even though there is no separate measurement noise. Here denotes predicted state covariance; it differs from the measurement-noise notation in the general Kalman filter equations. The observation innovation variance is . Omitting the second term incorrectly removes the current process noise. If , Gaussian conditional expectation gives the posterior covariance matrix . This can be a singular matrix because the observed linear combination is then known exactly.
For a concrete example with two state components that are dimensionless quantities, take predicted mean , predicted covariance matrixand exact observation of the first component, , . The innovation is , its variance is , and the Kalman gain is . The posterior mean and posterior covariance matrix are thereforeThe observed component now has zero variance. The second component remains uncertain, but its posterior mean changes and its variance falls from to because its prediction error had nonzero correlation with that of the first. This is the mechanism by which measurements of one component can inform another.
The Kalman measurement update incorporates the new observation by Gaussian conditional expectation:The posterior covariance matrix subtracts a positive semidefinite matrix, reflecting the information supplied by the measurement. Even if the innovation is zero and the mean does not move, the uncertainty can decrease. In this linear Gaussian model the posterior covariance matrix depends on the observation geometry and its uncertainty, rather than on the numerical observed value.
The derivation is one application of Gaussian conditional expectation per measurement. Before observing , the state and observation have joint covariance matrixConditioning the upper block on the lower block gives exactly the two update equations. The upper-right block explains the Kalman gain: a measured component corrects a state component only to the extent that their prediction errors have covariance. The measurement can therefore improve an unobserved velocity when a state-space model correlates its error with an observed position.
The Kalman gain maps an observation innovation into a state correction:For a scalar state observed directly, it reduces to . With positive variances, , and the Kalman measurement update is the weighted mean . That interpretation belongs to the scalar unit-coefficient case; a general Kalman gain is a rectangular matrix, not a collection of weights necessarily between zero and one.
For the Kalman filter model, the innovation is . Its conditional covariance matrix before the measurement isThis includes uncertainty in both the predicted state and the measurement noise. It is a covariance in observation coordinates; is a covariance in state coordinates, and need not even have the same dimensions.
The Kalman prediction step advances the previous posterior mean and posterior covariance matrix through the state transition:The minus superscript marks information before observing . The transpose and matrix multiplication propagate the old uncertainty; adds the uncertainty of the new process noise. A known control input changes the mean but contributes no additional variance. If the control input itself is uncertain, that uncertainty needs its own model.
A Besicovitch set is a planar Kakeya set of Lebesgue measure zero containing a unit line segment in every direction.
For a zero-one Boolean function of mean , the displayed bound holds for sufficiently large , uniformly in . If it failed, put , and split its nonconstant Fourier weight at level . The total influence bound puts at most above that level. The hypercontractive weighted influence bound with puts only below it: the conversion factor stays bounded, while . This contradicts total nonconstant weight .
For a zero-one Boolean function on the unbiased Boolean hypercube with flip-probability influences , the displayed bound holds for sufficiently small . If it fails, write . The total influence identity puts at least half the nonconstant Fourier weight on levels . The hypercontractive weighted influence bound at then gives . Its upper bound contradicts .
The union of finite invertible matrices under . Every element and relation occurs in a finite matrix size; adding identity blocks permits comparisons between different sizes without changing the stable class.
In the constant-stress overlap layer, the law of the wall gives and the Reynolds stress gives . Thus and local balance gives . Combining with the K-epsilon model viscosity formula gives the displayed constant . The energy diffusion term then vanishes. The dissipation diffusion term does not: it is . Balancing it against the dissipation-equation source terms yields the displayed Von Kármán constant relation. Neglecting dissipation diffusion would incorrectly require equal production and destruction constants.
A stationary turbulence edge with no production has an advection–turbulent-diffusion leading balance. For , and , this balance gives and . The integral length and turnover frequency both tend to zero when . The front viscosity is linear, with . This is formal high-Reynolds-number consistency, not a uniform justification for neglecting molecular viscosity at the exact edge.
For a polynomial of degree at least two, the filled Julia set consists of the points with bounded forward orbit. Choose an escape radius so that for . Then is compact, and its complement is the basin of infinity. On the interior all iterates are bounded by , so they form a normal family; on the complement they converge locally uniformly to infinity. At a boundary point, normality would give a subsequential limit equal to infinity on an open escaping part and hence identically infinity, contradicting the uniform bound at a nearby point of . Therefore .
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact