Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Conditional probability
Sibling recurrence risk 2026-10-13
Sibling recurrence risk is the conditional probability that another child has the disease, given an affected sibling. For unaffected parents, complete penetrance and a single recessive disease allele, the affected child identifies both parents as genetic carriers. Independent Mendelian segregation then gives recurrence probability , whether or not the parents are related. Incomplete penetrance, phenocopies, different causal loci or affected parents change this calculation.
// Target: biology.bigb
Simulated annealing Created 2026-10-14 Updated 2026-10-18
Simulated annealing accepts worse feasible solutions to escape a local minimum. Minimize an objective function , analogous to energy. Effective temperature has the same units as , absorbing the Boltzmann constant; it controls exploration, rather than a material's thermodynamic temperature.[ref]
Optimization by Simulated Annealing by Scott Kirkpatrick and others. Printed pp. 672–673: effective temperature and cost as energy
Given current feasible point , draw from a proposal distribution . For a symmetric proposal distribution, , use the Metropolis–Hastings acceptance probabilityAccept with this conditional probability; on rejection retain . Every downhill or equal-cost proposal is accepted. Draw a fresh uniform random variable on and accept if . The off-diagonal transition probability includes proposing .[ref]
Optimization by Simulated Annealing by Scott Kirkpatrick and others. Printed p. 672: acceptance rule and rejected proposals
For a maximization problem with objective function , set : every improving proposed neighbor is accepted, and a worsening move of loss has conditional probability of acceptance, under the same symmetry assumption. Likelihood-power annealing uses precisely this sign convention for a log-likelihood. Retain the best feasible solution seen, since the current state can worsen even after a global minimum has been visited.
If the proposal distribution is asymmetric, use the full Metropolis–Hastings acceptance probability, for ,A missing reverse proposal gives zero acceptance. Even a downhill proposal need not be accepted with probability one in this case. Choosing uniformly among a variable number of neighbors is generally asymmetric: and give the correction , where is vertex degree.[ref]
The useful idea is to separate exploring from insisting on improvement: an uphill move can open a route to a better feasible solution. Its usefulness depends on the proposal distribution, the scale of the objective function, and the cooling schedule for simulated annealing. Finite practical schedules carry no general guarantee of finding a global minimum.
Standardization with common weights 2026-10-25
Let be a group-specific conditional probability in stratum , and let with . Average each group's conditional probabilities using the same weights. ThenThis is a descriptive comparison under a common covariate composition. Its difference from a crude contrast need not be a causal effect. Causal outcome standardization additionally requires its identification assumptions.
Strongly universal hash family 2026-10-13
A strongly universal hash family makes every ordered pair of outputs equally likely: for distinct inputs and arbitrary specified outputs ,Thus the two outputs are independent random variables, each with the uniform distribution on a finite set. Adding the equal ordered pairs gives collision probability , so the family is also a universal hash family.
Here is a completely enumerable example. In the finite field , take the affine functions , using modular arithmetic modulo . Choose and as independent random variables, each with the uniform distribution on a finite set of all five finite field elements , including . There are equally likely hash functions. For , the ordered pair is . For instance gives ; gives . Every prescribed occurs exactly once, at .
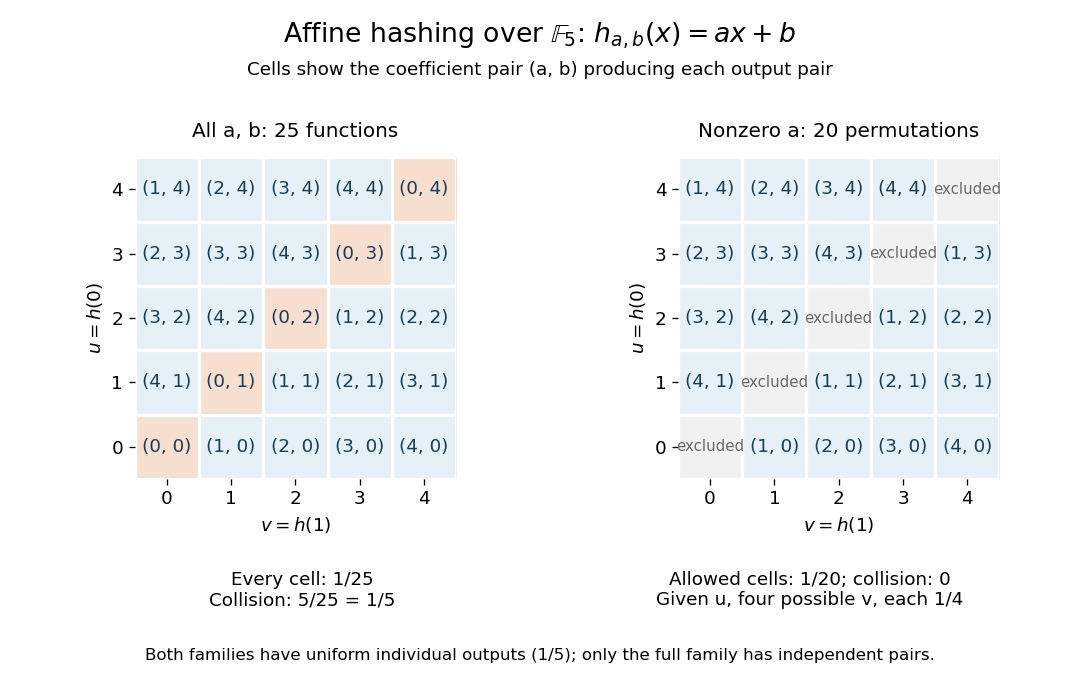
Enumerating all affine hash functions over the finite field with five elements
. Each cell shows the unique coefficient pair (a,b) producing the displayed outputs at 0 and 1. Removing a = 0 deletes the diagonal and leaves dependent outputs despite uniform individual values. Details.Each row contains five choices, so each individual output has probability . Each cell has probability , and the five diagonal cells give collision probability . For any distinct , the same conclusion follows from and : a nonzero finite field element has a unique inverse. This is the beauty of the construction: two small random coefficients provide exact pair balance without choosing five unrelated values.
The example uses equal-sized input and output sets to make every choice visible; it illustrates the family definitions rather than compression. In a larger input set, a hash function cannot avoid all collisions into five buckets. What a universal hash family controls is the fraction of its members that collide on each fixed pair, rather than the existence of any collision anywhere.
Restricting to leaves permutations with zero collision probability for distinct inputs. Individual outputs remain uniform, but given , the four values other than each have conditional probability and has zero. Hence these outputs are not independent random variables: this is a universal hash family but not a strongly universal hash family. Finally, the full -member example contains five constant functions, with immediately visible collisions. Its pair guarantee concerns a random choice of hash function, and makes no claim of cryptographic collision resistance.
Survival function Created 2026-09-24 Updated 2026-10-14
For a nonnegative survival time , the survival function iswhere is the cumulative distribution function. Thus is the probability that the chosen occurrence is still in the future at time . We consistently use the strict inequality : a probability mass at has already left the survival function at itself. With this convention is a right-continuous function and a nonincreasing function taking values in . If , then ; if is finite with probability one, then as .
For and , conditional probability givesFor example, and mean that of those still event-free at year two remain event-free through year five. Their intervening event probability is , whereas the original population's probability of an occurrence in is . Conditioning changes the denominator.
The area under the survival function up to a horizon gives the restricted mean survival time. A positive terminal plateau in a plotted Kaplan–Meier estimator does not establish that the occurrence will never happen: terminal censoring and survival-mean identifiability explains why the unobserved tail remains undetermined.
Tail probability Created 2026-10-03 Updated 2026-10-14
For a real random variable , an upper-tail probability has the form and a lower-tail probability has the form . Each is the probability of an event lying beyond a chosen threshold in one direction. A tail probability need not be small: the threshold determines how much of the probability distribution it includes. A concentration inequality bounds such probabilities, often for deviations from an expected value.
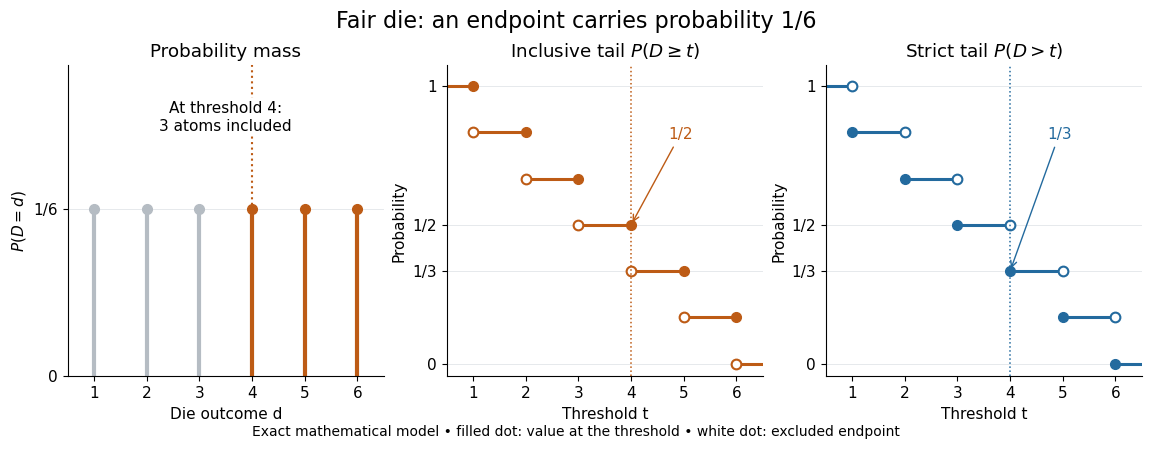
Endpoint conventions matter. Write for the cumulative distribution function and . The complement rule of probability gives four distinct formulas:The strict upper-tail convention is the survival function . Its value differs from the inclusive upper tail probability by exactly the probability mass at the threshold:A singleton with positive probability mass is an atom of a measure. Thus excludes an atom of a measure at , whereas includes it. These endpoint identities follow directly from the cumulative distribution function properties in Kyle Siegrist, Distribution and Quantile Functions: endpoint probabilities and right tails.
As the threshold increases, both upper tail probabilities are nonincreasing functions. The strict survival function is a right-continuous function; the inclusive upper tail probability takes the upper endpoint value at a downward jump, equal to the left limit of the survival function. Both tend to zero as for a real random variable, but the speed of that decay differs across probability distributions. The cumulative distribution function properties and their proof from continuity of probability measures are given in MIT 6.436J, Lecture 4: random variables and cumulative distribution function properties.
For a fair six-sided die , the discrete uniform distribution assigns probability mass to each of . At threshold four,Between four and five, both upper tail probabilities equal . At the largest possible outcome the distinction is especially visible: , but . The diagram shows exact probabilities for this mathematical model; its dots specify which endpoints belong to each step function.
If a probability distribution has a probability density function , then every singleton has zero probability mass andFor an exponential distribution of rate two, for and zero otherwise, so for and for . Hence . This tail probability is an integral of the probability density function, not its height . A mixed probability distribution retains endpoint jumps even with a smooth component: give zero probability mass and choose this exponential distribution with probability . Then , , and for .
A two-sided tail probability can measure the absolute value of displacement from a specified center . For , the two extreme events are disjoint events, soFor strict displacement , replace the last expression by . The condition prevents overlap; at adding inclusive tails double-counts any probability mass at . For a uniform distribution on , take and : the two tail probabilities are each and their sum is . Equal tails follow from this symmetric probability distribution, not from the phrase two-sided alone; for a uniform distribution on with , the two tail probabilities are zero and .
The tail-sum formula for expectation turns a whole curve of tail probabilities into an expected value. For any nonnegative random variable , without assuming a probability density function or a finite expected value,For a proof outline, write pointwise and exchange the expected value and Lebesgue integral using Tonelli theorem; is an indicator function. The inclusive version has the same Lebesgue integral: positive probability masses occur at only a countable set of thresholds, which has Lebesgue measure zero. For a nonnegative integer-valued random variable , the tail-sum formula instead gives . The integer hypothesis is essential for these sums. The integral identity, its indicator function proof, and the integer version appear in Kyle Siegrist, Additional Properties of Expected Value: integration and summation of right tails.
For the fair die, this tail-sum formula yields , equal to the direct weighted arithmetic mean . For the rate-two exponential distribution, the area under the survival function is , its expected value. The first panel below shades an integral of the probability density function for a single threshold; the second shades an integral of the survival function across all nonnegative thresholds. These are analytical illustrations, with the displayed curves truncated at three; their exact total areas use an infinite integration range.
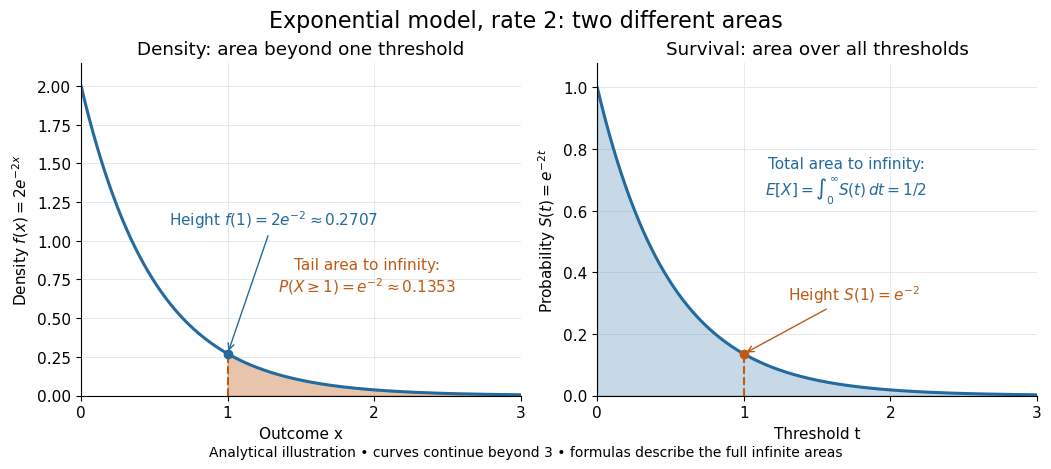


Nonnegativity is essential to interpreting the upper tail probability area as : for a general real random variable that area equals the expected value of its positive part. An integrable random variable satisfies , subtracting the expected value of its negative part; infinite terms cannot be canceled. Even when is finite almost surely, its expected value can be infinite. For the shape-one Pareto distribution on , on and for , so the area is . The finite versus infinite expected value distinction is illustrated in Kyle Siegrist, Definitions and Basic Properties: exponential and Pareto expected values.
Why are tail probabilities useful? They answer threshold questions directly, and a concentration inequality can bound them without knowing the full probability distribution. For nonnegative with finite expected value, Markov inequality gives for : a large threshold relative to the expected value forces rarity. The quantile function reverses the question by choosing a threshold for a prescribed cumulative level. If with , then ; an atom of a measure may prevent equality. For the die, , with strict upper tail probability zero and inclusive upper tail probability .
A tail probability describes rarity under a specified probability distribution; it is not automatically a conditional probability after extra information. For with ,because the threshold events are nested. Thus the die has but . Conditioning changes the sample space and renormalizes its probability measure; the same extreme outcomes can become common in that restricted population.
Three prisoners problem Created 2026-10-14 Updated 2026-10-31
A messenger names an excluded candidate while concealing the uniquely selected one. The conditional probability depends on the naming rule. With three equally likely selected candidates and a messenger forbidden to name the observing candidate A, let be the probability of naming B when A is selected. When C is selected the messenger must name B, and when B is selected cannot name B. Thus the probability that A is not selected, conditional on B being named, is . Unbiased naming has and leaves this probability ; bias toward B gives , and bias toward C gives one. Conditioning on the name is different from conditioning only on B's exclusion.
Type I and type II errors Created 2026-09-24 Updated 2026-10-25
For a null hypothesis , a type I error rejects when it is true, while a type II error does not reject when the alternative is true. If a test does not reject on an event , their conditional probabilities are and . Nonrejection does not establish the truth of the null hypothesis.