The Laplace distribution, also called the double exponential distribution, is a location-scale family with probability density functionThe location is its mean, median and mode; controls its spread. In the centred rate convention, the same law has and , giving . Keeping track of whether a parameter is a scale or its reciprocal prevents reversing the effect of increasing it. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Probability Density Function and Common Statistics; NIST denotes the scale by beta
The two halves of the probability density function are reflected exponential decay curves, each with total probability . Their meeting point has a sharp corner: the left and right derivatives are and . This finite peak is not a positive probability mass at . Indeedso , just as for any absolutely continuous probability distribution.
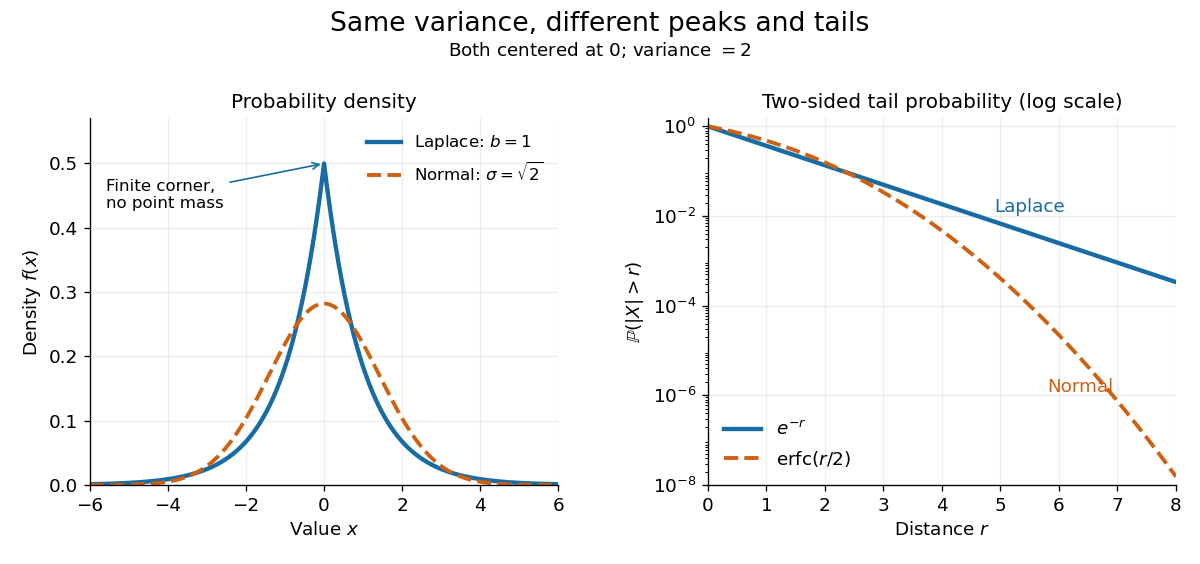
The figure compares a Laplace distribution with , against a normal distribution with mean zero and standard deviation : both have variance 2. The right panel uses a logarithmic scale for the two-sided tail probability . Its straight Laplace distribution curve comes from ; the normal distribution tail falls faster. Thus values far from the center can be more plausible under a Laplace distribution even after matching the variance. These are theoretical curves, not measured frequencies. The tails still have exponential decay; this is not a heavy-tailed distribution in the convention requiring every positive exponential moment to diverge.
Integrating either half of the probability density function gives the cumulative distribution functionIn particular . The basic moments areThus the scale is the expected value of the absolute distance from the center, and is not the standard deviation. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Cumulative Distribution Function and Common Statistics; rescale the standard form by x=mu+bz
A short way to obtain the moments is to note that has an exponential distribution with rate : for . Integrating gives and ; the symmetric distribution gives the centered first moment zero.For a random variable with probability density function , the event is for . Integrating the symmetric density gives the displayed cumulative distribution function; it is zero for negative . The density on is . Its integrable singularity at zero does not create an atom, because the cumulative distribution function is continuous there.
For an independent and identically distributed Laplace distribution sample with density and known rate , the sample mean has mean and variance . The central limit theorem gives the displayed asymptotic confidence interval for at confidence level . The sample mean need not be a maximum-likelihood estimator for this construction to be valid. The Laplace location and scale maximum likelihood location is a sample median; that is a different choice of statistic.
Suppose , , are independent and identically distributed with Laplace distribution , where . For realized values , the likelihood function and log-likelihood function areFor fixed , maximum likelihood estimation of the location therefore minimizes the sum of absolute losses. This connects the Laplace distribution to robust statistics: each observation contributes a cost growing linearly with its distance, whereas squared-error loss grows quadratically.
Why does a sample median minimize ? Between successive order statistics, moving a little to the right increases each distance to a value on the left and decreases each distance to a value on the right. Hence the slope is the number on the left minus the number on the right. It changes from negative to positive at the middle. More precisely, if , all minimizing locations areFor an even sample size, the objective is flat throughout the interval between the two central order statistics. The midpoint convention for the sample median selects one solution; it does not prove uniqueness. [ref]
Laplace (Double Exponential, Bilateral Exponential) Distribution. SciPy 1.18.0 documentation; SciPy reference guide, Laplace distribution, ML location estimator and the even-N interval between the two central order statistics
This is the finite-sample counterpart of median minimizes expected absolute loss.If , maximizing over givesThe derivative is positive below this value and negative above it. Moreover the maximized likelihood function is proportional to wherever , so the same minimizing locations give the joint maximum-likelihood estimates. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Parameter Estimation; median and average absolute deviation formulas
The scale estimate divides by ; this formula is not an assertion that it is an unbiased estimator.The boundary case matters: if all observations equal , choose . Then and as . There is no finite joint maximum-likelihood estimate in the parameter space . In particular, this always occurs for . Writing does not produce an admissible Laplace distribution.
Choose the five numbers as an original illustration. Their sample median is 2 and their sample mean is 4. The sum of absolute losses at the sample median isIf these numbers were modeled as an independent and identically distributed Laplace distribution sample, the joint maximum-likelihood estimates would therefore be and . Using the sample mean instead gives , so it does not maximize this likelihood function.
Now replace only 10 by 100. The sample median stays at 2, while the sample mean becomes . The minimized sum of absolute losses rises to , and the fitted scale rises to . Stability of the fitted location therefore does not mean stability of every fitted parameter.
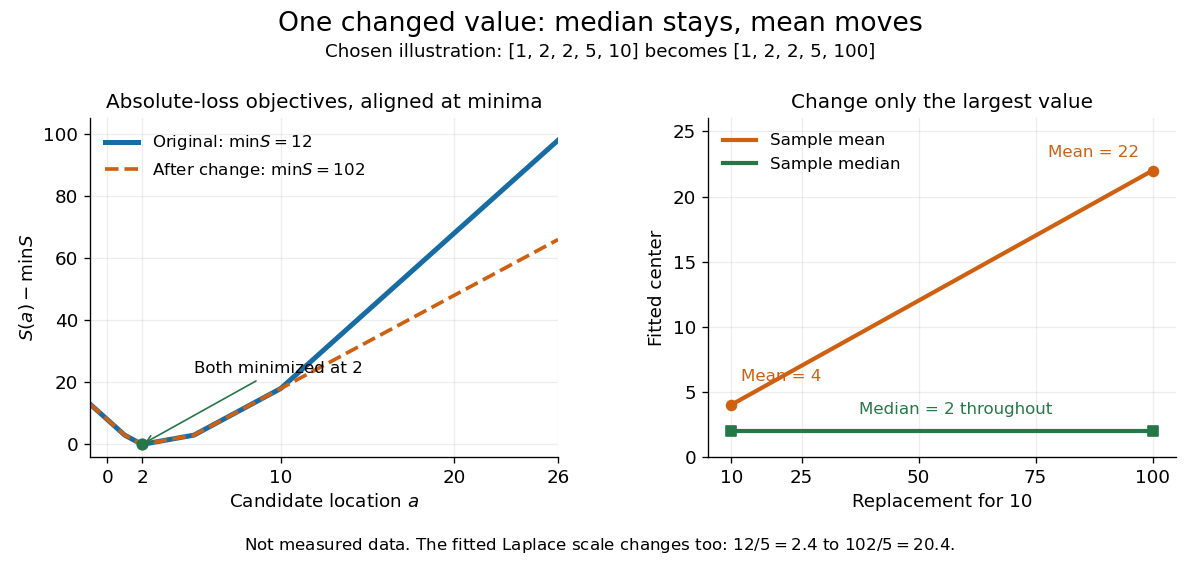


The left panel subtracts each objective's minimum so the two absolute loss curves can be compared despite the different totals. The right panel tracks the sample mean and sample median as the largest chosen value changes. This is an outlier sensitivity illustration, not actual observations or a check that a Laplace distribution fits any population. In applications, regression residuals and the data-generating assumptions need separate examination; a stable sample median alone does not validate a statistical model.
Independent centered Laplace distributions for pixel intensities give the prior distributionThis prior favors small intensities through its sharp peak at zero, while its tails permit isolated appreciable pixels. Its negative log density is an L1 norm penalty, so with a Gaussian likelihood a maximum a posteriori estimate minimizes a sum of squared residuals plus that penalty. A draw from this continuous prior has no exactly zero coordinate with positive probability; sparsity of a maximizing estimate and concentration of prior mass near zero are different statements. The product prior also does not encode spatial contiguity. Inverse transform sampling produces each coordinate from an independent uniform distribution by for and otherwise, ignoring the probability-zero endpoints.
For linear regression with fixed predictor vectors , assume conditionally independent responses with a common scale :Each conditional median and mean is . The log-likelihood function is , so maximum likelihood estimation minimizes the sum of absolute regression residuals:This is least absolute deviations. With only an intercept, it reduces to the Laplace location and scale maximum likelihood problem, so a sample median is a fitted intercept. Provided the minimum , the scale estimate is ; the conditional standard deviation is . If the scale is denoted instead of , the conditional standard deviation is .
Minimizing a sum of absolute losses does not automatically give a unique coefficient vector. Even an intercept-only fit to an even sample size can have an interval of solutions, and redundant predictor columns can introduce further nonuniqueness. If a fit makes every regression residual zero, the joint likelihood function is unbounded as , so there is no finite joint maximum-likelihood estimate with positive scale.
The linear growth of absolute loss limits sensitivity to an extreme response at fixed predictors compared with squared-error loss. It does not protect against every outlier: an extreme predictor can have large regression leverage. The numerical example above changes a response in an intercept-only problem, and makes no general claim of immunity to such predictor changes.
Articles by others on the same topic
There are currently no matching articles.