Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Laplace distribution
For an independent and identically distributed Laplace distribution sample with density and known rate , the sample mean has mean and variance . The central limit theorem gives the displayed asymptotic confidence interval for at confidence level . The sample mean need not be a maximum-likelihood estimator for this construction to be valid. The Laplace location and scale maximum likelihood location is a sample median; that is a different choice of statistic.
Laplace distribution Created 2026-09-24 Updated 2026-10-18
The Laplace distribution, also called the double exponential distribution, is a location-scale family with probability density functionThe location is its mean, median and mode; controls its spread. In the centred rate convention, the same law has and , giving . Keeping track of whether a parameter is a scale or its reciprocal prevents reversing the effect of increasing it. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Probability Density Function and Common Statistics; NIST denotes the scale by beta
The two halves of the probability density function are reflected exponential decay curves, each with total probability . Their meeting point has a sharp corner: the left and right derivatives are and . This finite peak is not a positive probability mass at . Indeedso , just as for any absolutely continuous probability distribution.
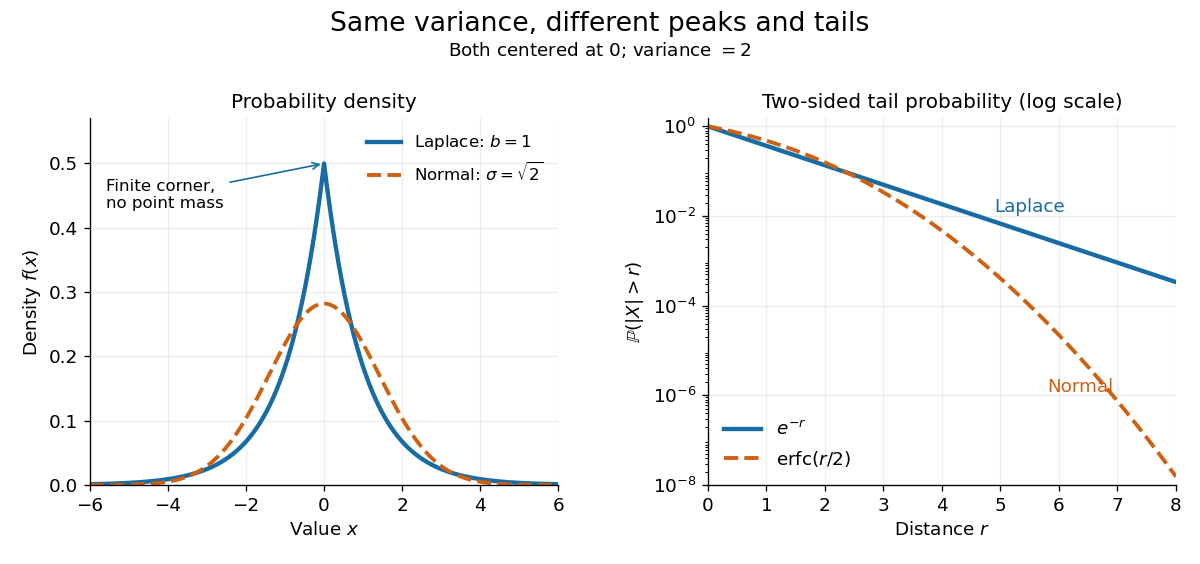
The figure compares a Laplace distribution with , against a normal distribution with mean zero and standard deviation : both have variance 2. The right panel uses a logarithmic scale for the two-sided tail probability . Its straight Laplace distribution curve comes from ; the normal distribution tail falls faster. Thus values far from the center can be more plausible under a Laplace distribution even after matching the variance. These are theoretical curves, not measured frequencies. The tails still have exponential decay; this is not a heavy-tailed distribution in the convention requiring every positive exponential moment to diverge.
Integrating either half of the probability density function gives the cumulative distribution functionIn particular . The basic moments areThus the scale is the expected value of the absolute distance from the center, and is not the standard deviation. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Cumulative Distribution Function and Common Statistics; rescale the standard form by x=mu+bz
A short way to obtain the moments is to note that has an exponential distribution with rate : for . Integrating gives and ; the symmetric distribution gives the centered first moment zero. Laplace location and scale maximum likelihood Created 2026-10-18 Updated 2026-10-25
Suppose , , are independent and identically distributed with Laplace distribution , where . For realized values , the likelihood function and log-likelihood function areFor fixed , maximum likelihood estimation of the location therefore minimizes the sum of absolute losses. This connects the Laplace distribution to robust statistics: each observation contributes a cost growing linearly with its distance, whereas squared-error loss grows quadratically.
Why does a sample median minimize ? Between successive order statistics, moving a little to the right increases each distance to a value on the left and decreases each distance to a value on the right. Hence the slope is the number on the left minus the number on the right. It changes from negative to positive at the middle. More precisely, if , all minimizing locations areFor an even sample size, the objective is flat throughout the interval between the two central order statistics. The midpoint convention for the sample median selects one solution; it does not prove uniqueness. [ref]
Laplace (Double Exponential, Bilateral Exponential) Distribution. SciPy 1.18.0 documentation; SciPy reference guide, Laplace distribution, ML location estimator and the even-N interval between the two central order statistics
This is the finite-sample counterpart of median minimizes expected absolute loss.If , maximizing over givesThe derivative is positive below this value and negative above it. Moreover the maximized likelihood function is proportional to wherever , so the same minimizing locations give the joint maximum-likelihood estimates. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Parameter Estimation; median and average absolute deviation formulas
The scale estimate divides by ; this formula is not an assertion that it is an unbiased estimator.The boundary case matters: if all observations equal , choose . Then and as . There is no finite joint maximum-likelihood estimate in the parameter space . In particular, this always occurs for . Writing does not produce an admissible Laplace distribution.
Laplace median robustness example 2026-10-18
Choose the five numbers as an original illustration. Their sample median is 2 and their sample mean is 4. The sum of absolute losses at the sample median isIf these numbers were modeled as an independent and identically distributed Laplace distribution sample, the joint maximum-likelihood estimates would therefore be and . Using the sample mean instead gives , so it does not maximize this likelihood function.
Now replace only 10 by 100. The sample median stays at 2, while the sample mean becomes . The minimized sum of absolute losses rises to , and the fitted scale rises to . Stability of the fitted location therefore does not mean stability of every fitted parameter.
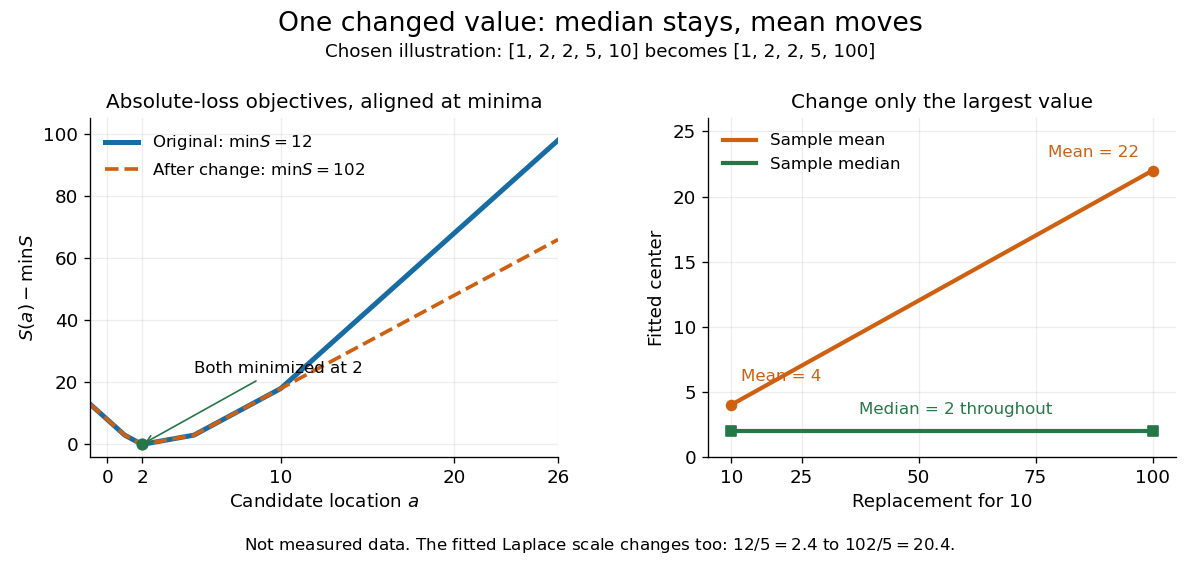
The left panel subtracts each objective's minimum so the two absolute loss curves can be compared despite the different totals. The right panel tracks the sample mean and sample median as the largest chosen value changes. This is an outlier sensitivity illustration, not actual observations or a check that a Laplace distribution fits any population. In applications, regression residuals and the data-generating assumptions need separate examination; a stable sample median alone does not validate a statistical model.
Laplace prior for sparse images Created 2026-10-05 Updated 2026-10-18
Independent centered Laplace distributions for pixel intensities give the prior distributionThis prior favors small intensities through its sharp peak at zero, while its tails permit isolated appreciable pixels. Its negative log density is an L1 norm penalty, so with a Gaussian likelihood a maximum a posteriori estimate minimizes a sum of squared residuals plus that penalty. A draw from this continuous prior has no exactly zero coordinate with positive probability; sparsity of a maximizing estimate and concentration of prior mass near zero are different statements. The product prior also does not encode spatial contiguity. Inverse transform sampling produces each coordinate from an independent uniform distribution by for and otherwise, ignoring the probability-zero endpoints.
Laplace ratio-of-uniforms envelope 2026-10-14
For the unnormalized Laplace distribution probability density function , the ratio-of-uniforms method uses . The maximum of is one. On , the maximum of occurs at and equals . On , it occurs at and equals . Thus the displayed rectangle contains the region. Its area is , while the target region has area . Uniform proposals in the rectangle, accepted when , therefore return the correct Laplace distribution with acceptance probability .
For , the Lévy process with characteristic function has zero Gaussian coefficient, zero uncompensated drift, and the displayed Lévy measure. Indeed, the symmetric jump integral is . Differentiating in gives , and integrating back from zero gives . The time-one law is the Laplace distribution of rate . The jump activity is infinite, since has infinite mass near zero, but the jump variation is finite because .
Moreau smoothing of a negative log-density 2026-10-06
For a proper convex function with sequential lower semicontinuity , form with . The Moreau envelope theorem gives . If is integrable, it defines a smooth surrogate probability density function. Infimizing the logarithm of a probability density function with a positive quadratic penalty has the opposite sign and does not generally smooth it. For the Laplace distribution, that incorrect operation leaves , which is not differentiable at zero.
Most powerful test for a Laplace location shift Created 2026-10-14 Updated 2026-10-25
For two unit-scale Laplace distributions with locations , the likelihood ratio is nondecreasing in , with constant tails and an increasing middle interval. Therefore an upper-tail statistical test of exact size of a statistical test is a most powerful test. Its cutoff is for , and otherwise. Under location , its statistical power is if , and otherwise. Constant likelihood ratio tails can make the most powerful test nonunique.
Pareto distribution Created 2026-10-07 Updated 2026-10-18
The Pareto distribution describes a positive random variable whose tail probability falls as a power law. In the shape–minimum convention used here, has shape parameter and minimum , with probability support . Its probability density function isThe minimum has the same units as ; the shape parameter is dimensionless. At fixed , changing gives a scale family, since . This convention is also used in uniform-Pareto conjugacy.[ref]
Pareto Probability Density Function. NIST Dataplot Reference Manual; Description: standard Pareto density and lower bound; source gamma,a correspond to alpha,beta here
The survival function and cumulative distribution function areFor , solving gives the quantile functionIts right-hand limit at is ; it tends to infinity as .[ref]
The Pareto Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Pareto Distribution, Distribution Functions: density, CDF and quantiles; source a,b correspond to alpha,beta here
There is no probability mass at : changing a probability density function's value at that single point changes no probabilities.Choose and as an original theoretical example. Then , , the median is , and the 0.99 quantile is . These chosen values and all figures below describe mathematical probability distributions, not actual wealth observations.
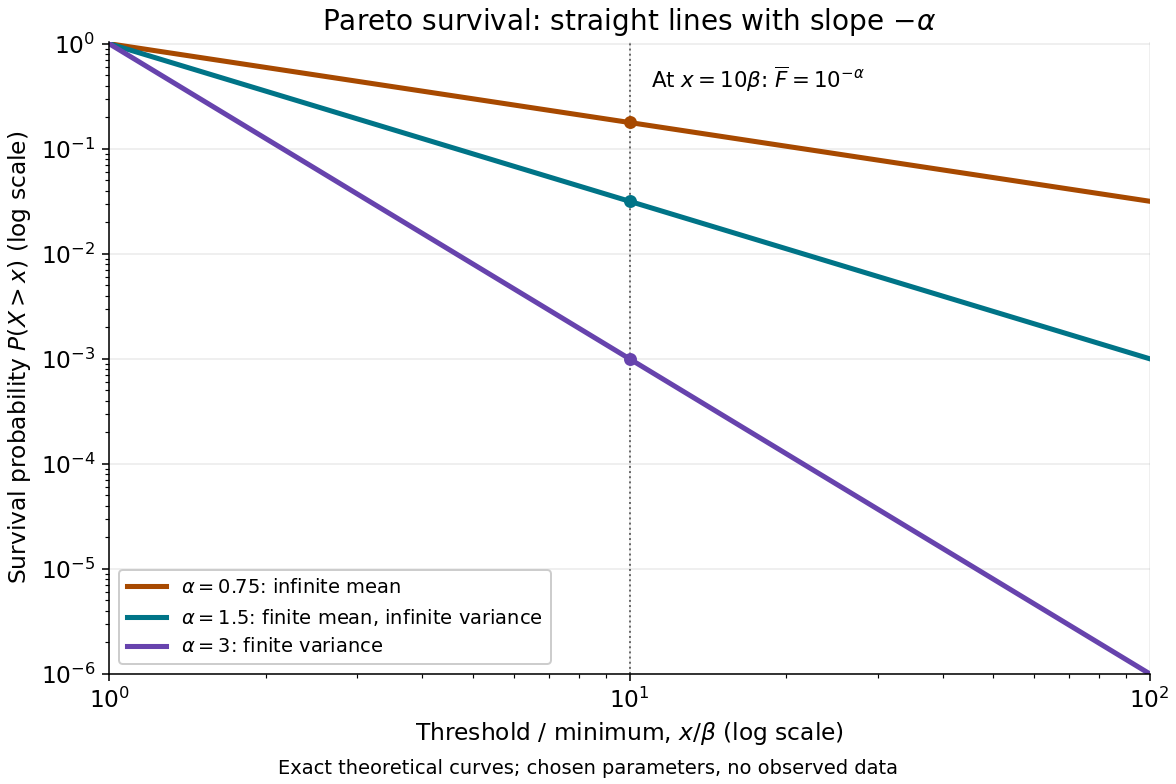
On this log-log plot, write to obtain . The slope is , whereas the probability density function has power exponent . Multiplying a threshold by ten divides its tail probability by . A larger therefore concentrates the Pareto distribution nearer ; a smaller makes extreme values more plausible. This exact scaling is useful when modelling large positive losses or sizes over several orders of magnitude.
The Pareto distribution is a heavy-tailed distribution: for every , the exponential moment diverges because eventually grows without bound. In contrast, the Laplace distribution has exponentially decreasing tails and some finite positive exponential moments. The Student's t-distribution also has power tails, but on both sides of the real line, with a smooth central region rather than a positive minimum.
Past exam of the mathematical methods II course of the University of Oxford 2019 4 Solution 2026-10-25
For a continuous random variable with probability density function , its cumulative distribution function isConsequently wherever the density is continuous, and almost everywhere for an absolutely continuous distribution.
Here . Thus for . For , the event is . Symmetry of the Laplace distribution givesTherefore the square of a standard Laplace variable has cumulative distribution functionIt is continuous at zero, so there is no point mass there. As a check, its probability density function for is , whose integral becomes after setting .
Past exam of the mathematics course of the University of Cambridge 2001 iii Paper 32 3 ii Solution Created 2026-10-03 Updated 2026-10-14
For the unit-scale Laplace distribution, integrating separately over the two half-lines gives the moment-generating functionfor ; the appropriate half-line integral diverges outside that interval. ThereforeIts derivatives needed for the saddlepoint density approximation areSet . Solving and selecting the root in gives the stable formulaincluding at . The other quadratic root is outside the domain. At the correct saddlepoint,Substitution gives the saddlepoint density of a Laplace sample mean:It is symmetric in , as the underlying Laplace distribution requires. At zero its value is , consistent with the local normal approximation having variance . This is an approximation, not an exact finite- density or an automatically normalized one.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 40 1 a iv Solution Created 2026-10-03 Updated 2026-10-14
Independently generate uniform on and uniform on , using the bounds above. Accept the proposal ifotherwise generate a fresh pair. On acceptance return . The bounding rectangle contains the entire ratio region: , and lies between the extrema of . Conditioning a uniform rectangle point on acceptance makes it uniform on , so the preceding marginal distribution calculation proves that the returned value has the desired Laplace distribution.
For this target , so the region has area two. The rejection sampling acceptance probability isEndpoints have zero probability and can be excluded to avoid divisions by zero in implementation.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 40 1 b ii Solution Created 2026-10-03 Updated 2026-10-14
Integration of the Laplace distribution probability density function givesSolving these two equations for givesGenerate one uniform and return this piecewise expression. The branches agree at and the inverse transform sampling proof establishes the target law without any rejection step.
Past exam of the mathematics course of the University of Cambridge 2004 ib Paper 2 21H Solution Created 2026-09-24 Updated 2026-10-14
A simple hypothesis specifies one probability distribution. Let the null hypothesis and alternative have probability density functions with respect to a common measure. A possibly randomized statistical test is a measurable function , its conditional probability of rejecting the null hypothesis. Its size of a statistical test is , and its statistical power at the alternative is . A most powerful test at level maximizes power among tests with size at most .
The Neyman-Pearson lemma says to choose and a test of size with where and where , choosing values on the equality set to reach the specified size. Equivalently, threshold the likelihood ratio, treating positive alternative density with zero null density as an infinite ratio. Randomization on a threshold atom ensures exact size when needed. If , all remaining null-only mass can be used to reach size without changing power.
For any test of size at most , the signs of the two factors givepointwise. Integrating provesThis is the required optimality proof. If and another test is equally powerful, both inequalities must be equalities. It must have size and agree with wherever , apart from null sets for the relevant densities. Thus freedom is confined to the equality set and sets null under both hypotheses; at , additional size need not improve power. This also explains the nonuniqueness below.
For the unit-scale Laplace distribution, put . Its likelihood ratio isIt is nondecreasing, so an upper-tail critical region has the Neyman-Pearson lemma form, even if the cutoff lies inside a constant-ratio tail. Solving gives the most powerful test for a Laplace location shift,Continuity of the distribution makes this nonrandomized test exactly size . It need not be the unique most powerful test: within a flat extreme likelihood ratio region, other selections having the same null probability are equally good.
Its statistical power isHere denotes power, not the probability of a type-II error. For , . Thus the power is for , and otherwise. The first branch is at most . On the second branch, power at least is equivalent to . Therefore the required pairs are exactly , with no restriction on the common location.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 42 3 Solution Created 2026-10-03 Updated 2026-10-14
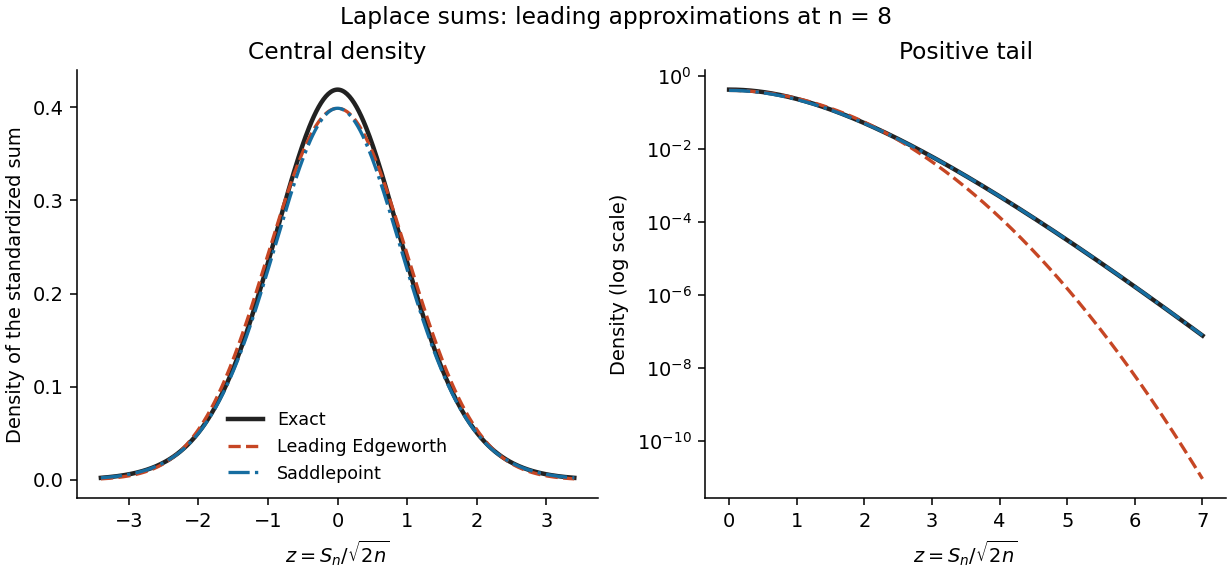
Let the summands have mean mu, variance , and cumulants . For the standardized sum , expansion of its log-characteristic function gives a normal leading term and successively smaller cumulant terms. Fourier inversion turns these terms into Probabilists' Hermite polynomials. Under sufficient moments and a smooth nonlattice condition, the Edgeworth expansion beginsfor bounded z. Higher orders include the fourth cumulant and products of lower cumulants. This is a central expansion in powers of ; it need not remain positive, normalized, or accurate in far tails after truncation.
For a saddlepoint density approximation, require the summand cumulant-generating function K to be finite on an interval about zero. At a sum value , find the interior saddle satisfying . Exponential tilting makes the tilted mean y, so the tilted sum is approximated locally by its normal probability density at its mean. Undoing the tilt givesEquivalently this follows by deforming the transform-inversion contour through its stationary point. Suitable analytic and nonlattice regularity gives relative error at fixed interior y. This approximation incorporates a nonquadratic tail exponent and is positive, while an Edgeworth truncation uses a normal probability density times a polynomial. It uses more information from the distribution and stronger exponential-moment assumptions. Its integral may differ from one by a higher-order amount, so positivity does not imply exact normalization.
For the centered Laplace distribution, , hence and . Its skewness vanishes, so the order- Edgeworth correction is zero. With , the requested expansion, omitting terms of order in the standardized correction, isFor bounded z the exact probability density function is this expression times . The prefactor is because this is the probability density function of the unstandardized sum; that change of units should not be confused with the orders inside the Edgeworth expansion.
For the saddlepoint, . Write and . The root in isThese formulas include without a division by y. Substitution yieldsThis is the leading saddlepoint approximation, without its order- relative correction. Expanding d near one recovers the same central normal approximation, while retaining d captures the Laplace-sum large-deviation exponent away from the center.


Past exam of the mathematics course of the University of Cambridge 2007 ii Paper 2 5I Solution Created 2026-09-24 Updated 2026-10-14
The independent Laplace distribution responses have log likelihoodFor every fixed positive , maximizing this expression means minimizing the sum of absolute residuals. Thus is a least absolute deviations estimate, not a least-squares estimate. Such a minimizer exists: minimize the distance in the finite-dimensional closed column space of the design matrix. It need not be unique if the data or design allow multiple minimizers.
Write . For , differentiating the profiled log likelihood gives . Its unique maximum isIf the fitted residual sum is zero, the likelihood instead increases without bound as : there is no joint maximum with the stated positive scale parameter. The displayed estimate then denotes the boundary limit, not an admissible positive-scale MLE.
An ordinary exponential dispersion family has log density , so changing the mean changes the log density by an affine function of . For two distinct Laplace locations , their log-density difference is , with different slopes on the intervals separated by the two locations. It is not affine in . Equivalently the kink at moves with the parameter. The Laplace location family is not an ordinary exponential dispersion family.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 47 3 b i Solution Created 2026-10-03 Updated 2026-10-14
For rate , the exponential distribution has cumulative distribution function on . Inverse transform sampling gives ; since is also uniform, an equivalent answer isFor , , verifying the exponential distribution directly.
The centered Laplace distribution with density can be obtained by multiplying by an independent sign taking and with equal probabilities. Alternatively, its inverse transform sampling formula uses just one uniform variate:The first branch inverts the negative half of the cumulative distribution function and the second branch inverts the positive half. Add a location parameter if a noncentered Laplace distribution is wanted.
Correct uniformity is essential for each marginal distribution, and independence is essential for independent samples and for the sign construction. For example, setting every equal to a single uniform gives uniform marginals but identical transformed draws. Likewise, choosing a sign from the same uniform used for the magnitude can change the Laplace distribution unless the one-uniform inverse above is used.
Past exam of the mathematics course of the University of Cambridge 2015 iii Paper 37 4 c iii Solution Created 2026-10-03 Updated 2026-10-06
Recognize the integrand as a Gaussian scale mixture. If has the unit Rayleigh distribution and is an independent standard normal distribution variable, then the conditional density of given is . Multiplying by the radius density givesThus use for the independent radius and for the normal output of the Box-Muller transform:The mixture argument also proves that integrates to one, by the Tonelli theorem. As a check, is exponential of rate , so the characteristic function of is . This is the Rayleigh-normal scale mixture, with Laplace distribution density .
Past exam of the mathematics course of the University of Cambridge 2015 ii Paper 4 26K ii Solution Created 2026-09-24 Updated 2026-10-06
Here and . The asset payoff has a centered Laplace distribution. Its moment-generating function is for , and diverges otherwise. Expected constant absolute risk aversion utility for a holding isTo maximize it, minimize the logarithm of the positive factor on . Its derivative is , and its second derivative is strictly positive. It diverges at the endpoints, so the unique critical point is the global optimizer:At use the continuous limit . The other quadratic root is outside the finite-utility domain.
Let . Aggregate demand is . Unit positive supply requires and . Squaring and excluding givesThis negative price satisfies the unsquared equation and every individual finite-utility constraint. When , there is no finite clearing price. Indeed for every finite negative , with limit as . If this maximum limiting demand is below supply; if equal, demand only approaches one at an infinitely negative price. A formal positive solution obtained by squaring when violates the original demand equation.