Source release: Oxford examination archive, member
FOI-20210708-1 - Data/a13759w1 (4).pdf. The cover dates the examination to 26 June 2015.Answer availability checked on 28 October 2026: a bounded search of official Oxford sources found no advertisement of complete or selected-part solutions for this exact paper. Oxford's stated policy excludes odd examination years apart from the exceptional release for 2019.[ref]
https://www.maths.ox.ac.uk/members/students/undergraduate-courses/examinations-assessments/overview-examinations. Mathematical Institute, “Past papers and model solutions”: release policy for odd examination years and the 2019 exception
For , the one-panel trapezoidal rule isIt integrates the linear interpolation between the two endpoint samples. Indeed the affine functionhas definite integral . The two quadrature nodes are and both quadrature weights are .
It suffices to assume . The polynomial interpolation error for the endpoint linear interpolant gives, for every interior , some withLet , which exists by continuity of the second derivative and the extreme value theorem. Since ,Integrating this pointwise inequality and using the triangle inequality for an integral yieldsThusThis derivation does not require choosing as a continuous function of ; the pointwise upper bound is sufficient.
The constant is sharp. Take the quadratic polynomial and write . Its exact integral is , its trapezoidal rule value is , and . ConsequentlyEquality holds, so no smaller universal constant than works under these assumptions. This is the sharp one-panel trapezoidal error bound.
The trapezoidal rule is exact for every affine function , equivalently every polynomial of polynomial degree at most one: the linear interpolant is the function itself. These functions have , so the preceding upper bound is also zero. There is no contradiction: zero error is precisely what the bound predicts.
The degree of precision of a quadrature rule is one, since the quadratic polynomial in part (i) is not integrated exactly. This does not exclude exactness for particular higher-degree or nonpolynomial functions. For example , , has zero integral and opposite endpoint values, so the trapezoidal rule also gives zero. Its second derivative is generally nonzero, making the upper bound positive; an upper bound need not be attained. Signed quadrature error can cancel.
On a partition of an interval , apply the trapezoidal rule separately to each panel and add:For uniform spacing , this composite trapezoidal rule becomesEach interior sample occurs in two panels; their half-quadrature weights combine to . The endpoint quadrature weights are .
For every uniform partition of an interval with panels, the quadrature nodes satisfy . Their composite trapezoidal rule quadrature weights agree, so the two sampled sine values cancel. If there is a node at zero its sine value is already zero. The constant term is integrated exactly, givingThis is symmetric trapezoidal exactness for odd functions, applied after adding a constant function so that the resulting definite integral is nonzero. It is exactness for this particular integrand, rather than a claim that every nonpolynomial function is integrated exactly.
Write for the supplied approximation. The asymptotic expansion iswhere is Big O notation. At the refined parameter ,Multiply this identity by nine and subtract the first one. The unknown leading truncation error coefficient cancels:Thus the Richardson extrapolation estimate isThe two supplied values giveThe correction to the finer approximation is . Neglecting the higher-order remainder would also give .
The conclusion is asymptotic: the leading error order improves from two to at least three when both parameter values are in the range of the stated asymptotic expansion. With no bound on the remainder constant, the two finite observations alone do not guarantee that is closer to . Indeed, for any proposed value , the polynomial modelsatisfies , and the required asymptotic expansion with true limit . This is why finite observations do not certify Richardson extrapolation accuracy: asymptotic cancellation provides an improved-order estimator, while a numerical error certificate needs quantitative remainder information.
The polynomial interpolates at the interpolation nodes whenFor distinct interpolation nodes, define the Lagrange cardinal polynomialsThe denominators are nonzero, each polynomial degree is at most , and , with the Kronecker delta. Thereforeis a Lagrange interpolation polynomial belonging to the vector space of univariate polynomials , and it has all the required sampled values.
If also works, has distinct roots of a polynomial while its polynomial degree is at most . The root bound for a polynomial forces it to be the zero polynomial, proving uniqueness. The phrase “degree ” denotes the allowed maximum; the actual polynomial degree may be smaller. No continuity assumption is needed merely to construct the interpolation polynomial from these finitely many values.
Assume and set , a monic polynomial of polynomial degree . Fix distinct from all the interpolation nodes, and chooseThe auxiliary functionvanishes at the distinct points . Order those points and repeatedly apply Rolle's theorem. After applications, there is some strictly between their smallest and largest values, hence in , such that .
Because has polynomial degree at most and is monic of polynomial degree ,Substituting the resulting value of proves the polynomial interpolation error formulaAt an interpolation node, both sides are zero, so any works. Such an interior point exists because and the interpolation nodes are distinct. The selected generally depends on ; the theorem makes an existence assertion, not a regularity assertion about that dependence.
Assume and reorder the interpolation nodes increasingly as . The polynomial interpolation error vanishes at all of them. Rolle's theorem suppliesThese points are distinct because their containing intervals are disjoint. Thus is a polynomial of polynomial degree at most that interpolates the function at the interpolation nodes .
Apply the polynomial interpolation error theorem to with these interpolation nodes. Since the th derivative of is , for every there is a withFor the equality is zero on both sides; otherwise the same auxiliary-function and repeated-Rolle's theorem proof applies. This also covers , where is a constant polynomial and the proof is the ordinary mean value theorem for .
Writing gives the genuine error boundThe first formula is sharper, but its intermediate interpolation nodes depend on ; the last bound eliminates those unknown locations. This is derivative interpolation error from Rolle points.
The remainder in part (b) involves an unspecified . Its existence for every does not ensure a differentiable selection. Even if such a selection existed and had an additional derivative, the product rule and chain rule would giveThe first term cannot be discarded or bounded from the given information. Neither nor is supplied by the original theorem.
For an explicit demonstration, interpolate the cubic polynomial at zero and one. Then , andDifferentiating correctly givesTreating the remainder coefficient as a constant would omit and give a wrong answer at every interior point. An existential intermediate point cannot be frozen when differentiating. Part (i) instead applies Rolle's theorem directly to the polynomial interpolation error.
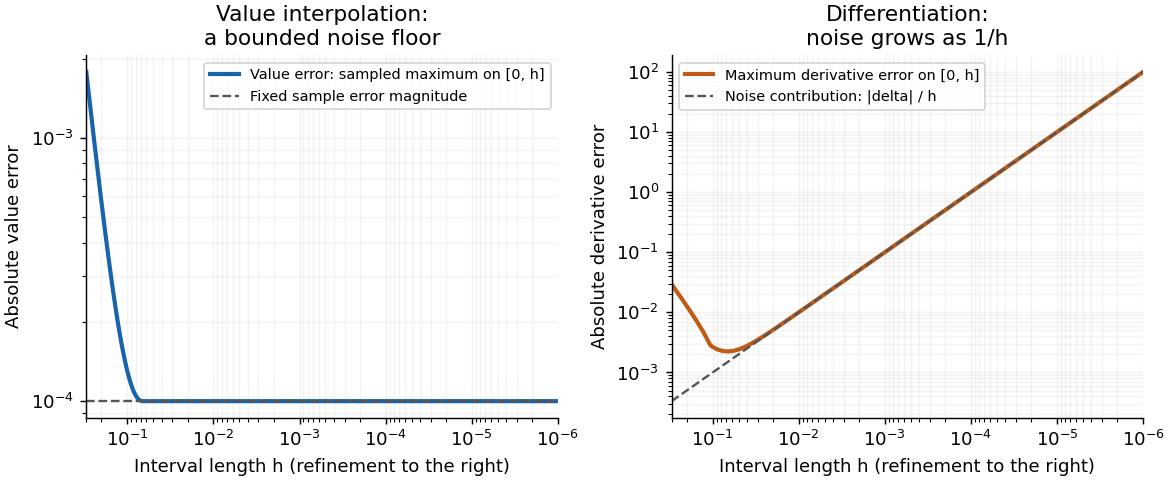
Write and for the quantities computed from the perturbed second sample. The endpoint linear interpolation and its derivative areCompare them on their interpolation interval , with fixed . Put , . The Taylor series of the sine gives, uniformly in ,Here the second equality compares with . More generally, the exact derivative is andThe input perturbation itself changes the value interpolant by exactly , and changes its derivative by exactly . ThusFor fixed nonzero , the value approximation has a bounded noise floor: its maximum error approaches , and at that error is exactly . It does not converge uniformly to the exact values as . However, it does not amplify the absolute sample perturbation on . The derivative error instead grows without bound like .
With exact samples, , both approximations do converge on the shrinking interval: the value error is for this particular sine, and the derivative error is . With step-dependent noise, value convergence requires , whereas derivative convergence requires the stronger , where denotes little o notation.
This is noise amplification by differentiation of a linear interpolant. Value interpolation has an absolute perturbation bound independent of on the sampled interval. Numerical differentiation has a perturbation factor , expressing the ill-posedness of numerical differentiation from values with fixed absolute uncertainty. The amplification follows from the mathematical data map even in exact arithmetic; it is distinct from additional roundoff error in a particular implementation. For fixed outside , the operation becomes extrapolation, and the value perturbation can also diverge.

A real square matrix is an orthogonal matrix when , equivalently its columns form an orthonormal basis. Here is the transpose and the identity matrix. For every vector ,Taking nonnegative square roots provesThus an orthogonal matrix preserves the Euclidean norm.
Since , the QR factorization givesFirst compute by a matrix-vector product, costing scalar multiplications and additions for dense . Then solve the upper triangular matrix system by back substitution:Every denominator is nonzero because is invertible. The back substitution costs multiplications and subtractions together, plus divisions, for arithmetic operations. Including , the total is arithmetic operations under this scalar counting convention, hence , with denoting Big O notation. The already supplied QR factorization is reused; no matrix inverse needs to be computed.
Choose the following consistent sign convention. The Givens rotation equals the identity matrix except for the block on coordinates :Thus it changes only the th and th coordinates of a vector. Write , . Its two-coordinate block satisfiesAll remaining coordinates are unchanged, so . Hence every such Givens rotation is an orthogonal matrix. With this convention the two-coordinate rotation matrix rotates through angle .
Let . If , choose so thatSuch an angle exists because the two ratios have squared sum one. Then the changed coordinates areAll other coordinates satisfy . If , both input coordinates are zero; take , giving the identity matrix on this pair. In all cases,This fixes a nonnegative retained coordinate and handles division by zero explicitly. For floating-point computation, the stable construction of a Givens rotation uses scaled Euclidean norm evaluation to avoid unnecessarily overflowing or underflowing the squares.
Apply the product from right to left, choosing every Givens rotation from the current first column. First replaces by . Next combines that retained entry with and sets the third entry to zero. Inductively, after eliminating coordinates , the first coordinate isand coordinates are zero. Later Givens rotations involve only coordinate one and a new coordinate, so those zeros remain zero. Thereforewhere is the first standard basis vector. The zero vector is included by choosing the identity matrix for every zero pair. The nonnegative sign follows from the convention fixed in part (c)(ii). This is the first-column stage of QR decomposition by Givens rotations.
Put and write its second column as . For , takewhere each angle is computed from the current second column, in the right-to-left application order. These Givens rotations eliminate its entries in rows by accumulating their Euclidean norm in row two.
Each rotation acts only on rows with indices at least two. The first column of is , whose entries in all those rows are zero. Mixing two zeros leaves them zero, and row one is untouched. Thus the first column is unchanged. The resulting matrix has the formThis verifies both required properties, including the case of zero second-column tail. When there are no rows to eliminate: take , the empty product. No sign change of is required in that case. Each Givens row-pair update preserves previously eliminated columns, which is the central invariant of QR decomposition by Givens rotations.
The orthonormal columns satisfy and . By part (i), . A product of orthogonal matrices is an orthogonal matrix, since . ConsequentlyThe last expression is the first coordinate of the transformed second column. Thus the first row isThe one in the first entry uses the nonnegative retained-coordinate convention. A different consistent sign convention could give instead; the second entry must still be zero by preservation of the inner product.
Articles by others on the same topic
There are currently no matching articles.