Worked solutions to the paper dated 16 June 2022. The released archive files it under
2021/T/a10101w1.pdf; the printed date identifies the examination. Source release: Oxford computer science examination release. All eight questions are covered, including those beyond the examination's choice requirement.For bits , use two negation logic gates and two AND gates:The two unequal bit pairs activate their respective output; the equal pairs activate neither. In particular, a digital comparator never produces .
Split each input into its more and less significant -bit halves: and . Let the two digital comparators produce and . The more significant halves are equal exactly when . The comparator composition is thereforeImplement with a logical disjunction followed by a negation, then use two AND gates and two more logical disjunction logic gates. If , the difference has magnitude at least , whereas ; hence the more significant comparison decides the result. If , the lower comparison decides it. This proves correctness in every case using a constant number of extra logic gates.
Apply comparator composition recursively in a balanced binary tree, with one-bit digital comparators at its leaves. For a power of two , the circuit size and circuit depth satisfyThere are leaves and internal nodes, so the circuit size is and the combinational delay is . Here each fixed-fan-in logic gate has bounded delay. For arbitrary , pad both inputs with leading zero bits to the next power of two, which is less than ; this preserves their unsigned interpretation and both bounds.
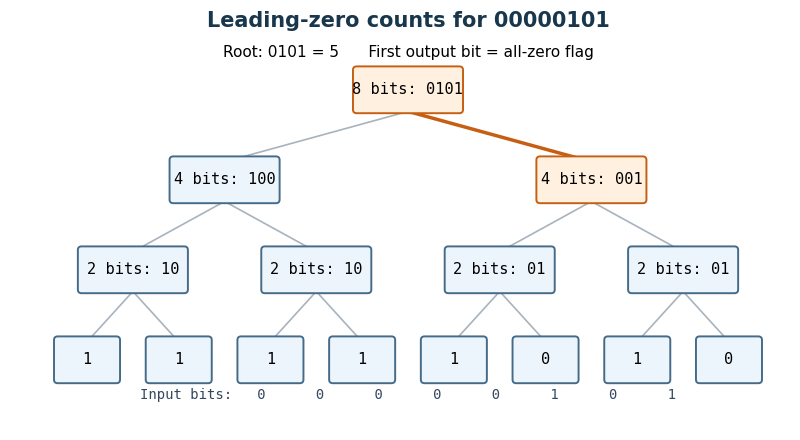
Use a hierarchical leading-zero counter. A block of bits returns a zero flag and low count bits : its count leading zeros result is the concatenation . Thus means that the block is entirely zero and ; otherwise and is its leading-zero count. A one-bit block needs just and no low count bits.
For a block of bits, run two such Boolean circuits on the upper and lower halves in parallel. Write their flags as and their low count bits as . SetThe last expression is a two-input multiplexer. When the upper half is nonzero, its count is already the answer and . When only the upper half is zero, supplies the contribution while the multiplexers supply the lower half's count. When both halves are zero, the answer is , representing . This special encoding avoids an adder on the critical path.
Each node adds constant circuit depth, even though it uses logic gates for its parallel multiplexers. HenceIndeed the internal-node work is bounded by a constant times , and the leaves add . Delay is and size is , counting fixed-fan-in logic gates and the usual wire fan-out model.

Use the AAPCS32 convention:
r0 holds the input address, r1 the length, and r0 receives the result. The following Thumb instruction set assembly language uses only scratch processor registers, so no callee-saved registers need saving. Assume the array is valid, halfword-aligned, and has nonnegative length; for the mathematical sum assume it fits a signed 32-bit two's complement integer..syntax unified
.thumb
.thumb_func
sum16:
movs r2, #0 @ accumulated sum
cmp r1, #0
ble .Ldone @ empty array; also returns 0 if n < 0
.Lloop:
movs r3, #0 @ Thumb signed load needs a register offset
ldrsh r3, [r0, r3] @ signed halfword at a; offset read before r3 changes
adds r2, r2, r3 @ include this signed value
adds r0, r0, #2 @ advance by one short, not one byte
subs r1, r1, #1 @ one fewer element remains
bne .Lloop
.Ldone:
movs r0, r2 @ result register
bx lr @ leaf routine: lr was not overwrittenAfter iterations, the loop invariant is that
r2 contains the first elements' sum, r0 points to element , and r1 is . The sign extension in ldrsh supplies the correct signed addend. One iteration preserves this loop invariant, and the decreasing remaining length proves algorithm termination. For the seven-element calls, the sum lies between and , so it fits. For longer arrays that overflow, these instructions compute the sum modulo ; that is not a claim about defined signed C programming language overflow behavior. The operand forms are those of the paper's reference sheet.[ref]Thumb 16-bit instruction set quick reference by Arm. Load: signed halfword; Add/Subtract; Branch
Let the stored bits be and let . The sign extension performed by
ldrsh keeps output bit equal to for , and sets every output bit to . Thus a nonnegative halfword gets sixteen leading zero bits, while a negative halfword gets sixteen leading one bits.Its signed 32-bit two's complement value isThe last expression is exactly the original signed 16-bit value. The equality uses the finite geometric series . In particular, simply inserting zero bits would be wrong for a negative halfword: its unsigned interpretation differs from its signed value by .
Keep
total in the callee-saved register r4, and the first returned sum in the callee-saved register r5. Suppose the surrounding function has made an aligned stack frame with the local seven-halfword array at the current sp, occupying fourteen bytes in a sixteen-byte slot. One possible frame setup is push {r4,r5,r6,lr} followed by sub sp,sp,#16; the earlier code initializes total, regular, and special before this fragment. ldr r0, =regular @ assembler literal load of the global array address
movs r1, #7
bl sum16
movs r5, r0 @ first sum must survive the next call
add r0, sp, #0 @ current frame's local special array
movs r1, #7
bl sum16
muls r0, r5, r0 @ second sum times first sum
adds r4, r4, r0 @ update totalThe AAPCS32 permits each call to overwrite
r0–r3, r12, and condition flags, but requires preservation of r4–r8, r10, r11, and sp. Thus both r4 and r5 remain valid even if sum16 is replaced by another conforming implementation. bl changes the link processor register lr, so the enclosing function saves its own return address in its prologue. Its epilogue can use add sp,sp,#16 and pop {r4,r5,r6,pc}. The frame uses thirty-two bytes in total, preserving the required eight-byte stack pointer alignment at both calls.[ref]The two calls may be evaluated in this order. Assume the product and final addition fit the signed 32-bit result expected by the source program; unlike each individual seven-element sum, their product need not fit. The assembly language operations retain their low 32 bits if this assumption fails, whereas signed integer overflow in the C programming language has different semantics.
Maintain the latest five temperature readings in a circular buffer, together with their running sum. The following C programming language code spells out the message passing interface rather than assuming a particular library:
send(dst,&m) is a blocking synchronous message passing send; receive(src,&m) receives from the specified sender or ANY and returns the sender's identity; sendrec(dst,&m) atomically sends the request and waits for that sender's reply in the same message object. Successful, reliable operations are assumed. Message contents are copied by the interface.enum { ANY = -1, TIMER = 1, TEMP = 2 };
enum { PULSE, PING, REQUEST, REPLY };
typedef struct {
int type;
int period_ms;
double value;
} Message;
extern void send(int dst, const Message *m);
extern int receive(int src, Message *m);
extern void sendrec(int dst, Message *m);
void smooth(void) {
double history[5] = {0};
double sum = 0;
int count = 0, next = 0;
Message m = { .type = PULSE, .period_ms = 1000 };
send(TIMER, &m); /* subscribe once */
for (;;) {
int sender = receive(count < 5 ? TIMER : ANY, &m);
if (sender == TIMER && m.type == PING) {
Message t = { .type = REQUEST };
sendrec(TEMP, &t); /* matching REPLY contains t.value */
if (count == 5)
sum -= history[next];
else
++count;
history[next] = t.value;
sum += t.value;
next = (next + 1) % 5;
} else if (count == 5 && m.type == REQUEST) {
Message answer = { .type = REPLY, .value = sum / 5.0 };
send(sender, &answer);
}
}
}Before the fifth reading, selective reception from
TIMER prevents premature client requests from being accepted. Such clients wait at their synchronous sends; they are not given a partial arithmetic mean. Thereafter the operating-system process receives both timer messages and client requests. Each accepted PING initiates one measurement; each accepted client request returns the arithmetic mean of the five most recently completed measurements, without initiating another measurement or changing the circular buffer.The loop invariant is that
count is the number of valid readings, capped at five, sum is their sum, and next is the next unused slot during startup or the oldest slot afterwards. Removing the overwritten reading and adding the new one preserves this loop invariant. Each update and reply uses time complexity and storage, since the window length is fixed. Under timely sensor replies, timer delivery and process scheduling, measurements are initiated once per second. The next parts explain failures of these timing assumptions; the code does not promise one-second sampling when the sensor itself cannot sustain it.With synchronous message passing, the smoothing operating-system process can still be waiting for
TEMP when its next PING is due. If the timer service sends to subscribers serially, it blocks on this unready recipient and cannot deliver the other subscribers' ticks: one slow sensor can delay every timer client through head-of-line blocking. Once it resumes, implementations may deliver late ticks, drift from their schedule, or accumulate overdue work.The consequence depends on the delivery model. With buffered sends the timer need not block immediately, but its queue can grow or overflow; the smoothing operating-system process still cannot process readings at a sustained rate faster than the sensor. A nonblocking notification mechanism or separate timer-delivery workers can isolate other subscribers, while coalescing missed ticks prevents an unlimited backlog. These changes do not make an over-slow sensor meet the original sampling rate.
With a synchronous reply,
send(client,&answer) blocks until the client receives. An indefinitely unready client therefore stalls the smoothing operating-system process, which may in turn stall the timer service and its other clients as in the preceding part. If the client is merely delayed, this is blocking and delayed service; a deadlock requires a circular wait or a client that will never receive.Requiring correctly used synchronous send-and-receive helps. A client calling
sendrec(SMOOTH,&m) is committed to waiting for the matching reply as soon as its request has been accepted. This closes the scheduling window between a separate send and receive and prevents unrelated client computation from postponing that receive. It does not by itself fix slow measurements, arbitrary failures, circular dependencies between other services, or lack of CPU scheduling. With buffered replies the initial effect may instead be queue growth, depending on the message passing contract.In a cooperative scheduler, a permanently runnable background operating-system process that never yields can monopolize the CPU. The timer service, smoothing operating-system process, and display may then fail to run even when their messages are ready. Correct message passing alone does not supply process scheduling.
Use timer-driven scheduling preemption, so an interrupt can force a context switch without cooperation. To give the measurement and display work bounded response despite background computation, use priority scheduling with the background operating-system process below the responsive services, or an explicit reservation policy. Round-robin scheduling gives CPU access among a fixed finite runnable set, but meeting a particular deadline additionally requires bounded service execution and sufficient CPU capacity.
Write and , where are the standard basis vectors. Since ,Thus the columns of form an eigenbasis, and the requested ordered basis is . Its basis matrix is , giving . More completely, for each distinct eigenvalue , its eigenspace isAll nonzero vectors in these eigenspaces are eigenvectors; when an eigenvalue repeats, they need not be individual columns of .
Let and . ThenBy matrix similarity, every eigenvalue of is for some . These are corresponding eigenvalues on the common eigenbasis, rather than every possible pairwise sum. This is eigenvalue addition in a common eigenbasis.
With the two diagonal matrices from the preceding part, write and . Their diagonal products agree entry by entry, so . ThereforeHence simultaneous diagonalization implies that are commuting operators.
Using and linearity,This establishes that commuting maps preserve eigenspaces. The vector can be zero, so this step alone does not assert that is an eigenvector.
Work over the field containing the stated distinct eigenvalues of ; in a real formulation these must be real to obtain real eigenvectors. Choose one eigenvector for each distinct eigenvalue. By independence of eigenvectors for distinct eigenvalues, these vectors are a basis. Consequently each eigenspace has dimension one: in an expansion in this eigenbasis, forces every coefficient with a different eigenvalue to vanish.
Now let be any eigenvector of . By part (d), belongs to its one-dimensional eigenspace, so for some scalar . This proves that is an eigenvector of , including the case , where . This is the crucial one-dimensional step in simple spectrum gives simultaneous diagonalization.
The independent eigenvectors of from part (e) are also eigenvectors of . Put and . ThenThis supplies the required simultaneous diagonalization over the same field as in part (e).
For , takeThey are commuting operators because every matrix commutes with the identity matrix. However has only the eigenvalue zero, and has dimension one. It has no eigenbasis, so it cannot appear in any simultaneous diagonalization. Equivalently, a diagonal matrix similar to this nonzero nilpotent matrix would have to be zero, an impossibility. For any prescribed , use and ; its zero eigenspace has dimension . For no such example exists.
The zero matrix has the required pattern, and matrix addition and scalar multiplication preserve every prescribed zero entry. This proves the vector subspace condition. A basis consists of the matrix unitsThey independently select every permitted entry of a tridiagonal matrix, so the dimension is for .
For , the upper entry of in positions is , and the corresponding lower entry is . They are equal when . All coefficients used here are positive, so chooseDirect matrix multiplication gives the symmetric matrixIts pattern remains tridiagonal. This is positive diagonal symmetrization of a tridiagonal matrix.
For the analogous positive off-diagonal entries in size , takeThe same entrywise computation gives and , with every other entry zero. Thus the result is a symmetric matrix with a tridiagonal pattern. Positivity of the diagonal entries is not needed for this positive diagonal symmetrization of a tridiagonal matrix; positivity of ensures the displayed positive, invertible . In particular, the assertion is not an arbitrary-real-coefficient symmetrization claim when the off-diagonal signs differ.
They are similar matrices, so their eigenvalues, with algebraic multiplicities, are identical. Explicitly,Moreover their eigenvectors correspond by . Since the transformed matrix is a real symmetric matrix, the spectral theorem for real symmetric matrices also shows that has real eigenvalues and is a diagonalizable matrix.
Use banded Gaussian elimination followed by back substitution. To distinguish the right-hand side from the upper-diagonal coefficients , write it as . If the modified pivot elements are nonzero, the tridiagonal elimination recurrences areThey eliminate just the one entry below each pivot element. Solve the resulting upper bidiagonal matrix system byThere is a bounded number of arithmetic operations per row in each sweep, giving arithmetic operations and storage. The unpivoted recurrences cost arithmetic operations under the usual scalar-operation count.
For a general tridiagonal matrix, nonsingularity alone does not guarantee these pivot elements. If a zero or unsafe pivot element occurs, use partial pivoting between the current row and the next row. These are the only possible nonzero candidates in the current column; adjacent row swaps introduce at most a second upper diagonal. Tracking that fill-in keeps both Gaussian elimination and back substitution at arithmetic operations. For example, is invertible but requires a row swap. If the input is singular, report a zero final pivot element; a unique solution cannot be promised, and compatibility or free-variable analysis is a separate issue. No nonsingularity or safe-pivot assumption is silently inferred from the word tridiagonal.
Let be the determinant of the leading principal submatrix. Expansion along the last row gives an term and a term with negative cofactor sign. In the latter minor, the final column has only nonzero, and deleting that row and column leaves the leading principal submatrix. Thus the tridiagonal determinant recurrence isHere is the empty determinant convention, needed to include . The derivation uses cofactor expansion, so the recurrence relation remains valid when coefficients or intermediate determinants vanish; it never divides by a pivot element.
Evaluate the recurrence relation successively, retaining only the preceding two values. Each of the updates uses three multiplications and one subtraction. Hence arithmetic operations and auxiliary storage suffice, excluding the stored input. Naively branching into two recursive calls would repeat work; the sequential computation is essential. This is an arithmetic-operation bound, not a bit-complexity bound for arbitrarily large exact integers.
Writing the given bases as and , a basis of the Cartesian product with its componentwise vector space operations isThis is the direct sum basis. Therefore . The construction includes zero-dimensional factors, whose corresponding portion of the basis is empty.
The intersection of vector subspaces contains zero, so . If and are scalars, thenbecause by the vector subspace conditions. These pairs belong to , since both and belong to the required factors. Thus is a vector subspace of .
Define by . It is well-defined by the definition of , andThus is a linear map. If , comparing first components gives , proving injectivity. Every element of has the form , proving surjectivity. Hence is a linear isomorphism, with inverse , and .
Every output lies in the sum of subspaces , since it is a linear combination of members of the two vector subspaces. For , and scalars ,Therefore is a linear map. Every vector in is such an output: group the terms of any linear combination from according to their originating vector subspace. Thus the addition map of subspaces is also surjective.
The kernel of a linear map is precisely , sincePart (c) gives . Apply the rank-nullity theorem to the finite-dimensional vector space , and then parts (a) and (b):This proves the dimension formula for a sum of subspaces. The kernel of a linear map records exactly the freedom to transfer a shared vector from one summand to the other without changing their sum.
Eliminating logical implications givesAn absorption step simplifies this to the disjunctive normal formEach one-literal term is a permitted logical conjunction in a disjunctive normal form.
The given logical implication is false exactly when and . For every literal on , there is such a false Boolean valuation making that literal true. For a prescribed value of or , give the other the same value and choose . For a prescribed value of or , give the other the opposite value and choose .
Consequently no literal implies the whole propositional formula: there is no one-literal implicant. If an equivalent disjunctive normal form contained a one-literal conjunction term , then every Boolean valuation satisfying would satisfy that disjunctive normal form, contradicting its equivalence to the given propositional formula. This proves the claim. Even if auxiliary Boolean variables are allowed in the equivalent expression, a one-literal term on one of them fails too: fix any false Boolean valuation of the original four and set the auxiliary literal true. The word “conjunct” here refers to a conjunction term in the disjunctive normal form, not a factor in a conjunctive normal form.
Use structural induction on the propositional formula. The induction claim is that its truth value under the all-one Boolean valuation is one. A variable has this truth value by definition. For the induction step, suppose the immediate subformulas each have truth value one. ThenThese are all permitted construction cases. Thus every such propositional formula evaluates to one. Equivalently, the three logical connectives define one-preserving Boolean functions, and composition preserves this property. The variable-only base grammar matters: admitting a constant false formula would invalidate the claim.
Let and , so the two displayed propositional formulas are and . Their complete truth tables areTherefore is a tautology; is not. For example makes the antecedent true via , while is false because is true and is false. This explains why having just one of the two logical implications is insufficient for the forward direction.
Only requires a natural deduction proof. Assume . Within that assumption, temporarily assume . By disjunction introduction, obtain ; applying by the implication elimination rule gives . Discharge by the implication introduction rule to derive . Disjunction introduction now gives . Finally discharge by the implication introduction rule:All temporary assumptions are discharged. No classical rule is needed; the same proof works in Intuitionistic propositional logic. The false propositional formula has no proof in this sound natural deduction system.
Express existence of a minimum using only the given strict-order relation:In the closed interval , the witness is . In the open interval , every possible witness has the smaller member , so the first-order sentence is false. These witnesses are explanations in the ambient real numbers, not additional symbols in the first-order signature.
Express that the order is a dense order:In either real interval, lies strictly between any two distinct ordered elements and remains in the domain. In the integers, have no intervening integer, so this first-order sentence is false. The endpoints of a closed interval do not prevent a dense order.
Combine a minimum with an adjacent pair in a linear order:In , choose . The minimum and the adjacent pair in a linear order both exist. In , the dense order property rules out such an adjacent pair. In , adjacent pairs exist, but no minimum exists: for any , the integer is smaller. Thus this first-order sentence has precisely the required three truth values. Neither the endpoints nor the numerical witnesses occur as constant symbols in the first-order sentence.
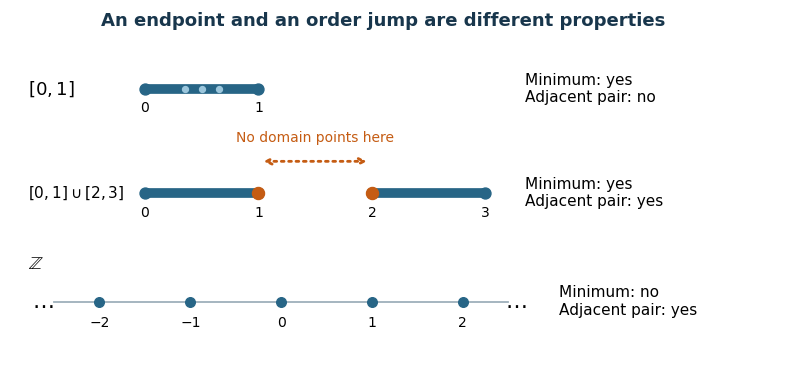
A minimum and an adjacent pair distinguish the two-interval order from a closed interval and the integers
. Orange highlights the consecutive domain members and in the two-interval order. The dotted arrow crosses points absent from that domain. A closed real interval has intervening domain members; the integers have adjacent pairs but no minimum. Details.
Use the intended first-order structure of real arithmetic, with
Int selecting the integers; is the parameter in . A suitable first-order formula isThe first condition requires a real square root of . The second excludes every representation as a rational number with a nonzero integer denominator. This uses only the listed function and constant symbols, the Int predicate and logical equality; in particular, is written and there is no extra division symbol. A square root exists exactly when , and either sign of a root is a rational number exactly when the other sign is a rational number, so the absence of a positivity condition on does not affect the claim about the principal square root. At the formula is false; for there is no real witness. The meanings of and as real arithmetic, not just the meaning of Int, are part of this interpretation.Two unary predicates suffice. Require all four unary predicate types to be inhabited:There are no constants, no logical equality and no nonunary predicates. Any two of these conditions disagree on at least one predicate, so one domain element cannot witness both. Hence every satisfying first-order structure has at least four elements, by distinct witnesses from incompatible unary predicates. Conversely take domain , and : the four elements realize the four displayed unary predicate types, respectively. These element names describe the example; they are not constants in the first-order sentence.
The term is not free for substitution for . The occurrence of in is under , which would capture the inserted . The other occurrence, in the outside disjunct , has no enclosing quantifier. The inner does not bind the occurrence of in its antecedent, so it creates no additional capture at that substitution site.
Rename the bound to a fresh , then carry out capture-avoiding first-order substitution. The result isThe inserted in remains free because it lies outside the scope of . One may additionally rename that bound for readability, but it is not necessary for correctness.
The term is free for substitution for . The only free occurrence of the target is in the outside disjunct , beyond both quantifier scopes. The occurrences under are bound variables and are not replaced. Therefore no renaming is required, andThe new and in the last disjunct are free. First-order substitution replaces the original free occurrences once; it does not recursively substitute into the inserted term.
The printed expression has one unmatched closing parenthesis. Remove that final surplus parenthesis and read the first disjunct as ; the other disjunct has outer universal quantification over the displayed implication. To distinguish the two independent bound uses of , rename the first to .
Push the outer negation through the logical disjunction and through the quantifiers. Negating the implication preserves its existential antecedent and negates its consequent. Applying De Morgan's laws and the quantifier negation rules gives the negation normal formEach negation is now directly before an atomic formula. No bound variable has been captured, and no original existential quantification in the antecedent has accidentally been negated twice.
Articles by others on the same topic
There are currently no matching articles.