Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Subgradient inequality
Convex function Created 2026-09-24 Updated 2026-10-14
A function on a convex set is a convex function if, for every and ,Geometrically, a line segment joining two points of its graph of a function lies on or above that graph of a function. The convex set condition ensures that the intermediate input stays in the domain of a function. An affine function satisfies the defining inequality with equality.
For the quadratic function , the inputs and have equally weighted arithmetic mean . Evaluating at the arithmetic mean gives , whereas averaging the outputs gives . Averaging first saves one unit in this example. More generally, direct expansion givesThis identity proves convexity and also shows exactly when its defining inequality is strict.
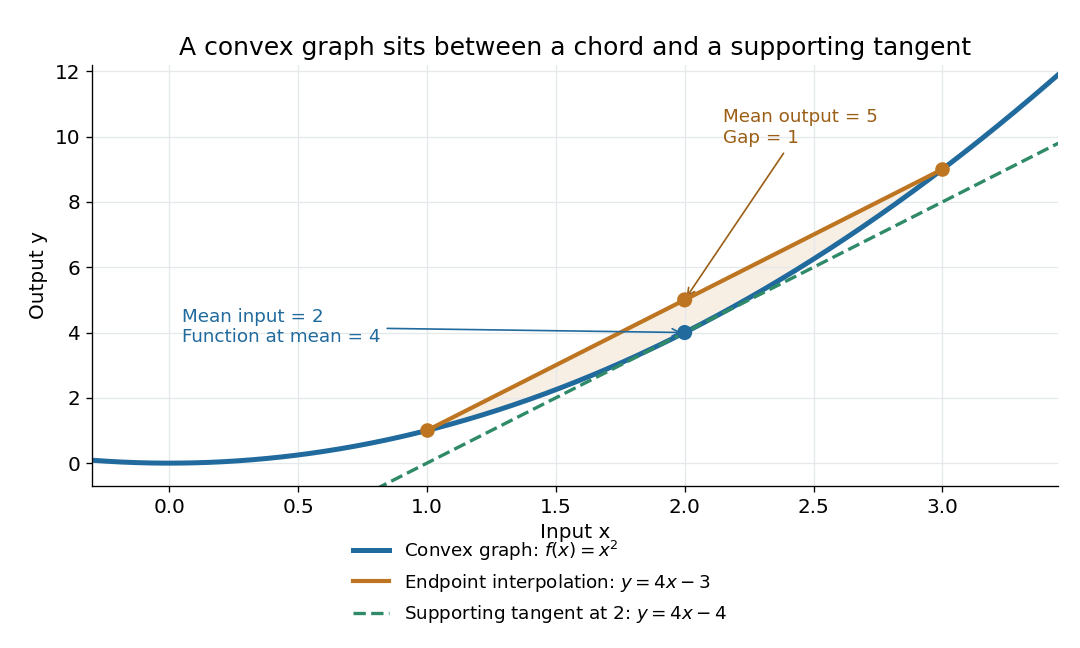
The graph of a convex quadratic lies below its endpoint interpolation and above its supporting tangent
. For , the line segment through and has height at , while the graph of a function has height . The tangent line is an affine minorant: everywhere. Details.For a differentiable convex function, the tangent line in one dimension, or the corresponding supporting affine function in several dimensions, lies below the entire graph of a function. This is the subgradient inequality. The equivalent geometric statement is that the epigraph, consisting of points on or above the graph of a function, is a convex set. These characterizations are developed in Boyd and Vandenberghe's convex-function slides, sections 3.1–3.4.
Convexity does not require differentiability: the absolute value function is a convex function with a corner at . When a function is twice continuously differentiable on an open interval, it is a convex function exactly when its second derivative is nonnegative throughout that interval. In several dimensions, the corresponding criterion on an open convex set is that its Hessian matrix is positive semidefinite everywhere. The domain of a function matters: is a convex function on , but not on all of . A strictly positive second derivative is sufficient for strict convexity, but is not necessary: is a strictly convex function although its second derivative vanishes at .
The usefulness of convexity is that local information can certify a global conclusion. Every local minimum of a convex function on a convex set is a global minimum: if a lower value existed elsewhere, the defining inequality would produce lower values arbitrarily close to the proposed local minimum. For a differentiable convex function on an open convex set, a zero gradient therefore certifies a global minimum. Strict convexity gives uniqueness when a global minimum exists; it does not supply existence by itself. These facts explain the role of convex functions in convex optimization.
Convex optimization Created 2026-09-24 Updated 2026-10-13
Convex optimization is a minimization problem with a convex function as its objective function and a convex set of feasible points. For a finite-valued , the problem is to find with for every . The displayed infimum describes its value even when no minimizing point exists. The two convexity requirements concern different objects: the allowed decisions and the scores assigned to them.
A convex set contains the whole line segment between any two of its points:A convex function lies below the interpolation of its endpoint values:Thus mixing two allowed decisions preserves feasibility, and the mixed score is no worse than the same mixture of endpoint scores. The objective function may have flat regions or corners. For a strictly convex function, the second inequality is strict when and .
A useful constraint representation iswhere are convex functions on a common convex set , and the equalities are affine functions. Each inequality defines a convex sublevel set; their intersection with and the equality set is a convex set. An equality involving a general convex function need not preserve this geometry: allows and but excludes their midpoint . See Boyd and Vandenberghe, Convex Optimization (2004), §4.2.1 for the standard problem form.
Why local information can certify a global answer. Every local minimum of a convex optimization problem is a global minimum, including minima on the boundary. If a feasible point had , points would remain feasible and have value strictly below for every . Taking arbitrarily small contradicts a local minimum at . This argument explains the special power of convexity: a better distant decision would reveal an improving direction immediately nearby.
If a minimizer exists and the objective function is strictly convex on , it is unique. Two distinct minimizers of value would have a feasible midpoint with value strictly below . Existence is a separate question: the exponential function is strictly convex on , but its infimum is approached only as . Even a bounded convex set need not suffice: on also has unattained infimum . A continuous function on a nonempty compact set attains its minimum by the extreme value theorem.
Nor does strict convexity imply differentiability. For , the squared term gives the strict inequality while the triangle inequality gives the weak inequality for the absolute value. At zero the left and right derivatives are and , so no derivative exists there, although zero is the unique minimizer. Such objectives require subgradients or proximal operators rather than an ordinary gradient at every point.
For a differentiable convex function on an open convex set containing , the constrained first-order condition isIndeed, the subgradient inequality makes this sufficient; taking the one-sided derivative along feasible line segments makes it necessary. At an interior minimizer, both directions are feasible and the gradient must vanish. At a boundary minimizer it can be nonzero: it only needs to make every feasible direction nondecreasing. See Boyd and Vandenberghe, §§3.1.3 and 4.2.3.
A fully computed nearest-point problem. Project onto the half-space by minimizing half the squared Euclidean distance:The Hessian matrix is the identity matrix, so the objective function is strictly convex. The unconstrained minimizer violates the inequality. With the convention , the optimization Lagrangian is , where the Lagrange multiplier satisfies . Its Karush-Kuhn-Tucker conditions areThe last two equations give , . The choice is infeasible, so complementary slackness forces . Consequently , giving , and . The Euclidean distance is , rather than the objective function value . The gradient at the answer balances ; the displacement from to is a normal vector to the boundary.
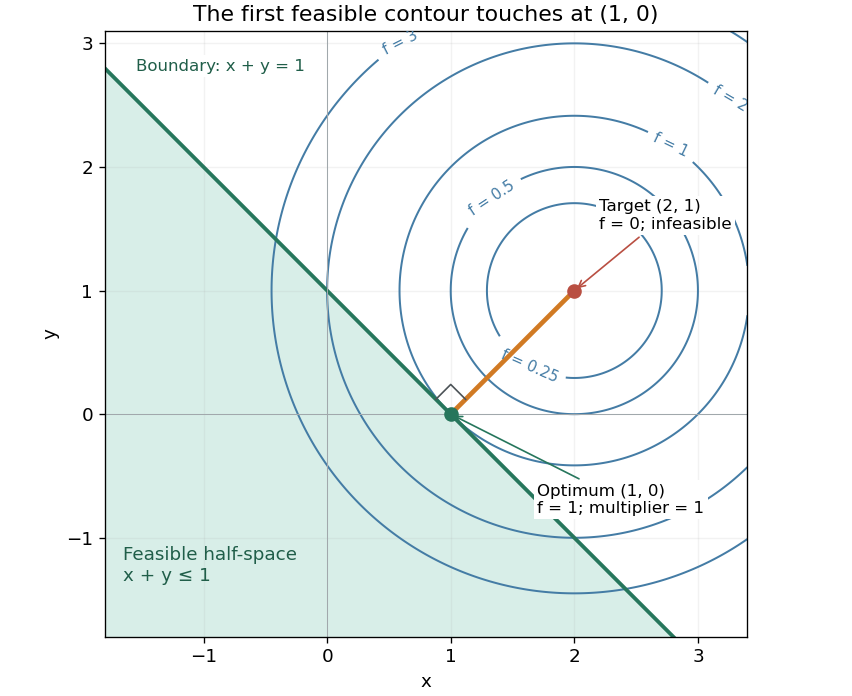


There is an exact certificate independent of numerical search. Completing squares givesFor every feasible point, implies . Thus every feasible objective is at least , and attains this bound. More generally the Lagrangian dual problem has objective for . Its maximum is also , illustrating strong duality through matching computed bounds. This makes the example a model for Euclidean projection onto a convex set and the projection step in projected gradient descent.
What the multiplier conditions require. For differentiable convex functions on an open convex set and equalities defined by affine functions, the KKT conditions combine feasibility, , complementary slackness , and stationaritywith unrestricted equality Lagrange multipliers . They suffice to certify a global minimum without an additional regularity assumption: the optimization Lagrangian is convex, stationarity minimizes it, and feasibility with complementary slackness gives the same certificate as above. To guarantee their necessity at an attained finite optimum, a regularity hypothesis suffices: Slater's condition requires some with and . The projection example has the strictly feasible point . See Boyd and Vandenberghe, §§5.2.3 and 5.5.3. This hypothesis guarantees suitable multipliers, not existence of a primal minimizer.
Without regularity, necessity can fail even for convex functions: minimize subject to . The sole feasible point is optimal, but stationarity would require . No Lagrange multiplier works. There is no strictly feasible point, and the gradient of the constraint vanishes at the answer.
The nonconvex contrast. The polynomial has derivative and second derivative . Numerically solving the cubic gives stationary points , , and . Their objective values are respectively , , and , with second derivatives , , and . Hence both outer points are local minima, and the middle point is a local maximum. Since at both ends, its global minimum exists and must be one of the stationary minima: it is the left one. A method stopping at the right local minimum misses a better value by approximately .
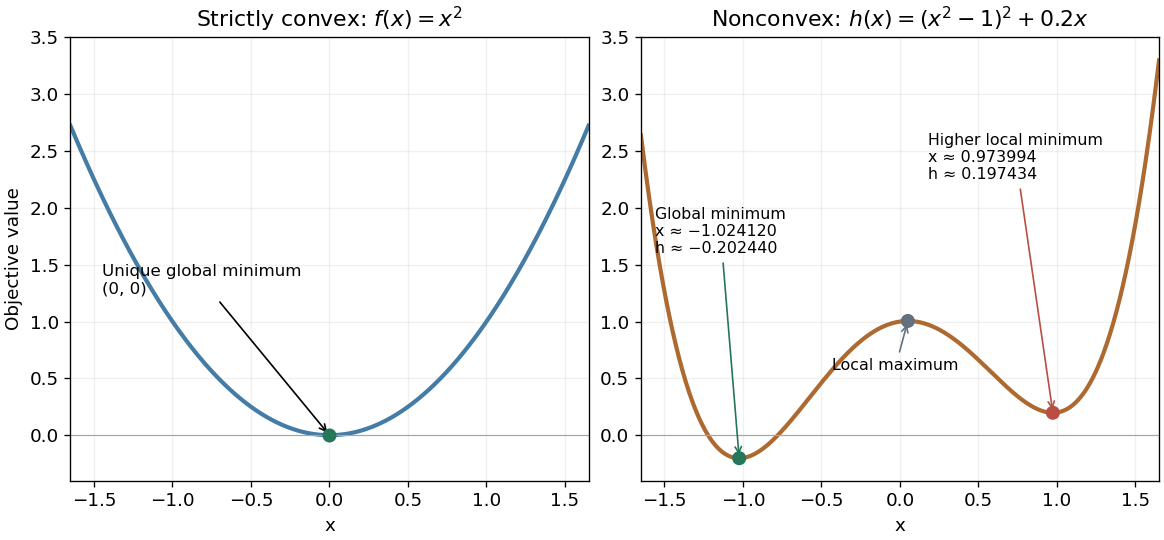
A strictly convex quadratic has one minimum; a tilted quartic has two local minima with different values
. Details. 
The practical appeal of convex optimization is the ability to check an answer globally using geometry and matching Lagrangian duality bounds. The projection certificate certifies every feasible alternative at once; the tilted quartic shows why a zero gradient alone cannot do that for general nonlinear optimization.
Historically, an early landmark is Kuhn and Tucker's [ref]
https://digicoll.lib.berkeley.edu/record/112776/files/math_s2_article-35.pdf. Nonlinear Programming, Second Berkeley Symposium (1951), pp. 481–492
. Its §3 explicitly states a regularity hypothesis for inequality-constrained Lagrange multipliers; its discussion of saddle points explains how concave functions support global conclusions for maximization. This documents an early formulation of the multiplier approach; it does not establish sole discovery of today's KKT conditions or of convex optimization as a whole. Convex positively one-homogeneous functional 2026-10-06
This is a proper convex function that has degree-one positive homogeneity, with . It need not be even or nonnegative; linear functionals are examples. Its subdifferential satisfiesThe two tests and prove equality; the subgradient inequality then gives the global upper bound. Conversely that bound and equality prove the subgradient condition. Hence a subgradient at also supports every nonnegative multiple of . Requiring gives an absolutely one-homogeneous functional.
Suppose is a differentiable convex function with coordinate Lipschitz continuity constant . Put , the Bregman divergence from the supporting affine function at . The subgradient inequality gives , and its coordinate Lipschitz constant is still . The coordinate descent lemma with step size yieldsSince , rearrangement proves the bound. Continuous differentiability suffices; a Hessian matrix is unnecessary.
Target: gradient-descent.bigb, under Lipschitz gradient. Euler identity for a convex one-homogeneous functional Created 2026-10-05 Updated 2026-10-06
For an absolutely one-homogeneous functional that is convex and ,The subgradient inequality at zero gives , and at gives the reverse inequality. This is an Euler identity that needs no differentiability.
Suppose and . For , the subgradient inequality and dual pairing bound giveThus forces every minimizer to solve exactly. Comparison of penalties then shows it is a J-minimizing solution, and . The conclusion also holds for all when . One-homogeneity is not needed for this argument.
Fenchel–Young inequality Created 2026-09-28 Updated 2026-10-14
The Fenchel–Young inequality says that every input and every slope obeywhere is any proper extended-real function and is its convex conjugate. No convexity assumption on is needed for this inequality: the defining supremum is at least the particular value . If either term on the left is , the inequality still holds, but cannot be an equality because the dot product on the right is finite.
For a proper convex function, equality is equivalent to the subgradient conditionTo see this, with finite, equality says that attains the supremum defining , so for every . Rearranging gives the subgradient inequality . Geometrically, the affine minorant touches at .
If the proper convex function is also closed, meaning its epigraph is a closed set, or equivalently it is lower semicontinuous, thenThe forward implication holds without closedness; the reverse one requires the additional hypothesis in general. Applying the equality criterion to relates to , and the Fenchel-Moreau theorem supplies when is closed. See Bertsekas, Convex Optimization Theory: A Summary, §5.4.1, Proposition 5.4.3 for precisely this distinction.
A concrete failure of the reverse implication occurs for the indicator functional of a constraint set of the open interval . Its convex conjugate is : the endpoint gives the supremum, even though it is excluded from the interval. At , , but , so equality fails and is empty. Closing the interval changes the endpoint value and restores equality there.
For the convex quadratic function , the Fenchel–Young inequality is , and equality holds exactly when . For the absolute value , finite equality requires at , where is the sign function; at every gives equality. These are exactly the subgradients of the absolute value, including its entire interval of slopes at the corner.
Fermat rule for convex minimization 2026-10-06
For a proper convex function finite at , global minimality is equivalent to . This follows immediately from the defining subgradient inequality. Combined with a subdifferential sum rule, it converts a convex minimization problem into an inclusion, for example the equation defining a proximal operator.
Monotonicity of a convex subdifferential 2026-10-06
Adding the two subgradient inequalities for and givesThus the subdifferential is a monotone operator. This inequality proves uniqueness of its resolvent: two solutions of must coincide when .
Past exam of the mathematics course of the University of Cambridge 2013 iii Paper 62 4 a Solution Created 2026-10-03 Updated 2026-10-07
The forward subgradient step and backward subgradient step are the set-valued mapsThus means . They are respectively the explicit and implicit time discretizations of subgradient flow . At a differentiable point the forward update is , while the backward update evaluates the gradient at the new point. For proper closed convex data the latter is the proximal operator
To prove at most one output, suppose . Then and . The two subgradient inequalities imply monotonicity of a convex subdifferential, givingSince , . Convexity supplies this monotonicity; lower semicontinuity is not needed for this at-most-one argument.
Under the full printed assumptions the output actually exists at every . Properness ensures a finite point and excludes . Proper lower-semicontinuous convex has an affine minorant, so the quadratic proximal objective is coercive. Lower semicontinuity makes its minimum attained on a compact sublevel set. Convexity and the positive quadratic curvature make it strongly convex, hence its minimizer is unique. The subgradient optimality condition, with the differentiable quadratic term, is exactly . ThusThis also identifies precisely which assumptions provide existence, uniqueness and the update's optimality interpretation.
Past exam of the mathematics course of the University of Cambridge 2014 iii Paper 65 3 a Solution Created 2026-10-03 Updated 2026-10-06
For a step size , define the set-valued mapsThe forward subgradient step maps to the set . If is differentiable this is the explicit gradient step . The backward subgradient step consists of the satisfying , an implicit step for the subgradient flow. It is the resolvent of a monotone operator associated with .
Suppose . Then . The two defining subgradient inequalities areTheir sum proves monotonicity of a convex subdifferential, . But , soConvexity supplies the subgradient inequalities and monotonicity; membership in the subdifferential ensures the two function values are finite, so subtraction is legitimate. Positivity of supplies the decisive sign. Properness rules out the identically infinite and negative-infinity pathologies in the overall setting, but lower semicontinuity is not needed for this at-most-one argument. Its role is in existence, proved next. The backward step cannot have two values, though uniqueness alone has not yet shown its domain is all of .
Past exam of the mathematics course of the University of Cambridge 2016 iii Paper 325 1 i Solution Created 2026-10-03 Updated 2026-10-06
Use the extended real numbers . A proper convex function never takes and is finite somewhere. Its effective domain isFor a proper extended-real function, convexity meansThe endpoint cases are identities; taking avoids the ambiguous product . Equivalently, its epigraph is a convex set. In particular, the effective domain is a convex set. Properness is an additional condition: it rules out the identically function and all values, rather than requiring finiteness everywhere.
For , the subdifferential is the set of supporting slopesEach element is a subgradient. Define outside . The defining subgradient inequality must hold globally, not merely in a neighborhood of . For a differentiable finite convex function, .
Past exam of the mathematics course of the University of Cambridge 2016 iii Paper 326 2 i Solution Created 2026-10-03 Updated 2026-10-06
For a proper convex function on a real Hilbert space, its subdifferential at isIn a Banach space, interpret the pairing with an element of the dual space. For a chosen subgradient , the Bregman distance isIf also , its symmetric Bregman distance isThe subgradient inequality proves nonnegativity. These quantities depend on the chosen subgradients and generally are not metrics: they need not distinguish different points or obey the triangle inequality.
Past exam of the mathematics course of the University of Cambridge 2016 iii Paper 326 2 vi Solution Created 2026-10-03 Updated 2026-10-06
The relevant nonlinear generalized singular vector relation, without imposing unit-data normalization, isThis is a generalized eigenfunction in the forward-operator metric, rather than a distributional generalized eigenfunction of a linear operator. It supplies the normal-operator source condition with . For a convex positively one-homogeneous functional, the subgradient inequality applied at zero and at gives . If , thenAssume the usual positive eigenvalue and . By positive homogeneity,The shifted-comparator Bregman bound therefore yieldsThe vector is itself a minimizer: remains a subgradient along the nonnegative ray, and substitution satisfies the subgradient optimality condition. If is injective, this also proves . Otherwise distinct minimizers can differ in the kernel while sharing the same predicted data.
For a nonnegative convex positively one-homogeneous functional, the branch continues as above the threshold, since there. Nonnegativity is needed for that clipping argument; bare positive homogeneity allows signed linear functionals.
Zero Bregman distance does not imply exact recovery. For , , and , the minimizer is , but . Both points touch the same supporting line, as described by zero Bregman distance and supporting faces.
Past exam of the mathematics course of the University of Cambridge 2017 iii Paper 205 5 Solution Created 2026-10-03 Updated 2026-10-05
For and labels , with squared-norm penalty normalized as , the kernel soft-margin support vector machine solvesHere is the hinge loss building block, and is column of the symmetric kernel matrix. The prediction iswith a fixed class choice, for example , when the score is zero. Other positive rescalings of the penalty change numerical coefficients in the optimality equation but not the zero-coefficient conclusion.
For a finite convex function , its subdifferential at isFor , affine composition preserves the defining convexity inequality: for ,If , the subgradient inequality gives , proving .
Conversely, let and first suppose . For every , the function is constant along . Applying the subgradient inequality for both signs of shows . Thus is in the span of , or with . Substituting gives for every real . Hence . If , is constant and ; since finite convex on all of has a nonempty subdifferential at , as well. This handles the case in which the suggested orthogonal projection would be undefined. ThereforeThis proves the subdifferential under scalar affine composition identity with all its degenerate cases.
Let be a fitted support-vector-machine margin. The subdifferential of the hinge loss yields choicesApplying the affine-composition identity and the subdifferential sum rule to the convex objective, its optimum satisfiesThe second equation is the intercept condition. Since is invertible, multiplying the first by gives the kernel support-vector coefficient from hinge activity formulaIn particular Invertibility is needed for this statement about the chosen coefficients: for with two positive labels, and give zero objective and both margins equal to two, while both coefficients are nonzero. A singular kernel matrix allows coefficient changes in the null space without changing the fitted function.
At prediction time, the sum can omit all zero coefficients, requiring only the number of evaluations of the positive-definite kernel corresponding to retained support vectors rather than all . This need not remove the cost of forming or solving with a dense training kernel matrix. Every misclassified point has , including a score-zero tie assigned to the opposite class, so and . Thus many classification errors imply many active support vectors and little prediction-time sparsity benefit. Correctly classified points inside the unit margin can also have nonzero coefficients; a point exactly on the margin need not have a nonzero coefficient.
Past exam of the mathematics course of the University of Cambridge 2017 iii Paper 340 4 c Solution Created 2026-10-03 Updated 2026-10-06
Work in the real Hilbert space , with and . The penalty is a proper convex function: it is finite at zero, and the bounded-variation space domain is convex. Its subdifferential at a finite-penalty consists of satisfying for every .
Conversely, let be a minimizer. Its penalty is finite since comparison with zero gives a finite objective. For any with , set , where . Convexity gives . Minimality and quadratic expansion then implyLetting yields . The inequality is automatic if . HenceThis also follows from the subdifferential sum rule, since the quadratic term is everywhere continuous and differentiable, and the subgradient optimality condition. The direct proof above needs no unproved existence theorem.
On the entire plane, the printed global BV domain is not closed in the L2 geometry. The usual definition includes an condition. For , belongs to , has finite distributional variation , and fails to belong to . The truncated lies in and tends to in . Its variation is the interior variation plus , and tends to a finite limit. Thus stays bounded but the literal , establishing failure of L2 closure of the global BV domain. One must not infer universal minimizer existence from an inapplicable closed-penalty proximal operator theorem. The standard closed extension uses the homogeneous bounded-variation space, allowing finite distributional variation without global . The optimality equivalence just proved is valid for the literal penalty whenever a minimizer exists; the next datum has an explicit certified minimizer in its domain.
Past exam of the mathematics course of the University of Cambridge 2019 iii Paper 326 3 b Solution Created 2026-10-03 Updated 2026-10-05
An absolutely one-homogeneous functional satisfieswith . The printed strictly positive codomain cannot hold at zero; the standard interpretation is a nonnegative, possibly extended-real functional.
For , apply the subgradient inequality at :so . Apply it at and use one-homogeneity:which gives the reverse inequality. ThereforeThis is the Euler identity for a convex one-homogeneous functional; differentiability is unnecessary.
Past exam of the mathematics course of the University of Cambridge 2019 iii Paper 326 4 a Solution Created 2026-10-03 Updated 2026-10-05
For a convex functional and , the generalized Bregman distance isThe inequality is exactly the subgradient inequality.
Suppose is strictly convex and , with both values finite. If the distance vanished, the supporting affine function at would also meet at . At , , the subgradient inequality would givecontradicting strict convexity. Hence zero distance implies .
Past exam of the mathematics course of the University of Cambridge 2019 iii Paper 326 4 b Solution Created 2026-10-03 Updated 2026-10-05
The source condition in variational regularization at an exact solution is the existence of a source element such thatFor a Hilbert data space one identifies with . If satisfies and , then every other exact solution obeys the subgradient inequalityHence is a J-minimizing solution. This is source-condition certification of a penalty-minimizing solution.
Past exam of the mathematics course of the University of Cambridge 2019 iii Paper 326 4 c Solution Created 2026-10-03 Updated 2026-10-05
Let , , and . The subgradient inequality, the dual pairing bound, and giveMinimality of in the exact penalty method givesCombining them yieldsThe coefficient is strictly positive, soNow minimality gives , and exact feasibility plus the defining minimality of gives the reverse inequality. Thus is a J-minimizing solution. Finally,This exact-penalty threshold from a source condition does not require one-homogeneity; convexity and the source subgradient suffice. If , the same argument works for every , interpreting the upper threshold as infinite.