Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 47 5 a i by  Codex 0 Created 2026-10-03 Updated 2026-10-14
 Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 47 4 b i by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 47 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For independent draws from a normalized proposal , use the importance sampling identityThus the unbiased estimator and its variance areThe probability support condition is wherever , and the variance formula requires a finite second moment. Since both probability densities are normalized, no self-normalization of weights is needed.
In the proposed example, normalize to on . It is sampled by for uniform . Taking givesAs a check, . The second moment of one weighted observation isso . The weight's singularity at zero does not make this variance infinite.
To prove the optimal proposal rule, apply the Cauchy-Schwarz inequality:Equality holds when the two factors are proportional almost everywhere, giving the minimum-variance importance distributionFor the present nonnegative integrand, normalization givesUnder this proposal, is constant, so the variance is exactly zero. If sampling is wanted, its distribution function is , with inverse . In general the optimal proposal's normalizing constant can itself be the unknown integral, limiting this zero-variance construction's practical use.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 47 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14A linear congruential generator starts with an integer seed and iteratesThe outputs lie in and are used as pseudorandom numbers approximating a uniform distribution. They are deterministic once the seed is fixed. The largest possible period is , since there are only states; good period alone does not establish independence or good multivariate uniformity.
The full-period criterion for a mixed congruential generator says that period for every seed occurs exactly whenFor , these conditions reduce toThe multiplier must satisfy both and . A positive shift alone is insufficient: for example, a shift divisible by three cannot give period when the multiplier is one modulo three. If the required coprime shift has already been chosen, the condition on the multiplier alone is for an integer .
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 4 iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Cluster analysis groups observations without given class labels. It starts by deciding what similarity means, usually through a dissimilarity matrix. Euclidean distance is natural for comparable continuous coordinates; a Mahalanobis distance can account for differing scales and correlations when a meaningful nonsingular covariance estimate is available. Scaling and variable selection can change the groups. Binary, ordinal or categorical data may need a different dissimilarity, rather than arbitrary numerical codes and Euclidean distance.
Agglomerative hierarchical clustering begins with singleton groups, repeatedly merges the pair with smallest intergroup dissimilarity, and records the merges in a dendrogram. The height represents the algorithm's merge criterion. Cutting the dendrogram gives partitions at different resolutions, and merges cannot subsequently be reversed. In single-linkage clustering, the criterion is the nearest cross-pair distance; this detects chains and nonconvex groups, but a thin bridge can connect otherwise separated clouds. Complete-linkage clustering uses the farthest cross-pair distance and tends to produce compact groups, at the cost of sensitivity to extreme points. Average-linkage clustering uses the mean cross-pair distance, lying between these two criteria for a given pair of clusters.
For squared Euclidean geometry, Ward clustering merges the pair that least increases the within-group sum of squares. Expanding deviations about the merged mean givesThis favors low within-group dispersion, but interpreting it as a sum-of-squares increase requires Euclidean data. Different software may plot a rescaled height, so the vertical units of a dendrogram from Ward clustering must be stated.
A nonhierarchical alternative is k-means clustering. For a prescribed , minimizeAt fixed assignments, expanding squared distances or differentiating shows that the minimizing is the group mean. At fixed centroids, each point is assigned to a nearest centroid. Alternating these operations does not increase ; with a consistent tie rule and nonempty groups it reaches a locally stable partition. Initialization matters, so use multiple starts, and give an explicit rule for empty groups. It favors roughly spherical clusters and is sensitive to outliers and scaling. It cannot be expected to reproduce a nonconvex single-linkage partition.
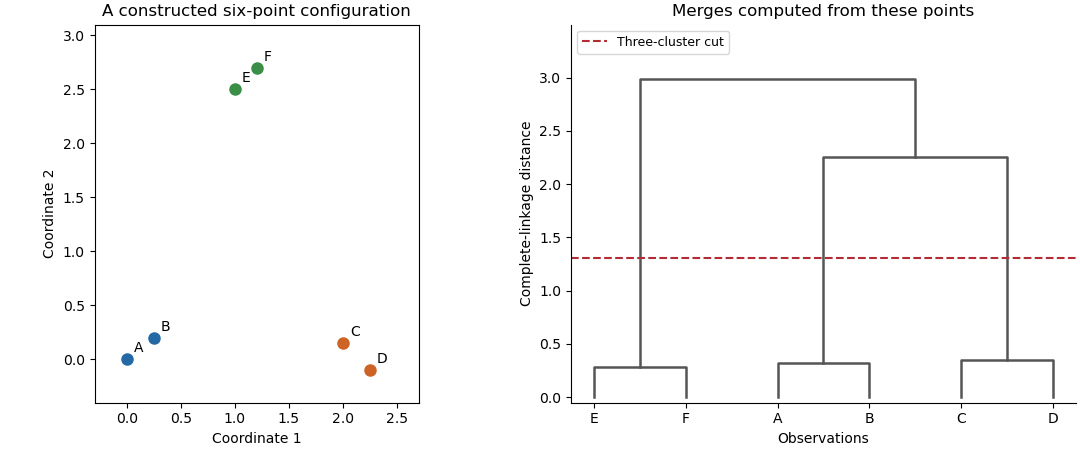
An original point configuration and its computed complete-linkage dendrogram with a three-cluster cut
. Details. The sketch displays a constructed point configuration and the complete-linkage merges computed from its actual Euclidean distances. A cut between the within-pair and between-pair merge heights yields three groups. Such visual separation is useful evidence, not proof of a uniquely correct number of populations. Select a resolution using subject knowledge, stability under resampling, separation diagnostics or the change of with . Clustering always gives a partition even for unstructured data, and different distance or linkage choices can yield different sensible summaries. Clustering is an exploratory construction whose conclusions depend on the geometry and the chosen resolution.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 4 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Factor analysis models a large set of correlated measurements using a smaller collection of shared latent factors and variable-specific variation. A classical orthogonal factor model isTake , centered errors, and positive specific variances for the inverse-covariance and likelihood formulas below. The factor loadings form the matrix , and the model covariance isThus for , ; the common latent factors explain off-diagonal correlation. The communality of variable is , and . For standardized variables this is . The specific variance represents measurement noise or genuinely unshared variation; it is not another common latent factor.
This differs from principal component analysis. A principal component maximizes projected total variance and is a determined linear score after choosing its direction; a factor model attempts to explain shared covariance while reserving diagonal specific variance. Low-dimensional PCA truncation can help initialize a factor fit, but it does not justify setting all specific variances to zero. Latent factors are unobserved, not directly observed scores. When the latent factors and the errors are jointly Gaussian, their conditional mean iswhich supplies one factor-score estimate, with remaining uncertainty. This follows from the block conditional normal formula in Question 1; it does not make the latent factor uniquely recoverable from one observation.
For the Gaussian likelihood, use the empirical covariance . Fit the factor model by minimizing subject to admissible specific variances. Other approaches estimate communalities and extract latent factors from the reduced correlation matrix. Choose using substantive plausibility, a scree plot, fitted residual correlations and model-fit assessment. Under local identifiability, a likelihood goodness-of-fit count for the covariance model iswhere the subtracted rotational dimension must be removed from the loading parameter count. This count alone does not establish identifiability, and boundary fits with zero specific variance need special care.
Factor rotation addresses interpretability and nonuniqueness. For every orthogonal matrix , replace by ; then , so the fit is unchanged. The absolute orientation of unrestrained latent factors is therefore not identified by the covariance. Varimax rotation chooses orthogonal axes favoring a simple pattern of large and small squared loadings. Oblique rotation can permit correlated latent factors, provided their covariance is transformed consistently. Sign changes and permutations are further harmless relabelings; an interpretation must state its chosen convention.
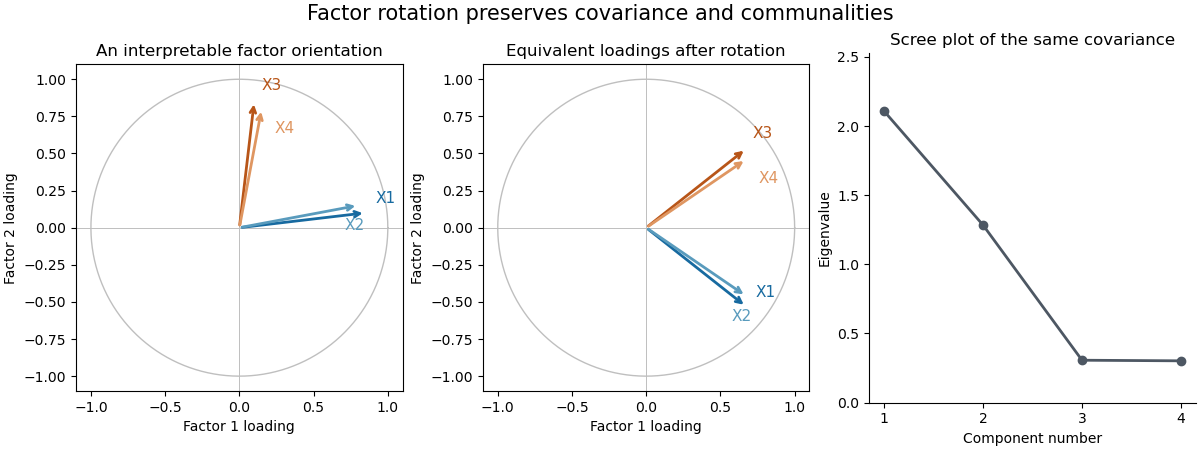
The sketch uses four standardized hypothetical measurements sharing two orthogonal latent factors. Rotating the factor coordinates changes the loading descriptions while preserving every implied covariance and communality; the scree plot belongs to that same constructed covariance matrix. Factor analysis separates shared variation from specific variance, and its latent factors require an identifying or interpretive orientation.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 4 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Multivariate analysis of variance extends analysis of variance to vector responses. For example, a treatment may affect several correlated physiological measurements jointly. Separate univariate tests do not use the correlation geometry and require adjustment if they are interpreted as one multiple-testing procedure. A joint test asks whether group mean vectors differ in any direction.
In a one-way model, take independent , , , with a common positive-definite covariance. Put , and let and be group and overall sample means. The within-group and between-group scatter matrices areExpanding around each group mean makes the cross terms vanish, giving total scatter . To test , use the Wilks lambda statisticwhere solve the generalized eigenvalue problem and is nonsingular. Under the alternative, maximize the normal likelihood at the group means and covariance ; under the null, use the overall mean and covariance . Their likelihood ratio is , so small rejects equal means. Under the null, orthogonal projections of the Gaussian data give independent and , supplying its null calibration. Here is nonsingular almost surely when . Merely having more total observations than responses is not enough if group fitting consumes too many statistical degrees of freedom.
The test is invariant under a nonsingular linear change of response coordinates: both determinants acquire the same factor . The directions associated with large identify mean separation relative to residual variability. With one response it becomes the ordinary ANOVA F-test. With two groups, writing and , the version using Hotelling's T-squared statistic iswith . This formula demonstrates explicitly how the covariance weights a group difference.
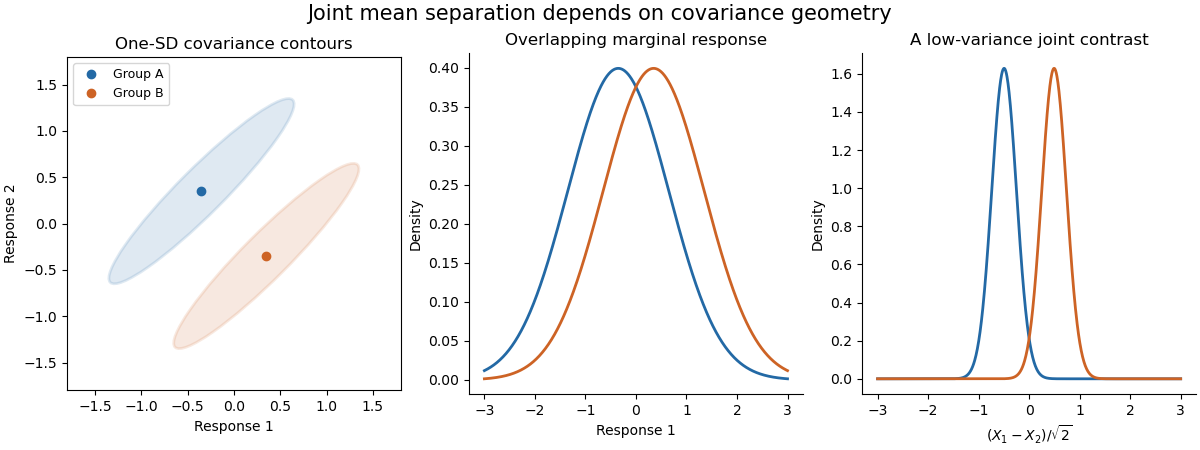
The sketch shows hypothetical groups with strongly positively correlated responses and mean separation along their low-variance contrast. Marginal comparisons can look weak even when the joint comparison is informative. The ellipses represent individual-response covariance, not confidence regions for the means. Independence of observations, approximate multivariate normality and common covariance are substantive assumptions; outliers and unequal covariance can invalidate the usual calibration. Follow-up contrasts can identify the affected responses or groups, with appropriate multiplicity control. MANOVA uses shared covariance to test a multivariate mean difference, rather than testing unrelated coordinates in isolation.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 2 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Extend the selected to an orthonormal basis of eigenvectors, writing it as . For a unit vector orthogonal to it, , and thereforeA unit eigenvector attains equality. Thus is a unit eigenvector for the largest eigenvalue on , and the maximum is . If the largest eigenvalue is repeated, a second orthogonal vector in that eigenspace is allowed and ; there is no uniquely determined first pair of directions.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 2 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be the eigenvalues of the symmetric covariance matrix , and choose an orthonormal basis of eigenvectors . If has unit length, then andEquality is attained by , and precisely by unit vectors in the top eigenspace. Hence choose to be any unit eigenvector for the largest eigenvalue; the maximum variance is . This proves the maximizing property of the Rayleigh quotient, rather than merely specifying a stationary point.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 1 iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Applying the conditional multivariate normal distribution to the two differences gives, more generally,At the result isBoth this law and the marginal law have mean zero, but the conditional variance is smaller. Specifically, with , the conditional variance is the marginal variance times . The assumptions imply , so the decrease is strict. Matching the breadth differences to zero gives information about the correlated length differences; it does not force the length differences themselves to be zero. The residual uncertainty remains positive. The original PDF has the between-son differences used here; the self-subtractions in the converted TeX are transcription errors.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 1 ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Taking the first marginal of the normal vector in part (i) givesEquivalently its variance is ; the covariance between the two sons must be retained when taking their difference.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 46 1 i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put , andThe difference vector is . Its mean is zero because the two sons have the same mean vector. Its covariance matrix isFor example, . ThusThe positive definiteness assumption supplies and : these are eigenvalues of the original matrix on within-son contrast and between-son difference directions. In particular the resulting difference covariance is positive definite.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 45 4 v Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Five consequences of the ancestral recombination graph are:
- Linkage disequilibrium and its distance dependence. Nearby sites often inherit the same local genealogy, so mutations on their shared ancestral branches produce correlated alleles. The chance of an ancestral breakpoint between sites increases with their genetic distance, reducing shared genealogy and, on average, linkage disequilibrium. This gives the genealogical explanation of the two-locus decay calculation.
- Haplotype blocks and recombination hotspots. With a varying recombination map, the ARG has relatively few breakpoints within low-recombination regions and many near recombination hotspots. Long intervals can consequently retain a small number of common ancestral haplotypes, while genealogical relationships change more frequently across the intervening regions. This explains why LD blocks are heterogeneous rather than equally spaced units.
- Mosaic inheritance and shared ancestral tracts. Backward splits assign different pieces of one contemporary chromosome to different ancestral chromosomes. Two sampled chromosomes can therefore share a recent ancestor over one interval but not its neighbors. For a specified total of independent ancestral meioses, a tract of genetic length has approximately expected crossovers under a Poisson crossover model, so its probability of remaining intact is . This relates long IBD segments to recent common ancestry, while distinguishing tract-boundary sampling from length-biased sampling at a random genomic point.
- Incompatible site patterns and four observed gametes. Under an infinite sites mutation model on a single rooted tree, the descendant sets of two mutations are nested or disjoint. They cannot cross, so all four haplotypes cannot occur. Recombination permits different local trees: one site's derived clade can be and the other's , producing all four without repeated mutation. The four-gamete test therefore detects a failure of the unrecombined, single-mutation-per-site model. Recurrent mutation would be an alternative explanation if the infinite-sites assumption were dropped.
- Variation in local diversity and allele frequencies. Coalescent mergers describe genetic drift; their random times produce different branch lengths and descendant-group sizes. Recombination makes these genealogies vary along the chromosome. Conditional on a local genealogy, its segregating site count is Poisson with mean , so a longer tree tends to contain more variants. A mutation on a branch subtending of the samples appears at sample frequency . Together, random branch lengths, descendant counts and mutations explain heterogeneous local diversity and the distribution of allele frequencies without requiring selection.
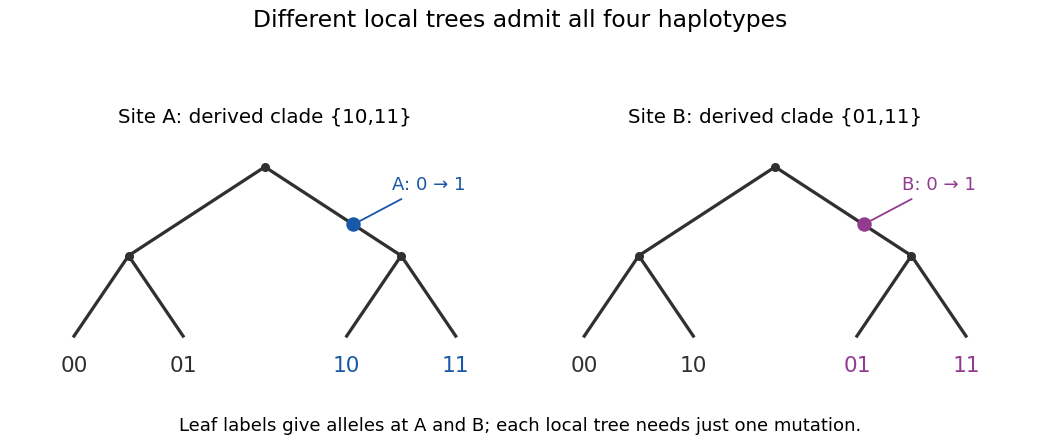
Different local genealogies can generate all four haplotypes with one mutation per site
. Details. Shared ancestry explains correlation; recombination makes ancestry a mosaic; mutation on the resulting branches converts genealogy into observed variation. These explanations use the neutral ARG, with a variable recombination map where stated. Selection, population subdivision or changing population size can also be studied genealogically, but require extending the event model rather than being consequences of the constant-size panmictic neutral process alone.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 45 4 iv Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14An ancestral recombination graph, or ARG, is the directed ancestry of a sample of chromosomal segments when ancestral lineages can both coalesce and undergo genetic recombination. It records which ancestral material each lineage carries, the times of events and the recombination breakpoints. At any fixed genomic position, following only the ancestral material at that position gives a marginal phylogenetic tree. Different positions can have different trees, while sharing substantial parts of their history. The graph is acyclic in time, although its underlying undirected graph can have loops because a lineage splits backwards and its ancestors can later rejoin.
For the standard neutral, constant-size, randomly mating diploid model, measure time in generations and set , where is the recombination rate across the whole segment. The backward process is a continuous-time Markov jump process on collections of lineages carrying ancestral material:
- Each unordered pair of current lineages coalesces at rate one. The parent lineage carries the union of their ancestral material, with common ancestry recorded at overlapping positions. With lineages the total coalescence rate is . The full ARG permits a pair to merge even when its carried material is disjoint; such an event creates no merger in a local tree at that instant.
- A lineage splits into two parental lineages at a recombination breakpoint. With a uniform recombination map on a segment of normalized length one, the intensity of breakpoints along a fully ancestral lineage is per unit length. If a lineage carries only part of the segment, only cuts leaving ancestral material on both sides need be retained, giving rate , where is the span between its leftmost and rightmost ancestral positions. Material to the left goes to one parent and material to the right to the other. A gap within that span still permits a cut that separates two carried pieces.
For a state with lineages, independent exponential event clocks give total rateThe next waiting time has exponential distribution with rate ; choose its event type in proportion to the corresponding rate. A coalescing pair is uniform among unordered pairs; a recombining lineage is selected with weight and its breakpoint is uniform over its active span. With a nonuniform genetic map, use the corresponding integrated intensity and map-weighted breakpoint distribution. Initially all sample lineages span the whole segment, so the initial rate is . Ancestral material no longer needed after its sample copies have found their local common ancestor can be pruned.
Mutations are placed independently on the resulting ancestral branches, with local rate in coalescent units for a locus having scaled mutation parameter . Without recombination, the graph reduces to a single Kingman's coalescent tree. With recombination, each individual locus still has that marginal coalescent distribution, but trees at different loci are dependent. The ARG combines backward pairwise mergers with backward recombination splits; local trees are its position-specific projections. The neutral two-locus construction is developed in Hudson's two-locus model.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 45 4 iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Suppose a disease-risk mutation first occurs on an ancestral haplotype. Descendants carrying the risk allele initially share that surrounding haplotype. Historical genetic recombination progressively replaces the flanks while retaining the disease allele, leaving linkage disequilibrium between the causal variant and some nearby genetic markers. A noncausal marker can therefore have different allele frequencies in affected individuals and suitably chosen controls. This is the basis of association mapping.
One first tests dense markers or multi-marker haplotypes for genetic association with the disease phenotype. Strongly correlated single-nucleotide polymorphisms can be represented by tag SNPs to locate an associated region efficiently. Within that region, denser genotyping and examination of disease-associated haplotypes locate historical recombination breakpoints: segments retained across independently recombined disease-bearing chromosomes are stronger candidates for containing the causal allele. Compare affected and unaffected carriers as well, since incomplete penetrance and other risk factors can prevent a perfect haplotype-disease correspondence.
Association mapping can achieve fine resolution because it uses recombination accumulated over many generations, rather than only the few observed meioses in a present-day linkage pedigree. Resolution depends on the local recombination history: a long region of strong LD may identify a disease-associated block while leaving many variants statistically indistinguishable. Additional informative haplotypes or populations with different LD can help separate them. Conversely, very weak LD requires closer marker spacing to avoid missing the causal region.
Population stratification must be controlled by ancestry-matched comparisons, statistical adjustment or an appropriate family-based association design, since ancestry can affect both disease frequency and marker frequency. A marker association alone establishes neither causality nor identity of the disease gene; nearby correlated variants must be distinguished by further genetic and functional evidence. Use LD to detect a disease-associated ancestral segment, then use historical recombinants to narrow the causal interval. The correlation between causal variants and their surrounding haplotypes, together with the value of representative markers, is illustrated in the HapMap study.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact