Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

A Monte Carlo estimator is a random approximation obtained from simulated samples, commonly a sample average or a weighted sample average.
The spatial translation operator is the unitary operator generated by momentum. For displacement ,where is the reduced Planck constant. In a position representation in quantum mechanics, , so its action on a wavefunction isA localized wave packet is therefore displaced by . A momentum eigenstate of eigenvalue instead acquires the phase .
The canonical commutation relation givesThus the expectation value of the position operator in the translated quantum state increases by .
For an operator-valued scalar field, the compatible translation convention isInfinitesimally this means . The field's coordinate argument labels where a local observable is evaluated; is the position operator of a particle. These meanings explain their differently ordered conjugation formulas. [ref]
Quantum Field Theory by David Tong. Author supplement More translation invariance, formulas for translated position eigenstates, the position operator and a local field; hbar restored here
A missingness mechanism is ignorable for likelihood or Bayesian inference about outcome-model parameters when the missingness-model factor can be omitted without changing that inference. missing at random together with distinct outcome and missingness parameters is a standard sufficient condition for likelihood inference; Bayesian inference also requires the corresponding prior factorization, so outcome and missingness parameters are independent a priori.
If counts states in a narrow experimental energy window, the Boltzmann entropy isChanging the macroscopic resolution by a fixed factor changes only by an additive quantity of order , whereas itself is of order in the thermodynamic limit. The dependence on the precise energy-window width is therefore negligible for macroscopic thermodynamics.
Gauss's law for magnetism is . Its integral form says that the net magnetic flux through every closed surface vanishes, so the normal magnetic field is continuous across an ordinary interface.
A stochastic volatility model gives an asset a separate random volatility or variance process. For example, a stock can have pricing dynamics , with random , instead of the constant variance of the Black-Scholes model. The Heston model uses a CIR model for ; an Ornstein-Uhlenbeck process can instead model a signed volatility whose square is the variance.
The extra state lets current uncertainty affect future uncertainty, and correlated asset and variance shocks change the distribution of future returns and option values. This differs from a local volatility model, where the coefficient is a deterministic function of time and current spot alone.
With two independent sources of uncertainty and only a stock and bank account, the variance risk is generally not fully hedgeable. A physical variance model then does not uniquely determine its pricing dynamics: a volatility-risk premium or additional traded instruments must be specified. Heston's original model makes the joint asset/variance system tractable through an affine characteristic-function calculation.[ref]
A fixed-income security promises cash flows at specified future dates. Its price depends on the term structure of interest rates and the relevant credit and liquidity risks.
For the normalized equations and on the positive quadrant,is a first integral. It is nonnegative, strictly convex, and tends to infinity at the boundary and at infinity. Every positive regular level is therefore a compact simple closed curve traversed by one periodic orbit.
In a linear-quadratic-Gaussian control problem, the optimal control applies the full-information linear-quadratic feedback law to the conditional state estimate. The control gain is independent of the state-estimation error covariance.
For complex square matrices and , the Sylvester equationhas a unique -by- matrix solution for every exactly when the spectra of and are disjoint. The linear map has eigenvalues : triangularize and , or use its Kronecker product representation with columnwise vectorization. It is invertible exactly when none of those differences vanishes. Over another field, the same criterion uses the polynomial roots of the two characteristic polynomials in an algebraic closure.
A block upper triangular matrix is a block matrix with square diagonal blocks and zero blocks below them. Its determinant is the product of the determinants of its diagonal blocks.
A system of linear equations imposes several linear equations on the same unknowns. In the compact form , the matrix contains their coefficients, the vector contains the unknowns, and the vector contains the required outputs. Over the real numbers, the following examples exhibit the three possible outcomes: one solution, infinitely many solutions, or no solution.
For and , adding the two linear equations gives , hence and . Each linear equation describes a line in the plane; the two lines meet only at . Substitution checks both requirements: and . The two measurements together determine both unknowns.
Keeping only leaves a whole line of solutions:For instance, gives . The direction belongs to the kernel of the linear map : its two contributions cancel. Moving in that direction changes the unknowns without changing their measured sum. The solution line is an affine space, translated away from the origin.
For and , the second linear equation instead demands . The parallel lines never meet. In the augmented matrix, subtracting twice the first row from the second is an elementary row operation that exposes the contradiction:The last row says . A zero row of coefficients is harmless only when its appended entry is also zero.
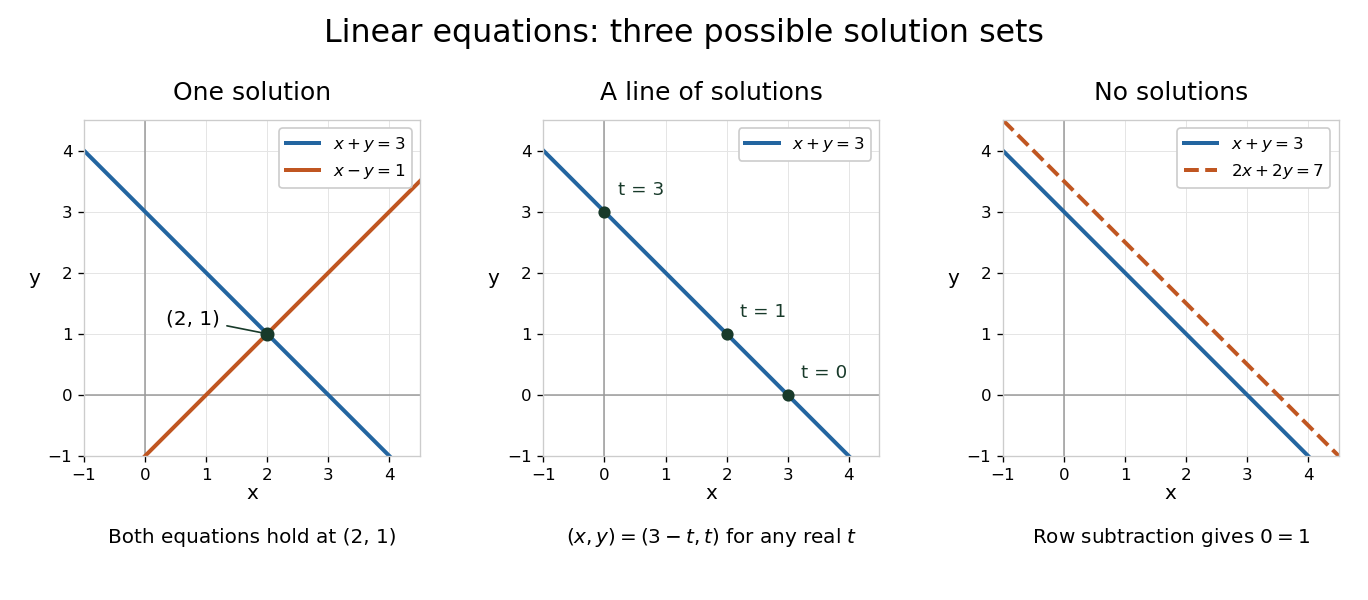
The column viewpoint unifies these pictures. If are the columns of , then : a linear combination of those columns. A linear system is consistent precisely when lies in the column space, the image of a linear map represented by . Once one solution is known, every solution is with , since . Conversely, subtracting any two solutions gives an element of the kernel. Thus the kernel measures freedom, while the image of a linear map decides existence. A consistent linear system has a unique solution exactly when its kernel is .[ref]
Counting linear equations alone does not tell us how much information is present. If the second requirement were , it would repeat , so the two linear equations would still leave the same solution line. The matrix rank counts independent requirements. For a consistent linear system with unknowns and matrix rank , the rank-nullity theorem gives as the dimension of the kernel. This is the number of independent directions in which a solution can move. In the single-measurement example, one measured combination leaves one direction of freedom; in the sum-and-difference example, neither unknown can change without changing an output.
Two square matrices over the same field are similar if for an invertible matrix . They can describe one linear operator using two different ordered bases, with the same basis used for input and output in each description. Fix the convention : is the old coordinate vector, the new coordinate vector, and the columns of are the new basis vectors in old coordinates. This is the convention of the change-of-basis matrix.[ref]
Linear Algebra Done Right by Sheldon Axler (4th edition). §3D, Theorem 3.84, printed p. 93: change-of-basis formula; the matrix there converts in the opposite direction to our
For a concrete linear operator on the physical plane, let double horizontal components and multiply vertical components by five. In the old standard basis , its matrix of a linear map is . Choose the new ordered basis with , . ThenThe second column of says . Its off-diagonal entry records how the chosen basis vectors describe the output; the physical linear operator still stretches along the old horizontal and vertical directions.
Take the physical vector . Its two coordinate vectors, and the two descriptions of , areReconstruction gives . The output coordinate vectors differ, but the endpoint in the physical plane is the same.
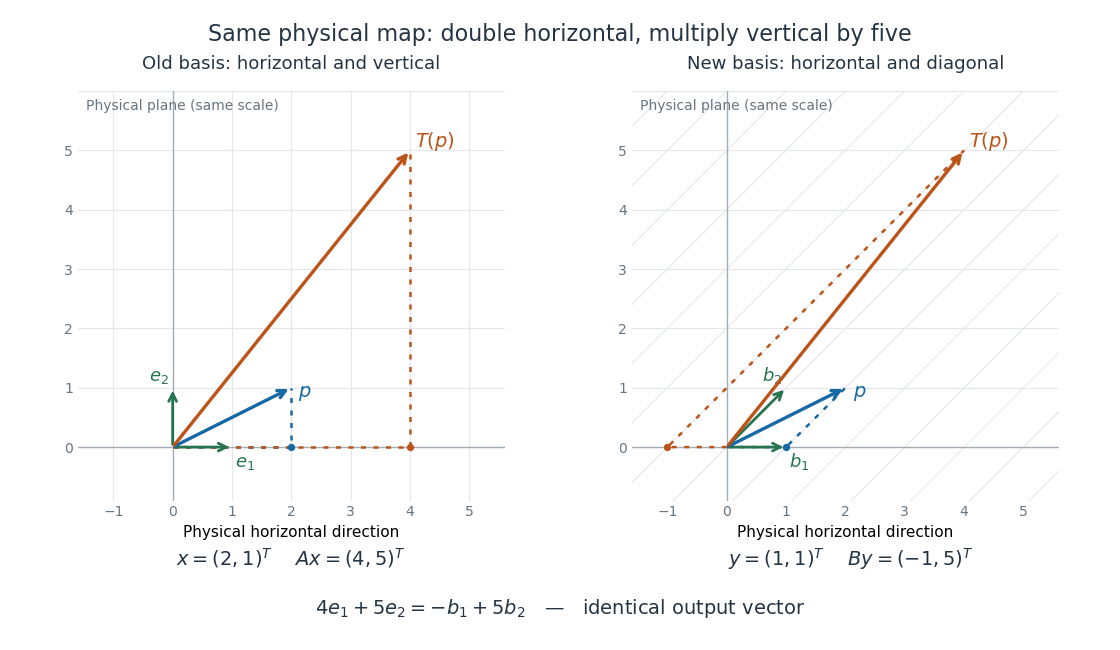
One linear operator and the same two physical vectors described in a standard basis and an oblique basis
. Both panels use the same physical plane and scale. The blue arrow is , and the orange arrow is . Dotted paths reconstruct them from their respective basis vectors; the right grid follows , . Details.This is why matrix similarity is useful: a convenient basis can simplify calculations without changing the linear operator. A diagonalizable matrix can be replaced by a diagonal matrix, making repeated application a calculation with powers of its eigenvalues. In the example, makes the two independent stretch factors visible, while expresses the same action in directions chosen for another purpose. Matrix similarity invariants separate properties of the linear operator from features of its address system.
A Householder transformation is a reflection that leaves every direction in a chosen hyperplane fixed and reverses its normal direction. For a real unit vector , its matrix isTo understand the formula, decompose any vector into its orthogonal projection onto the normal and a perpendicular component:Then . Subtracting twice the normal component changes its sign while retaining everything parallel to the mirror. A nonzero normal gives the equivalent formula , so normalization can be deferred.
For example, take . Its mirror is the straight line , andThe midpoint of these two vectors is , which lies on the mirror; their connecting segment is parallel to its normal. Both vectors have Euclidean norm five.
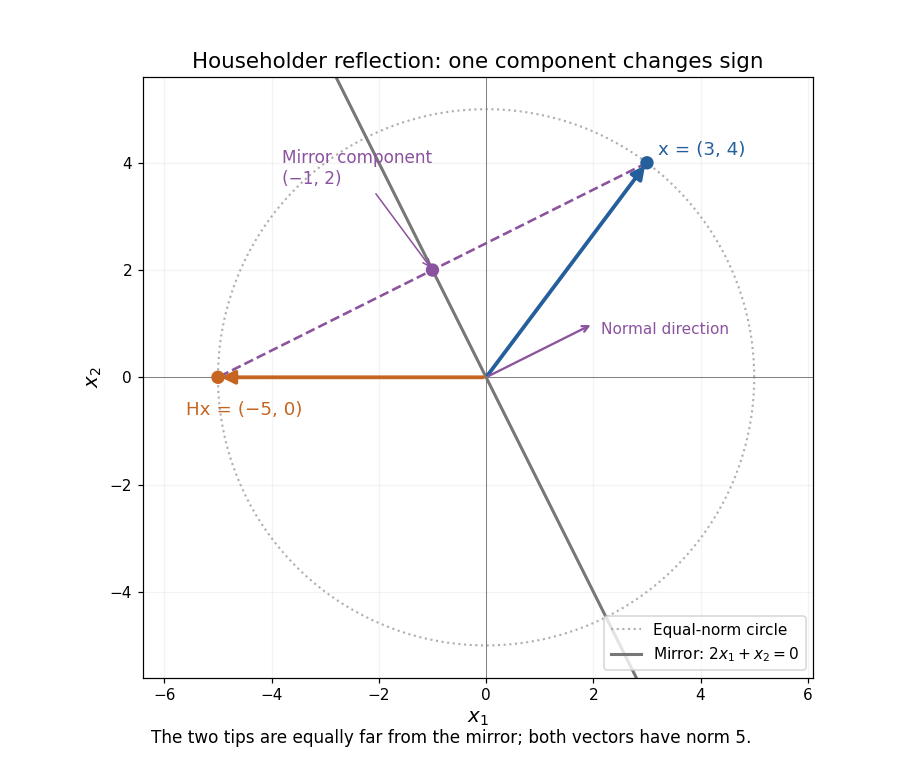
Several useful properties follow from this decomposition. The Householder reflection is a symmetric matrix and an orthogonal matrix:Reflecting twice restores the original vector; Euclidean norms and inner products are preserved. The eigenvalue is along and on , so . A reflection reverses orientation even though it preserves lengths.
The computational payoff is that the mirror can be chosen to send a whole vector onto one coordinate axis, eliminating several entries at once. Householder QR decomposition repeats this operation on the remaining parts of successive columns. For a real symmetric matrix, applying the same Householder reflection on both sides gives a matrix similarity that preserves symmetry and eigenvalues; this is the basis of Householder tridiagonalization.
Alston S. Householder's 1958 paper Unitary Triangularization of a Nonsymmetric Matrix develops this elimination method. Its motivation includes reducing the arithmetic needed for triangularization while retaining the conditioning advantages of orthogonal transformations. [ref]
https://web.stanford.edu/class/cme324/classics/householder.pdf. Householder (1958), Journal of the ACM 5(4), pp. 339–342: original paper
Over the complex numbers, for a unit is Hermitian and unitary, with the star denoting the conjugate transpose; the coordinate-axis construction below is stated for real vectors.The Berhu, or reverse-Huber, penalty with threshold isIt behaves like the absolute value near zero and quadratically for large coefficients.
With axisymmetric streamfunction , the regular normalized similarity profile isIts volume flux grows linearly with , expressing fluid entrainment.
For axial velocity in the boundary-layer approximation,is independent of . If and are characteristic centre-line speed and width, then , while the momentum balance gives . Thus
Turaev torsion is a sign-refined form of Reidemeister torsion for manifolds and chain complexes. For a knot exterior with meridian and first Betti number one, its group-ring normalization satisfies
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact