Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Conditioning reduces entropy
Conditional entropy Created 2026-09-24 Updated 2026-10-14
For finite discrete random variables, conditional entropy is the average remaining information entropy of after the value of is known:Each observation changes the probability distribution used to describe ; the average weights that uncertainty by how often the observation occurs. An observation can increase uncertainty for one particular outcome, even though conditioning reduces entropy on average for finite variables.
For example, let choose with probabilities , and let report whether . If it reports yes, there is no remaining uncertainty. Otherwise the conditional probabilities are , whose information entropy is bits. The two reports each occur with probability , so of a bit. The original uncertainty was bits: this observation removes exactly one bit on average.
If is a function of , then : the observation determines the answer. If and are independent random variables, then : the observation gives no improvement. These endpoints make conditional entropy useful for separating relevant observations from irrelevant ones. They also lead to the chain rule for information entropy, , which counts the first uncertainty and the remaining uncertainty without double counting.
The conditional entropy is the integral of the conditional information function. Its chain rule expresses the entropy of a join of measurable partitions as unconditional entropy plus conditional entropy. Conditioning reduces entropy, also for countable partitions of finite entropy.
Conditional entropy rate 2026-10-14
For a strictly stationary process on a finite alphabet, put and for . Each is the average remaining uncertainty in the next symbol after its history is known. More history can improve prediction, so this sequence is nonincreasing:The inequality uses conditioning reduces entropy; the last equality uses strict stationarity. Nonnegative therefore have a limit. By the chain rule for information entropy,The Cesàro mean converges to the same limit, proving the equality with the entropy rate. This is a statement about average information entropy. A constant almost-sure limit of the realized information content requires the further hypotheses in the Shannon-McMillan-Breiman theorem; stationarity without ergodicity in an information source explains the distinction.
Conditional mutual information Created 2026-09-24 Updated 2026-10-14
For finite discrete random variables, conditional mutual information measures the average reduction in uncertainty about from observing , when is already known. With base-two logarithms, it is measured in bits:The second expression follows from the chain rule for conditional entropy and makes the symmetry in visible. Equivalently, compute the mutual information separately in each conditional probability distribution and then average:Here is the Kullback-Leibler divergence, also computed with base-two logarithms; zero-probability terms contribute zero. The Gibbs inequality gives , with equality exactly when and have conditional independence given : the conditional joint probability mass function factors for every of positive probability.[ref]
For a fully computed example, take independent random variables that are fair bits, and let , where is exclusive or. The complete joint probability distribution has only these four positive entries:
Table 1. .
Every pair has probability , so . But . Given , the pairs each have conditional probability , while both conditional marginals are fair. ThusGiven , the pairs give the same calculation. ThereforeThe conditional entropy calculation tells the same story: because either value of leaves fair, whereas because . Learning the exclusive or does not reveal either bit alone; it reveals whether they agree, so learning one then determines the other.
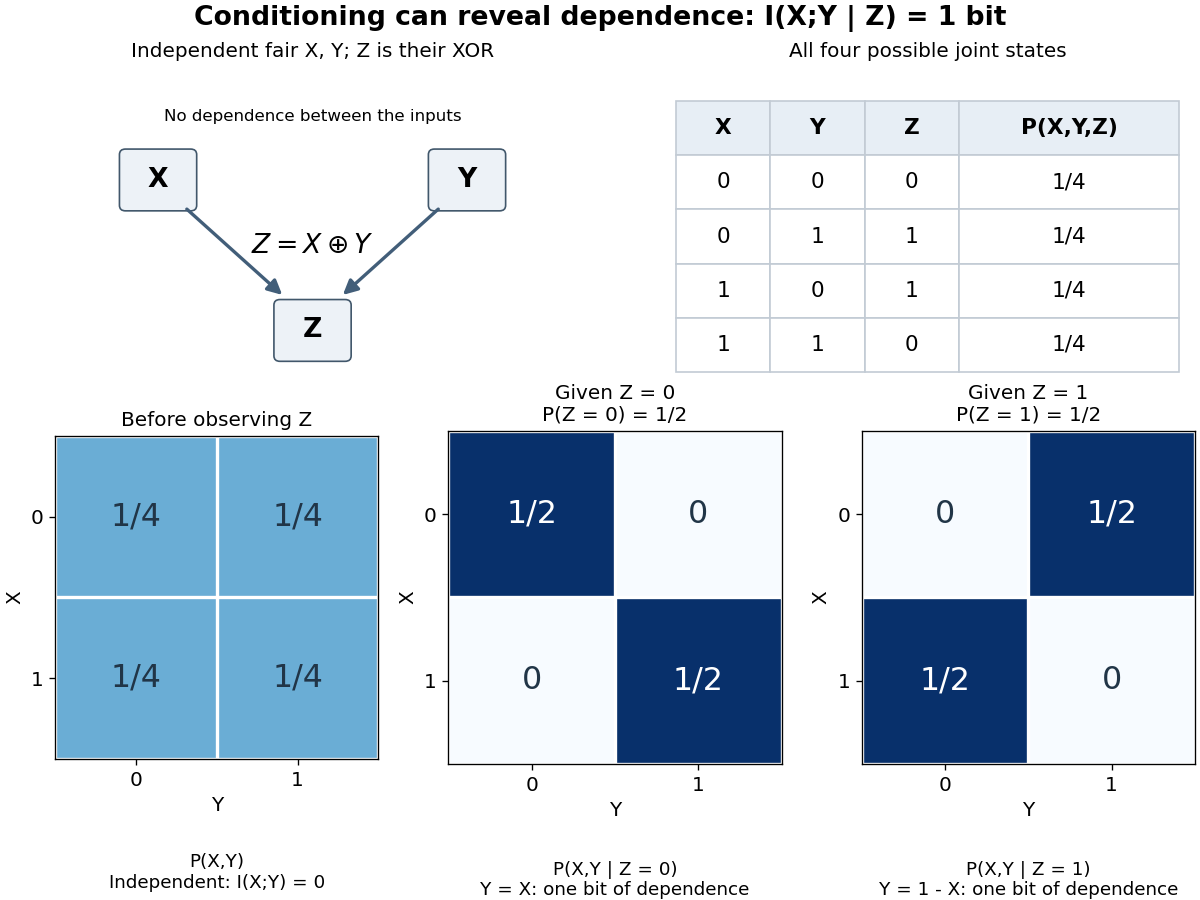

This example distinguishes conditional independence from ordinary independence. It also disproves the claim that conditioning always reduces mutual information, despite conditioning reduces entropy. There is no general ordering between and : the example above increases it from zero to one, while taking and for a fair bit decreases it from one to zero. The chain rule for mutual information explains why both are possible.[ref]
Conditional mutual information is useful for asking whether an additional observation tells us anything after information already available has been accounted for. Its zero case expresses conditional independence exactly; in a Markov chain, this is the step that turns the chain rule for mutual information into the data processing inequality.
Conditioned entropic Ruzsa distance of a summand Created 2026-09-24 Updated 2026-09-24
If are independent random variables in , thenIndeed, conditioning reduces entropy and independence giveIn , , so conditional entropy under a deterministic change of variables shows that the left-hand side is unchanged when and are exchanged. Averaging the displayed bound with its exchanged version gives the result.
Entropy rate 2026-10-14
The entropy rate measures average new uncertainty per emitted symbol of a stochastic process. Predictability from earlier symbols can make this much smaller than the information entropy of one symbol. For example, a binary Markov source can emit a fair bit at every time while repeating its previous bit with probability : each individual symbol has one bit of uncertainty, but the entropy rate is only about bits per symbol.
For a finite alphabet source , definewhen the limit exists. Base-two logarithms give bits per symbol. Multiplying by a fixed emission frequency gives bits per unit time; the symbol rate and the uncertainty of the sequence are different inputs. A strictly stationary process on a finite alphabet always has an entropy rate, equal to its conditional entropy rate.[ref]
6.441 Information Theory (Spring 2016 lecture notes) by Yury Polyanskiy and others. §5.5, Definition 5.1 and Theorem 5.5, printed p. 57: block entropy and stationary conditional-entropy limit
For an independent and identically distributed source, the chain rule for information entropy gives , hence . With dependence, conditioning reduces entropy and makes the past useful. The examples under Markov information source show this benefit using exact finite-block calculations.
Fano's inequality via an error indicator Created 2026-10-06 Updated 2026-10-14
Under the hypotheses of Fano's inequality, let , , and let be the indicator random variable of an error. Its probability of being one is . The in the displayed bound denotes binary entropy in bits. Since is a deterministic function of , . Applying the chain rule for conditional entropy in both orders gives the exact decompositionThe first term is bounded by , because conditioning reduces entropy. For the second term, fix a report : if , then is known; if , then lies among at most other symbols. Maximum entropy on a finite alphabet bounds the latter uncertainty by . Averaging over the reports and the error flag givesThis proves Fano's inequality. Events of zero probability contribute zero to this average, so the proof also covers without assigning a conditional distribution to an impossible event.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_notes.pdf. Weissman, Ochoa and Tatwawadi, EE376A course notes, Section 5.7, proof of Theorem 46
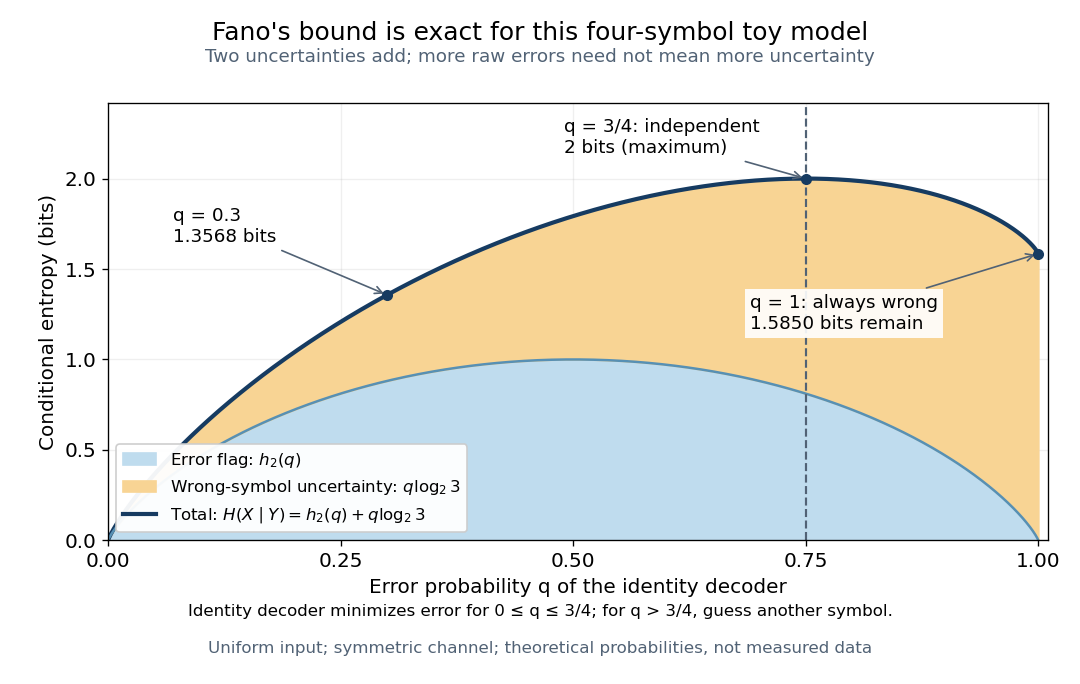
The four-symbol entropy budget peaks at chance-level error and separates the error flag from the three alternatives
. Details. 
The decomposition also explains equality. The first bound is exact when the indicator random variable and are independent random variables: knowing the report does not change the error probability. The second is exact when, for every report with positive error probability, the wrong-symbol conditional distribution is uniform on all alternatives. Both conditions hold in the four-symbol toy channel of Fano's inequality. At , the second condition is vacuous; at , the flag is constant but three alternatives remain, giving . For , there is just one alternative after an error, so the second term vanishes: all remaining uncertainty is whether the single alternative must replace the guess.
Joint entropy Created 2026-10-14 Updated 2026-10-25
Joint entropy is the information entropy of an entire random vector, treating its coordinates together as one outcome. For random variables with finite alphabets and joint probability mass function ,It is measured in bits. The distinction from separate information entropies is whether shared uncertainty is counted once or repeatedly. Two copies of the same fair bit have joint entropy one bit, since only and can occur. Two independent fair bits have joint entropy two bits, since all four pairs are possible and equiprobable.
For a less symmetric example, assign probabilities to respectively. ThenHere is fair, while . Thus and bits, where is binary entropy. Adding the separate information entropies would give approximately bits, overcounting by the mutual information bits.
The chain rule for information entropy makes the shared information explicit:In this example is certain given and fair given , so its average conditional entropy is bit. Sending the first coordinate changes how much uncertainty remains in the second. A prefix code with codewords
0, 10, 11 for the three possible pairs has average length bits, exactly the joint entropy in this stipulated law.For finite alphabets,The lower bound follows because knowing the full random vector determines every coordinate; the upper bound follows from conditioning reduces entropy in the chain rule for information entropy. Equality in the upper bound means joint independence. The difference from that upper bound is total correlation, whose noisy parity total correlation example shows why separate pairwise comparisons need not find all the dependence.
Madiman–Tetali entropy inequality 2026-10-14
For a nonempty ordered coordinate set , write and . An exact -cover satisfies . A short proof uses the chain rule for information entropy contributions : each conditional subset entropy bounds on the appropriate side, by conditioning reduces entropy. Weighting gives the lower inequality for a fractional packing and the upper inequality for a fractional cover. See Madiman and Tetali, "Information Inequalities for Joint Distributions".
Monotonicity of normalized block entropy 2026-10-05
For a stationary process associated with a finite-entropy measurable partition, is non-increasing. The increments are non-increasing by conditioning reduces entropy, and the chain rule gives . Averages of a decreasing sequence are decreasing.
Monotonicity of normalized subset entropies 2026-10-14
For discrete random variables, normalized subset entropy decreases with subset size. For finite entropies, the chain rule for information entropy and conditioning reduces entropy give . Sum this over all -subsets . Every -subset occurs times, and cancels the normalization factors. This proves . If a marginal entropy is infinite, every one of these subset averages is infinite; otherwise all entropies used in the proof are finite.
The inequality is true for ordinary addition, and also for addition in a group. For any fixed , the translation is injective, so it merely relabels the probability masses in the conditional distribution. Since are independent random variables,Averaging over and using conditioning reduces entropy proves entropy monotonicity under independent addition:There is no requirement that remain in the original finite alphabet. The proof also gives by symmetry. Independence matters: for a nonconstant and , the sum is constant while .
Let and let be the error indicator random variable. Because is determined by , the chain rule for conditional entropy in its two orders givesBy conditioning reduces entropy, . On , knowing determines , so the corresponding conditional entropy is zero. On , at most symbols remain possible for . The maximum Shannon entropy of a probability distribution on at most symbols is . ConsequentlyFor an arbitrary function , repeat the argument with . This is still determined by ; when it is zero, , and when it is one, has at most possibilities for each . Thus Fano's inequality givesEvents of zero probability contribute zero to the conditional average, covering the error probabilities zero and one. If , the left side and error probabilities are zero; the trivial conclusion is handled separately instead of writing as an ordinary finite product.
Past exam of the mathematics course of the University of Cambridge 2002 iii Paper 33 3 Solution Created 2026-10-03 Updated 2026-10-14
Use logarithms to base two, so all entropies are in bits. For a discrete probability distribution and a density operator with eigenvalues , the Shannon entropy and Von Neumann entropy are respectivelyUse . The second definition is basis-independent by the spectral theorem; for a density operator diagonal with probabilities , it agrees with the first.
The classical relative entropy, or Kullback-Leibler divergence, of from isIt is if some has . The quantum relative entropy iswhen the support of is contained in that of , and is otherwise. Matrix logarithms are taken on the corresponding positive supports. In a common eigenbasis this reduces to classical relative entropy; both divergences are nonnegative and are generally asymmetric.
To prove Fano's inequality, let the finite alphabet size be and let indicate an incorrect guess. Since is determined by , the chain rule for conditional entropy first givesExpanding in the opposite order givesConditioning reduces entropy, so , the binary entropy function. When , knowledge of determines and the conditional entropy is zero. When , can lie in at most the alphabet values other than . Entropy on values is at most : its deficit from that number is the nonnegative relative entropy from the uniform distribution. Averaging the two cases therefore givesCombining the two expansions provesThis proof of Fano's inequality via an error indicator works for any alphabet-valued guessing rule, not just an optimal one. If , there is no guessing uncertainty and the claim is simply ; that case is treated separately rather than writing .
Past exam of the mathematics course of the University of Cambridge 2003 iii Paper 13 3 a Solution Created 2026-10-03 Updated 2026-10-14
Write for the number of labelled -uniform hypergraphs with the hereditary hypergraph property, so for . The assertion is nonincrease; strict decrease need not hold, since allowing all uniform hypergraphs gives .
If , heredity forces . If , the desired inequality is immediate. Otherwise choose uniformly from and record its edge indicators as a random vector . Its information entropy, with any fixed logarithm base, is . Deleting a vertex gives the restriction to the edges avoiding . By heredity and relabelling, this restriction has at most possible values, so .
Each edge coordinate occurs in exactly of these restrictions. For completeness, order all the edge coordinates. The chain rule for information entropy expands a restriction entropy as a sum of conditional coordinate entropies. The predecessors retained in a restriction form a subset of all predecessors, and conditioning reduces entropy; hence each restriction term is at least the corresponding full-vector term. Summing over the restrictions counts each full-vector term times. This proves the needed Shearer inequality:Since , division gives . Therefore the normalized speed of a hereditary hypergraph property satisfies
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 11 6 Solution Created 2026-10-03 Updated 2026-10-14
Use discrete Shannon entropy with base-two logarithms. The standard facts needed are the chain rule for information entropy, conditioning reduces entropy, nonnegativity of conditional entropy, and the fact that a uniform distribution on outcomes has Shannon entropy .
Order the coordinates by their indices and put . Applying the chain rule within a coordinate subset and then adding the missing earlier conditioning coordinates givesOn summing over the family, coordinate occurs at least times. Since each is nonnegative,This proves Shearer's inequality without any independence assumption on the coordinates. For countable alphabets, apply the finite-valued assertion to refining finite coordinate partitions; the standard monotone approximation of Shannon entropy gives the same result with extended values. Differential entropy is not the Shannon entropy intended here.
For the graph application, let its bipartition be , with degrees on and on , where . Choose an independent set uniformly from all such sets, and let be its vertex-indicator vector. Then . For put and .
Each vertex of belongs to exactly of these neighbourhoods. Shearer's inequality therefore gives . Conditional on , a vertex of is forced absent if any neighbor was selected, and otherwise is a free fair binary choice. There are no edges within , and the conditional independent-set distribution is uniform on all these free choices. Henceand
There are possible neighborhood patterns. Give the zero pattern weight and every other pattern weight one. For its distribution , concavity of the logarithm, or Jensen's inequality, givesThis establishes the local weighted-entropy estimate rather than just counting neighborhood patterns.
Edge counting gives ; together with , it yields . Exponentiating the Shannon entropy estimate proves the independent-set bound for biregular graphs:The complete bipartite graph has exactly independent sets, since one chooses a subset of one side and subtracts the double-counted empty set. Disjoint unions of such components attain equality. If exactly one degree parameter is zero, edge counting forces the graph to be edgeless and the displayed bound equals , so it remains valid. If , the denominator is undefined; the edgeless graph has exactly independent sets.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 33 2 Solution Created 2026-10-03 Updated 2026-10-14
For discrete random variables, write for the joint probability mass function and for its marginal. The conditional entropy is the average of the entropies of the conditional distributions:Conditional distributions at zero-probability values of can be chosen arbitrarily; they contribute nothing. Here denotes Shannon entropy, with one common logarithm base and .
For , use and sum with weight . Summing out in the first term givesFor countable alphabets, the entropy contributions are nonnegative, so the equality remains valid with extended values by summing nonnegative terms. Applying this identity successively to the prefix and proves the chain rule for information entropy:For , the conditioning tuple is empty and the term is .
For the subset inequalities, first suppose the marginal entropies are finite, so all joint entropies below are finite by the chain rule and the assumed conditioning reduces entropy property. Put , and let be the joint entropy with coordinate omitted. Apply the two-variable chain rule in the order to getThe inequality holds because the prefix conditioning set is contained in the set of all other coordinates. Summing over and using the chain rule givesThis proves Han's entropy inequality. In terms of the normalized subset entropy, and , hence for .
Apply the same result to each -element coordinate set . It givesWhen this is summed over all -subsets, each fixed -subset occurs once for each possible added coordinate, namely times. ThereforeSubstitute and the analogous identity at . The binomial coefficient identity cancels the common positive factor and givesThis is the monotonicity of normalized subset entropies, obtained from the local -coordinate inequality by explicit counting.
If some marginal entropy is infinite, each subset average contains at least one subset including that coordinate. The entropy of such a subset is at least that marginal entropy, by the nonnegative conditional-entropy chain rule, so every is infinite. The inequalities then hold in the extended sense. Otherwise the finite-entropy proof applies. For independent random variables the averages are all ; repeated copies of one variable instead give , illustrating the entropy reduction caused by redundancy.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 15 3 i Solution Created 2026-10-03 Updated 2026-10-14
The Balister-Bollobas inequality says that if is the coordinate multiplicity in a multiset , and , then . More generally, each union-intersection compression decreases the entropy sum, by entropy submodularity.
For an exact -cover define and . Compressing the family of gives the nested family of all together with full sets. Rearranging the resulting bound gives the upper Madiman-Tetali inequality. Conversely, compressing the family of all together with full sets gives the nested family of , yielding the lower bound. In conditional-entropy notation these areThe coordinate multiplicities agree in each compression, because is an exact -cover. An equivalent proof expands the chain rule for information entropy contributions and uses conditioning reduces entropy. It also gives the upper inequality for arbitrary fractional covers and the lower inequality for fractional packings.
Past exam of the mathematics course of the University of Cambridge 2010 iii Paper 12 4 i Solution Created 2026-10-03 Updated 2026-10-14
Let be the number of independent sets of the biregular graph . Choose one such set uniformly and write . All information entropies below use logarithms to base two, soWe will prove .
We state and justify the entropy facts used. For a finite-valued random variable , with . Its conditional entropy is the mean of this quantity over the conditioning variable. Factoring the joint probabilities proves the chain rule for information entropy, . Conditioning reduces entropy: . To see this, condition on and use concavity of to compare the mixture of the conditional distributions given with their mean entropy.
The precise Shearer inequality needed here is: if subsets of the indices of a finite random vector cover every index at least times, then . To prove it, order the indices. The chain rule for information entropy expandsThe inequality is conditioning reduces entropy. Summing over counts each nonnegative conditional term at least times and proves the assertion.
For every , its vertex neighbourhood has vertices. Every lies in exactly of these neighbourhoods. Hence Shearer inequality givesLet , the probability that no neighbour of is selected. Conditional on a particular selected subset of , a vertex with a selected neighbour is forbidden, and all other vertices of are available. Because there are no edges within , every subset of the available vertices is a valid completion. Uniform choice of makes these completions equally likely. The available coordinates are therefore independent fair binary choices, each of entropy one, and the forbidden coordinates are zero. Averaging their number givesBy the chain rule for information entropy,It remains to bound each bracket. Let , a binary vector of length , with distribution on , and put . Assign weight to the all-zero vector and weight to every nonzero vector. ThenThe first inequality is Jensen's inequality for the concave logarithm; the weights sum to . This explicitly handles zero probabilities and does not assume the neighbourhood indicators are independent.
There are right vertices, so combining the bounds and using givesExponentiating proves the required independent-set bound for biregular graphs. The proof uses both degree constraints: supplies the neighbourhood-cover multiplicity and the conditional-completion weight, while determines the number of neighbourhood patterns.