Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Normal linear model
Adjusted coefficient of determination 2026-10-14
In a normal linear model with an intercept, observations and independent mean coefficients, adjusted isIt compares the residual variance estimate with the unmodelled sample variance, adjusting the raw coefficient of determination for fitted dimension. It can be negative and is not guaranteed to increase when another regressor is added. In penalized regression a related convention uses the fit's effective degrees of freedom instead of ; the precise smoothing-software variance convention should be specified.
Analysis of covariance 2026-10-14
Analysis of covariance combines a categorical treatment and a quantitative covariate in a normal linear model. A common-slope model is , with independent errors. Treatment differences compare fitted means at the same covariate value. Adding treatment-by-covariate interactions permits separate slopes, and a partial F-test compares this extension with the parallel-lines model. The treatment test after adding the covariate differs from an unadjusted comparison, because treatment groups can have different covariate distributions.
Analysis of variance Created 2026-09-29 Updated 2026-10-05
Analysis of variance decomposes variation into contributions associated with model terms and residual error. For nested normal linear models, differences of residual sums of squares give sequential or partial F-tests.
Balanced factorial orthogonality 2026-10-07
In a complete two-factor design with equal cell replication, centred factor indicator columns for different factors have zero cross-products. Consequently the two main effects in an additive normal linear model are orthogonal, and their extra sums of squares do not depend on the order in which these main effects are entered. An omitted interaction term can still require a separate adequacy check.
Coefficient of determination Created 2026-10-06 Updated 2026-10-14
In an ordinary least squares regression with an intercept and a nonconstant response, . It measures the fitted proportion of sample variation relative to an intercept-only baseline. It increases when regressors are added, even if those regressors are unhelpful for prediction. A high value does not establish the assumptions of a normal linear model or rule out a systematic regression residual pattern.
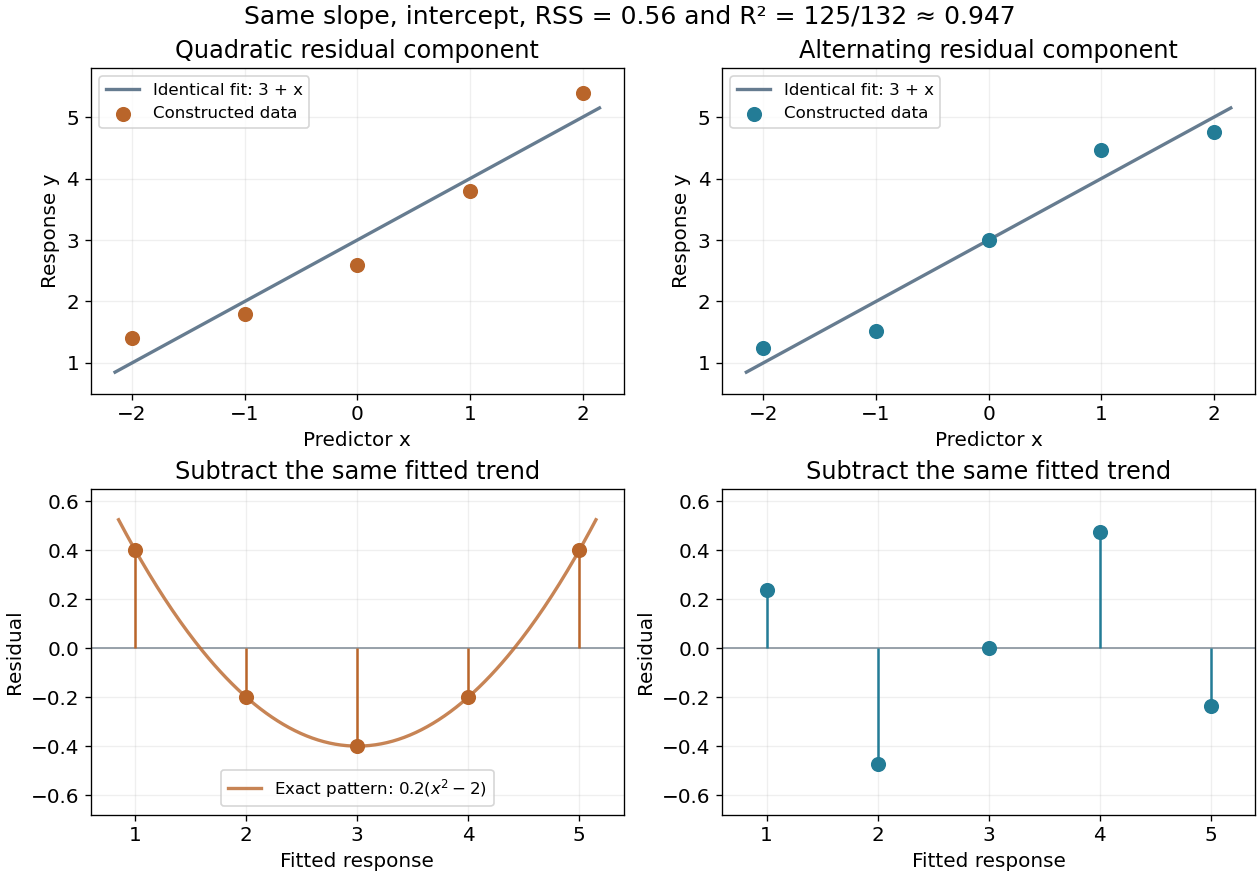
For the five-point example in linear regression, the total centered sum of squares is and the residual sum of squares is , so . This summarizes the fitted reduction in squared error. It does not record the order or shape of the regression residuals, which are worth examining in a residual-versus-fitted plot.
Here is a fully constructed illustration. Use and the same fitted line for both datasets. Add respectively the residual vectorsBoth sum to zero, both have zero inner product with , and both have squared norm . Their ordinary least squares fit is therefore exactly the same line, with the same . But the first residual is , a systematic quadratic shape, while the second changes direction across the predictor values. These examples show directly which information the scalar discards; neither constructed pattern proves a random-error model.

Corner-point constraint Created 2026-10-07 Updated 2026-11-05
In a normal linear model with an intercept and factor effects, set the effect of one factor level to zero. The intercept then denotes that reference level's mean, and the remaining effects are contrasts to it. The constraint removes redundant statistical parameters without altering the fitted mean space.
Deviance goodness-of-fit test Created 2026-10-06 Updated 2026-11-05
A deviance goodness-of-fit test compares a fitted generalized linear model with its saturated statistical model. With independent response groups, an identifiable rank- mean model and known common dispersion parameter , the candidate statistic is the scaled devianceIn an appropriate large-information regime, compare it with a chi-squared distribution on statistical degrees of freedom. For a normal linear model this is exact when is known: is the residual sum of squares. For Poisson regression, ; adequate expected cell counts are still needed for a useful approximation.[ref]
More individual Bernoulli observations do not automatically justify comparing their residual deviance with . Small cell counts, dependence and overdispersion can invalidate that calibration. An unknown dispersion parameter also needs an explicit estimation and testing convention; estimating it from and then treating as an independent goodness-of-fit check is circular.
In a normal linear model with residual degrees of freedom , an internally studentized residual satisfies and , provided its leverage is less than one. Choose an orthonormal basis of the residual space with its first direction proportional to the projection of the th coordinate vector. The Gaussian coordinates in this basis are independent standard normal random variables , and . The beta distribution follows from the independent chi-squared distributions of and . The bounded residual is not exactly distributed according to Student's t-distribution; it approaches the standard normal distribution as .
Distribution of the Akaike information criterion in a normal linear model Created 2026-09-29 Updated 2026-11-05
Consider the correctly specified fixed-design normal linear model , with an full-column-rank design matrix, , and with . Both and are unknown, so the Akaike information criterion counts fitted parameters. If is the residual sum of squares, thenThe orthogonal-projection decomposition of a random variable with a multivariate normal distribution gives . Substituting into yieldsHere denotes a random variable, not a quantile. The maximum-likelihood estimator of the error variance uses divisor ; the unbiased residual variance estimator with divisor cannot be substituted into the maximized likelihood. If and is invertible, the fit has zero residual sum of squares, and the Gaussian likelihood is unbounded as decreases to zero. There is then no finite positive-variance maximum-likelihood estimator to which the displayed Akaike information criterion law applies.
Equal-cell replication variance formula 2026-10-14
Suppose a normal linear model gives an unrestricted mean to each cell and has independent observations per cell, with common error variance . Each fitted cell mean is its sample mean, with variance ; different fitted cell means are independent. Estimate by the pooled within-cell residual sum of squares divided by , where is the number of cells. Thus a cell mean has standard error , a difference of two cell means has standard error , and a two-by-two difference-of-differences has standard error .
// Target: probability-and-statistics.bigb
Extra sum of squares Created 2026-10-06 Updated 2026-11-05
For nested normal linear models, the decrease in residual sum of squares obtained by adding coefficients is their Extra sum of squares. Dividing by the number of added coefficients and by the full-model residual mean square gives the partial F-test. A sequential analysis of variance attributes this decrease according to the specified order of entry; it need not equal the partial comparison when other terms are retained.
Factor-level pooling test 2026-10-06
To pool factor levels in a normal linear model, impose equality of their fitted means while retaining any needed interaction terms. Compare the resulting nested model with the full model using a nested-model F-test. For two cells each of size , pooling their fitted means adds to the residual sum of squares. If pooling two pairs separately within two other-factor levels, there are four restrictions.
Fitted-residual orthogonality 2026-10-06
For a full-rank ordinary least squares design matrix, the hat matrix and residual projection satisfy . Hence fitted values and regression residuals are perpendicular as observed vectors. Under isotropic errors their cross-covariance matrix is zero, and under a normal linear model the two vectors are independent.
Gaussian identity design for debiased Lasso 2026-10-05
In the normal linear model, assume is independent of . Independent rows of with multivariate normal distribution give a simple random design for Debiased Lasso. Let , and , with fixed positive noise scale. Choose the Lasso penalty and all Nodewise Lasso penalties as sufficiently large constant multiples of , including the noise scale in the former. Uniform sample cross-correlations are bounded by this scale, so zero is the nodewise solution with probability tending to one. Column squared norms divided by converge uniformly to one. To check the Compatibility condition for the Lasso directly, put and . On the Lasso cone condition, , and the Cauchy-Schwarz inequality givesFor , entrywise concentration of a Gaussian Gram matrix gives with probability tending to one for sufficiently large fixed . The stated sparsity condition implies on this event, so one can take eventually. The conditional Gaussian tail bound for the noise score and the Basic inequality for the Lasso then give with probability tending to one. Consequently the debiased-Lasso remainder bound is at most with probability tending to one, for a fixed constant . These assumptions allow both and to grow, for example , .
Gaussian independence of linear and quadratic statistics Created 2026-10-14 Updated 2026-11-05
When has full column rank, its Gram matrix is positive-definite and . The stacked normal vector therefore has zero cross covariance, so its blocks are independent. Since , the linear and quadratic statistics are independent. This is the projection argument behind independence of regression coefficient and variance estimators in a normal linear model.
Lack-of-fit F-test 2026-10-14
For independent normal responses of common variance at distinct predictor settings, a rank- normal linear model has residual degrees . The saturated setting-mean model has parameters and pure error degrees . Splitting orthogonal residual spaces gives lack of fit degrees . Under the fitted mean model, the two squared lengths divided by the common variance are independent chi-squared variables; their ratio of mean squares has the F-distribution shown. This test is unavailable without repeated settings or positive lack-of-fit degrees.
Linear regression Created 2026-09-24 Updated 2026-10-14
Linear regression models a response's conditional expectation as a linear combination of specified predictors. In matrix form,where the design matrix describes the observations, contains the regression coefficients, and contains the errors. The fitted values estimate the response means. The model is linear in its regression coefficients; its columns may include powers, interactions, or other transformed predictors, so polynomial regression can fit curved relationships using the same machinery.
For a concrete example, take five constructed observationsAn ordinary least squares fit with an intercept gives the line . Its regression residuals are and its residual sum of squares is . A one-unit increase in the predictor corresponds to a one-unit increase in the fitted response. This is a description of this fitted association; interpreting a change as a causal effect requires the assumptions of a causal inference problem.
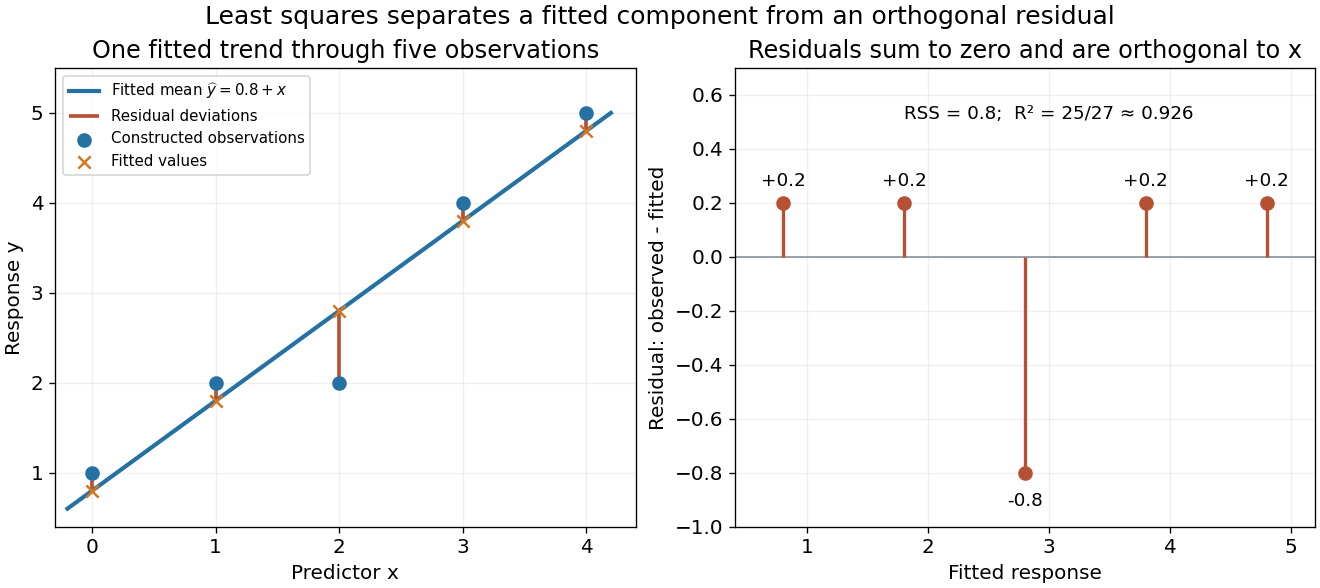
A five-point least-squares fit separates the fitted trend from residual deviations
. Details. 
The geometric reason for the fit is simple. The possible mean vectors form the column space of . Ordinary least squares chooses the orthogonal projection of the data vector onto that vector subspace, so the remaining regression residual is orthogonal to every permitted fitted direction. The least-squares normal equations express this orthogonality as . The data's explained component and unexplained component are therefore separated by the same geometry used in a Hilbert space.
The optimization definition makes sense for any observed data. Quantifying the uncertainty of the regression coefficients needs additional assumptions about the sampling and errors. With fixed of full column rank and mean-zero errors with covariance matrix , ordinary least squares is unbiased and has covariance ; the Gauss-Markov theorem compares it with other linear unbiased estimators. A normal linear model additionally makes Student t-distribution intervals and tests exact in finite samples. Model adequacy and predictive assessment remain relevant even when these calculations are available.
Two historical settings help explain the subject's appeal. Adrien-Marie Legendre's Nouvelles méthodes pour la détermination des orbites des comètes (1805) includes an appendix on the method of least squares: observations give more equations than unknowns, and squared errors provide a criterion for reconciling them. Its astronomical setting shows the motivation for combining imperfect measurements. [ref]
https://www.e-rara.ch/zut/content/titleinfo/10838079. Legendre, Nouvelles méthodes pour la détermination des orbites des comètes, 1805, appendix pp. 72–80
Francis Galton's Regression Towards Mediocrity in Hereditary Stature (1886) examines the association between parental and offspring heights and the tendency of group averages toward the population average. This is a historical use of the regression name; the modern linear model is a general statistical formulation. [ref]https://zenodo.org/records/1449548. Galton, Regression Towards Mediocrity in Hereditary Stature, 1886, original article
Nested-model F-test Created 2026-09-24 Updated 2026-11-05
For nested Gaussian linear models with a common unknown positive error variance, full-model rank , and rank difference , the statistichas an distribution under the reduced model.
If a design matrix has a nonzero null vector , the normal linear model has identical observation distributions at and . Any estimator has the same expectation at those two parameters, and therefore cannot be an unbiased estimator of both coefficient vectors. Full column rank is required for unbiased estimation of the entire unconstrained coefficient vector; identifiable linear combinations can still be estimated without it.
Normal-inverse-gamma prior Created 2026-10-05 Updated 2026-10-06
For a normal linear model with coefficient vector and residual variance , a normal-inverse-gamma prior has and , with a positive-definite matrix and . The inverse-gamma density is proportional to . Multiplying by the normal linear model likelihood function and completing the square preserves the family, giving an analytic posterior and evidence integral.