
For every finite collection of first-order formulas, there are arbitrarily large ordinals such that, for every and all parameters in ,The reflecting ordinals for form a closed unbounded class.
The quantum conditional entropy is . Unlike its classical counterpart, it may be negative.
For a bipartite pure state, the entanglement entropy is the Von Neumann entropy of either reduced density matrix. The two reduced states have the same nonzero eigenvalues, so their entropies agree.
For every positive integer , the divisor sum of its Von Mangoldt function weights recovers its natural logarithm:The sum runs over the positive integer divisors of . For , its only term is . Equivalently, if and is the constant-one arithmetic function, then , where is Dirichlet convolution. [ref]
For , the positive integer divisors are . Only contribute:Thus the vanishing of loses no information here: the divisor sum retrieves both copies of the prime factor from the integer divisors and .
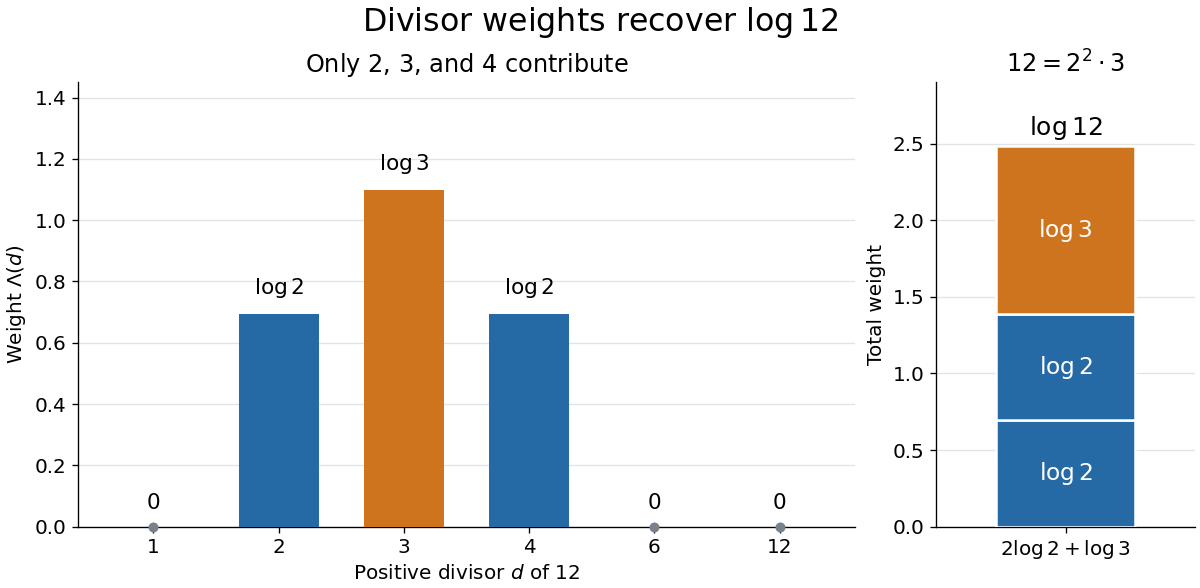
Proof outline: by the fundamental theorem of arithmetic, write with distinct prime numbers and positive exponents . Among the positive integer divisors, the ones with nonzero Von Mangoldt function weights are exactly . ConsequentlyThe natural logarithm turns the prime factorization product into a sum, and the prime powers greater than one supply exactly the required multiplicities.
For a circular cylinder translating parallel to a nearby wall at zero Reynolds number, leading lubrication shear and pressure recovery make the zero-torque condition force zero angular velocity.
The uniaxial extensional viscosity is the tensile normal-stress difference divided by the imposed extension rate.
The Oldroyd-B model combines a Newtonian solvent with infinitely extensible Hookean polymer dumbbells. It predicts constant shear viscosity, a positive first normal-stress difference, and an extensional catastrophe at a finite extension rate.
The conformation tensor describes the average stretch and orientation of polymer molecules. Its equilibrium value is the identity tensor under a common normalization.
A path has constant speed when the magnitude of its velocity does not vary with time. Its acceleration may still be nonzero: uniform circular motion has turning velocity and inward centripetal acceleration. Constant velocity is stronger, requiring unchanged direction as well as unchanged speed.
Acceleration is the time derivative of velocity, equivalently the second derivative of position:It is a vector with SI unit . A change in direction produces acceleration even if speed stays constant. For example, a car rounding a bend at steady speed needs an inward resultant force by Newton's second law. Thus acceleration does not mean only speeding up. When , the dot product gives : a perpendicular acceleration changes direction without changing speed at that instant.
Take counterclockwise circular motion about the origin with radius and constant angular speed . The position, velocity and acceleration areThe speed is throughout, while the inward centripetal acceleration has magnitude . At the four cardinal points, reached at , the velocities in are ; the accelerations in are . The vectors turn together, remaining perpendicular. [ref]
https://openstax.org/books/university-physics-volume-1/pages/4-4-uniform-and-nonuniform-circular-motion. Ling, Sanny and Moebs, section 4.4: uniform circular motion
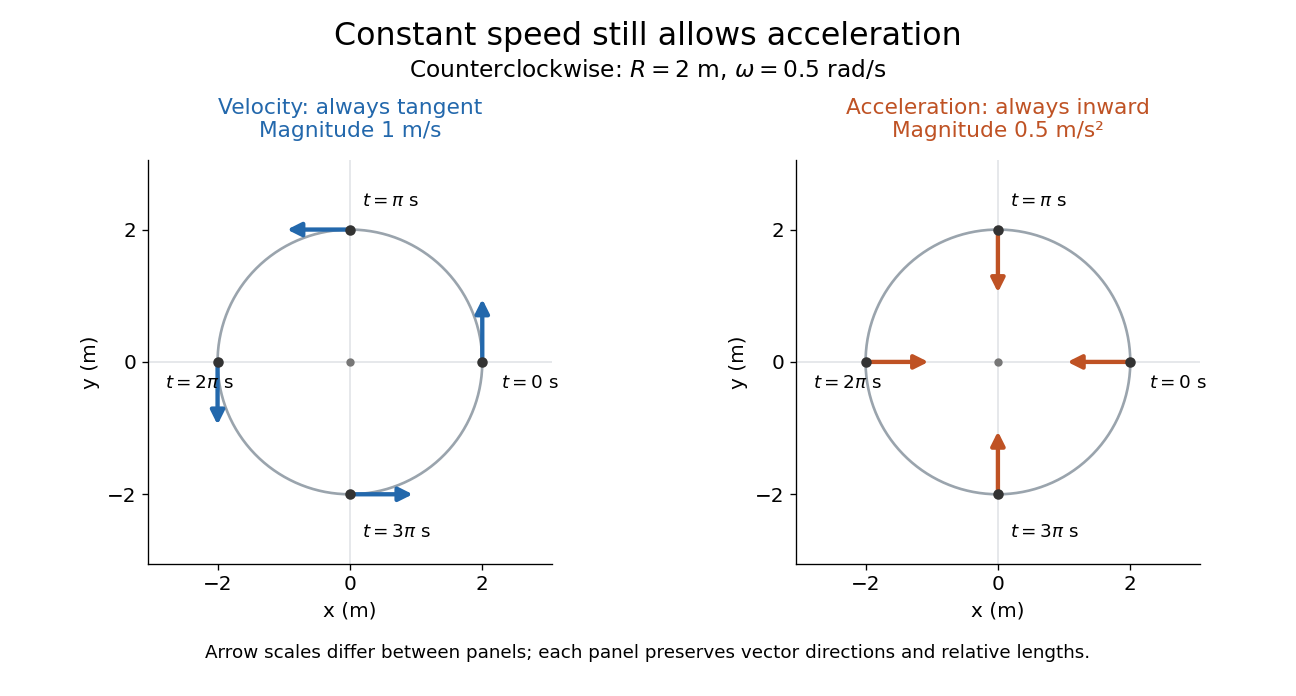


The proof outline is just two applications of the chain rule to ; then fixes both magnitudes. The usefulness is geometric: turning requires a force even when a speed reading remains steady, and doubling speed at fixed radius quadruples the required centripetal acceleration. The same mechanism appears in a circular orbit.
Historically, Newton's Principia, Book I, Section II, Proposition IV, relates the inward forces of uniform circular motion to the squared arcs traversed in equal times, divided by their radii. In modern notation, its dependence on speed and radius is ; Newton presents a geometric argument rather than the coordinate derivatives above. [ref]
https://en.wikisource.org/wiki/The_Mathematical_Principles_of_Natural_Philosophy_(1729)/Book_1/Section_2. Newton, Principia, Book I, Proposition IV; Motte's 1729 translation
Speed is the nonnegative magnitude of velocity, a scalar rather than a vector. In orthonormal Cartesian coordinates,Its SI unit is . In the reversal example under velocity, the endpoint velocities and both have speed , but the speed falls to zero between them. A speed reading alone therefore cannot tell which way the body is moving.
For a smooth path, the total distance traveled is its arc length, . Unlike the integral of a signed velocity component, this integral cannot cancel outward and return motion. The reversal example travels in , giving an average speed of , while its average velocity is zero. This makes speed useful for estimating travel duration or fuel use, while velocity also tracks progress toward a destination. [ref]
https://openstax.org/books/university-physics-volume-1/pages/3-2-instantaneous-velocity-and-speed. Ling, Sanny and Moebs, section 3.2: distance traveled versus displacement
A vector is an element of a vector space. Its defining operations are vector addition and scalar multiplication. An arrow in a Euclidean space is one example; a polynomial or a function can also be a vector when the chosen vector space uses the corresponding addition and scalar multiplication.
For instance, the polynomials and belong to the real vector space of polynomials of degree at most two. Their vector addition gives , and scalar multiplication gives . In the monomial basis these are the coordinate vectors , , and respectively. The vectors are the polynomials; these tuples are their representations in a chosen basis.
A general vector space does not itself prescribe lengths or angles. A norm supplies a size, while an inner product also supplies angle information and orthogonality. The familiar arrow geometry below belongs to Euclidean vectors, where this extra structure is available.
A basis is a linearly independent spanning set of vectors in a vector space. Every vector is a unique finite linear combination of basis vectors. Independence supplies uniqueness, and spanning supplies existence. An ordered basis turns the coefficients into a coordinate vector.
For , the matrix with these vectors as columns isHence the coordinate vector of is , and recovers the usual coordinates. The determinant is nonzero, so this recovery works for every vector in . A basis need not have perpendicular or unit-length vectors; an orthonormal basis adds those geometric conveniences when an inner product is available.
The point of changing basis is to simplify the operation being studied. Diagonalization uses an eigenbasis to turn a coupled linear map into independent scalings. In a space of polynomials, the basis makes differentiation easy to encode, while orthogonal polynomials can make approximation errors easier to measure. Gilbert Strang's MIT lecture on independence, basis and dimension develops this connection between attainable columns, redundant columns and coordinates.[ref]
https://ocw.mit.edu/courses/18-06sc-linear-algebra-fall-2011/. Strang, MIT 18.06SC, Independence, Basis and Dimension
In a vector space over a specified field , a finite family of vectors is linearly independent when, for coefficients ,Here the left-hand zero is the zero vector, while the right-hand zeros belong to the field . Thus linear independence excludes every nontrivial linear relation. For an infinite family, require this condition for every finite subfamily.[ref]
https://ocw.mit.edu/courses/18-06sc-linear-algebra-fall-2011/0bbc30e3f1d7933ea07a2d2e9ab050d9_MIT18_06SCF11_Ses1.9sum.pdf. MIT 18.06SC, Strang lecture summary 9, p. 1: linear independence
For and over the real numbers, the linear relation gives and . Adding and subtracting yields , hence . This verifies linear independence directly and explains why the linear combination giving has exactly the coefficients .
A linearly independent family cannot contain the zero vector: a coefficient of on that entry and on every other entry would be a nontrivial linear relation. The empty family is linearly independent, because its empty sum is the zero vector and there are no coefficients that could be nonzero. Linear independence identifies a collection without redundant vectors; combined with a spanning set, it gives a basis. The uniqueness of linear combination coefficients makes its representations unambiguous.
There are unlisted articles, also show them or only show them.