
The Standard Model is a gauge theory with gauge group . Its Higgs field breaks the electroweak subgroup to the electromagnetic .
Spontaneous symmetry breaking occurs when the action and equations have a symmetry but a chosen ground state is invariant only under a proper subgroup. Acting with the broken symmetry generates a degenerate vacuum manifold.
This is an orthogonal projection interpretation of linear least squares. The best affine predictor has slope covariance divided by predictor variance and intercept chosen to match means.
Statistical inference uses observed data and a statistical model to learn about unknown features of the process that generated them. In a parametric statistical model, write : the probability distribution depends on an unknown statistical parameter . An estimand specifies the target, such as a mean or a difference of means. A statistic is a function of the observations; an estimator is a statistic used to estimate the target. Uppercase denotes the random data before observation, while lowercase denotes their realized values.
Three questions lead to different outputs. Statistical estimation asks which target value the observations suggest. A confidence interval asks for a range produced by a procedure with calibrated coverage probability. A hypothesis test asks whether the observations depart sufficiently from a specified null hypothesis to enter its rejection region. These outputs complement one another: an estimated effect size describes magnitude, while a standard error describes the sampling distribution of an estimator. A p-value describes a tail probability under the null hypothesis.
The appeal of statistical inference is that it turns variable observations into reproducible uncertainty statements. In the normal mean confidence interval with known variance below, a sample mean of has standard error : both the estimated shift and its precision matter. The calibration depends on the statistical model, including independence and the specified probability distribution. Increasing sample size improves precision under those assumptions; it does not repair a systematically misleading sampling procedure. Bayesian inference provides another framework, using a prior distribution and a likelihood function to obtain a posterior distribution.
A Monte Carlo method approximates a deterministic quantity using averages of simulated random variables and controls the approximation with probabilistic limit theorems.
A statistic is sufficient for a statistical model when the conditional distribution of the full data given has a version independent of the unknown statistical parameter . Once is recorded, the remaining uncertainty about the data's arrangement can be generated without knowing . [ref]
Sufficiency (Stat 210a, Fall 2025) by Will Fithian. Sufficiency, Will Fithian, “Sufficiency”: definition
For data and statistic taking values in standard Borel spaces, express this precisely with one Markov kernel , common to every statistical parameter value:for each measurable event . Thus is a regular conditional distribution of given . Equality is only required outside a null set for the distribution of under each ; the choice of version matters on impossible conditioning events. For a continuous probability distribution, the event may have zero probability even at meaningful observations, so the definition uses a regular conditional distribution, rather than division by .
A sufficient statistic is a property of a specified statistical model, rather than of a formula for summarizing data in isolation. It need not be an unbiased estimator or even shorten the record: the full data is always sufficient. An estimator instead targets a quantity such as a mean. An ancillary statistic has a parameter-independent marginal probability distribution, whereas a sufficient statistic has a parameter-independent conditional full-data law. A minimal sufficient statistic permits the greatest reduction among sufficient statistics. A complete statistic satisfies a separate condition about zero expectations; a complete sufficient statistic must satisfy both conditions.
A regression residual is the observed response minus its fitted value. Residual plots diagnose failures of assumptions such as constant variance, linear mean structure, and independent errors.
If is a sufficient statistic and is an estimator with finite variance, then has the same expectation and no greater variance. Indeed, the tower property of conditional expectation preserves the mean and the law of total variance gives
Multiple hypothesis testing applies tests to a family of null hypotheses while controlling an aggregate error criterion.
A Markov additive process couples a Markov chain to an additive functional whose increments depend on the chain.
For an irreducible positive recurrent Markov chain with stationary distribution , the expected return time to state is . More generally, expected occupation rewards in a return cycle equal their stationary rate times the expected cycle length.
A Galton-Watson process is a branching process that counts individuals by generation. Start with one ancestor, , and let all offspring counts be independent and identically distributed random variables taking nonnegative integer values with a common offspring distribution. ThenThe empty sum is zero: zero is an absorbing state, so once a generation is empty every later generation is empty. The same offspring distribution applies to every individual in every generation. [ref]
https://ocw.mit.edu/courses/18-445-introduction-to-stochastic-processes-spring-2015/27aaeb9eb9a9cecce93d9ad74413ddf5_MIT18_445S15_lecture19.pdf. Hao Wu, MIT 18.445, Lecture 19, slides 3–4
For a concrete offspring distribution, take , , , and for . An individual has no children with probability , one with probability , and two with probability . The offspring expected value is . A possible sequence of generation sizes is : two children need not lead to a permanently growing family.
The probability generating function gives the exact generation probability distributions through branching-process generating-function iteration. With and , the second generation hasThus and . The figure shows full generation probability mass functions, computed by polynomial function composition, through generation six; no simulated frequencies are used.
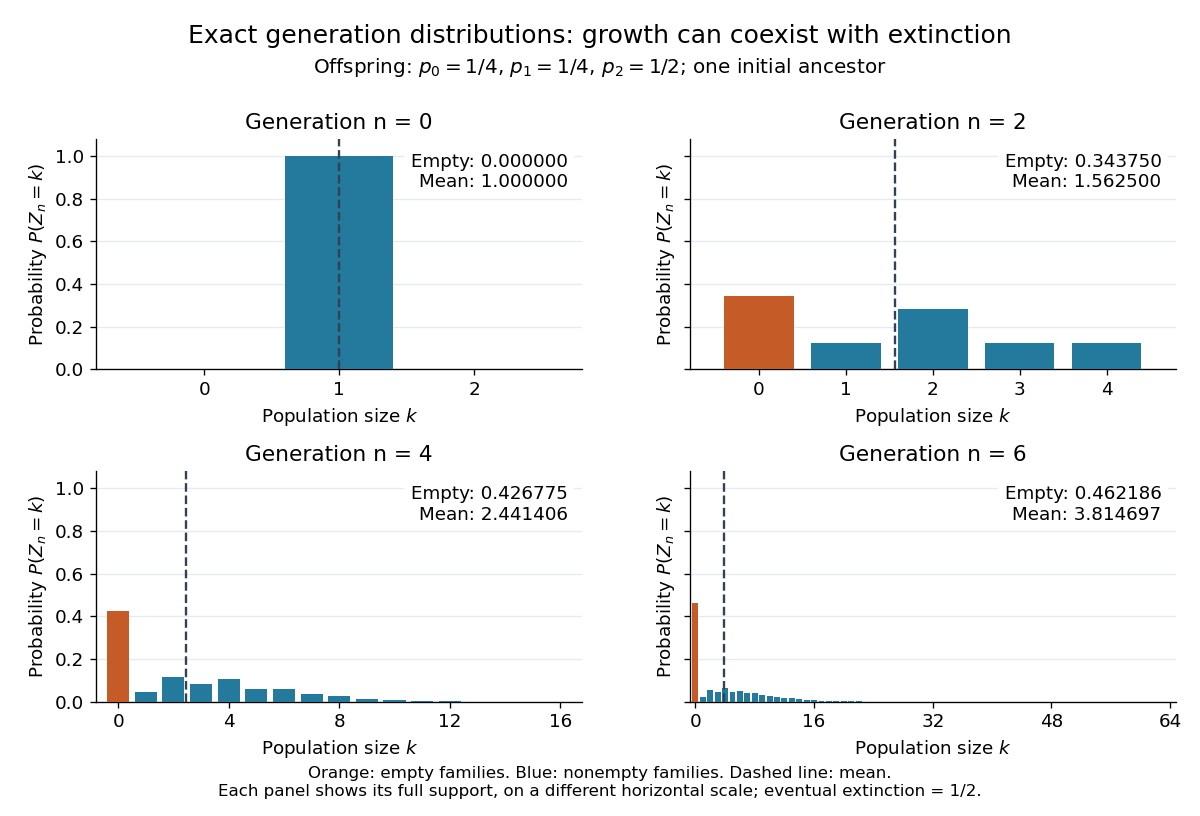

The contrast is striking: the expected generation size in a Galton-Watson process grows as , while the branching extinction probability is . By generation six, although . Larger surviving families carry the rising expected value; that mean is an average over possible families, not a forecast of one family's path. The Galton-Watson extinction fixed point turns an unbounded number of future generations into a single equation for this probability.
The historical question was the disappearance of surnames passed through male descendants. In Watson and Galton, On the Probability of the Extinction of Families, pages 139–140, Francis Galton formulates a constant-law model counting sons who reach adulthood, and Watson computes later generation probability distributions by composing generating functions. Those are assumptions of their model, rather than a claim that actual human reproduction follows this offspring distribution.
There are unlisted articles, also show them or only show them.