Raster graphics describe a picture by an array of pixels on a grid. For a rectangular image of width and height , write its stored values as , with and . A grayscale pixel can have one shade value; a colour pixel can have several component values. The grid specifies where values belong, while the encoding specifies what those values mean. A raster image therefore needs dimensions and an interpretation of its samples, not just a string of numbers.
The appealing feature is that pictures become explicit data: selecting a rectangle selects entries of an array; comparing two images compares their pixel values; image compression can exploit repeated or related values. Raster sampling and reconstruction explains why the stored grid and the displayed picture are different objects. A square drawn around a sample is one display convention, not a claim that the original scene consisted of little squares.
For example, a grayscale raster image stores 24 pixel values, even when displayed across a much larger rectangle. With one unsigned eight-bit sample per pixel, its uncompressed sample payload is bits; a file format can additionally require a file header, padding and other information, and image compression can change the stored size.
Enlarging that image can copy each pixel into a block through nearest-neighbor interpolation, or infer intermediate values through interpolation. Either procedure supplies a reconstruction rule; neither determines which unrecorded detail was present in the original. Vector graphics use a different representation, specifying geometric objects to be rendered onto a chosen grid. Re-rendering such a description and enlarging an existing raster image are different operations.
A pixel is one picture element at an indexed position in a raster image. It can contain a single grayscale value or several colour components. The word can also refer to a physical display element; the indexed element of the stored image is the meaning used here. One stored pixel need not occupy exactly one physical display element when the image is resized. Microsoft's bitmap documentation likewise distinguishes an image's grid and its numerical colour representation.[ref]
https://learn.microsoft.com/en-us/windows/win32/gdi/about-bitmaps. Microsoft Learn, About Bitmaps: pixel grids and bitmap representations
Separate position from value: raster sampling and reconstruction concerns the spatial grid, while sample depth concerns how many bits encode each component. Four times as many pixels can describe a finer grid without improving the quantization of any value. Conversely, more bits per sample can distinguish more shades without locating an edge more precisely.
In the binary example under run-length encoding, one bit per pixel selects black or white. In the grayscale example under lossy block averaging, eight bits per pixel select one of 256 codes. Calling them codes keeps their numerical values distinct from the physical light that a display emits.
The sample depth is the number of bits allocated to one stored sample. An unsigned -bit integer has codes, . This is per component, not automatically per pixel: three eight-bit components require 24 payload bits per pixel. A raster image with pixels and such components requires payload bits before data compression, padding or a file header.
For a toy normalized shade , define uniform quantization with endpoints included byThe floor function implements rounding to the nearest code, with exact halves rounded upward. The reconstruction step is , and . For , the levels are ; for they are . Increasing sample depth refines this value grid without changing the spatial grid. These levels are uniform in ; if is encoded sRGB, they are not uniform in relative luminance.
PNG uses a bit-depth field per sample or palette index. Its grayscale type without alpha permits 1, 2, 4, 8 or 16 bits per sample; its truecolour type permits 8 or 16 bits per component. These are format-specific restrictions, not a rule for every raster image.[ref]
https://www.w3.org/TR/png-3/#11IHDR. W3C, PNG Specification, Third Edition, section 11.2.1, IHDR, Table 12
A grayscale image varies along shades from black to white rather than recording independent colour differences. A numerical grayscale image assigns one shade sample to each pixel; an encoding determines how that sample maps to a displayed shade. A colour raster image can also look grayscale, for example when its three sRGB components are equal.
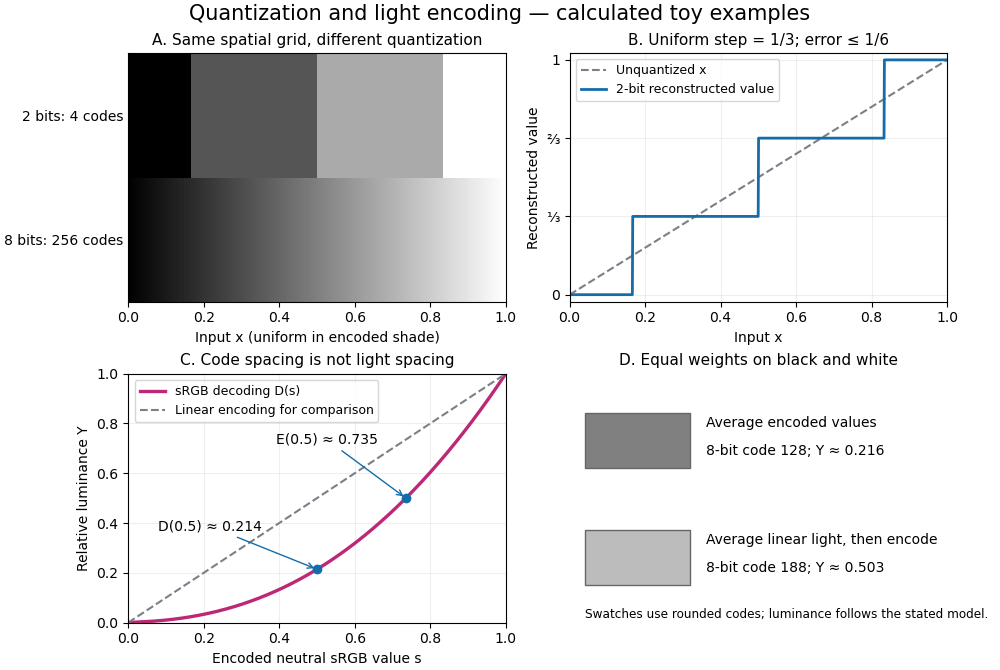
The convention in our lossy block averaging example is black at the integer code 0 and white at 255. Its arithmetic means act on those stored codes. This is a fully specified numerical experiment, but it does not claim that code 128 means half the physical light of code 255. PNG explicitly allows samples that are not proportional to light: its grayscale interpretation depends on the indicated transfer curve, and can be device-dependent when that information is absent.[ref]
https://www.w3.org/TR/png-3/#6Colour-values. W3C, PNG Specification, Third Edition, section 6.1: colour types, grayscale interpretation and transfer curves
Two different questions therefore need different operations. To average stored codes, average the integers. To average relative luminance for neutral sRGB shades, decode the codes to linear light, average there, and encode the result again. Equal weights on black and white give encoded value by the first method, but approximately by the second. Rounded to eight-bit codes these are 128 and 188. This example concerns ideal neutral shades and the specified sRGB conversion; it does not assert a universal grayscale conversion for every colour encoding.
The upper panels hold the spatial grid fixed and change sample depth: four levels produce broad constant bands, while 256 levels make smaller numerical steps. The lower panels hold the colour interpretation fixed and compare encoded sRGB values with relative luminance. All panels are calculated synthetic examples, not measured display data. Grayscale is useful when shade structure is the quantity of interest: a synthetic scalar image signal can be inspected without introducing separate colour components.
A point-sampling model assigns to a pixel on a grid, where is a continuous function representing an image signal. An area-sampling model instead assigns the average value of a function over a specified footprint. These are different models: a narrow feature between point samples can be missed, whereas its contribution to an area sample depends on its width and shade. Neither model says that the recorded value uniquely determines everything inside a grid cell.
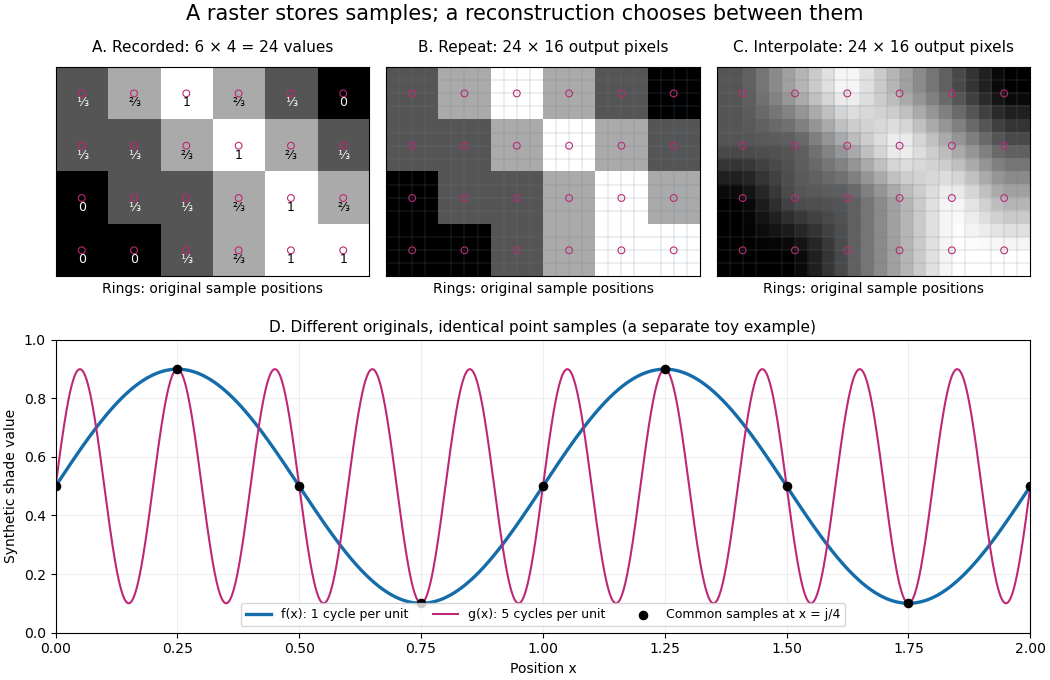
The upper panels start with exactly the same array. Nearest-neighbor interpolation repeats its values into a display; successive linear interpolations in the two coordinate directions produce a smoother display. Original sample positions are marked. Both displays use 384 output pixels, but only the same 24 recorded values. The extra values follow the chosen interpolation rule. Between-grid appearance is inferred, not independently recorded.
Spatial resolution needs a stated meaning. A grid over a rectangle of width and height has nominal cell pitches and . Over the same rectangle, doubling both dimensions halves these pitches and quadruples the pixel count. That is a finer grid, not a guarantee of more recoverable detail. Blurring before sampling, quantization and aliasing can make different originals share the same recorded array. Enlarging the rectangle without adding samples instead increases the displayed pitch.
A reproducible computational demonstration makes the ambiguity exact. Take the one-dimensional profiles and , repeated identically along every row. Sample at for . Since , the fact that the sine is a periodic function gives . Both yield , although at they give approximately and . The lower panel draws both originals and their common samples: no operation on those samples alone can identify the original profile. This is aliasing in an ideal point-sampling model, without image noise or rounding.
The Nyquist–Shannon sampling theorem describes reconstruction under a bandwidth restriction and ideal sampling assumptions; it does not grant uniqueness for arbitrary image signals from a finite raster image.[ref]
https://fab.cba.mit.edu/classes/S62.12/docs/Shannon_noise.pdf. Shannon, Communication in the Presence of Noise (1949), section II, Theorem 1 and reconstruction from the infinite sample sequence
The beautiful lesson is constructive: choose what detail the grid should preserve before sampling, and choose a reconstruction rule suited to the information actually retained.sRGB specifies a red-green-blue colour encoding. Restricting attention to component values in , its encoded component corresponds to the linear-light componentThus the conversion is piecewise, not a single power law. The reverse conversion used here isThese conventional rounded thresholds are used by the W3C conversion routines; they give a tiny mismatch at the join rather than a mathematically exact pair of inverses everywhere.[ref]
https://www.w3.org/TR/css-color-4/#predefined-sRGB. W3C, CSS Color Module Level 4, section 10.2: encoded and linear-light sRGB
[ref]https://www.w3.org/TR/css-color-4/#color-conversion-code. W3C, CSS Color Module Level 4, sample colour-conversion code: lin_sRGB and gam_sRGB
For an eight-bit neutral grayscale code , use in all three components. Its relative luminance is then . For example, , whereas . This is why averaging encoded values and averaging linear light give different answers. sRGB is a specified interpretation; merely calling a raster image grayscale does not imply it uses sRGB.
For the normalized sRGB calculations here, relative luminance is the linear-light weighted sumwhere are decoded linear-light components, not encoded code values. This is the sRGB calculation specified in W3C's WCAG 2.2 definition of relative luminance. It places reference black at 0 and reference white at 1; it does not by itself specify an absolute display light level.[ref]
https://www.w3.org/TR/WCAG22/#dfn-relative-luminance. W3C, WCAG 2.2, definition of relative luminance: sRGB decoding and weights
For a neutral sRGB shade, , and the weights sum to 1, so . For a coloured pixel, relative luminance can be encoded as a neutral sRGB shade with all three encoded components . This preserves the specified while discarding colour differences; it is one precisely defined grayscale conversion, not a unique way to turn all colour images into grayscale.
Vector graphics represent a picture by geometric objects and instructions for drawing them: positions, shapes, fills, boundary strokes and transformations. A circle can be stored as a centre and radius; a rectangle as a corner, width and height; a polygon as an ordered list of vertices. These geometric primitives describe whole objects rather than assigning a colour to every pixel. SVG provides elements for such basic shapes and for paths assembled from line segments and curves.[ref]
The useful separation is between the stored geometry and the finite output. A circle of radius 2 remains the same geometric description whether rendered across twenty or two thousand output pixels. This is the sense in which vector graphics are resolution independent: increasing the output grid can evaluate the original geometry again. The resulting raster image still has finite spatial resolution, and numerical coordinates have finite precision. Enlarging a previously rendered raster image through interpolation instead works with its existing samples. Neither operation guarantees that arbitrarily thin details remain visible at every size.
An SVG path uses a current point and drawing commands. For example,
M 1 4 L 5 4 L 3 1 Z moves to , draws two line segments, then closes back to the starting point, giving a triangle. Uppercase commands use absolute coordinates; the corresponding lowercase commands use offsets from the current point. Thus M 1 4 l 4 0 l -2 -3 z describes the same triangle. The coordinates belong to the current user Cartesian coordinate system, not necessarily to output pixels.[ref]For a curved example, the path
M 1 4 Q 3 0 5 4 Z uses one quadratic Bézier curve followed by a closing line segment. With control points , and , its curved boundary isThe endpoints are , and ; the interior control point is not a point on the curve. A fill paints the enclosed region, while a stroke paints a band around its boundary with a chosen width. One can use either or both: geometry and paint instructions are distinct.[ref]https://www.w3.org/TR/SVG2/paths.html#PathDataQuadraticBezierCommands. W3C SVG Working Group, SVG 2, section 9.3.7: quadratic Bézier path commands
[ref]https://www.w3.org/TR/SVG2/painting.html#Introduction. W3C SVG Working Group, SVG 2, section 13.1: filling interiors and stroking outlines
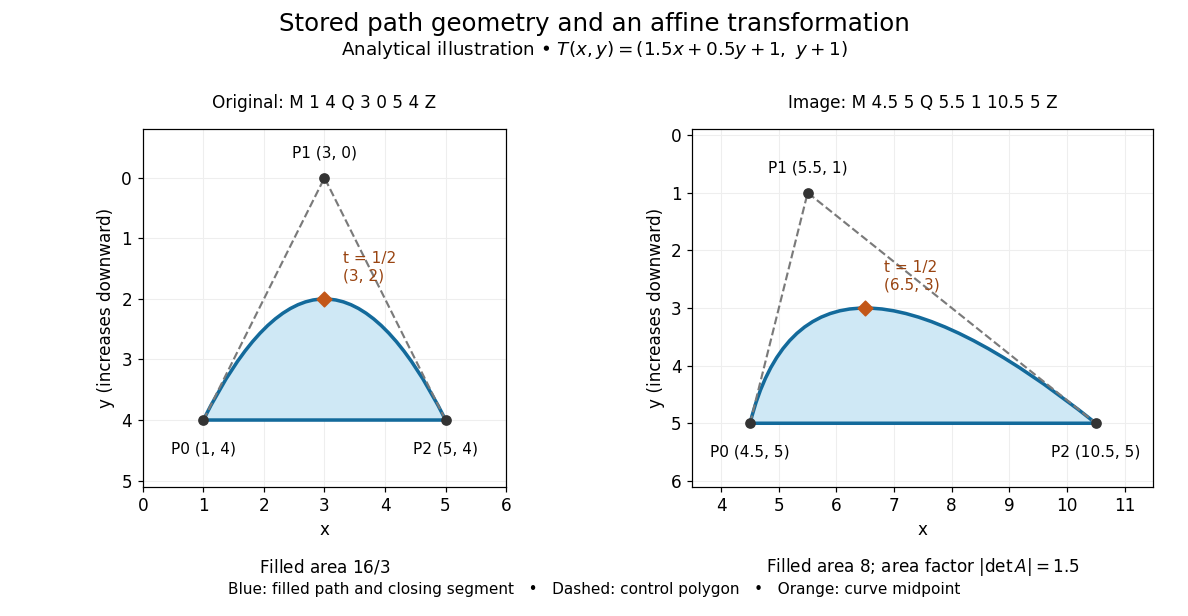
The first illustration uses increasing downward, following the initial SVG coordinate convention. Its dashed control polygon guides the eye; it is not part of the filled path. Apply the affine mapThis combines horizontal scaling, a shear mapping and a translation. The transformed control points are , and , giving the path
M 4.5 5 Q 5.5 1 10.5 5 Z. Its curved midpoint is . The affine equivariance of a geometric basis explains why transforming only the control points transforms the entire Bézier curve: its weights sum to one, so the translation is added exactly once. The enclosed area is before transformation and afterwards. These checks concern the filled region, excluding the width of any stroke.An SVG
viewBox specifies a rectangle in user coordinates to map into a display region. For example, viewBox="0 0 6 6" in a square viewport of 120 by 120 display units gives a scale of 20 display units per user unit; in a square viewport of 600 by 600 it gives 100. The path's control points need not change. For unequal proportions, preserveAspectRatio controls whether the mapping preserves proportions or stretches the axes separately. These display units need not correspond one for one to physical display pixels.[ref]https://www.w3.org/TR/SVG2/coords.html#InitialCoordinateSystem. W3C SVG Working Group, SVG 2, section 8.4: initial axes and user units
[ref]Rasterization converts the geometric drawing into a raster image on a chosen grid. Deciding whether each pixel centre lies inside a filled region is a simple rule, but a moving diagonal boundary can make entire pixels switch abruptly. Antialiasing reduces these sampling artifacts by accounting for a footprint around each sample, rather than treating every pixel as a single inside-or-outside decision. This connects vector graphics to raster sampling and reconstruction and aliasing; a finer grid and a better sampling rule solve different parts of the problem.
For an exact analytical model, fill the region . For a square pixel footprint , letHere is geometric coverage, and is relative luminance for ideal opaque neutral shades, with and . The intersection and area determine how much of the footprint is covered. This is a specified area-average model, not a claim that every SVG renderer uses exact coverage. The SVG
shape-rendering property supplies rendering hints and permits implementation tradeoffs, including disabling antialiasing for some choices.[ref]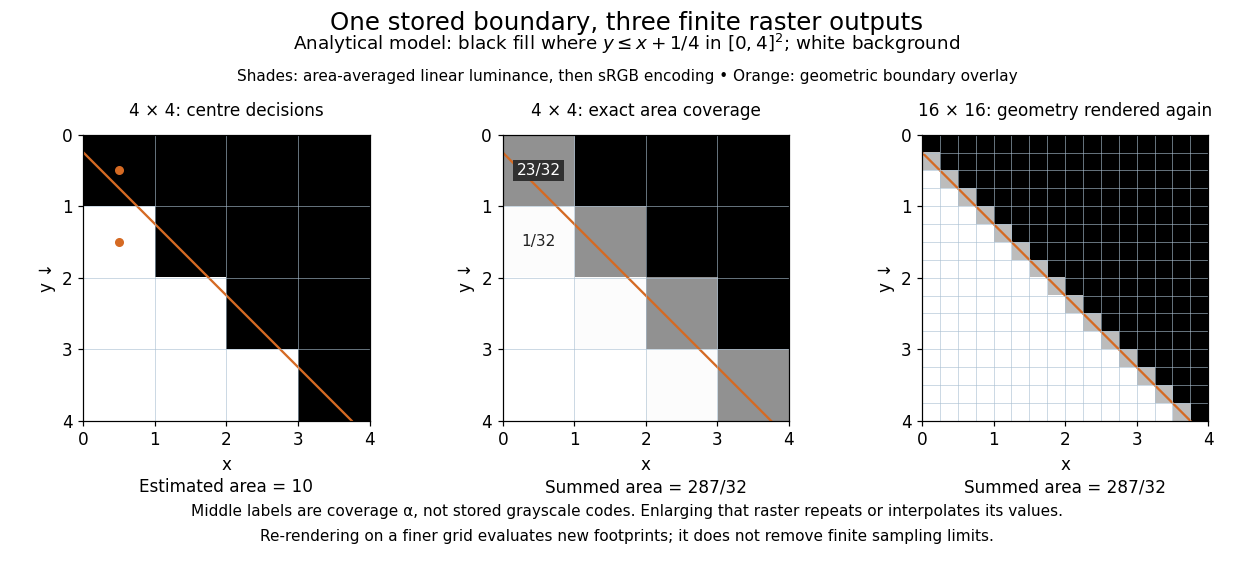
On the grid of unit squares, has coverage , whereas the pixel centre lies inside and gives coverage 1 under the centre rule. The adjacent square has coverage but its centre lies outside. The entire filled area is . Summing exact coverage times cell area gives this value on both the and grids; the coarse centre rule instead gives 10. Coverage values are displayed after sRGB encoding of the modeled relative luminance. The thin coloured line is a geometry overlay, not an extra sampled stroke. Enlarging the middle panel by nearest-neighbor interpolation would repeat its sixteen values; re-rendering the geometry produces the 256 independently evaluated footprints in the right panel. Antialiasing reduces abrupt edges but cannot make a finite grid preserve every geometric detail.
The attractive feature of vector graphics is editability at the level of intent: move one control point to bend a boundary, change a circle's radius, or transform a whole diagram while keeping its parts aligned. Logos, technical diagrams and outline fonts benefit because their structure can be expressed with relatively few shapes and curves. A complicated photograph may require enormous geometric detail, so vector graphics do not imply a smaller file than raster graphics. Nor does an SVG container guarantee that every object is vector geometry: its
image element can embed or reference a PNG raster image. Transforming that embedded raster image changes its placement and reconstruction, but does not recover missing original detail.[ref]https://www.w3.org/TR/SVG2/embedded.html#ImageElement. W3C SVG Working Group, SVG 2, section 12.3: image elements and embedded raster content
SVG, short for Scalable Vector Graphics, is a markup file format for two-dimensional graphics, specified by the W3C SVG Working Group. It describes vector graphics shapes, text and image objects, with grouping and transformations; it can therefore contain both geometric objects and raster images. The small command strings in vector graphics are path data within this format, not complete standalone documents.[ref]
https://www.w3.org/TR/SVG2/intro.html#AboutSVG. W3C SVG Working Group, SVG 2, section 1.1: scope, graphical objects and transformations



