Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

A projective hypersurface defined by a nonzero homogeneous quadratic form. Over , diagonalization identifies its rank; it is smooth when the rank is and otherwise is a cone with a linear vertex.
The scheme-theoretic intersection of a projective hypersurface with a projective plane. If the plane is not contained in the hypersurface, restricting the defining homogeneous polynomial gives a projective plane curve of the same degree, with possible repeated components.
The sample space is the set of outcomes represented by a probability model. One elementary outcome specifies a complete result at the level of detail the model keeps. An event is a subset belonging to the model's sigma-algebra ; it occurs when the actual outcome lies in that subset. Together with a probability measure , these form a probability space , with .[ref]
Introduction to Probability, Statistics, and Random Processes by Hossein Pishro-Nik. §1.3.1 Random Experiments: definitions of outcome, sample space, and event; three-toss example
Choosing a sample space means deciding which distinctions matter. For two tosses, recording the ordered head-or-tail sequence distinguishes from ; recording only the number of heads merges them. Neither representation is automatically wrong, but the second cannot answer a question about which toss was heads. Keeping a detailed sample space and defining a random variable for the desired observation lets several questions share one model.
A sample space alone assigns no probabilities. Even writing as a Cartesian product does not establish independence: that requires a condition on the probability measure. On a finite sample space with all subsets admitted as events,Only when all elementary probabilities are equal does this become , where the bars denote cardinality. This is the uniform distribution on a finite set, an additional modelling choice.
Sample spaces can also be infinite. For example, take , its Borel sigma-algebra, and the continuous uniform distribution. Then for , so each singleton has probability zero while . Thus an elementary outcome need not carry positive probability, and a continuous model cannot be understood by counting equally likely points. The distinction is developed in zero-probability event and countable additivity.
For finitely many probability spaces , their product probability space has underlying set , the product sigma-algebra and product measure . The coordinate projections are jointly independent: for measurable , the probability of all coordinate conditions is . Conversely a family of independent coordinates has this product joint distribution. Product structure permits coordinate exposure and independent resampling in concentration arguments.
Sampling without replacement selects distinct labelled units: after a unit is selected it is unavailable for the remaining draws. Distinct labels can carry equal numerical values, so repeated values do not necessarily imply a repeated unit. The rule alone does not specify selection probabilities; a procedure favoring particular units is still sampling without replacement but need not be simple random sampling.
In uniform sequential sampling without replacement, the next label is chosen uniformly among those remaining. For a population of labels, any ordered sequence of distinct labels has probability . Each size- subset has possible orders, so its probability is . This gives the fixed-size simple random sampling design. Equivalently, take the first labels of a uniformly random permutation. Restricting a uniformly random permutation to a specified label set preserves uniformity; biased modulo mappings should not replace uniform selection.
The draw positions have identical marginal probability distributions, but exhibit statistical dependence. If the first label is , the conditional probability that the second label is is zero, whereas its marginal probability is . Thus these draws are not independent and identically distributed when and . For a marked subset of labels, counting size- subsets with binomial coefficients gives the hypergeometric distribution. The resulting negative covariance explains the finite population correction for both counts and sample means.
Boole's inequality, also called the union bound, bounds the probability that at least one of several events occurs by adding their individual probabilities. For a finite or countable family of events in the same probability space,The union includes outcomes where several events occur together. There is no independence assumption: adding the individual probabilities counts such outcomes repeatedly, which can only make the sum larger. The cap at one uses the total mass of a probability measure. For infinitely many events, the sum is a nonnegative series, possibly infinite; an infinite sum gives only the bound one. This is countable subadditivity of a measure specialized to a probability measure. See Probability: Theory and Examples (fifth edition) by Rick Durrett (Section 1.1, Theorem 1.1.1(ii), printed p. 2).
For example, choose uniformly from the twelve outcomes , using the discrete uniform distribution. Put . If , these are disjoint events and their union has probability , exactly the union bound. If , the union has only six outcomes, so its exact probability is , although both individual probabilities are still and the bound is still . If , the exact probability falls to with the same bound. These examples isolate overlap in the union bound by keeping the individual probabilities fixed.
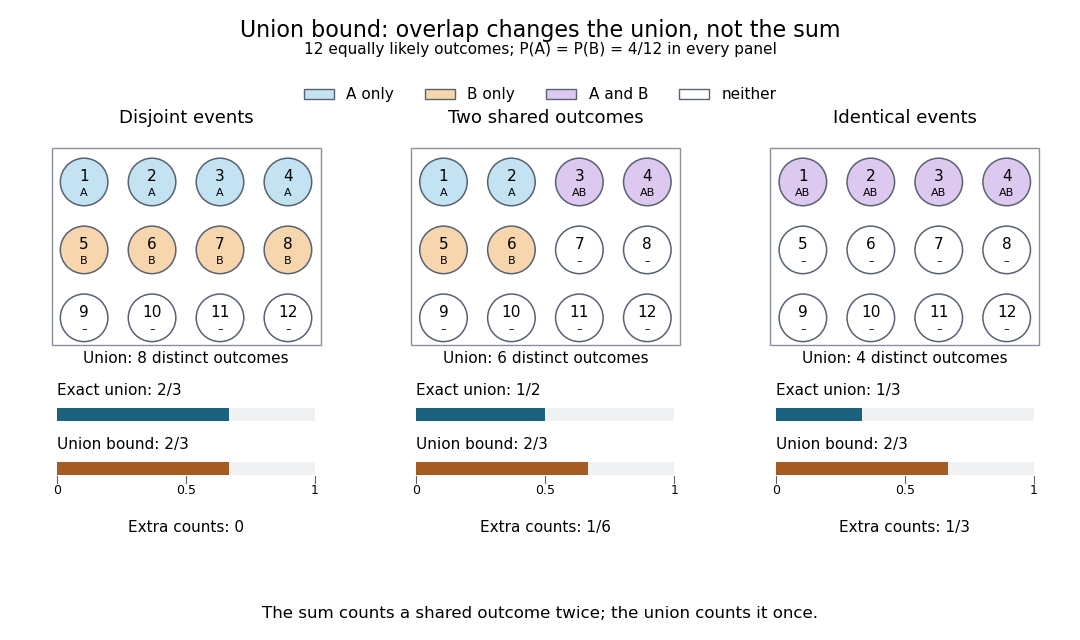
The same individual event probabilities give different exact union probabilities as overlap increases
. Each panel is a fully specified discrete uniform distribution on twelve numbered outcomes. Blue means only, orange means only, purple means their intersection, and white means neither. The bottom bars compare the exact union probability with the sum of the individual probabilities. The three unions contain eight, six, and four outcomes; the sum counts eight in every panel. Details.The union bound is useful when each event is easy to control but their joint behavior is difficult to determine. A short proof uses indicator functions: at every outcome,Taking expected values and using linearity of expectation proves the finite bound.[ref] For a countable family, the finite unions increase to the full union; continuity of probability passes the finite inequalities to the limit. The closure of a sigma-algebra under countable unions ensures that this limiting union is an event. For the continuity of probability step, see Probability: Theory and Examples (fifth edition) by Rick Durrett (Section 1.1, Theorem 1.1.1(iii), printed p. 2).
For a nonnegative random variable and threshold , Markov's inequality givesThe useful case has finite expected value; an infinite right side gives no finite information. The bound also holds if is nonnegative almost surely. Combining it with the elementary bound one gives . Nonnegativity is essential: negative values could otherwise cancel the contribution of large positive values to the expected value.
The idea is an average budget. Every outcome where contributes at least times its probability to , and the other outcomes contribute nonnegative amounts. Formally, the indicator function gives ; taking the expected value proves the bound. [ref]
https://ocw.mit.edu/courses/18-175-theory-of-probability-spring-2014/887e96172e82a615dac16fb26702d88b_MIT18_175S14_Lecture8.pdf. Sheffield, MIT 18.175, lecture 8: the expectation argument
.For example, let take , , , with respective probabilities , , , . Its expected value is . At , the tail probability is , while the bound is . At , the tail probability is , while the bound is . A different probability distribution with the same expected value, putting masses and at and , attains the bound exactly at .
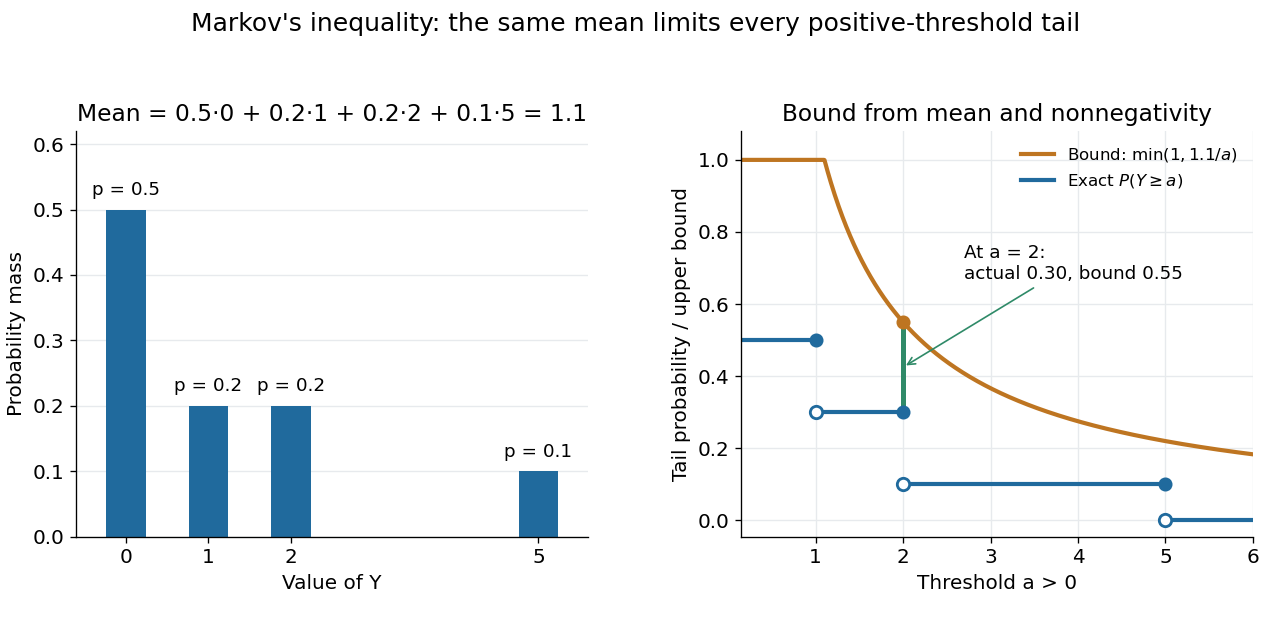
Markov's inequality is useful when a moment is easy to compute but a full probability distribution is difficult to determine. A nonnegative count with expected value less than one must have some positive probability of being zero, giving the first moment method. Applying the same bound to a squared centered random variable gives Chebyshev's inequality. Applying it to an exponential function of a random variable gives an exponential Markov bound, which can exploit more than a single moment.
For a real random variable with finite variance , expected value , and a threshold , Chebyshev's inequality givesOne can also cap this upper bound at one, since a probability cannot exceed one. If , taking gives . For example, at least of the probability lies strictly within two standard deviations of the mean. This statement needs only the finite variance assumption. If the variance is zero, almost surely and every positive deviation threshold has zero tail probability.
Consider a random variable uniformly distributed on . Its expected value is zero and its variance is . At the actual tail probability is , while Chebyshev's inequality gives . At the actual tail probability is zero, while the bound is . A valid bound need not describe the exact shape or bounded support of a particular probability distribution.
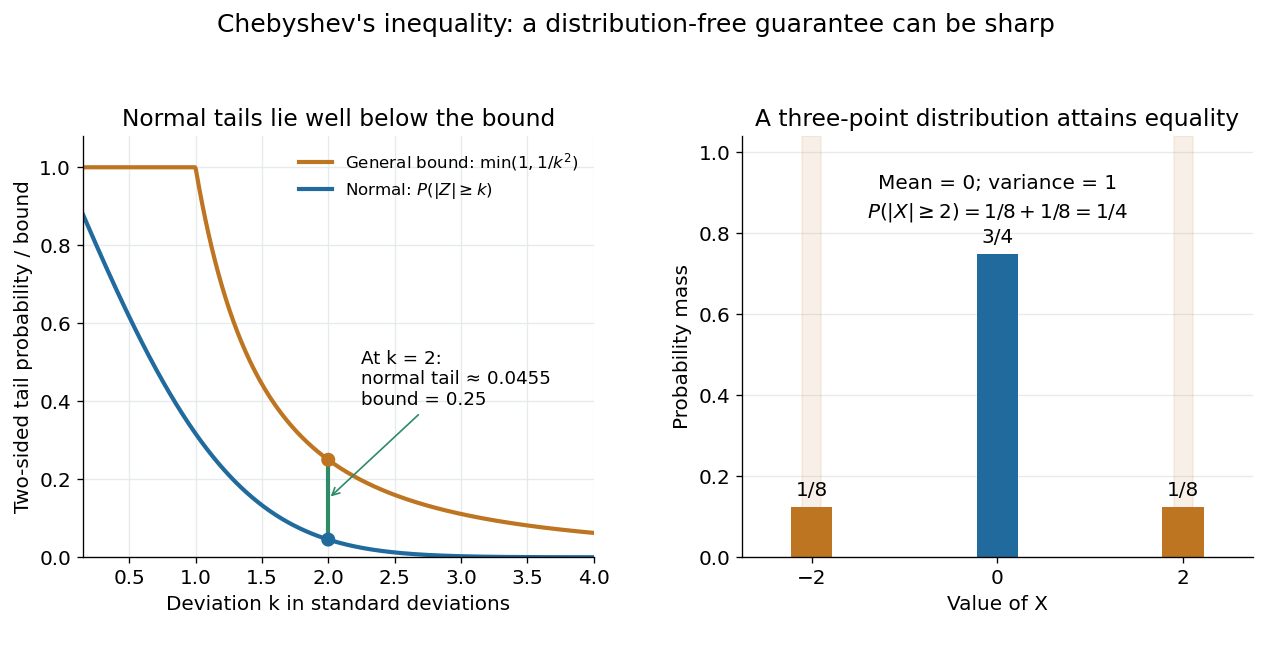
For the standard normal distribution, the actual tail probabilities beyond two and three standard deviations are approximately and , whereas the general bounds are and . More knowledge of the probability distribution can therefore improve the estimate. The comparison does not diminish the guarantee: the three-point example in equality in Chebyshev's inequality attains it exactly.
The proof is a one-line use of Markov's inequality on the nonnegative random variable . The event equals , and . This explains why the denominator is squared and why a finite variance supplies the necessary information. [ref]
https://ocw.mit.edu/courses/18-175-theory-of-probability-spring-2014/887e96172e82a615dac16fb26702d88b_MIT18_175S14_Lecture8.pdf. Scott Sheffield, MIT 18.175, lecture 8: Markov and Chebyshev bounds
.One important use is control of a sample mean. For independent and identically distributed random variables with finite variance , the variance of a sample mean is . HenceFor every fixed tolerance, the bound tends to zero as the sample size grows, proving the finite-variance case of the weak law of large numbers. For and , makes the bound . This is a sufficient bound under the stated assumptions, rather than an optimal required sample size.
An early historical source is Pafnuty Chebyshev's 1867 paper “Des valeurs moyennes”, published in French translation by N. de Khanikof. Its opening theorem bounds deviations of sums using their expected values and second moments, linking averages with control of exceptional outcomes. [ref]
https://www.numdam.org/item/JMPA_1867_2_12__177_0.pdf. Chebyshev, Journal de mathématiques pures et appliquées, 2nd series 12, 177–184 (1867)
.A probability law for a future observation conditional on currently available information. A posterior predictive distribution integrates the observation model over the posterior distribution of unknown parameters; a plug-in predictive law instead fixes an estimate of those parameters.
A probability distribution is infinitely divisible if, for every positive integer , it is the distribution of a sum of independent and identically distributed random variables. Their common distribution may depend on . A normal distribution has this property by dividing its mean and variance by ; a Poisson distribution has it by dividing its rate. The unit-time law of a Lévy process is infinitely divisible because it is the sum of its increments on equal time intervals.
In the right-tail convention, every positive exponential moment is infinite. This is a tail property, not the assertion that the variance or all power moments must be infinite. A heavy-tailed subexponential distribution has the additional property that a sum's far tail is dominated by one large summand.
The probability mass at an outcome is the probability of its singleton, . It equals the jump of the cumulative distribution function. For a discrete probability distribution these masses form the probability mass function; a continuous probability distribution gives every individual outcome mass zero. Positive probability mass at a point is distinct from the height of a probability density function.
A mixed probability distribution combines a discrete probability distribution with a continuous probability distribution. For example, put probability at zero and probability into a uniform distribution on . Its cumulative distribution function is for , for , and for . The jump at zero and the continuous increase both contribute; neither an ordinary probability density function alone nor a probability mass function alone describes the whole law.
For an event of probability , its odds in favor are . They compare the probability of the event with that of its complement. Conversely . For example, probability gives odds , or one to three in favor. The same transformation applies to a conditional probability; an odds ratio compares these transformed probabilities in two groups, while a risk ratio compares the probabilities themselves.
For an event in a sample space , the complementary event occurs exactly when does not occur. The complement rule of probability follows from the Kolmogorov axioms: and are disjoint, their union is , and their probabilities therefore add to .
This rule is useful when an event is easier to describe through its failure. For a nonnegative integer-valued random variable , turns an at-least-one calculation into a single value of the probability mass function. In sampling without replacement, the hypergeometric distribution gives the chance of missing all marked objects, so its complement gives the chance of finding at least one.
A junction tree connects the maximal cliques of a chordal graph into a tree satisfying the running intersection property. Its edges carry separators equal to the intersections of the endpoint cliques. Assigning original factors to containing cliques permits exact sum-product belief propagation without summing independently over the entire collection of variables.
For every positive density and positive integer , every sufficiently large subset of of size at least contains a nonconstant arithmetic progression of length .
The semi-random method constructs a combinatorial object in many small random rounds, discarding incompatible proposals and updating the remaining constraints after each round. Independent proposals give calculable expected changes; concentration and deterministic corrections preserve the statistics needed for subsequent rounds. Unlike a single random sample, this combines repeated randomness with a structured evolving state. The Rödl nibble is a matching in a hypergraph version of this method.
The iterated prisoner's dilemma is a repeated game with a prisoner's dilemma at each round. Earlier choices can change later best responses: a present gain from defection may be outweighed by lost future cooperation. A pure strategy now specifies an action after every possible observed history, including histories that its own prescribed play would never reach. The horizon, observations, initial actions, and payoff convention must be specified before assessing a Nash equilibrium or subgame perfect equilibrium.
For the following worked example, repeat the prisoner's dilemma above infinitely at rounds . Assume public perfect monitoring: after each round both players observe both actions exactly, without error. They share a discount factor and evaluate a path of stage payoffs using the normalized discounted payoffThe round-zero weight is one before normalization, including when . A larger discount factor gives future payoffs more weight; the geometric series makes a constant stage payoff have the same normalized value. These assumptions and normalization follow [ref]
https://ocw.mit.edu/courses/6-254-game-theory-with-engineering-applications-spring-2010/5a158a7558165d0e22b5b27fcfa01713_MIT6_254S10_lec15.pdf. Asu Ozdaglar, MIT 6.254, lecture 15, slides 6–15
. The numerical payoffs here are our example; the lecture uses a different table.Suppose both players use grim trigger: play initially and while every past action of both players was ; after any observed , play forever. With no unilateral deviation, each gets normalized payoff . A first unilateral deviation to earns now, then at most each round because the opponent switches permanently to always defect. The deviator attains that continuation payoff by choosing thereafter. At any history of mutual cooperation, the comparison is thereforeCooperation is a best response precisely whenEquivalently, without normalization the geometric series givesMultiplying both unnormalized payoffs by the same positive factor leaves the best response comparison unchanged.
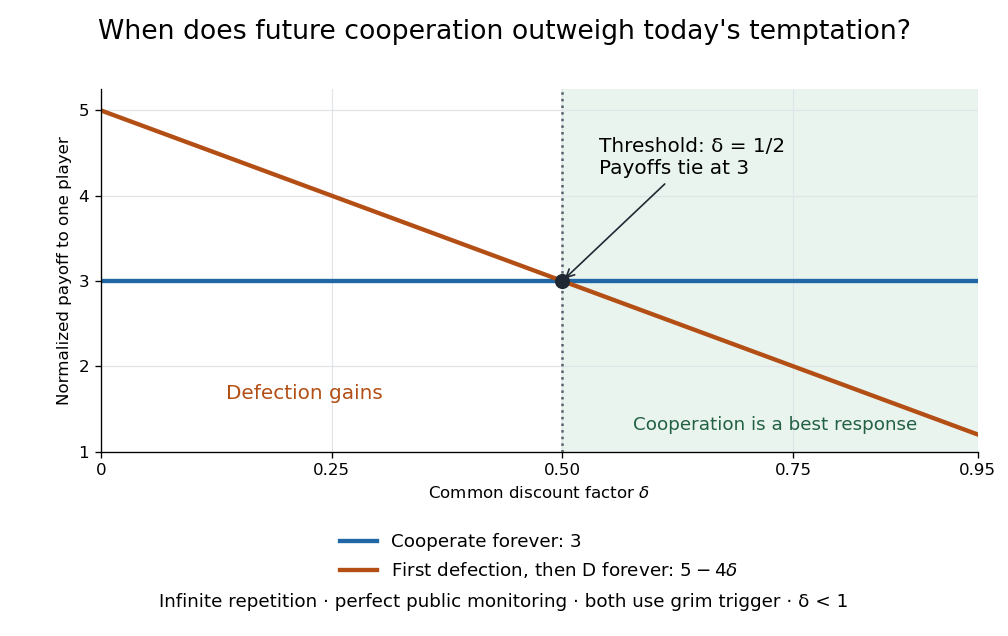
Repeated prisoner's dilemma: normalized cooperation and first-deviation payoffs cross at discount factor one half
. Details. For example, with discount factor , the first unilateral deviation gives normalized payoff , so mutual grim trigger is not a Nash equilibrium. At , it gives , so cooperation is preferable. At the two payoffs tie: the incentive to cooperate is weak, which is sufficient for a subgame perfect equilibrium.
The punishment is credible after every history containing a defection: the opponent's pure strategy then prescribes forever, and remains the stage best response, earning rather than . Together with the cooperative-history comparison, this establishes mutual grim trigger as a subgame perfect equilibrium for . Delaying the first unilateral deviation merely delays the same gain or loss; further cooperation during punishment only lowers the deviator's payoff. Mutual always defect also remains a subgame perfect equilibrium, so patience permits cooperation without making it inevitable.
This calculation assumes an infinite horizon and ; it does not define a discounted payoff at . With a finite, commonly known final round and positive weight on each round, backward induction instead gives mutual defection in every round of this stage game. Observational errors change the model too: one mistaken defection permanently activates grim trigger. Historical dependence, initial memories, and the payoff time convention also affect whether a cooperative rule resists or invades other pure strategies; the existing reactive strategy and Tit for tat discussions concern those additional questions.
The Spite plateau is the approximately constant lithium abundance in warm, metal-poor halo stars. It provides an important estimate of primordial lithium only after accounting for stellar atmosphere physics and possible transport and nuclear destruction of lithium within the stars.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact