A probability space is a measure space whose total measure is one. The sample space contains the elementary outcomes; the sigma-algebra contains the events to which the model assigns probabilities; the probability measure supplies those values. The sigma-algebra lets us combine observable questions using complements and countable unions while remaining within the model.
For two independent uniform dice, take , , and give each ordered pair mass . A random variable might record the sum, the larger result, or whether both results are even integers. These are different functions on the same sample space, rather than different elementary experiments. A probability distribution records the mass of the values of one such random variable and can forget information retained by the full probability space.
For finitely many probability spaces , their product probability space has underlying set , the product sigma-algebra and product measure . The coordinate projections are jointly independent: for measurable , the probability of all coordinate conditions is . Conversely a family of independent coordinates has this product joint distribution. Product structure permits coordinate exposure and independent resampling in concentration arguments.
The sample space is the set of outcomes represented by a probability model. One elementary outcome specifies a complete result at the level of detail the model keeps. An event is a subset belonging to the model's sigma-algebra ; it occurs when the actual outcome lies in that subset. Together with a probability measure , these form a probability space , with .[ref]
Introduction to Probability, Statistics, and Random Processes by Hossein Pishro-Nik. §1.3.1 Random Experiments: definitions of outcome, sample space, and event; three-toss example
Choosing a sample space means deciding which distinctions matter. For two tosses, recording the ordered head-or-tail sequence distinguishes from ; recording only the number of heads merges them. Neither representation is automatically wrong, but the second cannot answer a question about which toss was heads. Keeping a detailed sample space and defining a random variable for the desired observation lets several questions share one model.
A sample space alone assigns no probabilities. Even writing as a Cartesian product does not establish independence: that requires a condition on the probability measure. On a finite sample space with all subsets admitted as events,Only when all elementary probabilities are equal does this become , where the bars denote cardinality. This is the uniform distribution on a finite set, an additional modelling choice.
Sample spaces can also be infinite. For example, take , its Borel sigma-algebra, and the continuous uniform distribution. Then for , so each singleton has probability zero while . Thus an elementary outcome need not carry positive probability, and a continuous model cannot be understood by counting equally likely points. The distinction is developed in zero-probability event and countable additivity.
A family of disjoint events whose union is the sample space. For the countable law of total probability and law of total expectation, use a finite or countably infinite family. Conditioning formulas sum only positive-probability parts, or interpret zero-probability contributions as zero without assigning a conditional expectation there.
An elementary outcome is one member of the sample space. For the ordered two-toss model, is one outcome; it contains both toss results. By contrast, “at least one head” is an event containing three outcomes. The outcome and the singleton set are different objects: when that singleton is measurable, the notation gives its probability. In the finite model below, every subset is measurable.
The word elementary refers to the chosen level of detail. An outcome can be an ordered pair, a sequence, or an entire realization of a point process. A random variable then extracts a numerical feature of that outcome; the window count of a point process is one example.
Model two fair independent coin tosses, recording their order. Here denotes heads and tails, andThe power set includes every question expressible as a subset of these four outcomes. The mass comes from the fairness and independence assumptions. These are exact model probabilities, rather than measured toss frequencies.
Let be the event that the first toss is heads and the event that the second toss is heads. ThenThe union means “at least one head,” while the intersection means “both heads.” Their probabilities are and . Counting the union through the inclusion-exclusion principle gives ; alternatively its complement of an event is , of probability .
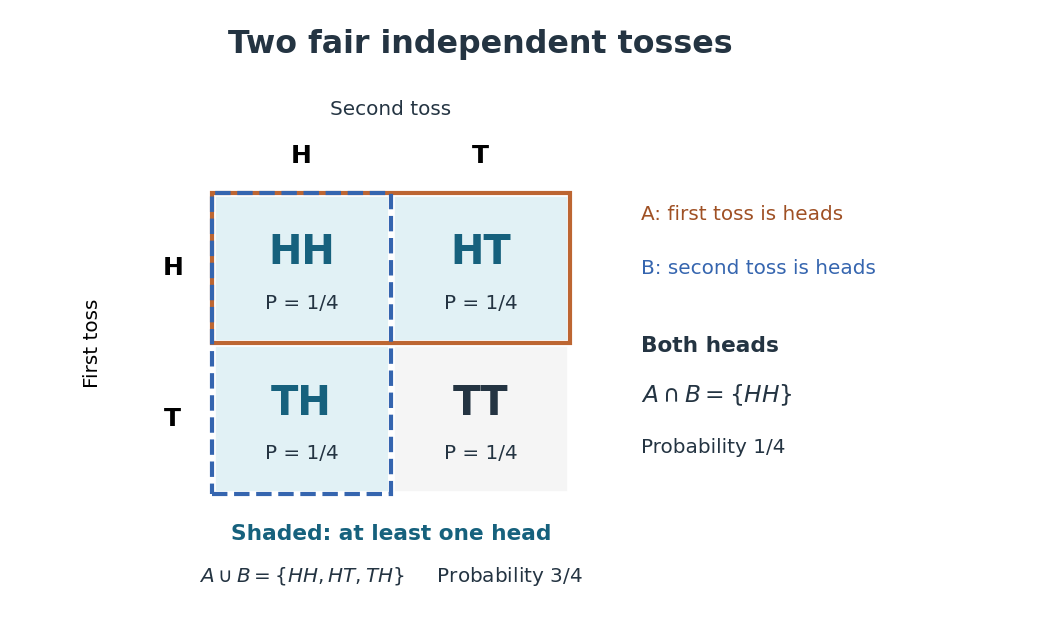
Four ordered outcomes and the event of at least one head
. Rows record the first toss and columns the second. Each cell has probability under fair independent tosses. The highlighted union includes , , and ; the overlap contains only . Details.On the same sample space, assigning masses to would still make each toss fair: . But , so the tosses would be dependent. The event of at least one head would have probability . Changing the probability measure changes the answer even when the sample space and the single-toss probabilities stay the same.
Define the head-count random variable byThe four elementary outcomes are inputs to this function; its three numerical values are outputs. Each fiber of a function collects all outcomes giving one value. Under the fair independent model, adding the masses in each fiber gives the probability mass functionConsequently the output values are not equally likely, although the inputs are. Using the reduced sample space with these masses gives the same head-count probability distribution; assigning to each value would describe a different model.
A question about a random variable's value becomes an event on the original sample space by taking an inverse image:For a real-valued random variable, this is an event whenever is a Borel set, by measurability. In this finite example every subset of is allowed. In particular,This is the same “at least one head” event counted above, expressed through an observable.[ref]
Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist. Probability Spaces, §2 Events and Random Variables, Random Variables: measurable functions and the inverse-image notation for value events
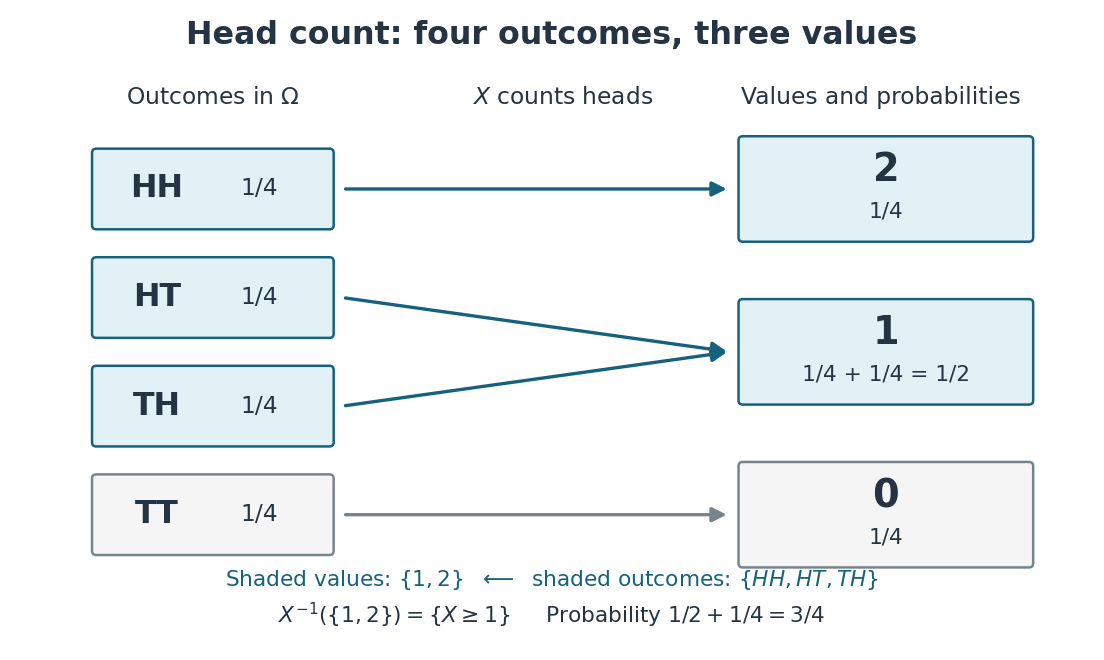
Head count merges outcomes into fibers and adds their probabilities
. The random variable sends to zero, both and to one, and to two. The inverse image of is the highlighted event of at least one head. Two arrows meeting at one explain its probability . Details.Every event determined by is a union of complete fibers. There are such events, whereas the full power set of has . In particular, the first-head event is not determined by : it contains but excludes , although both give . Choosing an observable makes calculations simpler precisely by forgetting distinctions; the useful choice is one that retains the distinctions the question needs.
An almost sure event is a measurable event of probability one. Countable intersections of such events still have probability one, allowing a conclusion to hold simultaneously for countably many parameter choices. Further deterministic reasoning may then extend it to uncountably many parameters, as in Brownian Hölder regularity or nowhere monotonicity of Brownian motion. An uncountable intersection need not preserve probability one without such additional reasoning.
A probability measure is a nonnegative, countably additive measure with total mass one. Thus , and for pairwise disjoint events ,The complement of an event has probability . The probability of a union of overlapping events needs a correction: . Counting the overlap once is the simplest instance of the inclusion-exclusion principle.
A zero-probability event need not be impossible as a member of the sample space. Under the continuous uniform distribution on , every individual point has probability zero, while the whole interval has probability one. Countable additivity applies to countable unions, not arbitrary uncountable ones; there is no contradiction.
Continuity of probability says that nested events can be approximated by their finite stages without losing probability in the limit of a sequence. In a probability space , let . ThenThe sigma-algebra ensures that both limiting events belong to . These are continuity from below of a measure and continuity from above of a measure. The first holds even for an infinite measure; the second requires finite measure of the first set, which is automatic for a probability measure because .[ref]
For a concrete model, toss a fair coin through a sequence of independent Bernoulli trials, and let be the event of at least one head in the first tosses. Its complement is the event of initial tails. On the sample space of infinite head-or-tail sequences,Every finite waiting horizon has positive tail probability, yet the event of waiting forever has probability zero. That intersection is not empty: it contains the all-tails sequence. Thus a zero-probability event need not be impossible as an outcome, and eventual success almost surely does not supply a deterministic deadline. The waiting time for the first head has a geometric distribution with success probability . After ten tosses, the remaining tail probability is exactly ; nine tosses leave .
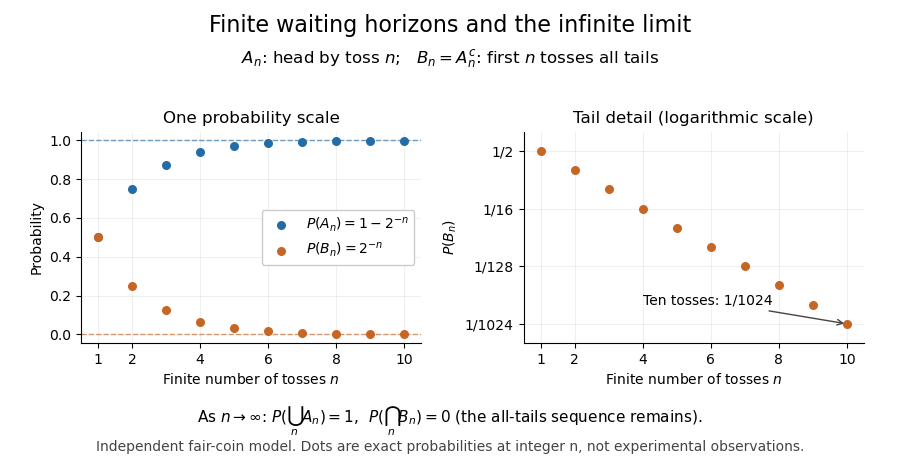
Exact fair-coin model: success by toss n increases to probability one, while the all-tails prefix probability decreases to zero
. Details. A proof outline exposes what makes countable additivity stronger than finite additivity of a set function. For increasing events, put and for . These set differences are pairwise disjoint events, their union is , and the first pieces have union . ConsequentlyFor decreasing events, their complements increase to ; applying the increasing result and the complement rule of probability gives . The finite-total-mass condition is essential for this subtraction. For comparison, the counting measure of each set of natural numbers is infinite, although their intersection is empty and has measure zero.
Conversely, on a sigma-algebra, a nonnegative normalized set function satisfying finite additivity of a set function and satisfies countable additivity. For pairwise disjoint events with , the remainders decrease to the empty set, andTaking the limit of a sequence recovers the infinite sum. This equivalence explains why continuity of probability is part of the foundations rather than a separate assumption about smooth curves.
One useful application controls infinitely many possible errors. If events satisfy , then the events decrease, and the union bound gives . Continuity of probability therefore makes : errors occur infinitely often with probability zero. This is the Borel-Cantelli first lemma, and it requires no independence. For the illustrative bounds , the probability of any error at index or later is at most , an explicit truncation guarantee.
The word continuity here concerns nested sets, not the absence of atoms in a probability distribution. For any real-valued random variable , the events decrease to . Hence its cumulative distribution function is right-continuous even when it has jumps, as for a geometric distribution. The nesting hypothesis matters: an arbitrary sequence of events need not admit either displayed interchange of limit and probability.
A probability measure is tight if compact sets carry arbitrarily nearly all its mass. Every Borel probability measure on a Polish space is tight. The stronger family condition is uniform tightness.
For càdlàg processes on a finite horizon, compact containment together with uniformly small increments over pairs of bounded stopping times whose separation tends to zero is a sufficient criterion for tightness in the Skorokhod J1 topology. The increment condition is in probability, not merely at deterministic times. If in addition the largest jump tends to zero in probability, every limiting law is supported on continuous paths.
The same compact set must work simultaneously for every measure in the family. Prokhorov's theorem relates this condition to relative compactness for the weak topology of probability measures on a Polish space.
A tight sequence of probability measures on the real line has a subsequence whose cumulative distribution functions converge at every continuity point of a cumulative distribution function. Choose a diagonal subsequence converging at every rational , write those limits as , and define . Monotonicity gives right continuity, and tightness of probability measures gives limits zero and one at the two ends of the real line. Bracketing by rational continuity approximations proves convergence at the continuity points of . The corresponding probability measure is the weak subsequential limit: approximate a bounded continuous test function by step functions on a compact interval, and use tightness to bound the tails.
A zero-probability event has probability measure zero. It need not be empty: for a continuously distributed random variable, equality with a specified value is such an event. The complementary event occurs almost surely.
For observations or orbit points , the empirical measure is . Integrating a test function gives its sample average. For orbit points , the difference between and telescopes to , so on a compact metric space with continuous , every weak limit is invariant.
If finite Borel measures and on satisfyfor every compactly supported continuous function , then . This follows from the uniqueness part of the Riesz representation theorem; alternatively, continuous functions that approximate indicators from above and below recover the measure of every interval and hence every Borel set.
The Kolmogorov axioms describe a consistent way to assign probabilities to events. Start with a sample space and an event sigma-algebra : it contains and is closed under complements and countable unions, hence also countable intersections. The probability measure is a function satisfyingThe triple is a probability space. The third axiom is countable additivity; the infinite series means the limit of a sequence of nonnegative partial sums. It applies to pairwise disjoint events, not to overlapping events and not to arbitrary uncountable unions.[ref]
The sigma-algebra specifies which questions have probabilities, while the axioms specify how those probabilities fit together. For a finite sample space one can take the entire power set; a continuous model commonly uses a Borel sigma-algebra. Nonnegativity and normalization do not require equally likely outcomes or independence: those are additional modelling choices.
For an exact six-outcome model, take , , and assign . The total is one because . Define the probability of an event by summing the weights of its outcomes. The disjoint events , and form a partition of a set withThis is a specified mathematical model, not measured die frequencies. The figure makes probability literal area: each region has the same height and a width proportional to its assigned mass. Regrouping disjoint events preserves their total area.
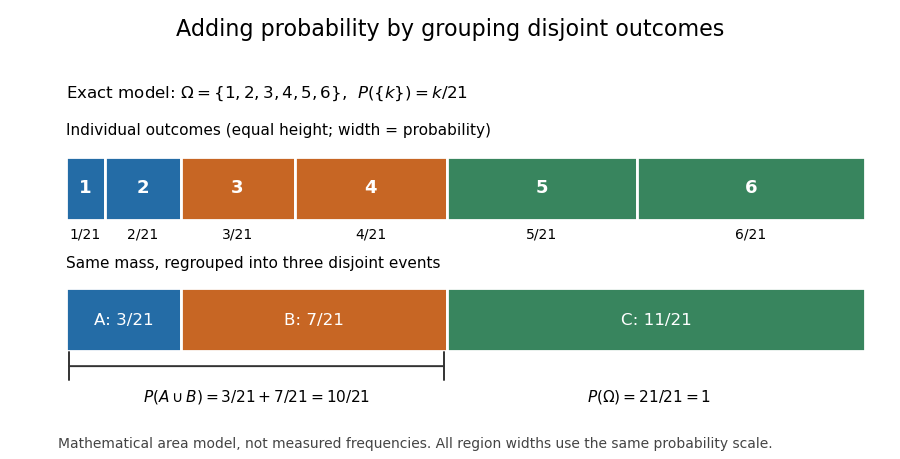
Several familiar rules are consequences, not further axioms. Finite additivity of a set function follows by appending empty events to the sequence in countable additivity; follows already by writing as a disjoint union. The complement rule of probability gives and therefore . Splitting larger events into a smaller event and a set difference shows .
For overlapping events, the inclusion-exclusion principle corrects double counting:In the six-outcome model, and give , agreeing with the weight of . This decomposition is useful because a complicated event can be assembled from simpler questions with known probabilities.
On a finite sample space, a family of pairwise disjoint events has only finitely many nonempty members, so finite additivity of a set function already handles every countable disjoint union. On an infinite sample space, the countable axiom additionally controls what is left beyond every finite stage. In the fair-coin waiting model of continuity of probability, the finite-stage calculations sum to through toss . Countable additivity makes the probability of a head at some finite toss equal to ; finite-stage sums alone do not justify that passage. For the continuous uniform distribution on , each singleton instead has probability zero, while their uncountable union has probability one. Countable, rather than unrestricted, additivity accommodates both models.
Historically, Kolmogorov's 1933 book Grundbegriffe der Wahrscheinlichkeitsrechnung established the influential axiomatic framework connecting probability theory with measure theory. The three conditions above are the modern presentation on a sigma-algebra. Shafer and Vovk's historical study explains that the original presentation began with finite additivity on an algebra of sets and added continuity for decreasing events with empty intersection, which supplies the countable extension.[ref]
Let be a countable measurable partition of the sample space, with positive probabilities. For any event , the law of total probability givesThe pieces are disjoint events, so add their masses and use the definition of conditional probability. Zero-mass partition pieces can be omitted without changing the answer.
For the coin selection in probability, let mean the -head coin was selected and let mean the first toss was heads. Then . Each conditional answer describes one possible hidden situation; its weight describes how often that situation occurs under the model. This decomposition is useful whenever a simple conditional model sits behind a more complicated marginal probability distribution.
The law of total probability combines local conditional probabilities into one overall probability. The measurable partition must cover the sample space with pairwise disjoint events: every elementary outcome belongs to exactly one part. Its probabilities are the weights of a weighted mean, and they sum to one.[ref]
Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist. Probability Spaces, §4 Conditional Probability, Basic Theory, Conditioning and Bayes' Theorem: countable partition formula and weighted-average interpretation
For an original constructed example, make a finite set of 1,000 items: 600 belong to and 400 to . Mark exactly 60 items in and 100 in , and let the event mean that the selected item is marked. Select an item using the uniform distribution on a finite set. These are prescribed counts, so the resulting probabilities are exact properties of this construction:The conditional probability uses only the 600 items in as its denominator. The probability of the intersection uses all 1,000 items instead: . Similarly, . Adding the two disjoint events gives
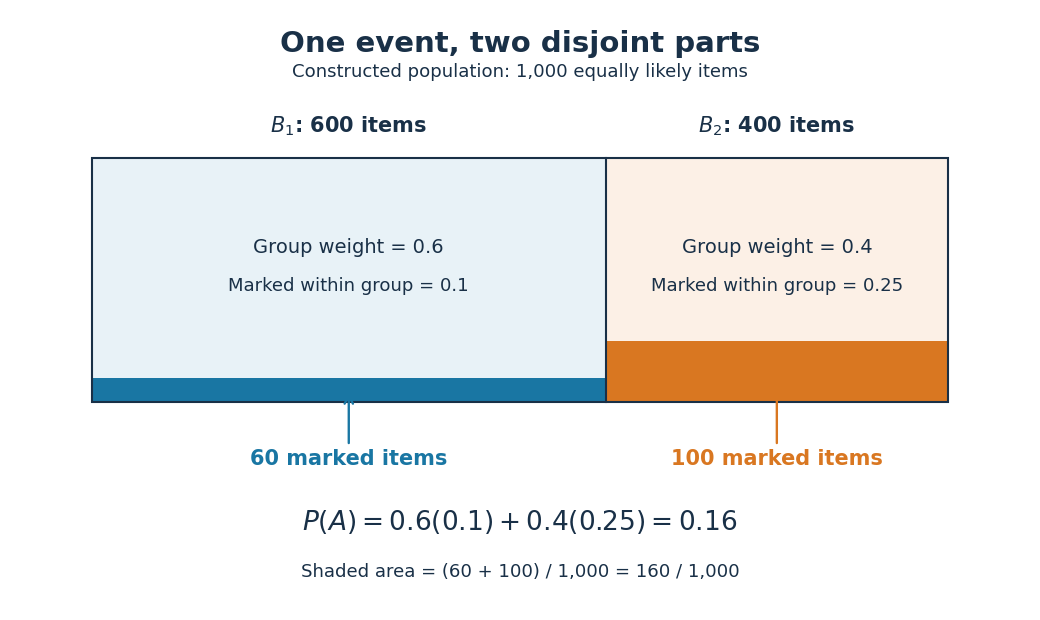
An unweighted arithmetic mean of the two conditional probabilities would give . That is the answer to a different selection rule: choose either group with probability , then select uniformly within that group. Here the first group contains more items, so selecting uniformly among all items gives it weight . In fact, if its weight were , the overall probability would be . Moving the weight from to lowers the result by , explaining exactly why is too large for the original model.
The same construction is a mixture distribution: first select a group with its mixture weight, then select an item within that group. Multiplying the weight by its conditional probability gives the probability of reaching through that group; adding the contributions gives the law of total probability. For example, an item in has selection probability , and an item in has selection probability , recovering the original uniform distribution on a finite set.
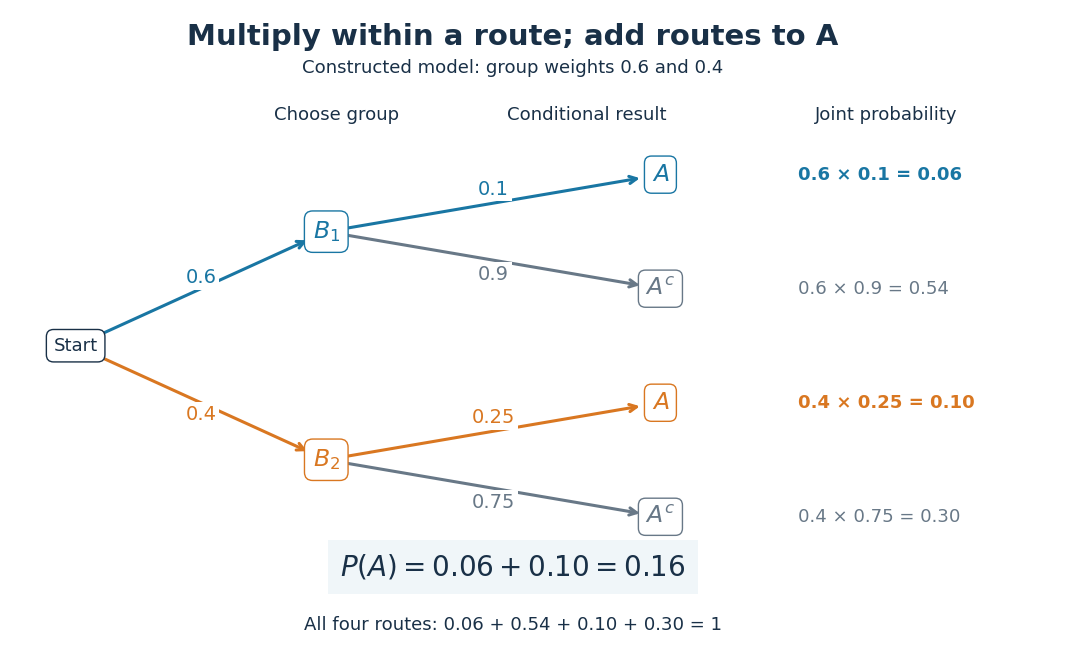
No assumption of independent events is needed. In this construction differs from , so and are not independent events. Also and are disjoint events with positive probabilities, so they cannot be independent events: their intersection has probability zero, whereas . The measurable partition supplies exclusive alternatives, not an independence assumption.
For a short proof, the intersection pieces have union and are pairwise disjoint events. Apply countable additivity, then substitute the definition of conditional probability on every positive-mass part:A zero-probability event has . Omit it: writing would divide by zero. Countability ensures that the union of the omitted zero-probability events also has probability zero. Overlapping parts would double-count their intersections, and incomplete coverage would omit the probability of in the uncovered region.[ref]
Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist. Probability Spaces, §4 Conditional Probability: The Basic Definition requires a positive conditioning probability; Conditioning and Bayes' Theorem proves total probability by partition intersections
Reversing the question gives one compact application of Bayes' theorem. Among the 160 marked items, 100 belong to , so its conditional probability after observing isThe law of total probability supplied the denominator by collecting every way that can occur. Its usefulness lies in choosing a measurable partition where the conditional probabilities are simple, then combining them without losing the relative sizes of the alternatives.
Let a discrete random variable have probability mass function . Given , return with probability ; otherwise draw from a conditional distribution with probability mass function . The law of total probability gives the displayed identity. Its total mass is . If the fallback is a discrete uniform distribution on , then , so the fallback sum includes .
Write , and . The law of total probability gives the displayed convex combination. With fixed and free in ,With fixed and free in ,The joint cell masses are nonnegative and sum to one, proving sharpness in the joint-model interpretation. For ordinary conditional probabilities, a conditioning event must have positive mass. If both and are specified by ratios, then : for the last bounds are strict and their endpoints are the infimum and supremum. If , the marginal equals that common value for every . Endpoint mixtures remain meaningful if the unused zero-mass conditional is treated as a prescribed conditional model rather than a defined ratio.
An event is a measurable set in a probability space: a question with a yes-or-no answer for each outcome. On , the event that the sum is at least nine consists of ten ordered pairs. Its probability is therefore under independent uniform dice. Saying that an event occurred means the actual outcome belongs to that set.
For events in a probability space, the infinitely-often event isIts complement of an event is : after some outcome-dependent index, no more events occur.[ref]
Probability: Theory and Examples (fifth edition) by Rick Durrett. §2.3 opening definition and infinitely-often notation, printed pp. 67–68
Deleting finitely many events leaves the limsup of events unchanged. It is therefore a tail event of the sequence of indicator random variables , whether or not those random variables are independent. For independent events, the Kolmogorov zero-one law restricts its probability to zero or one; the Borel-Cantelli lemmas determine which alternative holds from the series of probabilities. Also precisely when only finitely many events occur, connecting the First Borel-Cantelli lemma to almost sure convergence and the existing complete convergence criterion.
Let be a nondecreasing real sequence tending to , and let be any real sequence. The running maximum exceeds infinitely often exactly when infinitely often. Applying this pathwise to random variables gives the displayed event equality, without any independence assumption.
One implication follows from . For the other, if from some onwards, every later value with satisfies . The finite prefix also lies below for all sufficiently large , because . Therefore the entire running maximum eventually stays below the threshold.
Divergence of the thresholds prevents one large early observation from creating infinitely many crossings. Monotonicity ensures that a later running-maximum crossing is controlled by the corresponding earlier individual threshold. These two conditions explain why the resulting event belongs to the tail sigma-algebra when the thresholds are deterministic.
For any sequence of events, its limsup of events satisfiesSet . These are decreasing events with intersection . Continuity of probability from above givesThis is also the bounded-indicator form of the reversed Fatou lemma. The inequality can be strict: independent fair-coin head events each have probability , while their limsup of events has probability by the Second Borel-Cantelli lemma.
The event that does not occur has probability . Conditioning on an event positively associated with negatively associates its complement with .
Two events are disjoint when they cannot both occur. For a finite family of pairwise disjoint events, the probability of their union is the sum of their probabilities, so that sum is at most one. This condition differs from the condition defining independent events.
On a product space , the cylinder sigma-algebra is generated by coordinate projections. Every event in it depends on at most countably many coordinates.



