An Lp norm measures the size of a measurable function by averaging a power of its absolute value with respect to a specified measure. For ,when the integral is finite. The exponent controls how strongly large values influence the result. The Lp space identifies functions equal almost everywhere, so this becomes a norm on the corresponding equivalence classes. For , use the essential supremum of , as defined by the L-infinity norm. [ref]
Lp spaces (Chapter 7 of Measure Theory). Hunter, Measure Theory, Definitions 7.1 and 7.4: Lp spaces and norms
.For a two-coordinate vector , treat the coordinates as a function on two inputs with counting measure. Then , , and . The middle case is the Euclidean norm; the first adds the coordinate magnitudes, and the last takes their largest value. These are different answers to different questions about size, all satisfying the triangle inequality.
If instead each input has probability , the same values give and , while remains unchanged. Thus the measure is not an optional label. On a probability space, the finite Lp norms are nondecreasing in whenever they are finite, by Hölder's inequality; the unnormalized two-coordinate example above decreases instead. Statements comparing different exponents must specify their measure convention.
Why are these sizes useful? If is an error function, its L1 norm measures aggregate absolute error, its L2 norm measures the square root of aggregate quadratic loss, and its L-infinity norm bounds error almost everywhere. Concentrating a large error on a set of small positive measure can give a modest finite Lp norm but a large L-infinity norm. The three-point example and diagram in L-infinity norm show this explicitly, including why a null set behaves differently from a rare event.
On a measure space of positive total measure, the L-infinity norm of an essentially bounded measurable function is . The absolute value matters: a constant function has L-infinity norm three, even though its essential supremum is . The norm belongs to the equivalence class in Lp space; different representatives equal almost everywhere give the same answer. [ref]
Lp spaces (Chapter 7 of Measure Theory). Hunter, Measure Theory, Definition 7.4: the L-infinity norm
.For the function in essential infimum and essential supremum, under Lebesgue measure, whereas its supremum norm is four. Replacing the exceptional values by the ordinary values leaves every finite Lp norm unchanged as well: . This tends to one as . That agreement explains why the endpoint with exponent uses an essential bound rather than a pointwise bound.
A finite probability space makes the distinction between zero and small measure explicit. Let , , and . Assign weights , , , where . For ,When , the singleton is a null set and . For every , however small, . For example, gives and , yet the large- Lp norms approach ten. The ordinary pointwise supremum norm is ten in both cases.
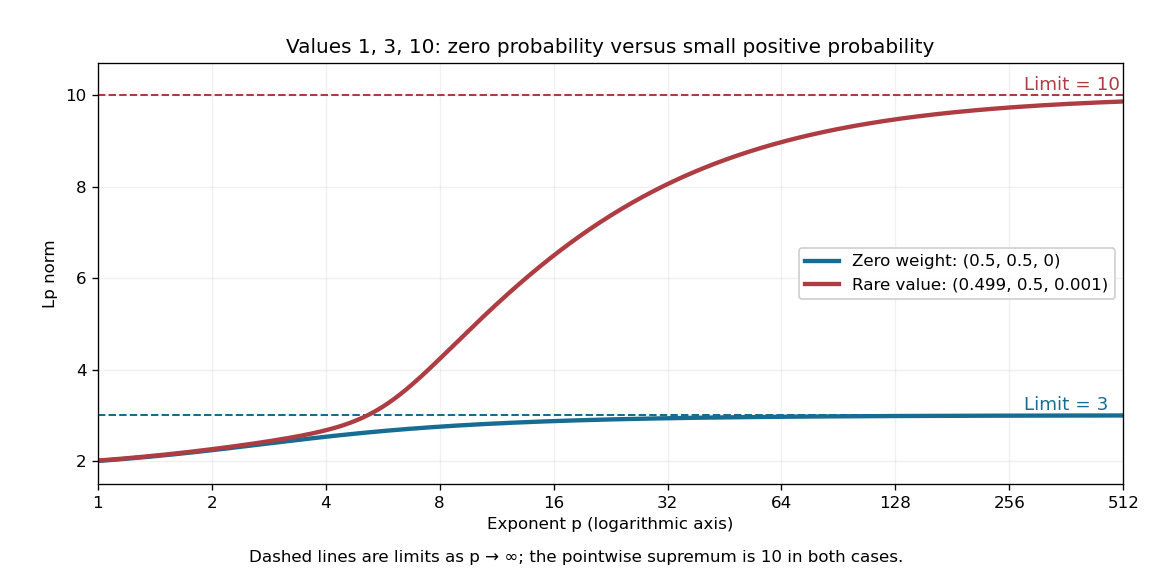
A zero-weight value disappears from every Lp norm, while a rare positive-weight value determines the limiting L-infinity norm
. The original three-point example has values . The curves use weights and , respectively. Dashed levels show the limiting norms three and ten; the plotted finite exponents do not themselves reach those limits. Details.
Why can a rare value dominate? For a bounded function on a probability space, an almost everywhere bound gives . If , the set has positive probability, so . As , the factor tends to one. These two bounds squeeze the limit to . The probability measure assumption keeps total measure finite; this explanation does not assert the same finite- integrability on arbitrary infinite-measure spaces.
A measurable function is essentially bounded if some finite nonnegative real number bounds its absolute value almost everywhere. The exceptional null set may contain arbitrarily large values. With Lebesgue measure on , a function equal to zero outside and equal to at is essentially bounded despite being unbounded pointwise: its exceptional countable set is a null set, so works. Its L-infinity norm is zero because it represents the zero equivalence class in Lp space.
Contrast this with on . For every , the values exceeding occupy , a set of positive Lebesgue measure. Hence no finite almost everywhere bound works, and this function is not essentially bounded. Being finite at every input does not imply essential boundedness.
The displayed quantity is homogeneous and separates zero, but generally violates the triangle inequality. Its th power is subadditive because for nonnegative . Minimizing it is equivalent to minimizing its th power. On finite vectors it is a standard nonconvex sparsity penalty.
For measurable functions with values in the real numbers or complex numbers on the same measure space , and , membership in the same Lp space givesThus adding two functions cannot make their combined Lp norm exceed the sum of their separate Lp norms. The measure need not be finite or a probability measure. The hypotheses require finite Lp norms; uses the essential supremum of the absolute value, not an ordinary pointwise supremum. For complex numbers, the absolute value is the complex modulus. As usual, Lp spaces identify functions equal almost everywhere. [ref]
Measure, Integration & Real Analysis by Sheldon Axler. Axler, Measure, Integration & Real Analysis, §7A, Definition 7.1, pp. 194–195, and Theorem 7.14, p. 199
The Minkowski inequality makes the Lp norm a workable notion of size: it supplies the triangle inequality needed to turn into a metric on Lp space. Applied to , it says that travelling through an intermediate function cannot shorten the direct distance measured by this metric. Applied to two error functions, it gives a bound on the total error even when the errors reinforce one another; Minkowski inequality for error aggregation gives explicit examples.
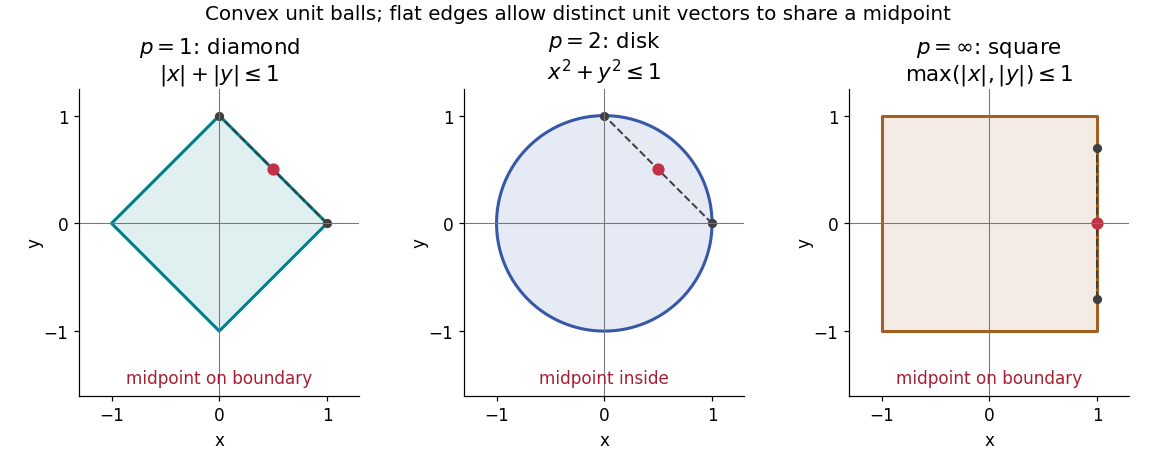
The geometry is already visible in the Euclidean plane. Under counting measure on two coordinates, the closed unit balls for the L1 norm, Euclidean norm, and L-infinity norm are respectively , , and . Every one is a convex set: if have Lp norm at most one, the Minkowski inequality and absolute homogeneity of a norm give for . The Euclidean norm has no flat boundary segments, whereas the other two norms do. This is the distinction captured by a strictly convex normed space and developed in equality in Minkowski inequality.

A short Hölder's inequality proof outline handles . First , so has finite Lp norm before any division. With conjugate exponents and , set ; then . The scalar triangle inequality followed by Hölder's inequality givesDivide if ; otherwise the desired bound is immediate. For , integrate . For , the almost everywhere bounds and give the result by the essential supremum. The same scalar triangle inequality works for real numbers and complex numbers.
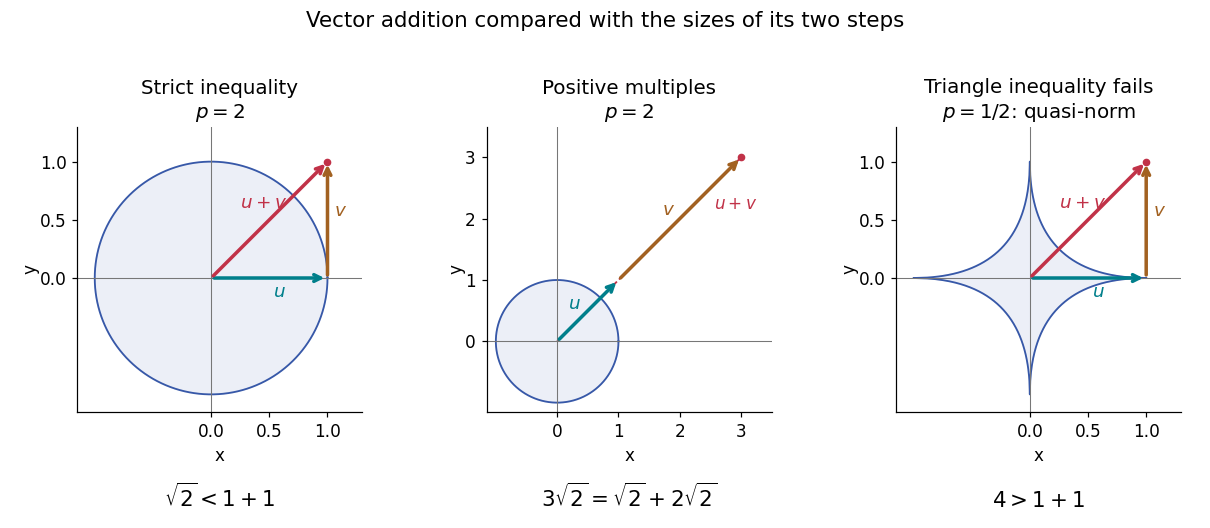
For vectors or , counting measure turns the Minkowski inequality intoFor , replace each displayed norm by the maximum of its coordinate absolute values. Take and . Both vectors have Lp norm one for every , but their sum has L1 norm , Euclidean norm , and L-infinity norm . Thus the same vector addition gives equality at , strict inequality at , and strict inequality at .
By contrast, and give equality for every : absolute homogeneity of a norm yields . At , the three sizes are , , and . Opposite vectors behave very differently: , so the inequality is strict whenever is nonzero. Cancellation is allowed; the bound describes the largest possible total size.

For and nonzero elements of the same real or complex Lp space, equality in the Minkowski inequality holds if and only ifEquivalently, almost everywhere for a single positive real number . The multiplier must be constant across ; matching signs at each input alone is insufficient. For complex numbers, an arbitrary complex scalar multiple is also insufficient: gives for nonzero . If either element is zero in Lp space, equality holds automatically, even if a representative has nonzero values on a null set.
The reason is strictly convex normed space geometry. Normalize to unit Lp norm and use weights and . Distinct normalized functions give a convex combination of Lp norm strictly below one. This follows by integrating the strict convexity of on the real numbers or complex numbers; equality therefore forces the normalized functions to agree almost everywhere.
At , equality instead means almost everywhere: the nonnegative difference has zero integral. For real functions, this is almost everywhere. For complex functions, their nonzero values must have the same argument wherever both are nonzero, but their magnitude ratio may vary. The disjoint-coordinate vectors and illustrate equality without constant proportionality.
At , no such constant proportionality condition is necessary: and have L-infinity norms one and a sum of L-infinity norm two. Nor must an essential supremum be attained: under Lebesgue measure on , give equality , although neither function takes the value one. The endpoint Lp spaces need not be strictly convex normed spaces.
Suppose an approximation is compared with a target through an intermediate approximation , with both error functions in the same Lp space. The identity and the Minkowski inequality combine two error budgets without any independence assumption. The L1 norm controls aggregate absolute error, the L2 norm controls the square root of aggregate quadratic loss, and the L-infinity norm controls the largest error almost everywhere. For equally weighted samples with the probability measure on each coordinate, the L2 norm is the root mean square error; the inequality still applies when this normalization is used consistently.
For example, two signed error vectors and have Euclidean norms and , while . Reinforcing errors and attain the bound ; opposing errors and cancel completely. The Minkowski inequality always allows reinforcement. A smaller combined budget requires additional information about the errors, not just their separate norms.
Iteration gives for every finite sum. For an infinite series, if all belong to one fixed Lp space with and , its partial sums form a Cauchy sequence in the full Lp norm. Completeness of this Banach space then gives norm convergence to an element of the same Lp space. A finite sum bound alone does not establish convergence, and completeness is an additional ingredient beyond the Minkowski inequality. [ref]
Lp spaces (Chapter 7 of Measure Theory). Hunter, Measure Theory, §7.4, Lemma 7.9, pp. 81–82, and Theorem 7.10, pp. 82–83: norm summability and completeness
For , write to emphasize that this is a quasi-norm, as in the Lq quasi-norm branch. On two coordinates with counting measure, and give , but . At , this is the explicit failure in the right panel of the diagram. The midpoint has , so the corresponding unit sublevel set is not a convex set.
A useful replacement survives: for nonnegative real numbers , . Together with the scalar triangle inequality, this yieldsConsequently is a metric on the equivalence classes of measurable functions with finite , even though itself need not be a metric. Do not replace the failed Minkowski inequality by a universal reversed bound for signed or complex functions: would give a zero sum but two positive separate sizes.
For independent mean-zero random variables and , the Marcinkiewicz–Zygmund inequality compares the norm of their sum with the square function:For , one may take .
Hölder's inequality controls a product using separate information about its two factors. If one factor is large on part of a domain, the other factor's complementary Lp norm limits how much their product can accumulate there. The same statement bounds finite sums, integrals and expected values; no independence is required in the probabilistic version.
Let be conjugate exponents, meaningOn a measure space, if and , then andHere the Lp norms are finite; at exponent the norm uses the essential supremum. For a finite vector, integration with counting measure givesThe first step is the triangle inequality; the second is Hölder's inequality.[ref]
For finite vectors, the endpoint case , is : bound every by its maximum, then sum the . Swapping the factors gives the other endpoint. The choice gives the Cauchy-Schwarz inequality.
The conjugate exponent of is , so . The endpoint conventions pair with and with . Examples are , and . The exponents themselves need not add to one; their reciprocals do.
Take , , and vectors and . Their coordinate products are , soTheir Lp norms give the larger boundThus cancellation explains , and Hölder's inequality explains the remaining gap between and the norm product. Small signed sums need not imply small individual coordinate products.
Now keep and choose . The coordinate products are , with no cancellation, andThe matching powers are , namely .
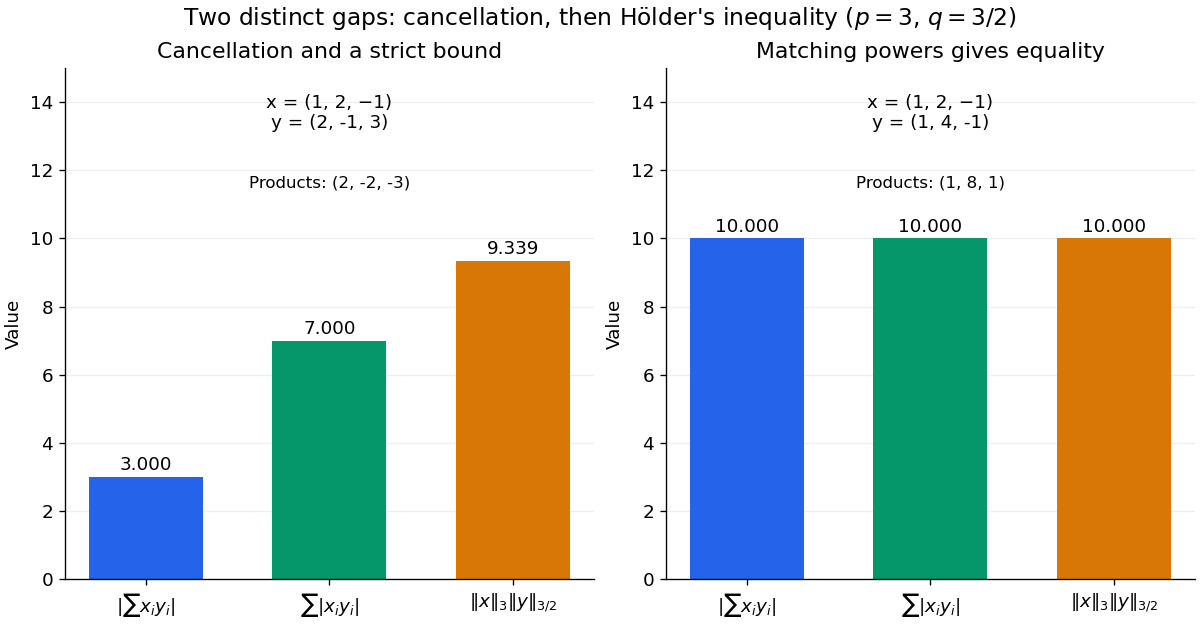
Cancellation and Hölder's inequality account for two different gaps
. Two original finite-vector calculations with , . The first pair has signed sum , absolute-product sum and norm-product bound approximately . The second pair attains equality at . The diagrams show calculated values, with no simulated data. Details.
For and nonzero factors in their respective Lp spaces, equality in the product-integral bound holds precisely whenIn other words, the normalized powers match. Zero factors give the trivial equality separately. For real vectors, equality for the signed finite sum also needs the nonzero coordinate products to have a common sign; otherwise the preceding triangle inequality loses information.
For and on , with , ,Changing only to gives , and both sides become . The factors need not be equal: their conjugate powers are what must agree after normalization.
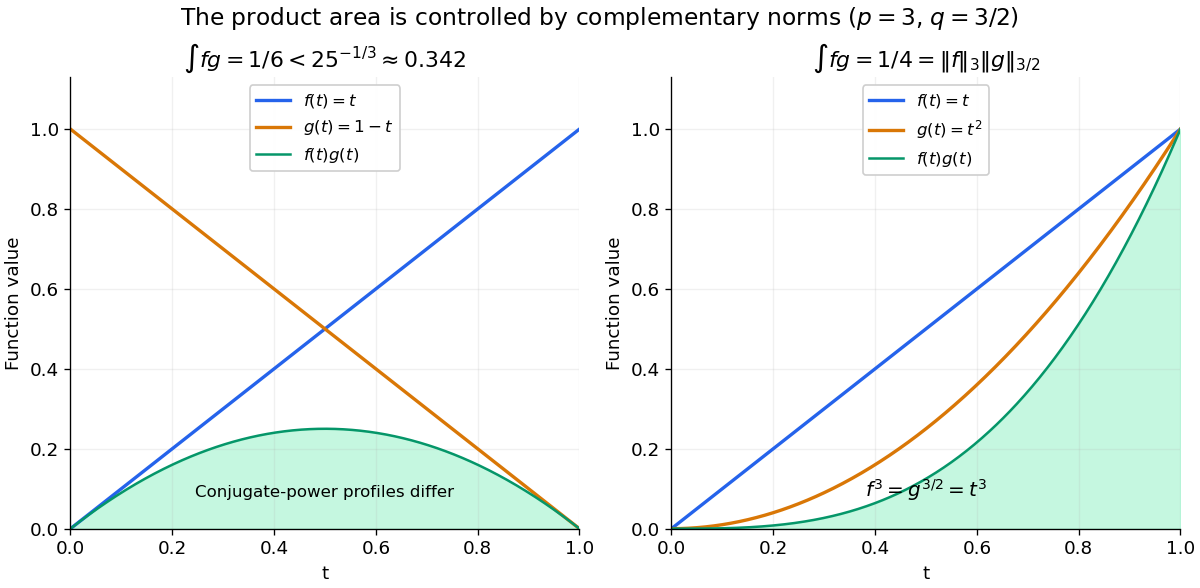

The proof outline makes the equality condition natural. Normalize and . The Young inequality gives ; integration yields . Equality requires almost everywhere. The endpoint proof uses the essential supremum directly, so it does not need division by at .
On a probability space, the same inequality readsIf the displayed moments are finite, the product is an integrable random variable. The random variables can be dependent: the estimate controls their possible overlap without assuming a factorization of the expected value. This is useful when a calculation needs the product to be integrable but the joint probability distribution is complicated.
Otto Hölder's 1889 paper begins with a weighted-mean inequality for a function with increasing derivative. In current terminology, its opening statement is a weighted form of Jensen's inequality: applying a convex function after taking a weighted mean gives a lower bound for the weighted mean of its values. This connects product estimates to the geometry of convex functions, rather than treating them as isolated formulas.[ref]
Ueber einen Mittelwerthssatz by Otto Hölder. Otto Hölder, Ueber einen Mittelwerthssatz (1889), §§1–2, printed pp. 38–39: weighted means and increasing derivative
Articles by others on the same topic
There are currently no matching articles.