Solutions to the single paper shared by the two printed routes, dated 8 June 2021. Oxford examination source release. The probabilistic programming calculations below use only information supplied in the paper. Question 2 contains two notation or naming issues, identified at the affected parts; Question 3 requires an explicit choice of prior distribution.
Assume , and work on the support . In rejection sampling, choose a normalized proposal probability mass function and a known finite constant satisfying everywhere. Draw independent random variables and , accepting when . The joint probability of proposing and accepting is , so the overall acceptance probability is and the accepted value has probability mass function . Fresh trials therefore produce independent and identically distributed random variables with the desired probability distribution. For a fixed positive number of accepted values, the sample average is an unbiased estimator of the expectation when that expectation is finite. Its variance is if the second moment is finite. Finding a valid envelope can be difficult, and a small acceptance probability makes the method expensive.
For the Metropolis–Hastings algorithm, choose a proposal transition matrix and, at the current state , propose . Accept with the Metropolis–Hastings acceptance probabilityA proposal outside is rejected; an impossible proposal need not be assigned a ratio. Otherwise remain at . This constructs a Markov chain satisfying detailed balance with , without computing or a global envelope. Estimate the expectation by averaging over iterations, including repeated states after rejections. Keeping only accepted jumps generally changes the stationary distribution of the recorded process.
The Metropolis–Hastings algorithm produces dependent samples, so the variance of its average includes autocovariances; starting outside stationarity can also cause finite-run bias. With Markov chain irreducibility, suitable recurrence and an integrable , the countable-state Markov chain ergodic theorem gives consistency. Aperiodicity is additionally needed for the usual convergence of one-time probability distributions. In contrast, accepted rejection sampling values need no initial transient. Neither method is universally faster: envelope rejection competes with the proposal quality and mixing time of the Markov chain. Nonnegativity of alone does not guarantee a finite expectation or variance.
Here , with fresh proposal randomness independent of the past. For , the Metropolis–Hastings acceptance probability isThus is independent of , and are independent and identically distributed random variables with probability distribution , even if was chosen arbitrarily in . The method becomes ordinary Monte Carlo method sampling from . The average of is an unbiased estimator, with the variance stated in part (a). Including an arbitrary initial state would spoil this finite-sample property. This is the independent stationary proposal lemma.
Neither Markov chain irreducibility nor fast convergence follows from detailed balance. On two states, the identity transition matrix satisfies detailed balance for the uniform probability distribution, but neither state can reach the other.
Even after imposing Markov chain irreducibility and aperiodicity, considerIt satisfies detailed balance for . Its nontrivial eigenvalue is , and, from state zero, its total variation distance from after steps is . This approaches zero arbitrarily slowly as decreases. Detailed balance without rapid convergence separates correctness of a stationary distribution from reachability and speed.
Put and . For , the off-diagonal probability flux of the proposed rule isIf , define both acceptance probabilities to be zero; both fluxes are zero. The diagonal detailed balance equations hold automatically, including the probability of rejected proposals. Summing the detailed balance equations over gives stationarity:The alternative rule therefore preserves . The unknown normalizing constant cancels after replacing by . This Barker acceptance probability is no larger than the Metropolis–Hastings acceptance probability for the same proposed move: if , then . Preservation of still requires separate Markov chain irreducibility and convergence checks before it guarantees useful sampling.
Use the Poisson distribution with probability mass function on . A symmetric nearest-neighbour proposal with a reflecting boundary isAll other entries vanish. In particular, the boundary proposal does not force a move to one: retaining the probability makes .
The adjacent ratios of the Poisson distribution are and . The Metropolis–Hastings acceptance probability consequently giveswhere the symbol denotes the upward transition probability. Thus the complete transition matrix iswith no downward entry at zero and all other entries zero. In matrix form,Every row is nonnegative and sums to one. An executable Python step of this Poisson Metropolis chain is:
def poisson_step(n, lam, rng):
    if lam <= 0 or n < 0 or int(n) != n:
        raise ValueError("require lam > 0 and an integer n >= 0")
    y = n + 1 if rng.random() < 0.5 else max(0, n - 1)
    ratio = lam / (n + 1) if y > n else n / lam if y < n else 1.0
    return y if rng.random() < min(1.0, ratio) else n
Supply a pseudorandom number generator such as
random.Random(2021) and retain each returned state, including repeats. No normalizing constant or evaluation of a factorial is needed by the algorithm.For each adjacent pair, the detailed balance equations follows directly:For nonadjacent distinct states both fluxes vanish, and diagonal fluxes agree trivially. Since , this is a genuine stationary distribution, rather than merely an invariant measure of infinite mass.
Every upward and downward transition probability between neighbouring states is positive for . Any two states can therefore be joined by a finite path of positive probability: the Markov chain is irreducible. Moreover,State zero has period one; Markov chain irreducibility makes every state aperiodic. Finally, the standard countable-state recurrence theorem states that an irreducible Markov chain admitting a stationary distribution of total mass one is positive recurrent, with that stationary distribution unique. The countable-state Markov chain convergence theorem then states that Markov chain irreducibility, positive recurrence and aperiodicity imply for all states . The hypotheses just verified hold on the infinite state space , not merely on a numerical truncation.[ref]
Markov Chains by James R. Norris. Sections 1.7–1.8, invariant distributions and convergence to equilibrium
Consequently, the unique stationary distribution and the limiting distribution are both , from every initial state. The countable-state Markov chain ergodic theorem also gives almost surely whenever .[ref]
Variational inference replaces exact Bayesian inference by an optimization problem over a tractable family . A guide program samples from this approximating family. Optimizing an evidence lower bound is equivalent to minimizing . Its appeal is that a fitted approximation can be cheap to sample and may scale well when an exact posterior distribution is inaccessible. A restricted family, such as mean-field variational inference, can miss dependence or entire modes; a local optimum can add further error. More optimization cannot remove approximation error caused by an inadequate family.
Monte Carlo method inference instead estimates posterior expectations using simulated values or weighted values. Examples include rejection sampling, importance sampling and Markov chain Monte Carlo. Under their respective support and convergence assumptions, increasing computation can yield consistent estimates without choosing a finite-dimensional posterior family. Their uncertainty includes simulation error; an inefficient proposal or slow mixing time can make that error large. Markov chain Monte Carlo additionally requires convergence and dependence diagnostics.
The central trade-off is optimization within an approximate family versus simulation under a target probability distribution. It is not an absolute distinction between deterministic and random computation: variational inference often uses Monte Carlo method estimates of its gradient, while Monte Carlo method inference may use fitted proposals. Neither method automatically guarantees accurate uncertainty estimates or superiority at a fixed computational budget.
Let , take supported where , and assume the following expectations exist. By the definition of Kullback-Leibler divergence and Bayes' theorem,Therefore the evidence lower bound isNonnegativity of Kullback-Leibler divergence proves . The marginal likelihood is constant with respect to the variational parameter , so maximizing minimizes the stated Kullback-Leibler divergence.
The practical advantage is that evaluating logarithms of joint probabilities and requires no evaluation of the usually intractable marginal likelihood. One can estimate and its gradient with Monte Carlo method. Equality with the log marginal likelihood occurs only when almost everywhere. Merely maximizing the evidence lower bound over a restricted family neither computes the exact posterior distribution nor proves that the maximum attains this equality.
The discrete base factors in the displayed construction inherit their variational parameters. Accordingly write , not a parameter-independent , for the joint base probability mass function or probability density function. The continuous noise factors can be parameter independent while the discrete factors are dependent. Calling the entire base law parameterless while retaining its nonzero score function would be inconsistent.
Let push the base law forward to , and defineUse a fixed base measure , with counting measure for discrete coordinates and Lebesgue measure for continuous coordinates. Assume locally parameter-independent support, differentiability and an integrable domination permitting differentiation under the integral sign. A valid reparameterization gradient givesApply the product rule before simplifying:This is the required combined score and pathwise gradient estimator. A sample from and the integrand on the last line give an unbiased stochastic gradient under the stated regularity conditions. Its first term is a score-function gradient estimator contribution; the remaining terms differentiate the sampled objective along the continuous transformation. The same separation appears in the general stochastic computation graph construction.[ref]
All derivatives inside the expectation hold fixed. They still include both explicit parameter dependence and dependence through . For a continuous coordinate ,The model joint density is fixed as changes, but its composition with need not be constant. Discrete coordinates are not differentiated as real-valued paths; their changing probabilities enter through the score function. Moving supports or parameter-dependent branch boundaries require additional care and are not justified merely by formally interchanging a derivative and an integral.
The two limiting-case names in the printed bullets are reversed. Fully reparameterized continuous choices give a reparameterization gradient; non-reparameterized discrete choices give a score-function gradient estimator. Here are both reductions, including the extra term that vanishes only after taking an expectation.
When all choices are reparameterized with parameter-independent base noise, and . The expression in part (c) becomesDifferentiating along the sampled transformation is precisely the pathwise gradient, also called the reparameterization gradient. There is no score function of the parameter-independent base law.
When all choices are discrete and left untransformed, and . Set and . Since has no variational parameter, the integrand in part (c) isNormalization gives the zero-mean score function identityThusThe first expression is the usual score-function gradient estimator; the second has a constant score baseline of one. The two random integrands are generally different even though their expectations agree. A suitable constant score baseline can reduce variance, but one is not universally the optimal baseline.[ref]
Gradient Estimation Using Stochastic Computation Graphs by John Schulman and others. Section 4, Theorem 2 and footnote 3
For a concrete check, take with and , and a fixed target . Direct integration givesUsing , , the combined integrand has components , and . Their expectations are respectively , and , matching direct differentiation. Dropping the discrete score function term would incorrectly give zero for the first component. This calculation checks the combination without accepting the printed reversal.
Treat each observed arrival label as a constraint on an unobserved walking duration. Departures are treated as fixed design information. Writing for the minutes available until work starts, the derived late-label thresholds have frequencies ; the early-label thresholds have frequencies . These are censoring thresholds, not measured journey times. A late label means , and an early label means ; equality has probability zero under the continuous model.
The paper specifies no prior distribution. One explicit proper model iswith independent priors; all times are in minutes. These ranges are a transparent modelling choice, not information deduced from the observations. In particular, this is a prior on the standard deviation , not a uniform prior on the variance . The normal distribution permits negative durations; it is the mathematical approximation requested here, rather than a claim that such durations are physically possible. A truncated model would be a different model.
The following Python implements hard conditioning by rejection sampling.
None marks a rejected trace; an accepted Boolean answers whether all five future arrivals are late. The same parameters are shared across past and future days.import math
import random
LATE = {20: 1, 21: 3, 25: 3, 27: 1, 32: 2}
EARLY = {29: 1, 34: 1, 36: 3, 37: 1, 38: 1, 39: 1, 43: 1, 44: 1}
RECORDS = [(c, True) for c, n in LATE.items() for _ in range(n)]
RECORDS += [(c, False) for c, n in EARLY.items() for _ in range(n)]
def journey_trace(rng):
mu = rng.uniform(0.0, 60.0)
sigma = rng.uniform(1.0, 20.0)
# Twenty latent past durations and five future durations.
past = [rng.gauss(mu, sigma) for _ in RECORDS]
future = [rng.gauss(mu, sigma) for _ in range(5)]
if not all(t > c if late else t < c
for t, (c, late) in zip(past, RECORDS)):
return None
return all(t > 30.0 for t in future)
def accepted_average(trace, n, rng):
if n <= 0:
raise ValueError("n must be positive")
successes = accepted = 0
while accepted < n:
result = trace(rng)
if result is not None:
accepted += 1
successes += int(result)
return successes / nFor example,
accepted_average(journey_trace, n, random.Random(2021)) estimates the desired conditional probability from accepted traces. Accepting False is essential: treating a false answer as a rejected trace would condition on the desired conclusion. The model deliberately emphasizes clear semantics; rejection can be inefficient because all twenty past-label constraints must hold together.An idealized underlying probability space iswith the product Borel sigma-algebra. Its 27 independent random coordinates are , , twenty past standard-normal noises, and five future standard-normal noises. Define . Sampling an unknown variance does not mean drawing a new variance on each day; a single draw of applies to all durations in a trace.
Let be the event that the first twenty durations satisfy their corresponding observed inequalities. The observations are the twenty late/early labels, conditional on the fixed departure thresholds. They are not exact values of the latent . The posterior probability measure on traces isHere : at every interior parameter pair each strict normal-tail probability lies in , so their finite product has positive prior integral.
The returned outcome isThus the underlying sample space has dimension 27, the successful output space is , and the observations define the conditioning event . The desired output probability distribution is the pushforward measure of under . Rejection is an implementation device, not a third scientific answer:
None is discarded before forming the conditional output law.Write for the standard normal distribution function. Integrating out the twenty independent past durations gives the threshold-censored normal likelihoodThe frequencies are those in part (a). For a future day, the conditional late-arrival probability is . Conditional independence of the five future durations gives .
Exactly three primitive random coordinates suffice. Draw from the same priors and one independent . Reject if ; otherwise return whether . Conditional on acceptance and the parameters, is uniform on an interval of length ; the true-answer subinterval has length . Reusing this same uniform value is therefore intentional, not an independence mistake.
Indeed the two output contributions at each parameter value areThese are exactly the contributions obtained by integrating the original twenty-five duration noises. Multiplication by the common prior density and normalization therefore give the same joint posterior distribution of . The revised program preserves the query and parameter posterior, but does not retain individual latent durations. This is uniform-interval encoding of conditioning and a binary query.
Here is an executable version, reusing the definitions from part (a). Logarithms avoid multiplying many small probabilities.
def normal_logcdf(z):
    value = 0.5 * math.erfc(-z / math.sqrt(2.0))
    return math.log(value) if value > 0.0 else -math.inf

def journey_loglik(mu, sigma):
    return (sum(n * normal_logcdf((mu - c) / sigma)
                for c, n in LATE.items())
            + sum(n * normal_logcdf((c - mu) / sigma)
                  for c, n in EARLY.items()))

def collapsed_trace(rng):
    mu = rng.uniform(0.0, 60.0)
    sigma = rng.uniform(1.0, 20.0)
    log_likelihood = journey_loglik(mu, sigma)
    # This uniform lies in (0, 1], avoiding log(0).
    log_u = math.log(1.0 - rng.random())
    if log_u >= log_likelihood:
        return None
    log_h = 5.0 * normal_logcdf((mu - 30.0) / sigma)
    return log_u < log_likelihood + log_h
accepted_average(collapsed_trace, n, rng) consequently has the same target as the original program. The ideal three-dimensional sample space is with product uniform probability measure, conditioned on the displayed acceptance event. Finite-precision normal tails can underflow to zero in this simple implementation; the mathematical equivalence concerns exact probabilities, and the numerical check in part (d) independently integrates the likelihood in the region carrying appreciable posterior mass.For any chosen proper prior density on with positive evidence, Bayes' theorem givesThe prior density comes from the first two random draws. The likelihood is the probability of satisfying all observed-label constraints after integrating the past duration noises. The factor is the probability of the five-day outcome conditional on the shared parameters. The denominator is the probability of acceptance, which converts the numerator's joint probability into the required conditional probability.
For the independent uniform priors in part (a), the constant cancels and both integrals reduce to , . A prior on the variance would require transforming the density: this chosen prior has density for conditional on . One must not silently replace it by a uniform prior on .
There is no unique numerical probability until the prior distribution is chosen. As a check for the stated uniform priors, independent Gaussian quadrature calculations with 256 and 512 nodes per coordinate agree at the shown precision:The prior-predictive probability of all observed labels is approximately , explaining the rejection cost. These numbers are illustrations of the explicit model, not additional observed data.
A subtle point is that the five future days are independent only conditional on . Integrating shared parameter uncertainty gives , not . The latter is about for these priors and understates the five-day probability. Jensen's inequality gives , while gives . For two future late-arrival indicator functions, their posterior covariance is . This is the posterior predictive repeated-success identity.
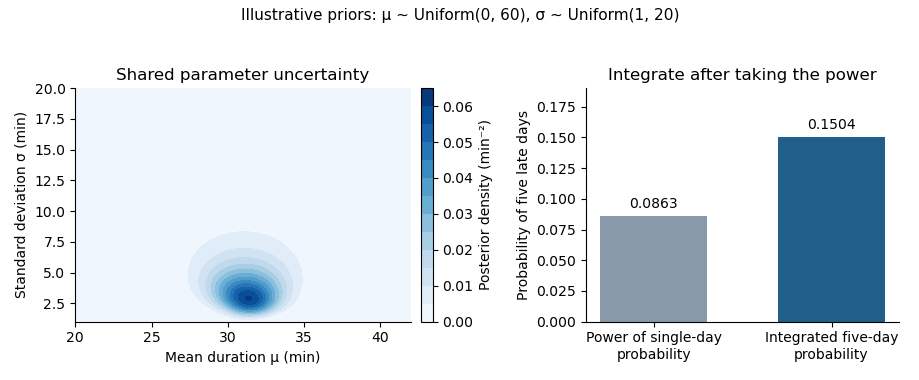
Posterior uncertainty and the five-day predictive probability for the explicitly chosen uniform priors. The contour is cropped to the parameter region carrying the visible mass; integration uses the full prior rectangle.
Details. 
I would first collapse the duration noises as in part (c), then use self-normalized importance sampling on the two shared parameters. Draw independent , give each the importance weight , and returnThis is likelihood weighting: the observations affect the weights rather than forcing repeated simulation of twenty latent inequalities. Integrating out both the constraints' auxiliary randomness and the future Boolean query is Rao-Blackwellization; at fixed parameters it removes randomness without changing the relevant conditional expectations.
The weights and weighted queries lie in , and the evidence is positive. The strong law of large numbers therefore makes the numerator and denominator averages converge to their corresponding integrals, proving almost sure convergence of their ratio to part (d). The finite- ratio is generally biased; the assertion concerns consistency rather than a finite-sample unbiased estimator. Use logarithms of importance weights to avoid numerical underflow:
def weighted_answer(n, rng):
    if n <= 0:
        raise ValueError("n must be positive")
    samples = []
    for _ in range(n):
        mu = rng.uniform(0.0, 60.0)
        sigma = rng.uniform(1.0, 20.0)
        samples.append((journey_loglik(mu, sigma),
                        math.exp(5.0 * normal_logcdf((mu - 30.0) / sigma))))
    offset = max(logw for logw, h in samples)
    if not math.isfinite(offset):
        raise ArithmeticError("all weights underflowed")
    scaled = [(math.exp(logw - offset), h) for logw, h in samples]
    den = math.fsum(w for w, h in scaled)
    answer = math.fsum(w * h for w, h in scaled) / den
    ess = den * den / math.fsum(w * w for w, h in scaled)
    return answer, ess
The returned effective sample size of importance sampling is a concentration diagnostic, not a proof of accuracy. Repeat runs and inspect the weights. If the prior is much broader than the posterior, improve the proposal with the corresponding importance sampling density correction, or use the Metropolis–Hastings algorithm targeting . Because this particular collapsed problem is only two-dimensional, deterministic numerical integration is also an excellent independent accuracy check; it was used for the figure and numerical illustration. Straight rejection of the original traces is correct but wastes most proposals here.
Articles by others on the same topic
There are currently no matching articles.