Topics (374k) Articles (387k) Users (410) Discussions (242) Comments (383) Files (13k) New article

The th Postnikov invariant is the cohomology class whose representing map has homotopy fibre . It specifies how the new homotopy group is attached to the previous stage. A zero invariant gives the product . Merely tensoring homotopy groups with does not describe rationalization of a topological space unless these classes are also transported.
A score is an observation's coordinate along a principal component direction. Center an observation by the fitted sample mean, apply the fitted variable scaling when using principal component analysis on a correlation matrix, then take its inner product with the unit principal component loading vector. New observations must use the training center and scaling. The score variance equals the corresponding eigenvalue when the covariance normalization is consistent.
Assume finitely many nonempty routes, positive weights and adjustment rates, and continuous nonnegative nondecreasing resource prices. Each route must meet a resource whose price is positive somewhere. Then the primal congestion potential has compact superlevel sets inside the positive orthant and a unique maximum. Along gradient flow with diagonal mobility, . The substitution makes the dynamics ordinary gradient flow ascent for . This is strictly concave: the logarithmic terms are strictly concave, and each integrated price is convex and nondecreasing, composed with a convex quadratic load. Thus its continuous gradient is monotone decreasing, which proves uniqueness of trajectories even without differentiability of the prices. Compact trapping and the dissipation identity force every limit point to be the unique maximizer. If every price on some route vanishes identically, its rate instead grows linearly and there is no equilibrium.
The virial theorem and hydrostatic equilibrium relate a cluster's gas temperature to , while . A calibrated mass-temperature relation converts the Press-Schechter halo mass function into . Its exponential rare-cluster tail is sensitive to the density contrast variance on cluster scales, hence to the power-spectrum amplitude, often parameterized by . Mass calibration, temperature scatter, nonthermal pressure, sample selection and the matter density must be included rather than treating temperature counts as an independent measurement of amplitude alone.
For a small category , its presheaf category is the free enlargement under small colimits. Each categorical presheaf is the colimit of the diagram sending to the representable presheaf . The map at sends to . It is surjective at each because is the image of at . If two representatives have the same image , they are both identified with the representative at by arrows in the category of elements, proving injectivity. Thus . For a cocomplete target, a functor on extends by these colimits, uniquely up to natural isomorphism among colimit-preserving extensions.
For a categorical presheaf on a small category, its category of elements has objects with and arrows satisfying . The canonical natural transformation sends to . These maps exhibit as the displayed colimit. At , a representative maps to , with inverse . The arrow identifies every representative with its canonical inverse image, proving the bijection and the colimit universal property.
With fixed covariates and independent new responses having the same marginal distributions as the training responses, expanding squared losses cancels their second moments. Independence makes , yielding the displayed identity. For a fixed linear smoother with covariance , it reduces to , linking prediction optimism to effective degrees of freedom.
// Target: analysis.bigb
For fixed total solar-unit mass and conserved orbital angular momentum, conservative binary mass transfer preserves . Hence . Its logarithmic derivative is , vanishing at with positive second derivative. The ratio diverges at both endpoints, so this is its global minimum. Comparing this minimum to a pre-giant bound tests whether any such conservative antecedent can overflow before the giant branch; satisfying it is necessary, not a proof of an entire evolutionary history.
If some is not injective, extend two distinct equal-image elements to tuples using common choices at all other coordinates; the product is not injective. If some is not surjective, extend a missing target element to a tuple; the product is not surjective. The axiom of choice supplies these extensions. Thus the set-product functor reflects isomorphisms between families whose coordinates are all nonempty.
For an elementary topos, existence of products in a category indexed by a fixed set is equivalent to existence of the corresponding coproducts in a category. The power-object monadicity equivalence gives the forward direction because Eilenberg-Moore categories create limits. For the converse, the diagonal into the pointwise product category is a logical functor. A coproduct is its left adjoint; the adjoint lifting theorem for monad algebra functors, applied through power-object monadicity, then gives its right adjoint, namely the product. The required reflexive coequalizers on the algebra side are opposites of finite equalizers in the topos.
For with and , the logarithmic radiative temperature gradient is . At a marginal boundary with an efficient ideal-gas convective envelope, the Schwarzschild criterion equates it to . Hence . The notation with real positive requires a nonnegative bracket. Vanishing or needs the corresponding logarithmic integration instead of this power form.
For , write an amplification root as . Its equation is . The roots have modulus one and a positive frequency-uniform separation exactly for , giving L2 norm stability through a uniformly bounded diagonalization. At either endpoint the Nyquist symbol has a repeated unit root and a Jordan block, producing linear growth. The normalized local truncation error is generally second order; at and exactly sampled characteristics solve the recurrence, although the latter parameter is unstable for arbitrary perturbations.
If a model configuration leaves a parameter absent from its likelihood function, giving that parameter an independent flat improper prior makes the posterior distribution normalization infinite whenever the configuration has positive prior distribution mass. Integrate first over that parameter: a positive constant likelihood function factor is repeated over all of . This occurs for the second segment mean of a Gaussian change-point detection model when the proposed split is after the final observation. There is no posterior distribution or valid Gibbs sampler for that joint kernel. A proper prior distribution on the unused parameter is necessary if the no-change configuration is retained.
In a hierarchical Bayesian model, replication conditional on fitted observation-level random effects checks the sampling layer. Replication with fresh random effects drawn from their population law also checks the population mean and variation. To assess a dose-response curve, sample the global parameters from their posterior distribution, draw fresh effects for new plates at each existing dose, and compare replicated means, spreads and trend discrepancies with the observed values. Reusing the fitted plate effects can conceal a misspecified mean curve by reproducing deviations those effects already absorbed.
When the prior odds of a real effect are , a study's Type I error is , and its statistical power is , a positive report updates those odds to . This follows directly from Bayes' theorem. A small false-positive rate does not itself make the effect's posterior probability high: the prior odds and power also matter. The posterior exceeds one half exactly when .
Write a loop as with smooth real periodic and its mean. For the level-one representation with modes filled below zero and , choose implementers , where increases charge by one, , and . Their product differs from by the displayed two-cocycle. Its phase is bilinear, which verifies the cocycle identity; integer makes it independent of the ambiguity in . Rephasing implementers changes it by a group coboundary.
Let be a real positive-definite matrix and minimize the displayed quadratic function over all of . Its gradient is , so its only stationary point solves the linear system . The matrix is an invertible matrix, making this solution exist and be unique. Completing the square around that solution proves the stronger global statement:The quadratic function is strictly convex, and its level sets above the minimum are translated ellipsoids. Positivity therefore turns solving a linear system into locating the bottom of a bowl.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §3.1.4, Example 3.2, p. 71: a quadratic function is strictly convex exactly when its symmetric coefficient matrix is positive definite
For the opening matrix , take and . Then , , and . Every displacement raises the value by ; along the unit eigenvectors and the increases are respectively and for displacement or .
For a singular positive semidefinite matrix, a solution of is still a global minimizer, but adding any kernel vector gives another. If is outside the image of a linear map defined by , some kernel vector has , and is unbounded below. For an indefinite quadratic form, a negative eigenvalue gives a direction along which the quadratic term tends to regardless of . Thus a stationary point alone does not establish a minimum. The same energy-difference identity extends to the quadratic variational principle for a symmetric positive operator, with additional existence hypotheses in infinite dimension.
For a real positive-definite matrix in finite dimension, write by the spectral theorem for real symmetric matrices. In the coordinates in an orthonormal basis , the positive level set becomesThis is an ellipsoid, with semi-major and semi-minor axes in two dimensions forming an ellipse; each semi-axis has length and direction given by the corresponding eigenvector. In the opening example, the shorter semi-axis is along , while the longer is along . A stiffer direction, meaning a larger eigenvalue, reaches the same energy at a smaller displacement. The ratio of longest to shortest semi-axis is , the square root of the spectral condition number of a positive-definite matrix.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §2.2.2, p. 30, equation (2.3): ellipsoids and semi-axis lengths; the book uses the inverse quadratic coefficient matrix
Strict positivity matters because givesHence a fixed positive level set cannot extend arbitrarily far. The Cholesky decomposition gives another view: , so the ellipsoid is the inverse image of a sphere under an invertible linear map. A singular positive semidefinite matrix has a nonzero kernel; adding a kernel vector preserves its quadratic form, so any nonempty positive level set is unbounded. These statements concern finite dimension; the positive definite symmetric operator entry explains why strict positivity alone need not give a uniform lower bound on an infinite-dimensional Hilbert space.
Vary the coupling in the opening example. The eigenvectors and form a fixed orthonormal eigenbasis, with eigenvalues and . Writing a vector as givesFor , both directions cost energy and is a positive-definite matrix. At , the quadratic form is : the entire line spanned by has zero energy, and is a singular positive semidefinite matrix. At , the flat line is instead spanned by . For , the quadratic form is an indefinite quadratic form; one direction lowers the energy without bound as its displacement grows. At , for instance, while .
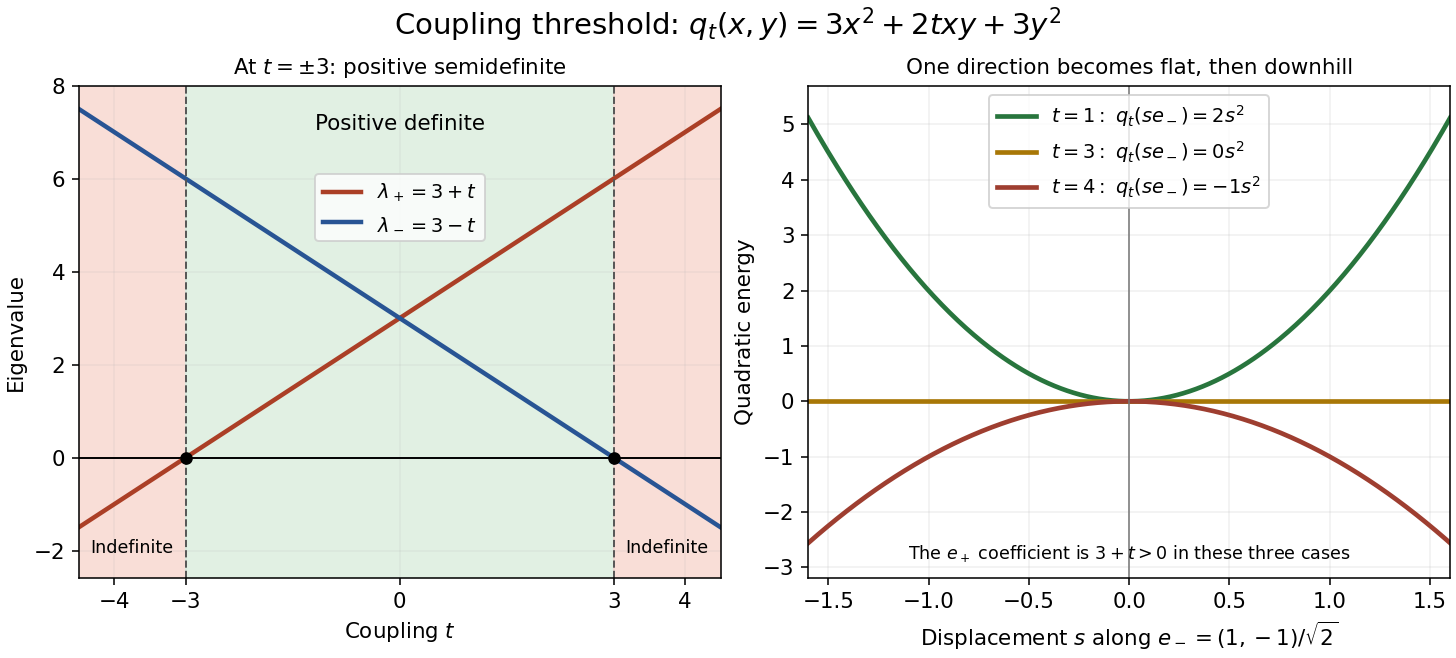
Eigenvalues and directional energies across the positivity threshold
. Details. The geometric transition is precise. For , is an ellipse. At , it consists of the two parallel lines , extending freely in the zero-energy direction. For , it is a hyperbola. The boundary case retains nonnegative energy but loses both the bounded positive level sets and the unique zero-energy vector.
For a real symmetric matrix , completing the square gives, when ,Thus is a positive-definite matrix exactly when and . For necessity, test first, then ; for sufficiency, the displayed two positive squares give the result. These are the first two leading principal minors in Sylvester's criterion. A positive determinant alone is insufficient: has determinant but is a negative-definite matrix.
The eigenvalues provide an equivalent test under the same real-symmetric hypothesis:The spectral theorem for real symmetric matrices supplies coordinates in an orthonormal basis in which . More generally, a complex Hermitian matrix has an orthonormal eigenbasis and , so it is a Hermitian positive-definite matrix exactly when every eigenvalue is positive. This is a short proof outline: test the eigenvectors for necessity, and sum the positive squared absolute values for sufficiency.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. Appendix A.5.2, pp. 646–647: symmetric eigenvalue decomposition and definiteness
For a real positive semidefinite matrix, the condition is instead for all vectors, equivalent here to , , and . If , the same completing the square proves this; if , nonnegativity forces and leaves with . Merely replacing the strict inequalities on the leading principal minors by nonstrict ones fails: has both leading principal minors zero yet gives . An indefinite quadratic form takes both positive and negative values; its real symmetric matrix has eigenvalues of both signs.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact