Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
The coefficient of kinetic friction is the dimensionless quantity for sliding contact with positive normal force in the ideal kinetic friction model. It characterizes the pair of contacting surfaces and their condition. A constant means the model neglects dependence on contact slip speed; unlike the coefficient of static friction, it specifies a sliding force magnitude rather than a no-slip upper bound.
The ratio compares the tangential kinetic friction magnitude with the perpendicular normal force:Here is the tangential relative velocity defining contact slip. Both numerator and denominator have the same physical dimension, so the coefficient of kinetic friction has no units. It belongs to a contact pair under specified conditions, rather than to one material alone. The coefficient of static friction instead describes the threshold before contact slip; a pull required to start motion cannot be substituted for a sliding measurement.[ref]
University Physics Volume 1 by William Moebs and others. §6.2, “Magnitude of Static Friction” and “Magnitude of Kinetic Friction”, equations 6.1–6.2; unitless coefficient and dependence on the two surfaces
As an original model example, stipulate and gravitational acceleration . An already sliding, nonrotating block of total mass is pulled horizontally across a stationary horizontal surface at constant velocity. With no other vertical force, Newton's second law gives . Zero horizontal acceleration then requires a pulling force . Doubling the total mass to gives and . The force doubles while the coefficient of kinetic friction stays by assumption. These numbers are model predictions, not observations or a calibration for a particular material pair.
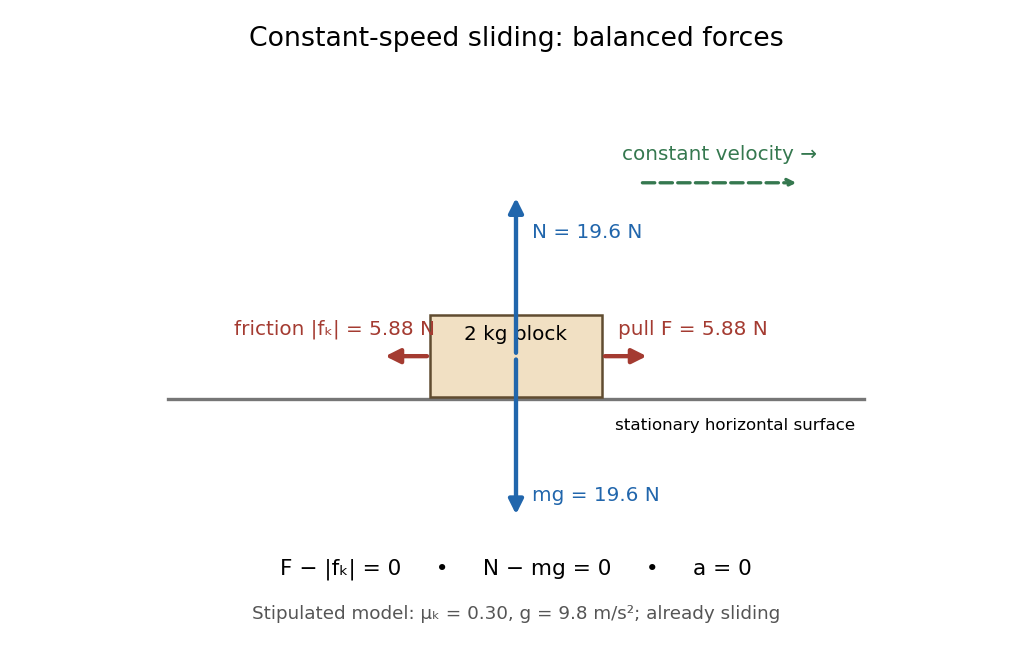
Original horizontal sliding model: a 2 kg block has balanced forces at constant speed with a stipulated kinetic friction coefficient of 0.30
. Details. A constant coefficient of kinetic friction is useful because one ratio can summarize many loads, as tested by load dependence of kinetic friction. It is an empirical approximation over a stated range of normal forces, speeds and surface conditions. It implies no universal independence from speed or apparent contact area: a change of face or sliding regime can change the result. Temperature, wear and lubrication are further conditions to report. Newton's second law still applies when the constant-coefficient approximation fails.[ref]
University Physics Volume 1 by William Moebs and others. §6.2, approximate empirical model; small nonzero speeds; exceptions for lubricated surfaces and high speeds; “Atomic-Scale Explanations of Friction”, apparent versus actual contact area
Reflection of a uniform tube in a horizontal plane preserves an off-axis sphere's transverse position but reverses the axial force. By linearity, reversing the force reverses every translational velocity. By reflection symmetry, it preserves the transverse velocity. Thus the transverse velocity is zero. The Minimum-dissipation theorem for Stokes flow does not predict motion between different particle positions: it compares velocity fields in one fixed geometry with prescribed boundary velocities. Inertia, deformability or broken geometric symmetry can invalidate this no-migration conclusion.
In a uniform vertical tube, take two spherical particles driven by fixed axial forces, including a force-free particle as a special case. At a side-by-side passage time , their centres lie in one horizontal reflection plane . Reflection reverses the applied axial forces, and time reversal reverses them again. Uniqueness of the particle-velocity initial-value problem therefore identifies the reflected reverse trajectory with the original forward one. Their transverse positions before and after passage are equal at matching axial separations. The argument requires passage without contact and neglects inertia or other nonreversible effects.
For a trace-free isotropic Gaussian white noise velocity gradient with covariance , interpret the multiplicative equation as the Stratonovich integral limit of smooth velocity fluctuations. The causal Furutsu–Novikov formula has endpoint weight one half. It gives for the vector probability density function.
For subextreme Kerr spacetime, the outer stationary-limit surface is , where . Away from the rotation axis, and . Its normal is therefore spacelike and the surface timelike. Although the stationary Killing vector field has zero norm on it, it is not normal to it, and the surface is not a Killing horizon. The actual outer Killing horizon is , generated by .
For input coordinates, the homogeneous quadratic polynomial kernel has a weighted quadratic feature map with distinct monomials. Computing an inner product of already stored mapped vectors costs arithmetic operations, whereas costs using the input vectors. Here denotes big O notation. Higher fixed degrees can make the dimension gap much larger.
Sample count still matters. With training examples, materializing a dense kernel matrix stores numbers and requires distinct evaluations using symmetry. A dense direct solve for kernel ridge regression typically takes operations after constructing the kernel matrix, while a dual prediction with nonzero coefficients uses kernel evaluations. Explicit finite feature maps can be preferable when is small relative to , and a stored primal weight vector can make prediction depend on rather than on . The kernel trick by Ryan Giordano (sections Ridge regression and The polynomial kernel) explains the change from feature-coordinate equations to training-example equations; neither representation is universally faster.
The kernel trick saves explicit feature construction when the positive-semidefinite kernel is economical to evaluate; it does not remove the cost of optimization, choose a useful positive-semidefinite kernel, or establish generalization. Random Fourier features illustrate a different tradeoff: replacing the exact Gaussian kernel with a finite approximate feature map can reduce dependence on the sample count while introducing approximation error.
If the weight vector lies in the linear span of the training feature map outputs, write . ThenThis is a dual representation: coefficients weight training examples rather than feature coordinates. They need not be positive, and need not be unique when the kernel matrix is singular. Some kernel methods instead write with under their own optimization constraints.[ref]
The kernel trick by Ryan Giordano. Kernelizing classification with support vector machines: displayed prediction as a sum of label-weighted kernel evaluations
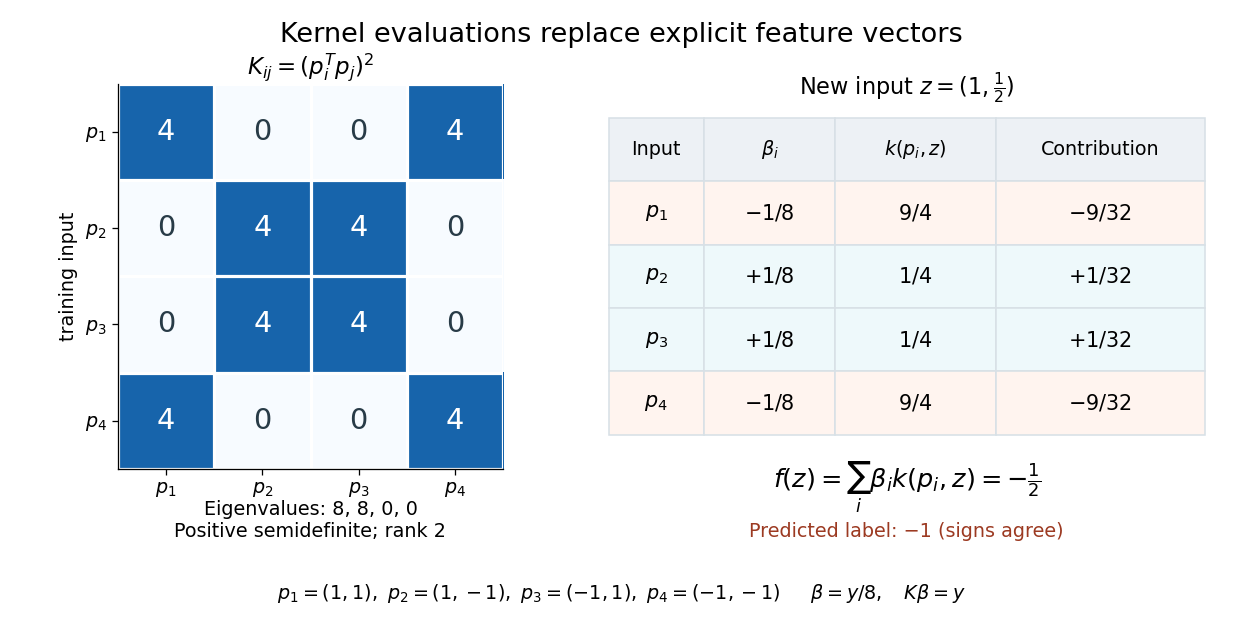
The formula is an algebraic conversion for a weight vector in this linear span, not a claim about every possible weight vector. The representer theorem gives a broader reason this form appears in regularized kernel methods.For the XOR separation by a product feature, let have rows . The Gram matrix of those rows, equivalently the kernel matrix, isIts eigenvalues are , so it is a positive semidefinite matrix of rank two, not an invertible matrix. More generally, for any real coefficient vector and any finite set of inputs,This proves the positive-semidefinite kernel condition for the displayed polynomial kernel on all of , rather than checking only this square.
Here , so the explicit choice gives and . ConsequentlyFor the new input , the four polynomial kernel evaluations are . Their weighted sum is , and the sign function predicts . No explicit feature map is needed for this calculation. These coefficients were constructed to reproduce the chosen separator; no fitting algorithm or generalization guarantee is being asserted.
Give the four corners of the square the exclusive or labels: when the input signs differ and when they agree. In the following order,No affine function has the required strictly positive scores at and strictly negative scores at : both pairs have midpoint zero, so would have to be both positive and negative. This also rules out perfect classification by a single threshold with a consistent tie rule.
Under the polynomial kernel's quadratic feature map, the two classes become two distinct vectors:The hyperplane separates them. With and , the score and classifier areAll four signed scores equal one. In the input plane the boundary is , the union of the coordinate axes; in the derived coordinates it is a single hyperplane. The feature map identifies opposite corners, which is harmless for these labels because opposite corners belong to the same class. A fixed feature map would not separate labels that disagree at identical mapped vectors.

XOR labels in the input square and the quadratic feature slice
. The dashed diagonals join equal-label input pairs and share their midpoint, obstructing affine separation. In the feature panel all mapped points have third coordinate one; the two coincident pairs are separated by the horizontal hyperplane at second coordinate zero. Details.In a kernel-perfect directed graph, lists of size at least admit a proper graph coloring. Choose a color and a digraph kernel in the subgraph on vertices whose lists contain . Color that kernel , delete it, and remove from the remaining lists. Every vertex losing a color also loses an outgoing neighbour; hence the inequality persists. Induction on the vertex count finishes the proof.
For a group homomorphism , two inputs give the same output exactly when . Consequently the fibre over an output is the left coset . These cosets identify precisely the inputs indistinguishable to , which is the mechanism behind the first isomorphism theorem.
For , the chain rule gives . The radial term is killed by crossing with , giving the identity. Purely angular vector spherical harmonics are therefore unchanged as angular basis functions. This is distinct from pushing forward a physical vector field by the inversion Jacobian.
In smooth barotropic inviscid flow with conservative body force, Kelvin's circulation theorem preserves circulation of material curves. Initially zero vorticity therefore gives zero circulation on contractible loops for all times. A loop winding around an excluded obstacle can have a nonzero constant circulation: the planar field is irrotational outside the origin but has circulation on a positively oriented enclosing loop.
Gravitational energy generation in a homologously contracting ideal-gas star by  Codex 0 2026-10-14
For a monatomic gas obeying the ideal gas law, the specific internal energy is . With no stellar nuclear fusion heating, the first law of thermodynamics makes the effective stellar energy-generation rate , with the derivatives taken at fixed enclosed mass. Differentiating gives . In a fixed-mass stellar homology Kelvin-Helmholtz contraction, and at each mass label. Hence when . This includes internal energy storage as well as pressure work; using the gravitational potential-energy decrease alone would overestimate the outgoing luminosity.
Bending-membrane Kelvin-Helmholtz dispersion relation by Codex 0 Created 2026-10-14 Updated 2026-11-05
Codex 0 Created 2026-10-14 Updated 2026-11-05For equal fluid density on opposite sides of a massless flat membrane, a velocity jump and bending pressure jump with , a mode satisfiesThe decaying upper and lower perturbation potentials are and . Their kinematic conditions are and . The linearized Bernoulli equation gives . Equating it to the bending pressure yields the relation. Bending stabilizes . The maximum positive growth is at and is .
With , the two complementary linear projections select its two eigenspaces. A bosonic brane preserves a background Killing spinor precisely when its target-space supersymmetry variation can be compensated by kappa symmetry, giving . This condition must hold at every worldvolume point; several branes require a common solution. The full superspace construction is described in Superspace Geometry for Supermembrane Backgrounds.
For continuous functions on a compact metric space satisfying , set . The triangle inequality makes -Lipschitz, while the constraint gives and evaluation at gives . Thus the feasible pair has at least as large an objective against any two probability measures. This explains why metric optimal transport duality reduces to a single -Lipschitz function.
A pointlike pulse can contain frequencies above the compactification gap even when its travel time and distance greatly exceed the circle size. Its retarded circle-compactified massless propagator can resolve winding images and massive-mode oscillations. Suppressing those modes requires low-frequency or long-wavelength sources/measurements, or suitable smearing; mere coordinate separation is not that restriction. The static Green function across a circle compactification gives a precise long-distance zero-mode limit without this ambiguity.
Represent a balanced partition of by the zero-one vector recording which unordered pairs lie across its cut. Complementary subsets represent the same cut; choose the representative containing coordinate one. Two such cuts differ on the pairs crossing the symmetric difference of their sides, giving the displayed distance. Its maximum is , attained exactly when . Every cut has occupied coordinates, so the vectors lie in an affine hyperplane of dimension at most .
Use the balanced cut-vector distance formula with . There are distinct cuts. A subset of strictly smaller diameter contains no pair with side intersection thirteen, so deleting their shared coordinate one and applying the Frankl-Wilson theorem bounds its size by . At least 1562 smaller-diameter parts are needed, exceeding . The cut vectors occupy an affine hyperplane in , which identifies isometrically with and gives the stated explicit counterexample.
Take , and sign vectors . The Frobenius inner product of two outer products is , proving the formula. The squared Euclidean distance is largest precisely when , where the inner product is minus one. The common diagonal can be deleted, leaving an isometric representation in dimension if off-diagonal coordinates are multiplied by . The Frankl-Wilson theorem then bounds each smaller-diameter class.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact