Unicity distance is the ciphertext length at which key equivocation reaches zero and the key becomes uniquely determined under the source model.
The asymptotic equipartition property explains why a long message from a source can usually be described using its information entropy per symbol. Individual messages can have very different probabilities, but the messages carrying almost all the total probability have similar logarithmic costs per symbol. The Bernoulli typical-set example makes the distinction between an individual message and a large collection explicit.
For independent and identically distributed random variables on a finite alphabet, let be their probability mass function and . ThenHere means the probability mass of the realized word, evaluated under the source law. The product rule for independent random variables turns its information content into a sum:The strong law of large numbers gives the limit. Zero-probability symbols do not occur; on the positive-probability support of a finite alphabet, these information costs are finite. The corresponding typical set consists of words whose cost per symbol is within a chosen tolerance of .
For a strictly stationary process with a finite alphabet, the constant-limit extension requires ergodicity. The Shannon-McMillan-Breiman theorem then replaces the one-symbol information entropy with the information rate. Stationarity without ergodicity in an information source shows why stationarity alone is insufficient.[ref]
6.441 Information Theory (Spring 2016 lecture notes) by Yury Polyanskiy and others. §8, Theorem 8.1 and Corollary 8.2, printed p. 90: stationary ergodic sources and typical sets
Huffman coding makes frequent symbols cheap to store by giving them short codewords, while allowing rare symbols longer codewords. For a known probability distribution on a finite alphabet with at least two positive-probability symbols, binary Huffman coding constructs a prefix code minimizing expected codeword length among binary prefix codes that encode one source symbol at a time. The objective is an average under that probability distribution; it does not promise to shorten every message. Encoder and decoder must agree on the resulting Huffman code. [ref]
The construction grows a binary tree from its leaves towards its root of a tree. Start with one leaf per symbol, weighted by its probability. Repeatedly join the two currently smallest weights beneath a new parent in a rooted tree, whose weight is their sum, and replace the pair by that subtree. Include newly formed subtrees when choosing the next pair. When one tree remains, label the two outgoing edges at every internal vertex with and ; the labels on the graph path from the root of a tree to a symbol give its codeword. This is a greedy algorithm: each step makes a locally cheapest merge, yet the result is an optimal prefix code.
For a concrete example, use probabilities , , , . First join and , creating weight . The remaining weights are for , for the subtree, and for . Join the two weights to make , then join with that subtree to make . The merge weights are therefore . Each merge adds one bit to every codeword below it, so their sum is the expected codeword length: bits per source symbol. The diagram fixes the edge labels to produce the Huffman code used below.
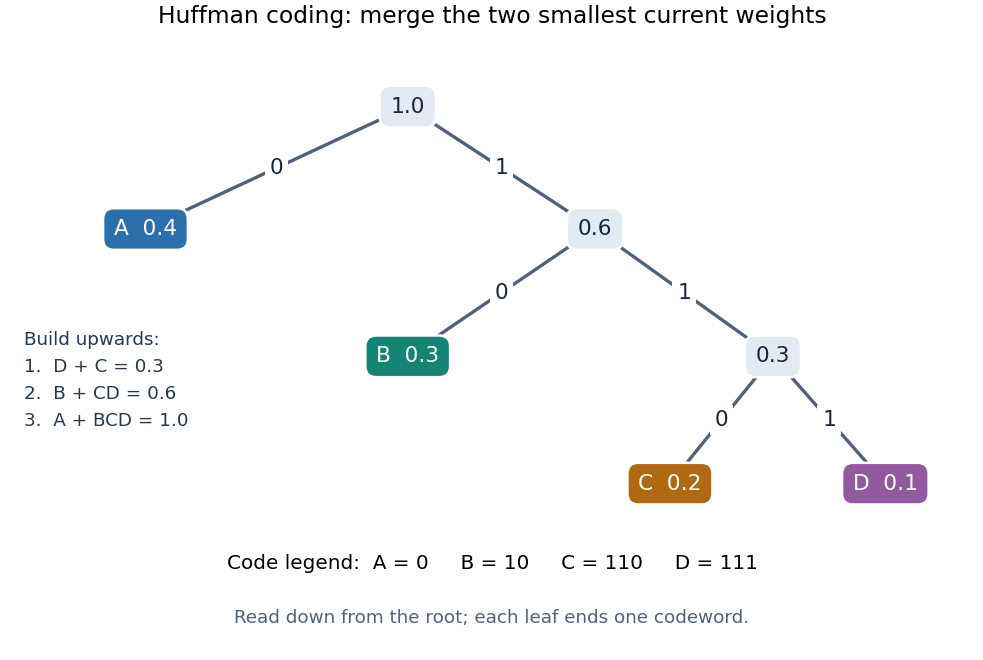

The useful insight is that choosing short codewords is a resource allocation problem: the prefix code condition constrains the available codeword lengths through the Kraft inequality. Huffman coding solves this one-symbol problem exactly for the supplied probability distribution. For repeated emissions of a memoryless classical information source, the same Huffman code can be applied symbol by symbol. More general compression can exploit dependencies or encode groups of symbols; the one-symbol optimality statement does not compare all such methods.
A one-to-one source code is an injective function from source symbols to finite codewords. Unlike a prefix code, it need not permit instantaneous decoding of concatenated codewords.
For a finite discrete random variable with probability mass function , its information entropy is the expected value of its information content:Base-two logarithms give bits; choosing a different base rescales the units. The convention is justified by a limit, so outcomes of zero probability contribute nothing. The definition also applies to countable distributions, but the sum may be infinite.
A fair bit has . A certain outcome has . A Bernoulli random variable that is one with probability has bits, because most of its outcomes are predictable. A rare outcome still has large information content: the outcome of probability contributes bits of surprise when it occurs. Entropy is the average surprise, rather than the surprise of each outcome.
For possible outcomes, , with the upper bound attained exactly by the uniform distribution on a finite set. The Gibbs inequality proves this by comparing with the uniform distribution: . Thus increasing predictability reduces the required average description length. The four-symbol prefix code in information theory attains bits exactly; for general probabilities, integer codeword lengths prevent such a perfect match for every individual symbol. Shannon's source coding theorem explains how coding sufficiently long independent blocks approaches the entropy per symbol.
The logarithm is especially natural because independent outcomes have additive surprise: . Taking expected values gives additive information entropy for independent random variables; for dependent ones, the chain rule for information entropy replaces the second term by conditional entropy. This is why the same quantity can govern both a single observation and a long message.
Channel capacity is the best reliable information rate available through a specified communication channel. For a discrete memoryless channel with finite input and output alphabets, fixed transition probabilities , and no input-cost constraint, it isin bits per channel use, when the mutual information uses base-two logarithms. The maximization varies the input probability distribution, while keeping the communication channel fixed. A large input alphabet or a large output information entropy alone does not determine how much information gets through: the receiver needs information about the input, rather than merely unpredictable output.
The operational meaning comes from the Shannon second coding theorem. A block code represents one of possible messages by a word of length , giving a rate bits per use. Take the message label from the uniform distribution on a finite set of those choices when measuring average decoding-error probability. For every fixed rate , there are sequences of such block codes whose decoding-error probability tends to zero as grows; a rate above cannot have vanishing decoding-error probability. This is an asymptotic limit, rather than a promise that an arbitrary finite block code at a rate below works well. See MIT 18.310, Shannon's Noisy Coding Theorem, sections 1–2.
For a binary symmetric channel with crossover probability , the binary symmetric channel capacity is approximately bits per use. Thus a binary code rate lies below the limit, while lies above it. At , two transmitted symbols represent one message bit on average; the redundancy helps distinguish messages after noise. This does not split individual physical symbols into fractional pieces.
The result is useful because it separates two tasks. Computing channel capacity establishes the target imposed by the transition probabilities; constructing an effective block code attempts to approach that target with acceptable delay and decoding effort. The surprise is that reliability can improve indefinitely without forcing every positive rate to disappear. In his 1948 paper, Shannon defines noisy channel capacity in section 12 and develops its operational significance in section 13, Theorem 11. His original formulation uses information per unit time; the fixed-duration channel-use convention here expresses the same rate question per symbol. [ref].
A type summarizes a string by how often each symbol occurs. Fix a finite alphabet of cardinality and a positive length . For a string , its empirical distribution is the probability mass functionThe empirical distribution forgets order. The strings and both assign probability to each binary symbol; assigns to zero and to one. Thus a long string can have a short summary even though that summary does not reconstruct the original order.
For independent and identically distributed symbols, this loss of order has a useful consequence: all strings with the same empirical distribution have the same probability. The method of types uses this symmetry to turn questions about exponentially many strings into counting questions about relatively few frequency profiles.[ref]
The Method of Types by Imre Csiszár. §I, printed p. 2505: partition by empirical distribution and equiprobability under a memoryless model
For two probability mass functions , a decision region accepts . Its two error probabilities are and .
For independent finitely supported random variables in a finite additive group,This is the data processing inequality for mutual information applied to the Markov chain .
For finitely supported random variables in a finite additive group, let be independent variables with their respective marginal distributions. The entropic Ruzsa distance isIt is symmetric and nonnegative, but can have .
For finite discrete random variables, mutual information is the reduction of information entropy provided by observing the other variable:The last expression makes the symmetry visible. It is nonnegative and is zero exactly when and are independent random variables. One way to see both facts iswhere is the Kullback-Leibler divergence with base-two logarithms. The Gibbs inequality gives nonnegativity; equality means that the joint probability distribution factors. The statement extends to more general distributions via relative entropy, but differences of infinite information entropies must not be used as if they were finite numbers.
A binary symmetric channel gives a useful example. Let be a fair bit, let be an independent Bernoulli random variable with error probability , and set , where is exclusive or. The output is also a fair bit, but knowing the input leaves just the error uncertainty:Here is binary entropy. At , , so the output carries about bits of mutual information about the input per use. This is an average uncertainty reduction, not a claim that each observed symbol can be divided into fractional physical bits.
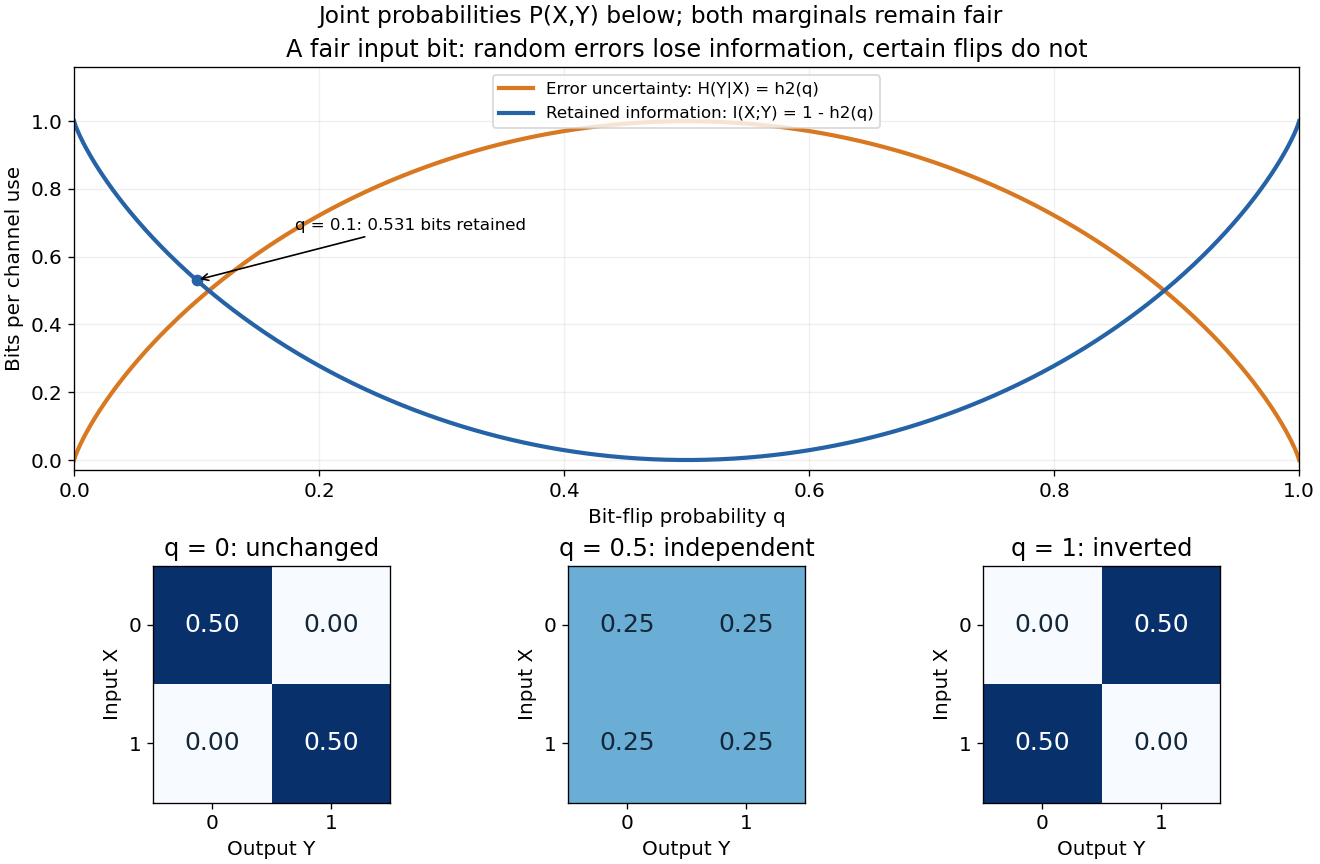
Binary entropy and retained information distinguish noisy transmission from predictable bit inversion
. Details. 
At , every output is equally likely for either input, so . At , the output is always the inverted input: knowing this rule lets the receiver recover the input exactly, so again. A high raw error rate need not mean low mutual information when the errors are predictable. For this particular channel the fair input is optimal, giving the binary symmetric channel capacity .
Mutual information detects dependence that ordinary correlation can miss. Let be uniform on and . Symmetry gives , hence zero covariance and zero correlation, while is completely determined by . Thus . This distinction is useful whenever a relationship is nonlinear: knowing one variable can reveal another without a linear trend.
For finite discrete random variables, conditional entropy is the average remaining information entropy of after the value of is known:Each observation changes the probability distribution used to describe ; the average weights that uncertainty by how often the observation occurs. An observation can increase uncertainty for one particular outcome, even though conditioning reduces entropy on average for finite variables.
For example, let choose with probabilities , and let report whether . If it reports yes, there is no remaining uncertainty. Otherwise the conditional probabilities are , whose information entropy is bits. The two reports each occur with probability , so of a bit. The original uncertainty was bits: this observation removes exactly one bit on average.
If is a function of , then : the observation determines the answer. If and are independent random variables, then : the observation gives no improvement. These endpoints make conditional entropy useful for separating relevant observations from irrelevant ones. They also lead to the chain rule for information entropy, , which counts the first uncertainty and the remaining uncertainty without double counting.
The infinite square well supplies the one-dimensional factors of this rectangular-box construction.
A divergence-free vector field satisfies . It preserves volume under its flow, and its transport operator is skew-symmetric when boundary fluxes vanish.
Endpoint expansion of the incomplete gamma function by  Codex 0 Created 2026-09-24 Updated 2026-09-24
When with , the integral is dominated by its lower endpoint. Setting and applying Watson's lemma gives coefficients rational in .
Asymptotic expansion by repeated integration by parts by Codex 0 Created 2026-09-24 Updated 2026-10-20
Codex 0 Created 2026-09-24 Updated 2026-10-20Repeated integration by parts generates successive inverse powers of a large endpoint, with a remainder expressed by the same integral with shifted parameters.
The interaction Hamiltonian generates interaction-picture time evolution. To leading order for many cubic field interactions it is the negative of the cubic interaction Lagrangian, although derivative interactions require the canonical Legendre transform to justify this relation.
There are unlisted articles, also show them or only show them.