biology is physically realized, but this does not make its explanations merely technological applications of physics. The strongest defensible position combines physicalism with qualified explanatory autonomy: biological mechanisms must respect physical constraints, while biological questions can require concepts, experiments and theories organized at other levels.
The contention associated with J. J. C. Smart should first be separated into different claims. Ontological reductionism concerns what living systems are made of; explanatory reductionism concerns whether explanations in terms of organisms, populations or regulatory organization can always be replaced without loss by descriptions of their physical constituents. A methodological preference for investigating smaller components is a further claim. Accepting the first does not logically establish the other two. The cited article supplies the historical setting for the contention; the distinctions here provide a way of assessing it.[ref]
Can biology be an exact science? by J. J. C. Smart. Synthese 11 (1959), pp. 359–368; article identified in the examination
The reductionist case has substantial scientific force. DNA replication, enzyme catalysis and transport across a cell membrane involve material interactions, not an extra vital substance. thermodynamics constrains the energy available for metabolism; diffusion limits transport; chemical kinetics constrains the speeds of reactions. Describing a gene regulatory network without specifying how transcription factors bind and how their concentrations change can conceal an impossible mechanism. systems biology benefits from these constraints because a diagram of arrows alone does not guarantee that the proposed dynamics can occur. Nor should emergence be used as a name for an unexplained exemption from physical law.
Nevertheless, physical consistency leaves many explanatory questions open. Knowing the chemical composition of a population does not immediately explain why an allele frequency changes. In a simple haploid natural selection model with two alleles and reproductive outputs , the next-generation frequency satisfiesThis relation identifies differential reproduction as the relevant comparison. It applies to many distinct molecular causes of the reproductive difference, provided the model's assumptions hold. An explanation of why an allele spreads can therefore be both physically implemented and usefully stated at the population level. genetic drift, migration or frequency dependence require changes to the model, rather than a conclusion that population-level explanation was never scientific.
Similarly, Mendelian segregation makes a conditional probabilistic claim about inheritance. For a heterozygote cross at one locus, equal segregation, random fertilization and complete dominance produce genotype probabilities and a phenotype ratio of . A molecular description explains how chromosomes segregate and why exceptions occur; it does not remove the utility of the inheritance-level relation. Molecular detail and the higher-level relation answer connected questions at different resolutions. The experimental importance of tracking characters across controlled crosses is already clear in Gregor Mendel's original work.[ref]
Experiments in Plant Hybridization by Gregor Mendel. experimental design and the segregation of characters in successive hybrid generations
Organization also matters. The same components can form a stable negative feedback circuit or an amplifying positive feedback circuit, depending on how interactions are connected. Conversely, distinct biochemical implementations can produce the same adaptation behavior. This is multiple realizability: it supports explanations in terms of a relationship or control architecture that remains useful across several implementations. It does not establish that every implementation has identical dynamics, or that a sufficiently complete physical description could never recover the behavior. The claim is about what makes an explanation informative and generalizable, not a proof of nonphysical causation.
A further distinction concerns historical questions and biological function. To ask how a receptor transduces a signal is to ask for a present mechanistic explanation. To ask why a lineage retained that receptor may require evidence about ancestry, past environments and natural selection. Present physical laws alone do not supply those historical boundary conditions. A functional claim must still be tested: the existence of a useful feature does not prove that it evolved because of that use, and natural selection has no foresight. Explanations of evolutionary history complement rather than contradict physical accounts of current operation.
The objection that biology lacks exceptionless laws is also too quick. Many useful biological generalizations are conditional on explicitly stated assumptions, but physical models also idealize away interactions, specify boundary conditions and use statistical descriptions. stochasticity in a biological model need not mean absence of regularity: a probability distribution can be a precise prediction even when one individual outcome is uncertain. The scientific issue is whether assumptions, predictions and domains of applicability are clear enough to be tested.
There are limits to this defense of autonomy. A higher-level explanation should not be protected from evidence about its mechanism, and an attractive organizing principle should not substitute for quantitative testing. Conversely, merely listing every molecular event can fail to reveal which changes would alter the outcome. A productive investigation moves between levels: identify a population or cellular regularity, propose a mechanism, perturb its components, and test whether the higher-level prediction survives. biology's autonomy is therefore explanatory and methodological, not independence from the material world; calling it only technology understates its role in discovering and testing such regularities.
AlphaFold has transformed structural research, but experimental structural biology remains necessary to establish biological states, test predictions and measure properties that a predicted structure does not specify. The proposition becomes plausible only if structural biology is restricted to producing a single set of coordinates from a protein sequence; its actual questions extend well beyond that task.
The achievement should not be minimized. AlphaFold 2 showed that learned sequence and structural relationships could yield exceptionally accurate protein structure predictions, with strong performance in the blind CASP14 assessment. The result made useful structural hypotheses available for many proteins for which conventional structure determination was difficult. Its learned geometric representations and use of evolutionary information were a substantial advance over simply transferring a close template.[ref]
Highly accurate protein structure prediction with AlphaFold by John Jumper and others. Abstract; structural accuracy assessment and the CASP14 evaluation
Such models can reveal likely protein domains, suggest candidate active sites, guide construct design and focus expensive experiments on specific uncertainties.By the examination date, the scope had already expanded. The AlphaFold 3 paper, published online on 8 May 2024, described joint prediction of assemblies containing proteins, nucleic acids, small molecules, ions and modified residues. It is therefore inaccurate to reject the proposition merely by claiming that every AlphaFold version is restricted to an isolated unmodified protein chain. Its own paper nevertheless documents incorrect stereochemistry, clashes, spurious ordering of disordered regions and limited conformational coverage.[ref]
The central distinction is between a plausible coordinate model and a measurement of a particular sample. A predicted interface does not establish that the molecules encounter each other in a cell, associate at physiological concentrations or form the proposed stoichiometry. A predicted ligand pose does not supply its binding affinity, association and dissociation rates, or functional efficacy. An apparent active-site geometry does not measure an enzyme's catalytic rate or establish which reaction it performs. Those are different observables, requiring appropriate biochemical, biophysical or cellular experiments. Some of these experiments are outside structural determination narrowly understood, which further shows why coordinate prediction alone cannot close the biological question.
Many proteins also act through a conformational ensemble. Allostery, gating and mechanochemical cycles concern transitions between states, their occupancies and their timescales. One accurate fold is not a measurement of that ensemble. Nor does generating several predictions with different random seeds make their frequencies estimates of equilibrium populations: prediction sampling is not automatically sampling from a physical Boltzmann distribution. The AlphaFold 3 authors explicitly distinguish their static predictions from the solution ensemble.[ref]
Accurate structure prediction of biomolecular interactions with AlphaFold 3 by Josh Abramson and others. Model limitations, discussion of conformational coverage and random seeds
An intrinsically disordered region may be biologically functional precisely because a single rigid structure is an inadequate description.Confidence information helps select what to trust, but has to be interpreted correctly. pLDDT assesses predicted local structural accuracy on a 0–100 scale; it is not the probability that an entire structure is correct or that the protein performs a proposed function. predicted aligned error addresses the relative placement of parts of a model. Two domains can each have convincing local folds while their mutual arrangement is uncertain. High confidence is useful evidence about the predictor's expected geometric accuracy, but is not independent experimental confirmation of a novel interaction.[ref]
Highly accurate protein structure prediction with AlphaFold by John Jumper and others. Methods and Supplementary Methods, predicted confidence measures
The different experimental methods answer complementary questions. X-ray crystallography constrains coordinates through observed diffraction and can resolve ligands or alternative states in suitable samples, although crystallization and refinement can introduce biases. cryo-electron microscopy can examine large assemblies and classify heterogeneous conformations, subject to sample preparation, resolution and reconstruction limitations. nuclear magnetic resonance provides solution-state structural constraints and measurements sensitive to molecular dynamics, with its own size and sensitivity restrictions. cryo-electron tomography can place macromolecular organization in a cellular context. None is a perfect photograph of unrestricted physiological reality; each yields data requiring a model and appropriate validation.
The practical relationship is increasingly reciprocal. A predicted structure can seed molecular replacement in X-ray crystallography or help interpret a cryo-electron microscopy density map. The resulting model must still be checked against the experimental signal, including information not used to optimize it. Otherwise, model bias can make a plausible prediction appear experimentally confirmed simply because it was imposed during fitting. Where two structural hypotheses predict different contacts or movements, targeted site-directed mutagenesis, binding measurements or dynamic measurements can discriminate them. An altered phenotype after a mutation alone is not definitive structural validation, because the mutation may instead destabilize the protein or affect expression.
Experiments also underpin evaluation of the predictor itself. Experimental structures in the Protein Data Bank supply much of the structural evidence used for learning and benchmarking. Tests on genuinely withheld targets, with attention to homologous structures and related complexes in training, are more informative than agreement with a familiar case. Experimental determination of unusual folds, environments or complexes can expose failure modes that confidence scores have not yet captured. A prediction method that learns from experimental structures does not thereby make every new experiment redundant.
The justified conclusion is a change in the allocation of effort. Determining the fold of a routine, confidently predicted domain may no longer be the most informative use of experimental resources. Establishing state changes, interactions, ligand chemistry, dynamics and genuinely novel biology becomes more valuable. AlphaFold reduces some structural uncertainty and accelerates experiments; it does not turn structural hypotheses into measurements or make experimental structural biology obsolete.
A simple model is especially valuable when it overturns a clearly stated expectation and explains why, but surprise is a means to understanding rather than a requirement that every useful model be counterintuitive. The expectation must be explicit enough to test, and the model should identify which assumptions make it fail. A surprising simulation without a mechanism or a plausible connection to observations is not sufficient.
One expectation is that a deterministic system with few variables must settle to a simple, predictable state. The logistic map,provides a compact counterexample. Its positive fixed point is , and the derivative there is . Thus the fixed point is locally stable for ; changing a single parameter can destroy that stability. At , repeated iteration approaches a two-cycle near and . For typical initial conditions at , the Lyapunov exponent is , so nearby initial states separate exponentially on average until the bounded state space limits their separation. Robert M. May's analysis made the consequences of such simple difference equations particularly influential in population modeling.[ref]
Simple mathematical models with very complicated dynamics by Robert M. May. pp. 459–467, first-order maps, stability changes and complex dynamics
The broken expectation is not that determinism is false: the rule remains deterministic. Rather, an irregular trajectory need not be caused by a complicated mechanism or external stochasticity, and exact rules need not permit long-range prediction from imperfectly measured initial conditions. This does not show that every irregular population time series is chaotic. Real populations may experience demographic noise, environmental variation or overlapping generations, and the map's parameters and state must have a defensible biological interpretation. Evidence should distinguish those alternatives. Even within the mathematical example, special initial states can be periodic; the claim about concerns typical trajectories, not every point of the interval.
A second expectation is that diffusion can only erase spatial variation. In a coupled reaction-diffusion equation,diffusion smooths each species separately, yet can destabilize their coupled uniform equilibrium. Linearizing about that equilibrium gives the mode matrix . Local stability of therefore does not by itself imply stability of every spatial mode. This is the organizing insight of the Turing instability.[ref]
The chemical basis of morphogenesis by Alan Turing. §§6–9, instabilities of homogeneous reaction-diffusion systems
For a concrete dimensionless linearization, takeThe well-mixed system has trace and determinant , so its perturbations decay. Writing , the spatial mode has trace and determinantThis determinant is negative for , creating one positive eigenvalue and a growing nonuniform mode. Equal diffusivities would instead shift both eigenvalues left and could not create this two-species instability. On a finite domain, at least one of the modes allowed by the boundary conditions must lie in the unstable band. The algebra exposes exactly why the intuition about smoothing fails: differential transport changes the balance of an interacting local system.
A Turing instability establishes a possible pattern-generating mechanism, not proof that a particular animal's markings use it. One must identify candidate interacting species, measure transport and response properties, and test perturbations that alter the predicted wavelength or stability. The linear example specifies onset only; nonlinear dynamics determine whether growth saturates into a stable pattern. Its value is to convert a vague statement about morphogenesis into discriminating questions, while leaving those experimental obligations visible.
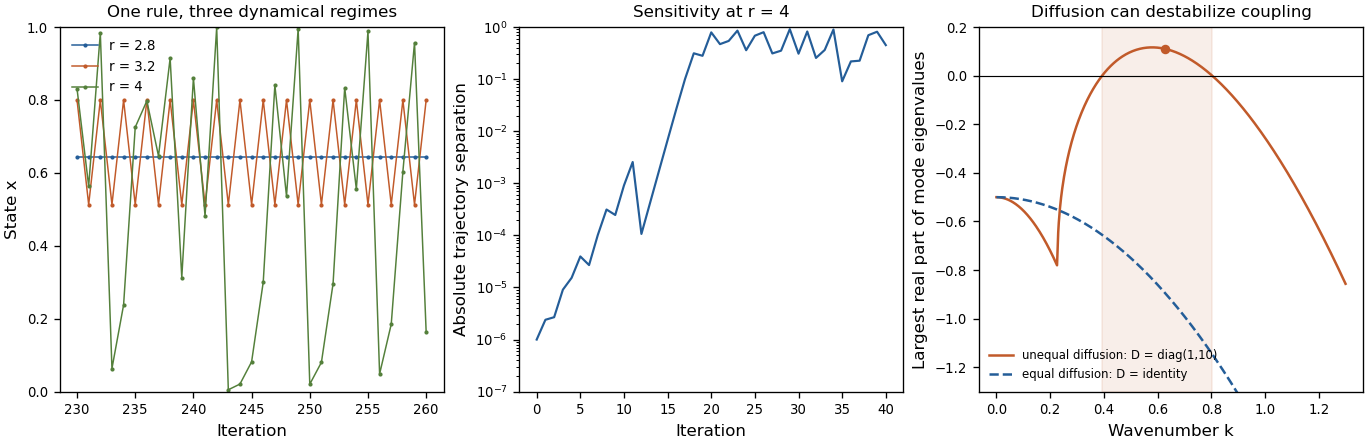
Original mathematical illustrations of changing logistic-map dynamics, sensitivity to initial conditions and diffusion-driven instability
. Details. 
A third expectation is that an infection with a basic reproduction number above one must produce a major outbreak. Consider the early phase as a continuous-time branching process, with independent per-infective transmission rate and recovery rate , while susceptible depletion is negligible. If is the probability of eventual extinction starting from one infective, conditioning on the first event givesTaking the smallest solution in yields when , and when . Thus still gives an early-lineage extinction probability of . A deterministic SIR model describes mean-field growth but omits this individual realization uncertainty. In a finite closed stochastic SIR model, every epidemic eventually ends; the branching calculation concerns early extinction before substantial susceptible depletion, not that eventual end or an arbitrary peak-size cutoff.
These examples show different benefits of simplicity: a stability calculation can separate predictable from sensitive dynamics, a mode calculation can uncover a new mechanism, and a probability recursion can expose what an average trajectory hides. The same discipline also explains why the word “should” needs qualification. A simple exponential-decay model that confirms a familiar expectation can still calibrate a rate, serve as a control, or expose a faulty measurement. A useful mathematical model must earn its simplifications through the question it answers. Breaking an expectation is a powerful route to discovery when the contradiction is precise, robust to reasonable assumptions and experimentally consequential; novelty alone is not a validation criterion.
network resilience depends on which function must persist, which disturbances are applied and how the network responds over time. Local interaction motifs, global architecture and physical operating constraints can protect different properties, often with tradeoffs. A graph that remains connected is not necessarily a functioning regulatory system, and a system that changes its output during a stimulus has not necessarily failed.
It helps to distinguish network robustness, meaning persistence of a specified property under perturbation, from network resilience, which also considers recovery after a disturbance. Relevant performance measures include the maintained output, transient deviation, recovery time, surviving connected component, transport capacity and cost. Disturbances can be brief or persistent, small or destructive, random or targeted, independent or correlated. Consequently, resilience is not one scalar attribute that can be read off a degree distribution.
At the local scale, negative feedback can oppose fluctuations, while network redundancy can provide an alternative route when one component fails. A feed-forward loop can filter stimuli by duration, and positive feedback can stabilize a switched state through bistability. These roles are conditional: a switch that remembers a transient signal can be useful in a developmental decision but undesirable in a homeostatic controller. feedback delay or excessive gain can destabilize a corrective loop; redundancy does little against a disturbance shared by every supposedly independent backup. One must analyze the signs, strengths, kinetics and operating ranges of the interactions, not just count motifs.
Bacterial chemotaxis supplies a concrete cellular example. In Escherichia coli, an attractant change affects receptor-associated kinase activity and hence downstream phosphorylation controlling swimming behavior. Slower receptor methylation and demethylation provide a feedback memory of the stimulus. In an appropriate operating range, the output responds transiently but approximately returns to its earlier level even while the new stimulus persists: robust perfect adaptation. This preserves sensitivity to subsequent changes rather than holding the entire molecular state fixed. The control interpretation identifies conditions under which adaptation does not require precise tuning of every reaction constant.[ref]
Robust perfect adaptation in bacterial chemotaxis through integral feedback control by Tau-Mu Yi and others. model analysis and Discussion, structural integral control and its assumptions
The essential logic can be isolated without pretending to reproduce every reaction. If is the output and an internal controller state, supposeWhenever the closed system reaches a stable steady state with an unsaturated integrator, forces . The controller accumulates the error, so a constant disturbance need not leave a persistent output offset. This is integral action. The equation demonstrates the mechanism, not an unconditional guarantee: the surrounding feedback must be stable, the required control action must be attainable, and the effective set point must remain meaningful under the parameter changes considered.
The example also clarifies what is and is not robust. Returning kinase activity to a set point does not imply an unchanged response time, noise level or swimming trajectory. Strong or sustained stimuli can exhaust the receptor's modification range; deleting an essential feedback component can remove adaptation; correlated changes in controller parameters can shift its set point. Cellular resilience therefore combines biochemical organization with finite resource and timescale constraints. A useful experiment measures the response and recovery after stimuli of different amplitudes, while independently perturbing feedback components, rather than inferring perfect adaptation from one endpoint measurement.
At the global scale, several architectural features matter. Alternative paths and disjoint routes reduce dependence on one component. network modularity can confine damage, although inter-module bridges may then become critical bottlenecks. Short paths improve communication but may also permit rapid spread of a disturbance. Highly connected hubs can support efficient coordination while concentrating vulnerability. Directed links, edge weights and capacities change which routes are usable; a path in an unweighted undirected projection need not carry a signal or the required load in the real system.
The Internet illustrates these distinctions for a real-world network. Nodes can represent routers or autonomous systems, with edges representing different kinds of connectivity; conclusions should state the chosen resolution. In a heterogeneous network, random deletion is likely to hit one of many low-degree nodes, whereas targeted deletion of high-degree nodes can disrupt a large fraction of the remaining paths. The classic attack-tolerance study demonstrated this contrast in model networks and mapped communication networks.[ref]
Error and attack tolerance of complex networks by Réka Albert and others. Figures 1–3, random failures versus targeted removal and network fragmentation
Its lesson is a vulnerability conditional on the topology and attack rule, not that every network with an apparent power-law tail is invulnerable to arbitrary failures.Actual Internet resilience also uses routing protocols, spare capacity, replicated services and operational recovery. Those are dynamical and engineering mechanisms additional to the static graph. Removing a node may reroute traffic through surviving links and overload them; failures can then cascade even while many topological paths remain. Conversely, route recomputation may restore service after an initially severe disruption. cascading failure therefore requires a load and dependency model, while geographically correlated failures require an account of shared physical infrastructure. Maintaining connectivity, throughput and low latency are different objectives.
The cellular and communication examples share a design principle but not a single universal architecture. A local controller can reject a persistent input error; a global alternative route can bypass a failed connection. Neither guarantees protection against every perturbation, and both incur costs in energy, components or spare capacity. A sound comparison specifies the disturbance ensemble, the measured function, the recovery interval and the intervention used to test the mechanism. Resilience is produced by matched topology and dynamics, and protection against one class of stimulus can create vulnerability to another.
Software defects can make a scientific result wrong even when another researcher reproduces it exactly. Reducing their impact requires both a traceable computational workflow and independent checks that its implementation and scientific assumptions are appropriate.
Terminology should be stated because usage varies. Here, computational reproducibility means obtaining consistent results from the same data and recorded computational procedure; scientific replication means testing the finding with newly collected data or an independently conducted study. model verification asks whether the code implements the intended equations and rules. model validation asks whether those equations and rules are adequate for the scientific use. A result can pass the first two computational checks and still fail biological validation. Conversely, floating-point differences between platforms need not invalidate a conclusion if they lie within a justified numerical or statistical tolerance.
A software bug can enter at every stage. A sample-order mismatch may associate measurements with the wrong labels while retaining plausible matrix dimensions. An indexing or sign error can reverse a treatment contrast. Unit conversion errors can alter a kinetic rate by orders of magnitude. A mistaken stopping rule can report an optimizer's initial value as its solution. A preprocessing script can leak test-set information into training and exaggerate predictive accuracy. These failures are dangerous because an apparently reasonable plot and a successful program exit are weak tests of correctness.
Data handling provides a documented biological example. Spreadsheet defaults can coerce identifiers into dates or numbers: historical gene symbols such as SEPT2 and MARCH1 are examples of this problem. A survey found such conversions in published supplementary gene lists, demonstrating that silent changes can propagate beyond the originating analysis.[ref]
Gene name errors are widespread in the scientific literature by Mark Ziemann and others. Abstract; examples of gene-symbol conversion and manual verification of affected supplementary files
Automatic conversion may be intended spreadsheet behavior, but it becomes a defect in an analysis that requires exact textual identifiers. Specifying identifier columns as strings, preserving stable accessions, checking uniqueness and matching against an expected identifier set directly address that failure mode.A second example distinguishes coding errors from modeling errors. The AFNI 3dClustSim program had a defect in variance rescaling after smoothing, associated with boundary effects. Its maintainers documented the repair and assessed its consequences. Their analysis also showed why the broader problem of inflated cluster-inference false positives could not be attributed to that defect alone: assumptions about spatial autocorrelation and the inferential procedure mattered as well.[ref]
FMRI Clustering in AFNI: False-Positive Rates Redux by Robert W. Cox and others. Results, “The past, I: 3dClustSim, and ‘The Bug’”; Discussion, effect of the correction
Thus correcting an implementation is necessary but does not automatically validate the statistical method it implements.The first defense is a clear, inspectable specification. Write down units, array meanings, intended inputs and limiting behavior; divide a pipeline into small components with explicit interfaces. A unit test for a decay solver can compare against . An integration test should check the connection between data import, model fitting and plotting, including sample identifiers and units. regression tests preserve justified behavior after a fix, but a saved output from an unexamined older version is not an independent truth standard. Test quality matters more than the percentage of lines executed.
Exact reference answers are often unavailable, so property-based testing and metamorphic testing are valuable. A closed chemical conversion should conserve total material; a probability vector should be nonnegative and sum to one; consistently permuting independent sample rows should leave a deterministic fitted model unchanged. A valid metamorphic relation must match the problem: permuting a time series would generally destroy temporal information rather than preserve the expected result. Testing extreme inputs, empty groups and zero-rate cases often exposes bugs that ordinary examples miss. Code review and an independently written implementation can find shared blind spots that additional tests derived from the same erroneous formula cannot.[ref]
Best Practices for Scientific Computing by Greg Wilson and others. sections on modular development, testing, assertions and collaborative code review
Numerical algorithms introduce another layer. For explicit Euler integration of , the update is . The exact solution is positive and decays, but makes the discretization unstable, and even produces alternating negative values. This can be an unsuitable algorithm or step size rather than a typographical defect. Comparing step sizes, solver tolerances and alternative algorithms separates discretization error from a biological prediction. In a sensitive dynamical system, convergence of statistical summaries may be more meaningful than exact agreement of a long trajectory.
Traceability makes failures discoverable and corrections usable. version control identifies the code revision that generated a result; data provenance records raw inputs, reference annotations, filtering decisions and transformations. An executable workflow regenerates outputs from those inputs without undocumented manual edits. Dependency versions and a recorded environment, possibly a software container, reduce accidental differences between installations. A random seed should be recorded together with the generator and, where relevant, the allocation of streams to parallel workers. One seed is not an uncertainty estimate, and parallel scheduling or library changes can defeat bitwise repetition even when it is reused.
continuous integration can run focused tests whenever the analysis changes, while release notes and archived versions let readers distinguish corrected results from earlier ones. The environment archive preserves the ability to reproduce an old computation; the maintained version should also contain the scientific correction. Publishing only a container that reliably reproduces a wrong result is inadequate. When a defect is found, quantify which conclusions change, rerun affected analyses, retain a minimal reproducing example and communicate the correction through the appropriate scientific record. Reliable computational science combines reproducible execution, verified implementation, quantified numerical error and validation against evidence; none is a substitute for the others.
A predictively useful simulation of a simple multicellular organism is a plausible long-term goal, but “fully” must specify resolution, environmental conditions and the predictions to be tested. A model that reproduces selected behaviors is attainable in a different sense from an exact simulation of every molecule throughout development, physiology, reproduction and aging. The former can be evaluated scientifically; the latter is neither established by present models nor a necessary definition of success.
A useful target might be a specified developmental stage of Caenorhabditis elegans, in a controlled environment, with predictions for cell states, body movement and responses to defined perturbations. Its small size, optical accessibility and extensively mapped cell lineage make it attractive. The classic embryonic lineage study traced divisions, cell deaths and fates, while also using perturbations to investigate the role of interactions.[ref]
The embryonic cell lineage of the nematode Caenorhabditis elegans by John Sulston and others. Abstract and cell-ablation experiments, lineage description versus developmental mechanism
Such a map constrains what a simulator must reproduce, but a list of normal outcomes does not itself specify the rules that generate them or how those rules respond to an unfamiliar intervention.whole-cell modeling demonstrates both progress and the scale of the gap. A model of the bacterium Mycoplasma genitalium integrated 28 process models to connect cellular molecular functions with phenotypes, including growth, division and responses to genetic perturbation.[ref]
A whole-cell computational model predicts phenotype from genotype by Jonathan R. Karr and others. model construction, integrated cellular processes and phenotype comparisons
This is a substantial integration achievement, but it is a unicellular system with many experimentally supplied quantities and modeling assumptions. Its existence does not show that adding a collection of copies yields a validated multicellular organism. Differentiation, tissue organization, intercellular communication and mechanical interactions introduce new dependencies.At the organismal scale, OpenWorm is a concrete attempt to integrate components of a virtual Caenorhabditis elegans, including neural activity, muscle activation, body mechanics and interaction with an environment. The project's published account describes a program of integration and validation, not a claim to have completed all the animal's biology.[ref]
OpenWorm: overview and recent advances in integrative biological simulation of Caenorhabditis elegans by Gopal P. Sarma and others. project overview and constituent modeling projects
A model can produce plausible locomotion while lacking developmental regulation, feeding or reproduction. Moreover, a neural wiring diagram alone leaves synaptic strengths, channel dynamics, neuromodulation, sensory transduction and the mechanical consequences of muscle forces underdetermined. Closing the loop through body and environment is therefore essential for behavioral prediction.Several experimental developments make the goal more tractable. light-sheet fluorescence microscopy can follow living development with lower illumination of out-of-focus regions than conventional volume scanning, enabling repeated observation of cell divisions and movements, although phototoxicity and tracking errors still matter. single-cell RNA sequencing reveals heterogeneous cell states at scale; the lineage-resolved molecular atlas of Caenorhabditis elegans embryos connected transcriptional variation with known developmental ancestry.[ref]
A lineage-resolved molecular atlas of C. elegans embryogenesis at single-cell resolution by Jonathan S. Packer and others. Abstract and lineage–transcriptome analyses
spatial transcriptomics complements dissociated-cell measurements by retaining spatial context. These approaches constrain different aspects of a model rather than supply interchangeable readouts.Measurement remains incomplete. A transcript count is not an absolute protein concentration, an enzyme activity or a reaction rate. Dissociation-based measurements usually destroy the sampled organism, so a trajectory reconstructed across many cells is not direct observation of every molecular state in one living animal. Mechanical properties, metabolite fluxes and signaling dynamics require other assays. Perturbations such as controlled changes in gene activity, laser ablation or altered environmental conditions are particularly useful because they distinguish causal mechanisms that fit the same unperturbed trajectory. A sufficient validation dataset must therefore contain interventions as well as descriptions.
Computationally, multiscale modeling offers a more plausible strategy than resolving every atom. A simulator might couple gene regulatory networks inside cells to cell growth, fate transitions and movement, then to extracellular transport and tissue mechanics. For a diffusing signal, for example,while each cell updates its internal state using the local signal concentration and its contacts. Those contacts change as the tissue moves, so the regulatory and mechanical descriptions must interact. Some processes can be deterministic at high copy number, while rare molecular events may require stochastic treatment. The choice of approximation should follow the prediction and timescale, rather than one mathematical formalism being imposed everywhere.
Platforms such as PhysiCell show how agent-based modeling can couple cell-level rules for division, death and mechanics to diffusible substrates and environmental conditions. Its demonstrations establish the feasibility of useful multicellular simulations, while leaving the user responsible for biological mechanisms and calibration.[ref]
PhysiCell: An open source physics-based cell simulator for 3-D multicellular systems by Ahmadreza Ghaffarizadeh and others. Author summary and simulation examples
Data-driven approaches add another tool: scGen demonstrated prediction of some held-out cellular perturbation responses. That supports a restricted kind of generalization, not unlimited prediction of arbitrary interventions, long-term development or an entire organism.[ref]scGen predicts single-cell perturbation responses by Mohammad Lotfollahi and others. Abstract and out-of-sample perturbation evaluations
Learned components can be useful surrogates, but their training coverage and compatibility with physical constraints remain relevant.The hardest obstacles are not just processor speed. Many parameter sets can reproduce the same measurements, creating identifiability problems. Errors in initial conditions, unobserved cell states and environmental boundary conditions can propagate through coupled modules. A mechanical model can change cell contacts, thereby altering signaling, which in turn changes growth and the mechanical state. Such feedback means that validating each module in isolation is necessary but insufficient. Interfaces must preserve units, spatial meaning, material balance and appropriate timing, and their numerical coupling must be verified. A larger model can accumulate more opportunities for error without producing more reliable predictions.
A credible development program would define success before fitting. For example, predict division timing, cell positions and a movement response within stated tolerances under a panel of withheld perturbations. Calibrate on different data, compare against simpler baselines, and evaluate whether predicted uncertainty covers observed variation across animals. Use sensitivity analysis and uncertainty quantification to identify which measurements would most improve the forecast, then design interventions that discriminate between competing mechanisms. model verification establishes that the simulator follows its rules; model validation tests those rules in the claimed biological domain. Neither a convincing animation nor recovery of data used in fitting is a sufficient substitute.
My expectation is therefore incremental predictive completion at chosen resolutions: increasingly broad, experimentally constrained models of development and behavior in controlled conditions. No fundamental physical separation prevents this, but limited observability, irreducible biological variation and the cost of resolving irrelevant detail prevent a guarantee of exact individual futures. The realistic goal is a whole-organism model with a declared and expanding domain of validated predictions, not an assertion that every detail has been captured because the simulation looks alive.
Articles by others on the same topic
There are currently no matching articles.