Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Covariance
For independent standard normal random variables , define the displayed errors for . Each has mean zero and variance one. Nonadjacent errors depend on disjoint sets of independent variables. Adjacent covariances vanish because their product contains an independent centered factor. Thus their covariance matrix is .
They are nevertheless dependent: the Gaussian fourth moment gives , and hence . Constant variance and zero pairwise covariance can conceal dependence in magnitudes. This is useful when interpreting a residual plot in linear regression.
Allelic correlation 2026-10-14
For two segregating biallelic loci, encode the allele on a random population haplotype by indicator variables . Their covariance is the linkage disequilibrium coefficient . The squared correlation is , between zero and one. It measures how well one marker predicts the other and is undefined if either marker is monomorphic.
// Target: biology.bigb
For standard Cauchy distribution probability density function and , this estimates its upper-tail probability without sampling a heavy tail. The function decreases on , while increases, so their covariance is nonpositive. The paired estimator is unbiased and has no larger variance than an estimator using the same number of independent probability density function evaluations.
Antithetic variates 2026-10-14
Antithetic variates deliberately couple unbiased estimators of the same expectation with negative covariance. Their average can have smaller variance than an average using independent draws. For example, evaluating a monotone integrand at and , where has a uniform distribution, gives opposite fluctuations while preserving both marginal distributions.
For total source electrons , aperture pixels, sky-plus-dark rate , time , reads with rms , and an independent mean-background estimate of variance per pixel, the aperture variance is before additional calibration terms. The last factor is because one uncertain background mean is subtracted from all aperture pixels. Pixel correlations require covariance terms.
Approximate experimental design 2026-10-14
An approximate design is a probability measure on the design region, with weight specifying a proportion of observations at . For independent observations and common error variance , a linear regression with vector has normalized information matrix of an experimental design ; its least-squares estimator has covariance when the allocations realize these proportions. Exact designs restrict to integers.
If is stationary, then has exactly the same increments and semivariogram, but is generally nonconstant. Thus existence of a stationary covariance model for a semivariogram does not imply stationarity of every process with that semivariogram. Adding an independent random constant also leaves the semivariogram unchanged while changing the covariogram.
Autocovariance Created 2026-09-28 Updated 2026-10-14
The autocovariance measures how two observations of the same stochastic process vary together. For a real weakly stationary process of mean , it isWeak stationarity removes dependence on the absolute time . Without it, the covariance function generally needs two time arguments. Lag zero is the variance, ; symmetry of real covariance gives . Positive values favor deviations from the mean in the same direction; negative values favor opposite directions. The units are the square of the observation units. See Bartlett, lecture 2: autocovariance examples.
For example, if with centered unit-variance white noise, expanding the product leaves only matching noise times. Thus , , and for . This MA(1) has a positive lag-one autocovariance because adjacent observations share one disturbance. Rescaling every observation by multiplies every autocovariance by , while leaving autocorrelation unchanged.
The autocovariance is useful beyond comparing pairs: it determines the variance of any finite linear combination of observations. For the sample mean ,Each separation occurs in pairs. For the preceding MA(1) and , this is , compared with for four uncorrelated random variables of the same variance. This is the finite-record counterpart of the long-run variance of a stationary process.
Autocovariance of an MA(1) process Created 2026-10-07 Updated 2026-10-14
For the MA(1) , centered white noise givesOnly products of noise values with matching time indices have nonzero expectation. At lag zero there are two squared weights, and ; at lag one there is one shared noise term with weight product ; at higher lags there are none. The calculation needs zero covariance between distinct noise values, not independence. This tridiagonal finite covariance structure makes the finite-sample innovations of an MA(1) process particularly simple.
The lag-one autocorrelation can never exceed in magnitude, since . For , replacing by leaves the entire ACF unchanged. For example and both give ; rescaling the latter noise variance by also matches every autocovariance. Moving-average root reflection explains this ambiguity and why a stable invertibility convention helps identify a representation. Equality of second-order laws need not imply equality of all joint probability distributions unless the processes are Gaussian processes. See Bartlett, lecture 6: equivalent representations and covariance of ARMA processes.
For a causal autoregressive moving-average model driven by independent white noise, multiply its recursion by and take covariance. When , all driving white noise values in its moving-average term occur strictly after , so their covariances with vanish. The resulting homogeneous tail recurrence has the same characteristic roots as the autoregressive model recursion. Distinct roots of modulus below one give exponential autocovariance decay.
If measured radiative flux is and with known , first-order uncertainty propagation gives the displayed result. Independent measurements have zero covariance; strict error bounds combine differently. Even a small fractional background contribution can matter if its relative uncertainty is large. Inferring the covariance or an unknown calibration factor from precision percentages alone is unjustified.
Balanced photodetection Created 2026-10-20 Updated 2026-10-25
Subtracting two photocurrents can suppress a shared classical intensity fluctuation when the optical responses and electronic gains are matched. Independent shot noise contributions do not cancel: their variances add in the difference. With equal charge and mean currents , the independent-arrival one-sided current power spectral density is . Correlated optical inputs require their covariance as well.
Bayes' theorem Created 2026-09-24 Updated 2026-10-14
For a finite measurable partition with positive probabilities, and an event of positive probability,Its beauty is that a model predicting observations from a hidden state can also describe uncertainty about the state after an observation. Each numerator is a joint probability; the denominator, supplied by the law of total probability, makes the answers sum to one. This is a direct consequence of conditional probability, rather than an extra axiom.
Select the coin from law of total probability once, then toss that same coin repeatedly, with conditionally independent tosses given its identity. Let denote the -head coin, initially of prior probability . After one head , its posterior probability isThe likelihood of a head is larger under , but remains less likely than the other coin because its prior probability was smaller. A large likelihood for an observation does not itself imply a large posterior probability for the hypothesis.
After an ordered sequence containing heads and tails, its likelihood ratio between the two coins is . Bayes' theorem therefore gives posterior oddsEach head multiplies the odds by and each tail by . Three heads give posterior probability , still below one half; four give , above one half. The finite-model update and the distinction between prior probability, likelihood and posterior probability are set out in MIT 18.05, Reading 11: Bayesian Updating with Discrete Priors.
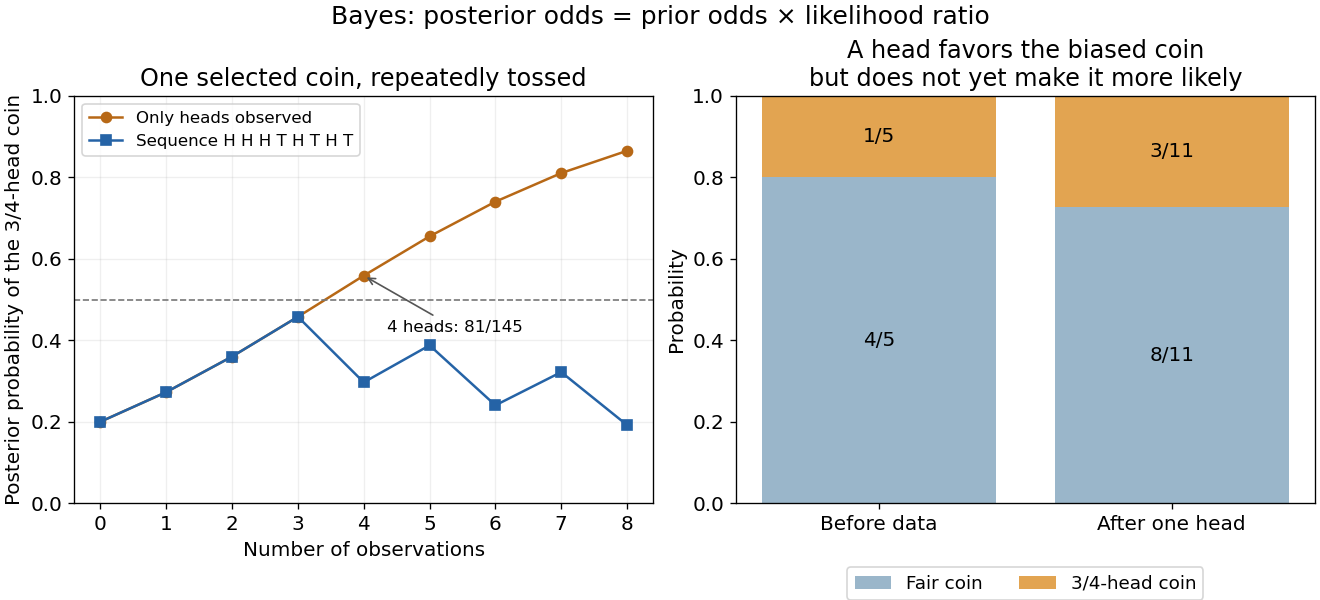
Updating uncertainty about one selected coin after repeated observations
. Details. 
The hidden selection also creates dependence. Each toss has marginal head probability , but two heads have joint probability , greater than . Their indicator covariance is . Seeing a head makes the head-favoring coin more likely, so it also raises the chance of a future head. This is covariance induced by a shared latent variable, despite conditional independence of the tosses given the coin.
Historically, Thomas Bayes's essay on an unknown success probability appeared in 1763 after his death, communicated by Richard Price. Its opening problem asks how observed successes and failures constrain that unknown probability; Price's introductory letter explains the connection to reasoning from experience. That is a more substantial inference problem than simply rearranging today's elementary identity. [ref]
https://www.gtfp.cs.rhul.ac.uk/pulskamp/Bayes/bayesessay-rjp.pdf. Bayes, An Essay towards solving a Problem in the Doctrine of Chances, 1763; original text transcribed, introductory letter and statement of the problem
Bernoulli independence from zero covariance Created 2026-10-14 Updated 2026-10-25
For two Bernoulli random variables with joint probabilities in the order , their covariance is . Zero covariance fixes the probability to the product of its marginals; subtracting this from each marginal fixes all three remaining joint probabilities to their products. Thus uncorrelated random variables taking only zero and one are independent, including degenerate marginals. The implication is special to this two-point setting and fails for general distributions.
Bessel focal length uncertainty 2026-10-14
For small measurement errors, write . Its partial derivatives and first-order propagation of uncertainty areHere the values are standard deviations used to describe uncertainty, and is the covariance. Independent carrier-reading errors give ; correlated readings require the term . Averaging repeated independent pairs reduces the random component of the uncertainty of the mean, but does not remove calibration or model errors.
As a stipulated uncertainty calculation, let , , and , with all three input errors independent. Then , , and . The result would be with this standard uncertainty in the stipulated thin lens model; these numbers are not a measured uncertainty budget. A small neglected principal-plane separation gives an additional first-order bias , distinct from that random budget.
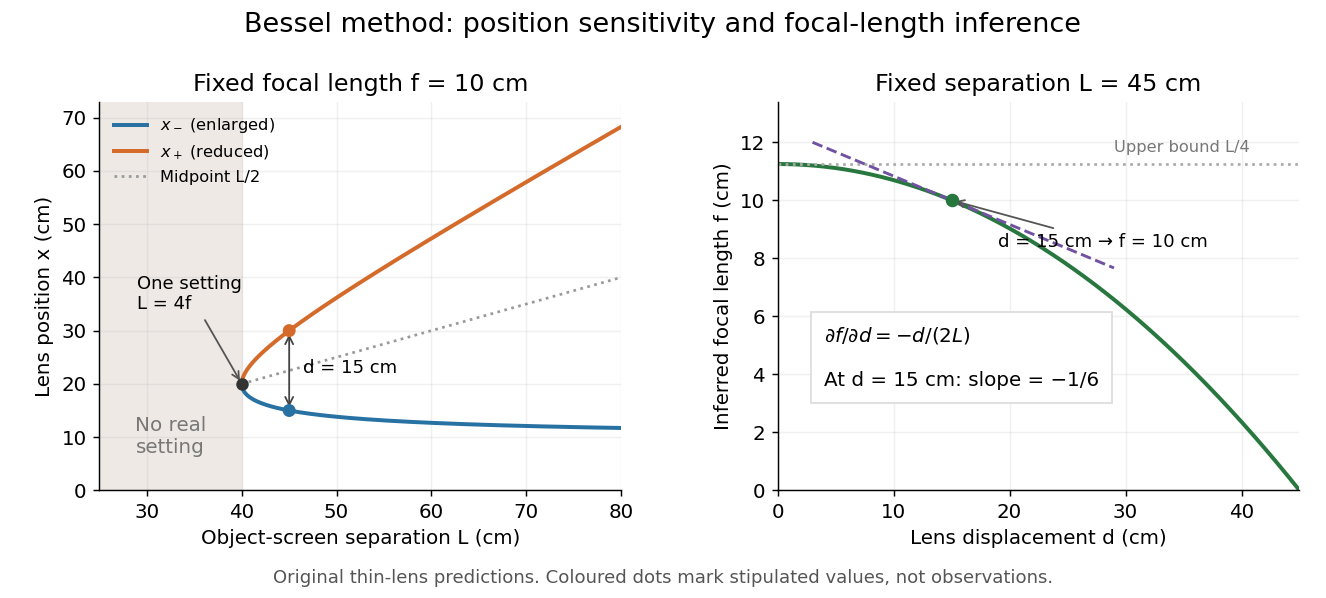
Bessel lens displacement method: merging settings and focal length sensitivity
. Original ideal-model curves. Left: settings versus object-screen separation for fixed ; below there is no real setting on the fixed screen. Right: inferred focal length versus measured displacement at fixed , with its tangent at the stipulated . The curves are predictions, not experimental points. Details.
The two kinds of sensitivity must be distinguished. At fixed focal length,These derivatives diverge as approaches from above: a small change in object-screen spacing strongly changes the separation of the two settings. Yet the inferred focal length's displacement sensitivity tends to zero. That does not make coalescing settings easy to measure. For fixed , define the axial mismatch between the predicted real image and the screen as , for . At a focused setting,Near , moving the optical lens changes this mismatch only weakly, making visual discrimination of the two settings difficult. At the example's settings and , so equal carrier motion produces different axial defocus responses. This is an axial mismatch calculation, not a full prediction of perceived image sharpness.
Choose sufficiently above to separate the two accepted focusing ranges, while retaining both real images on the available screen and rail. There is no universal best : focusing uncertainty itself depends on aperture, transverse magnification, optical aberrations and the target. Close to , the nonnegative measured separation and the quadratic term in also make first-order propagation of uncertainty unreliable if its error is comparable to its value. Repeatability, controls and the principal plane correction determine whether the elegant two-distance formula is an adequate measurement model.
Best linear unbiased estimator 2026-10-05
A best linear unbiased estimator minimizes covariance among linear estimators unbiased for the same target. In , assume , is a full-column-rank design matrix and the known covariance matrix is a positive-definite matrix. The best linear unbiased estimator of the coefficient vector is . A spatial trend estimate excludes the correlated residual prediction included in universal kriging.
For , use . Under regular regression assumptions, the delta method gives standard error , where and estimates the covariance of the regression estimate. Resample the observational units, refit, and compute both and . A percentile bootstrap confidence interval uses the .025 and .975 quantiles of . A bootstrap-t confidence interval uses quantiles of and reverses them when solving for . If both true coefficients vanish, the first derivative is zero and the standard first-order justification is unavailable; product-specific nonregular inference is then needed.
Bragg wavelength error propagation 2026-10-18
Differentiate Bragg's law at fixed correctly assigned diffraction order:Divide the second equality by the first. For small signed changes,The Bragg angle error must be in radians. An error quoted for detector deflection must first be halved. The expression is a first-order Taylor expansion; an unknown diffraction order is a discrete assignment error, not an infinitesimal perturbation.
For error bounds, add magnitudes. For independent zero-mean random errors with standard deviations , variance addition instead givesCorrelated errors require a covariance term. A shared calibration bias does not become independent merely because many line positions are measured.
With a chosen angular error arcseconds, , the angular contribution is at and at . Larger Bragg angles reduce this contribution because decreases. For a nearby spectral doublet, the inverse relation is : a fixed fractional separation spreads farther apart angularly at large Bragg angle.
This does not permit unlimited improvement. The geometry requires ; a desired wavelength might not have an accessible large-angle reflection with the chosen crystal. Higher diffraction orders can reach larger Bragg angles but their strengths depend on the crystal lattice structure factor. Finite crystal response, slit widths and source size remain relevant. An error in , including uncorrected thermal expansion, remains even when the angular term is small. Very near , the leading angular derivative vanishes and the second-order Taylor expansion matters.
Brownian bridge independence from its endpoint Created 2026-10-05 Updated 2026-10-14
For standard Brownian motion, the Brownian bridge , , is independent of . Every finite vector of bridge coordinates is jointly multivariate normal with , and its cross-covariances with vanish. The independence of uncorrelated jointly normal variables and independence extended from generating pi-systems prove independence of the whole stochastic process.
For and fixed , subtracting leaves the Brownian bridge . It is independent of , since it is independent of and has zero covariance with in their jointly Gaussian law. The observed path is determined by this bridge and its endpoint, so the bridge gives no further information about . Hence conditioning on the full observation filtration at gives the same posterior as conditioning on alone.