Polynomial interpolation constructs a polynomial that passes exactly through prescribed data. Given distinct interpolation nodes and values , there is exactly one interpolation polynomial of polynomial degree at most with for every . The values may be samples of a function, but no knowledge of that function between the interpolation nodes is needed to construct . The Lagrange polynomial and Newton polynomial are two representations of this same answer.[ref]
For example, the three data points give the quadratic polynomialThus polynomial interpolation supplies as an intermediate value. Whether this approximates an unknown underlying function well is a separate question about polynomial interpolation error.
Both hypotheses in the uniqueness statement matter. The Lagrange cardinal polynomials prove existence constructively. If two polynomials of polynomial degree at most fit the data, their difference has distinct roots of a polynomial, so it must be zero. Repeated interpolation nodes with conflicting values have no solution, and repeated equal values provide no additional independent condition; prescribed derivatives instead lead to Hermite interpolation. Without the polynomial degree restriction there are infinitely many solutions:where is any polynomial. By the factor theorem, this describes every polynomial fitting the same data. In the example, fits for every , but at its value is ; exact agreement at the three interpolation nodes alone says nothing about that intermediate value.
The usefulness of polynomial interpolation is that data become an explicit function whose values, derivatives, and integrals can be calculated. Differentiating or integrating the Lagrange cardinal polynomials produces differentiation weights from nodal evaluations or a quadrature rule. Exact passage through observations is the defining constraint. In polynomial regression, linear least squares instead chooses a polynomial degree and minimizes a sum of squared residuals, generally without passing through every observation. Interpolating noisy values reproduces their errors at the interpolation nodes and can amplify them between interpolation nodes; polynomial interpolation does not itself smooth measurement noise. A linear least squares problem with distinct interpolation nodes and polynomial degree at most does happen to attain zero residual at the same interpolation polynomial.
Suppose interpolation nodes in occur in pairs , with the middle node if is odd. For each pair,because both squared quantities lie between zero and one quarter. An unpaired middle factor has magnitude at most one half. Multiplication gives the displayed bound on the nodal polynomial.
The polynomial interpolation remainder therefore satisfies for . For , the derivative bound gives the particularly simple error bound . This proves uniform convergence for these symmetric-node interpolants of that function. It is not a general convergence theorem for arbitrary continuous interpolation data.
Let be a real continuous function on a nondegenerate compact interval and let be its best approximation among polynomials of polynomial degree at most for a positive integrable weighted inner product. Then has at least distinct zeros. Indeed, if it had at most , multiply it by the polynomial with simple zeros at precisely its interior sign changes. The product has constant nonzero sign away from finitely many zeros, so its weighted integral is nonzero, contradicting orthogonality of to all polynomials of polynomial degree at most .
For equally spaced nodes , write . The interpolating polynomial is . A table of forward differences supplies its coefficients; for a polynomial of degree at most , the formula reproduces the function exactly.
An interpolation polynomial for distinct nodes and prescribed values is a polynomial satisfying . There is a unique such polynomial of degree at most : the Lagrange interpolation polynomial constructs it explicitly, and uniqueness follows because a nonzero degree-at-most- difference cannot have distinct roots. Newton interpolation polynomials express the same object using divided differences.
For a real continuous function on a compact interval, choose its best uniform approximation of polynomial degree at most . If its error is nonzero, the Chebyshev alternation theorem supplies ordered alternating extrema. The intermediate value theorem gives a zero of in each intervening interval. At these distinct points, the polynomial interpolant is exactly . If the best error is zero, arbitrary distinct nodes suffice. The Weierstrass approximation theorem shows that these function-dependent interpolants converge uniformly. The nodes depend on the target function; the conclusion does not provide one universal node sequence for every continuous target.
An interpolation node is an argument value at which an interpolation polynomial must take a prescribed value . The interpolation nodes specify where the constraints apply; the values specify how high the graph must pass there. In the three-point example, the interpolation nodes are , while the prescribed values are . Changing the interpolation nodes changes the Lagrange cardinal polynomials and the polynomial interpolation error, even if their number stays fixed.
For , the Chebyshev-Lobatto nodes are the extrema of the Chebyshev polynomial on , including both endpoints: . Imagine equally spaced angles on a semicircle and project their points onto the horizontal axis. The interpolation nodes crowd near and because equal angular steps have smaller horizontal projections there. Reversing the order gives the same set. These are distinct from the roots of a polynomial of , which omit the endpoints. Driscoll and Braun call this endpoint-including family Chebyshev points of the second kind or Chebyshev extreme points.[ref]
https://fncbook.com/python/stability-1/. Driscoll and Braun, Fundamentals of Numerical Computation, §9.3.2, equation 9.3.2
On an interval , use . The Runge phenomenon example compares polynomial interpolation at eleven Chebyshev-Lobatto nodes with eleven equally spaced interpolation nodes. The distinction matters whenever sampling locations are a choice rather than fixed observations.
The Runge phenomenon is the failure of increasing-degree polynomial interpolation at equally spaced interpolation nodes to converge to some smooth target functions, with large oscillations near the ends of the interval. It is a property of the approximation problem, and can occur even with exact arithmetic. A numerically stable evaluation method cannot remove it. Endpoint clustering, as in Chebyshev-Lobatto nodes, changes the approximation problem and can greatly improve it.[ref]
https://fncbook.com/python/stability-1/. Driscoll and Braun, Fundamentals of Numerical Computation, §9.3.1–9.3.2
Take on and polynomial degree at most . Use either or for . Each interpolation polynomial passes through all eleven of its own samples, yet the first has severe endpoint oscillations and the second stays much closer to the target function. Evaluating both by the barycentric interpolation formula on equally spaced points, including the endpoints, gives sampled maximum absolute errors of approximately and , respectively: about a -fold reduction. These are maxima over the stated grid, not certified maxima over the continuous interval. The generator separately checks exact reproduction of all stored nodal values.
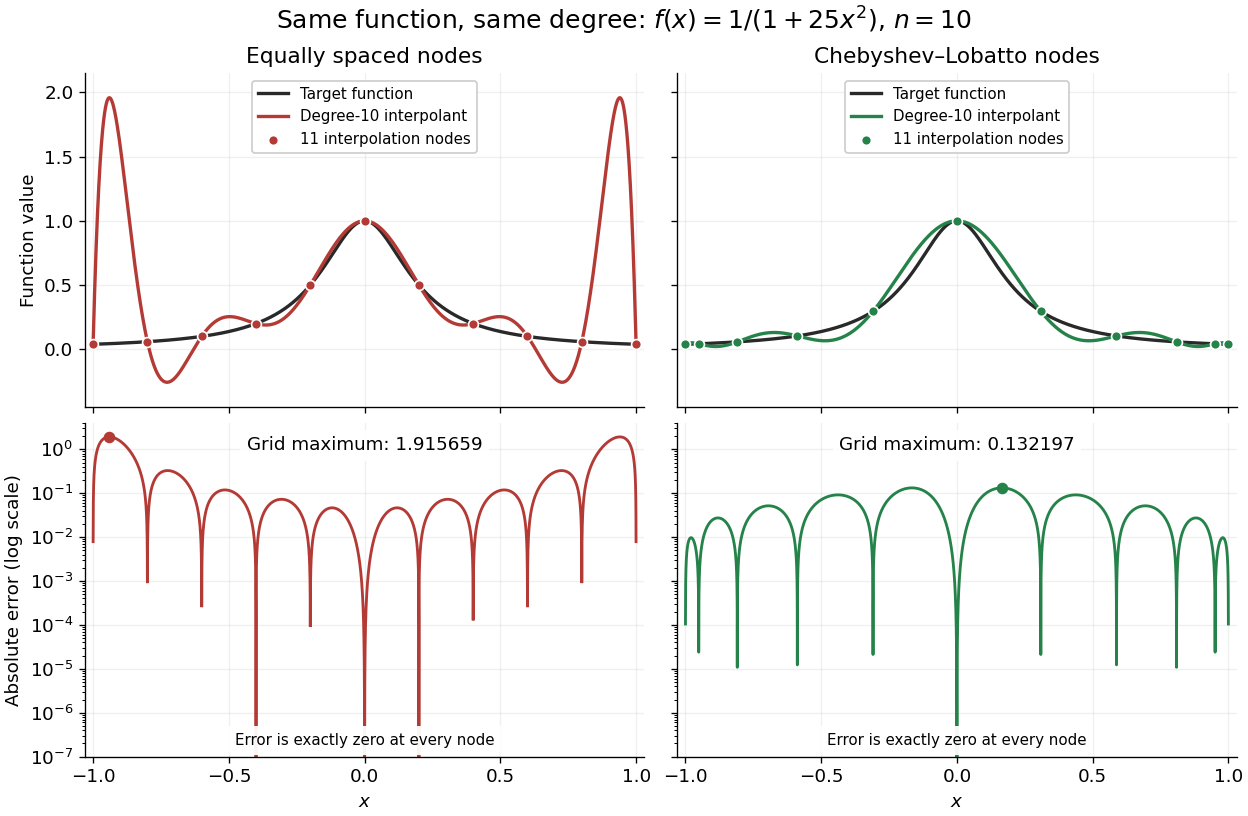
Degree-10 interpolation of the Runge function at equally spaced and Chebyshev-Lobatto nodes, with absolute errors
. Details. The polynomial interpolation error formula explains why interpolation nodes enter the analysis. If has continuous derivatives on an interval containing and all the interpolation nodes, then for a suitable in that interval,At an interpolation node the error is zero directly. Away from the interpolation nodes, both the product and the high-order derivative matter. A short proof applies Rolle's theorem repeatedly to , which vanishes at distinct points.[ref]
https://fncbook.com/polynomial/. Driscoll and Braun, Fundamentals of Numerical Computation, §9.1.2, Theorem 9.1.3
The successful comparison here does not assert that Chebyshev-Lobatto nodes solve every approximation problem for every function. The derivatives, the polynomial degree, and measurement errors still matter. The Lebesgue constant of interpolation measures worst-case amplification of nodal errors, while the polynomial reproduction error bound relates interpolation to the best uniform approximation available at that polynomial degree.
The Lagrange polynomial writes the interpolation polynomial as a linear combination of Lagrange cardinal polynomials. Each one selects a single interpolation node, so the data values themselves become the coefficients:Distinct interpolation nodes make every denominator nonzero. At , all terms vanish except . This gives an explicit construction without solving for monomial coefficients. The elegance of the Lagrange polynomial is that it builds all constraints into the basis, leaving no equations to solve for the data values.
For and , substitution givesAt , the Lagrange cardinal polynomial values are , so . A negative Lagrange cardinal polynomial value is allowed: these weights sum to one but need not be probabilities.
The product form is especially useful for deriving differentiation weights from nodal evaluations and quadrature rules. For repeated numerical evaluation, the barycentric interpolation formula reorganizes the same Lagrange polynomial into precomputed weights and sums; it avoids evaluating every full product at every argument.
For distinct interpolation nodes and an integer ,To prove this, the Lagrange interpolation polynomial for the data is exactly , by uniqueness of polynomial interpolation. The coefficient of in its th Lagrange cardinal polynomial is . Comparing the coefficients of gives the identity. At , values of the constant polynomial are intended even at a zero node. Negative exponents are outside the assertion.
At distinct nodes , the Lagrange interpolation polynomial has basis . Differentiating its exact expression for a polynomial of degree at most gives the displayed weights. Their uniqueness follows because the nodal evaluations form a basis of the dual space of that polynomial space.
For increasingly ordered nodes , let be their Lagrange cardinal polynomials, , and . The leading coefficient of has sign , so all summands in the leading coefficient of have the same nonzero sign. There is a unique canceling degree in . Its errors at the nodes are , and a better degree-at-most- approximation would have a difference polynomial with at least roots. Thus it minimizes the maximum node error. Increasing order matters: for the permutation the alternating interpolant is already the quadratic , so the leading-coefficient assertion for fails.
For distinct interpolation nodes , the Lagrange cardinal polynomial has value one at its own interpolation node and zero at every other interpolation node:Here is the Kronecker delta. These Lagrange cardinal polynomials form a basis of the vector space of polynomials of polynomial degree at most : every such polynomial has the unique expansion . The nodal evaluation linear functionals form the dual basis, since .
For the interpolation nodes , the three Lagrange cardinal polynomials areTheir values on the interpolation nodes are the rows of the identity matrix. In the figure, each colored curve passes through its own unit-height marker and through zero at the other two interpolation nodes. Multiplying the curves by the data and adding gives the Lagrange polynomial .
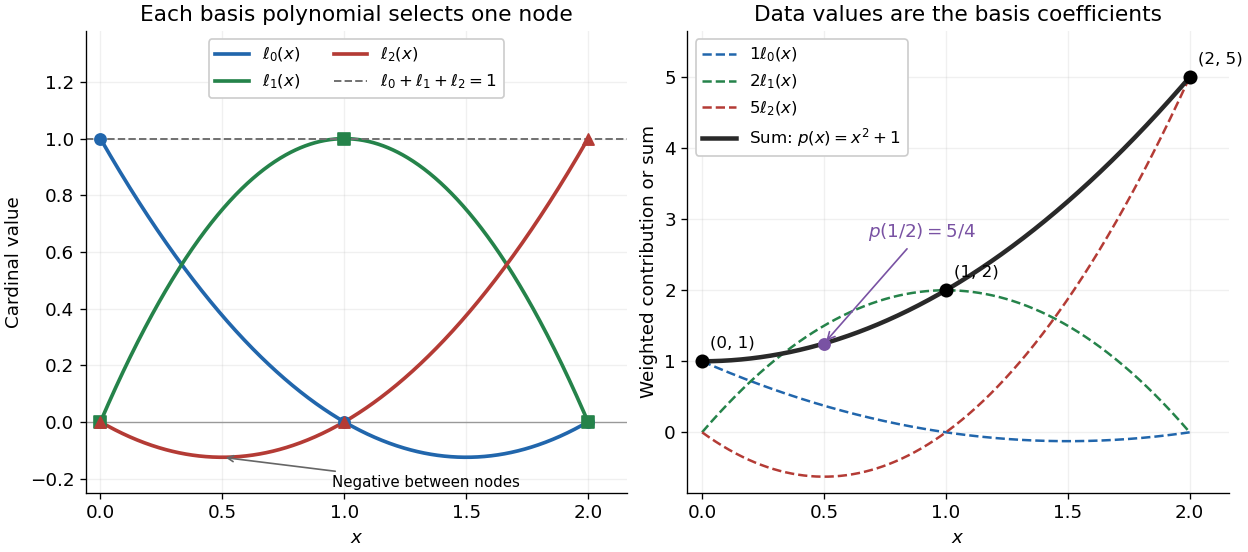
Since the constant polynomial one interpolates data values all equal to one, uniqueness gives . Nevertheless, , so Lagrange cardinal polynomials need not stay between zero and one. If a single data value changes by , the interpolation polynomial changes by exactly . Thus a Lagrange cardinal polynomial describes how one observation influences the entire graph, and controls the worst amplification of simultaneous data errors at ; its maximum is the Lebesgue constant of interpolation.
At decreasing distinct interpolation nodes , the Lagrange cardinal polynomial has denominator sign . For , its numerator's th derivative at one is times a sum of products of nonnegative factors . At most one factor vanishes, and at least one product avoids it, so that sum is strictly positive. The same alternating nodal signs therefore maximize every endpoint derivative simultaneously.
At distinct interpolation nodes, differentiating Lagrange interpolation gives . The triangle inequality gives the displayed upper bound, attained by prescribing each nodal value to be the sign of the corresponding derivative weight. For increasingly ordered real nodes, the Markov interlacing lemma and monotonicity of polynomial critical points in their roots imply that has at most one sign change, ignoring zero weights. Thus an extremizer has alternating nodal signs with at most one reversal of that alternating pattern. This reduces a choice among sign patterns to candidate polynomials.
The barycentric interpolation formula evaluates the same Lagrange polynomial using weights that depend only on the distinct interpolation nodes:At , return directly, before dividing; the formula has removable singularities at the interpolation nodes. Multiplying every by the same nonzero constant leaves the answer unchanged. Driscoll and Braun derive this formula as a more efficient, numerically stable way to evaluate polynomial interpolation.[ref]
For the interpolation nodes , the weights are , or equivalently . With data , at the denominator using the latter weights is and the numerator is , giving again. For eleven interpolation nodes in the Runge phenomenon figure, the generator computes the weights by the direct products above and returns stored values exactly at every interpolation node.
The direct products require arithmetic operations once; each subsequent value uses arithmetic operations. Here denotes Big O notation. At large polynomial degree or on poorly scaled intervals, forming these products can exceed the range of floating-point arithmetic; normalization or specialized weight formulas may be needed. Stable evaluation also cannot cure sensitivity intrinsic to the chosen interpolation nodes, measured by the Lebesgue constant of interpolation, or the approximation failure in the Runge phenomenon.
For distinct interpolation nodes, the divided difference is the coefficient of in the interpolation polynomial of polynomial degree at most through those interpolation nodes. It is the leading coefficient when that polynomial degree is exactly , and zero when it is smaller. Explicitly,starting with . The divided differences obey the recurrenceFor data , , , the first divided differences are and . The second divided difference is , the leading coefficient of . The first divided difference is the slope of a secant line; higher divided differences supply successive coefficients for the Newton polynomial.
A divided difference table arranges divided differences by starting interpolation node and order . Its base column is ; every later entry uses two neighboring entries from the previous column:The denominator spans all interpolation nodes of that entry, even though the numerator uses adjacent table entries. The interpolation nodes must be distinct; they need not be equally spaced or sorted.[ref]
3.3 Interpolation. NIST Digital Library of Mathematical Functions; §3.3(iii), equation 3.3.34: initial values and divided-difference recurrence for distinct nodes
Take the polynomial at the interpolation nodes , giving values . Its divided difference table isThe first divided differences are , , and . The second divided differences use the wider spans: and . The third divided difference is . Reading the top row gives the Newton polynomial coefficients , rather than all the entries in any one column.
The resulting Newton polynomial grows through four partial interpolants:At , misses by ; the correction supplies exactly there and vanishes at the earlier interpolation nodes . At , misses by ; the correction supplies exactly there and vanishes at all three earlier interpolation nodes. Each added term therefore preserves the previous agreements while satisfying the next one.
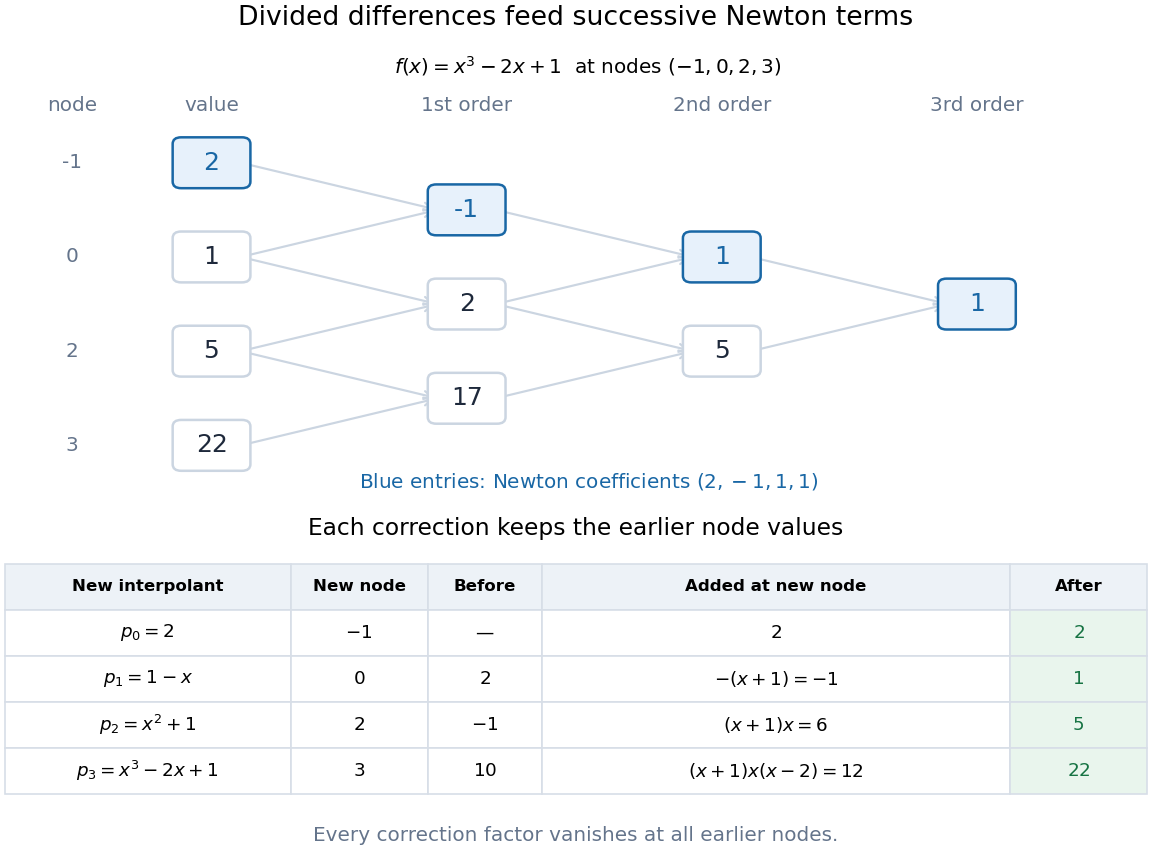
Divided-difference triangle and successive Newton interpolants for the constructed polynomial x cubed minus 2x plus 1
. Details. For interpolation nodes, the triangle contains recurrence steps. Once the top row is known, nested evaluation of the Newton polynomial uses only multiplications and additions per argument. The triangle organizes the work; the factors explain why the construction works.
A divided difference depends on the chosen interpolation nodes and their data, but is unchanged by any permutation of those same interpolation nodes. The explicit sum in divided difference makes this visible: a permutation merely rearranges its summands.[ref]
There is also a short explanation using Lagrange cardinal polynomials. The coefficient of in the th Lagrange cardinal polynomial is . Taking that coefficient in their weighted sum gives exactly the explicit divided difference formula. Since polynomial interpolation has a unique answer for a fixed set of distinct interpolation nodes, this coefficient cannot depend on their ordering. If the interpolation polynomial has polynomial degree below , the coefficient is zero.
For the four-point example in divided difference table, every ordering gives third divided difference . This does not make every Newton polynomial coefficient invariant: whereas , because these use different pairs of interpolation nodes. Even at second order, and use different triples. The node order in Newton interpolation determines which subsets occur along the top row.
For distinct interpolation nodes, write for the divided difference with omitted. Symmetry and the divided-difference recurrence give the displayed identity. Consequently, for ,The identity is algebraic and does not require the nodes to be ordered; the coefficients need not be nonnegative.
The displayed integral is for distinct exponents and when they coincide. The latter is the continuous limit, so a zero denominator is a removable singularity. This quantity appears in variation-of-constants formula estimates of matrix evolution and avoids omitting an equal-exponent case.
For ,
The Newton polynomial expresses the interpolation polynomial in products that successively vanish at all previously used interpolation nodes. With , the coefficients are divided differences:A triangular divided difference table computes all its coefficients using exactly divisions. The Newton polynomial and the Lagrange polynomial have the same polynomial degree bound and the same nodal values, hence are equal by uniqueness of polynomial interpolation.
For , , , the complete divided difference table isThe first divided differences are and , and their divided difference is . Reading the top entries givesThe initial term fits ; adding also fits ; adding fits while leaving the first two data values unchanged. This is the practical beauty of the Newton polynomial: each new correction respects all previous interpolation constraints.
If a new distinct interpolation node with value arrives, append one term:For example, appending to the three-point data gives , hence . Changing the order of the interpolation nodes changes the Newton polynomial coefficients and products, but not the final interpolation polynomial in exact arithmetic.
The products also permit nested evaluation analogous to Horner's method. If , start with and work backwards by ; the answer is . The three-point example becomes , needing two multiplications for each evaluation. This organization is useful when adding observations incrementally or evaluating a stored Newton polynomial many times; the Runge phenomenon still depends on the interpolation nodes rather than on which representation is used.
To justify the update formula, its added product vanishes at every previous interpolation node. Choosing by the new residual forces agreement at , so uniqueness of polynomial interpolation identifies the result. For , has polynomial degree at most , and the added product has leading coefficient one. Thus the new coefficient is exactly . The initial state is , with the empty product interpreted as one.[ref]
Appending to the four-point example in divided difference table leaves the Newton polynomial unchanged: , so the new fourth divided difference is zero. If the appended value is instead , the new coefficient isThis polynomial still takes values at the original interpolation nodes, and now takes value at . A zero update is a valid completed step: adding another exact sample of the original polynomial need not increase the polynomial degree.
Reordering the interpolation nodes changes the successive subsets used for the divided differences and the factors of the Newton polynomial. The final interpolation polynomial remains unchanged in exact arithmetic. For , reversing gives and values . The successive divided difference columns are nowFor example, the first second divided difference is . The top row becomes , givingThe earlier partial interpolants differ because they fit different subsets: fits , whereas fits . The highest divided difference is invariant because both complete top rows finish with the same set of four interpolation nodes; this is symmetry of divided differences.
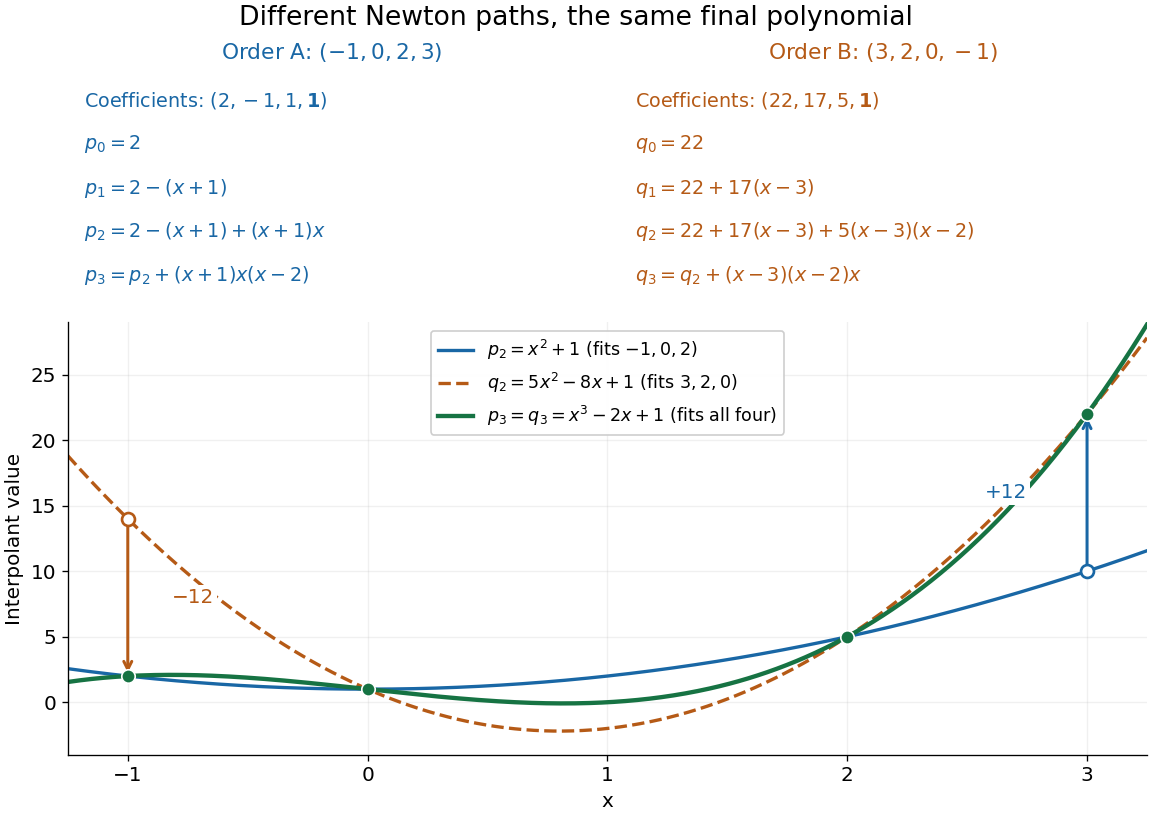
Reversing the interpolation nodes changes the Newton construction but gives the same final polynomial
. Details. This distinction is useful when checking a divided difference table: permuting all the interpolation nodes must preserve its final divided difference, even though the intermediate entries change. It also explains why data can be appended in their arrival order. In floating-point arithmetic, the subtractions and divisions may accumulate different rounding errors in different orders; exact invariance describes the mathematical polynomial, rather than guaranteeing bit-for-bit equality of numerical results.
Articles by others on the same topic



Polynomial interpolation is a mathematical method used to estimate or approximate a polynomial function that passes through a given set of data points.