A tree is a nonempty connected graph containing no graph cycle. Think of seven locations joined so that everyone can reach everyone else, but no connection supplies an alternative route. For a finite simple graph with vertices, three descriptions are equivalent: being a tree; having exactly one simple graph path between every pair of distinct vertices; and being a connected graph with exactly edges. Here a simple graph path repeats no vertex. Connectedness in the last description is essential. [ref]
https://www.maths.tcd.ie/~dwilkins/Courses/MA2C03/MA2C03Courseware_2014to15/MA2C03_S4_Yr1415.pdf. Trinity College Dublin, graph theory notes, Theorems 4.24–4.26 and Corollary 4.27
For a concrete tree, label the vertices and take the edgeswhere abbreviates the unordered pair . There are seven vertices and six edges. The unique graph path from to is , using five edges. The degree sequence in label order is : its sum is , as the degree-sum formula predicts. Each of is a leaf of a graph, having vertex degree one.
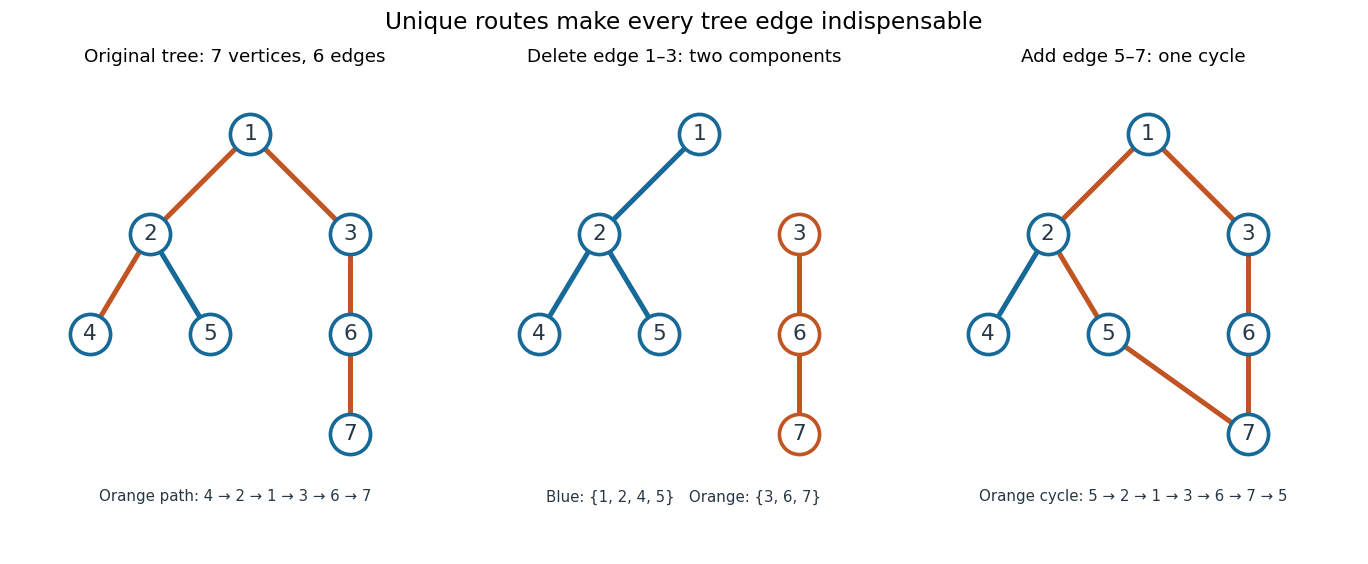
A seven-vertex tree: one graph path, two connected components of a graph after deletion, and one graph cycle after insertion
. Details. Deleting edge leaves precisely two connected components of a graph, on and . Every edge of a tree is a bridge in a graph. Instead add edge to the original tree: it closes the unique existing graph path into exactly one graph cycle. Thus a tree provides economical connections with no redundancy: a single failed link separates locations. Every finite tree with at least two vertices has at least two instances of a leaf of a graph; the endpoints of a longest graph path supply them. [ref]
https://www.mathstat.dal.ca/~janssen/2113/notes/class14/. Dalhousie University, Trees: leaves and indispensable edges
The number alone proves nothing about connectedness: a cycle graph on together with an isolated vertex has seven vertices and six edges, yet is disconnected. Briefly, two different simple graph paths between the same vertices would contain a graph cycle. Repeatedly removing a leaf of a graph and its incident edge proves the tree count by mathematical induction, starting with one vertex and no edges.
A nonempty connected subgraph of a tree. Between any two included vertices, it contains the unique tree path: its connectedness supplies a path, and the ambient tree has only one. Such subgraphs satisfy the Helly property. They need not contain every descendant of an included vertex in any chosen rooting, unlike the descendant-closed data-structure subtree convention.
A finite family of nonempty connected subgraphs of a tree with pairwise nonempty intersections has a common vertex. For a finite ambient tree, prove this by deleting a leaf of a tree . If one member is , pairwise intersection proves the result immediately. Otherwise remove from every member containing it. Each such member remains nonempty and connected and contains the unique neighbour of . Hence every pair still intersects, even if its original intersection consisted only of , and mathematical induction applies. This is the Helly property specialized to trees.
A tree together with an embedding in an oriented plane, considered up to deformation preserving the cyclic order of incident edges. For a rooted plane tree, the embedding orders the children of each vertex.
A plane tree with a distinguished root and root corner, equivalently a rooted tree with a linear order on the children at each vertex. Trees with edges are counted by the Catalan number .
The dissymmetry theorem for trees relates unrooted trees to trees rooted at a vertex, at an edge, and at a directed edge. In the corresponding counting identity, unrooted equals vertex-rooted plus edge-rooted minus directed-edge-rooted.
A tree whose vertices carry distinct labels from a fixed finite set, as a labelled combinatorial structure. Two labelled trees on the same vertex set are equal when their sets of edges are equal: any comparison must keep every label fixed. Cayley's formula counts these trees.
A tree considered up to graph isomorphism, with vertex names ignored. For example, all four labelled trees that are star graphs on represent one unlabelled tree. Dividing the total in Cayley's formula by does not count unlabelled trees: different shapes can have different numbers of distinct labellings.
An infinite connected tree is regular of degree if every vertex has exactly neighbours. Necessarily . For it is a two-sided infinite path. For , rooting it gives children at the root and children at each other vertex; this constructs the unique such tree up to graph isomorphism.
For a nonempty finite vertex set in a degree- regular tree, its induced forest has edges, where counts its components. Summing degrees and subtracting twice the internal edge count gives the displayed number of edges with exactly one endpoint in . In particular it is at least .
An oriented tree is an orientation of every edge of an undirected tree. Its arrows need not all point towards, or away from, any one root. It is acyclic as a directed graph, but different orientations can have different embedding behaviour in tournaments.
For a source-rooted oriented tree, let count edges pointing towards the root and let count nonempty connected components formed by those edges. A half-sparse median-order embedding exists in vertices. Remove forward leaves, or remove a terminal backward component of order and replace it temporarily by outward leaves. Their images contain an in-arborescence copy of the component. Choose the direction and root to minimize lexicographically; this makes the root a source and gives unless the tree is already an arborescence. The stated bound follows.
An arborescence is a rooted oriented tree whose edges all point away from its root. Reversing every edge gives an in-arborescence. An -vertex arborescence embeds in every tournament on vertices: repeatedly extend an outward leaf in a half-sparse median-order embedding. Reversal gives the analogous existence statement for in-arborescences.
A depth-first traversal starts at a root, recursively visits each child subtree, and returns along the entering edge. On a finite tree, the resulting closed walk traverses each edge exactly once in each direction.
Visit all child subtrees before visiting their parent. A depth-first traversal of a tree produces this order by processing a node on return from its recursive calls. It lets dynamic programming use the already computed answers of every child subtree.
Visit a rooted tree's root before recursively visiting its child subtrees in their specified order. For a binary tree, the order is root, left subtree, right subtree. Unlike inorder traversal, this interpretation stores an internal node's label before either child's labels.
A rooted tree is a tree with a distinguished vertex, its root of a tree . Choosing turns connections into a hierarchy: every other vertex has a unique parent in a rooted tree, the preceding vertex on its graph path from . Conversely, the vertices whose parent in a rooted tree is are the children in a rooted tree of . Choosing the root of a tree changes this description, while the underlying edges remain the same. Arrows towards the root of a tree can encode the relationship, as in MIT's counting notes; the undirected tree itself needs no arrows. [ref]
In the seven-vertex tree above, choose . The levels, grouped by graph distance from the root of a tree, are , , , . The children in a rooted tree of are , and the parent in a rooted tree of is . Choosing instead makes the levels , , , , , : now has parent in a rooted tree , reversing their relationship. All six edges survive.
This hierarchy supports structural recursion: process the smaller rooted trees below each vertex, then combine their results. A depth-first traversal of a tree explores one branch before returning; breadth-first search processes successive levels. The lowest common ancestor identifies where two routes from the root of a tree last coincide. For it is when . A binary tree imposes an additional restriction on children in a rooted tree; a general rooted tree has no such bound.
A rose tree is an ordered rooted tree in which each vertex can have any finite number of children in a rooted tree. A labelled Haskell representation is
data RTree a = Node a [RTree a]. Its tree fold has type (a -> [b] -> b) -> RTree a -> b: recursively fold the children, then combine their results with the current label. Unlike a binary tree, a rose tree has no fixed pair of child positions.A rose tree is perfect when all its leaves of a rooted tree have the same depth. This permits unequal branching counts and unary branches; perfectness alone does not require every internal vertex to have the same number of children. A bottom-up certificate returns
Just 0 at a leaf, Just (h+1) when all child certificates are Just h, and Nothing otherwise. Structural induction proves that a certificate exists exactly when the tree is perfect: all root-to-leaf routes acquire one edge when attached to the new root.A vertex reachable from a specified vertex by following child edges in a rooted tree. Allowing the length-zero graph path includes the starting vertex; a proper descendant excludes it. The subtree at a vertex consists of that vertex and its descendants. State the properness convention when using strict discovery-time inequalities.
Two distinct vertices are siblings when they have the same parent in a rooted tree.
A vertex with at least one child in a rooted tree. Internal vertices and leaves of a rooted tree partition the vertex set. The ancestors of an internal vertex are also internal; consequently the internal vertices of a nontrivial rooted tree induce a connected subgraph containing its root.
A node with no children in a rooted tree. This depends on the chosen root: the root of a nontrivial tree can have undirected vertex degree one while still having a child and therefore not being a leaf in the rooted sense. In a single-node rooted tree, the root is a leaf. The distinction matters when counting the complement of the internal vertices of a rooted tree.
A rooted tree in which every internal vertex has exactly three tree children. For a finite rooted tree with tree leaves and internal outdegrees , counting edges in two ways givesIndeed, the number of edges is the total number of vertices minus one and also the sum of the internal outdegrees. Thus a full ternary tree with internal vertices has tree leaves, always an odd number. More generally, if every internal vertex has either two or three tree children, . This parity controls the initial merge in ternary Huffman coding.
A full ternary tree whose leaves all have the same depth. At depth there are vertices, so a tree with levels has vertices and leaves, by the finite geometric series formula. For a rose tree representation, recursively flattening children and joining their lists with ordinary list concatenation copies each label once per ancestor. The work is therefore when the complete output is demanded. Passing an already constructed suffix through the recursion instead emits each label once, giving work.
The distinguished vertex that specifies a rooted tree. Its choice determines the parent in a rooted tree and children in a rooted tree relationships.
For a nonroot vertex, its adjacent predecessor on the unique graph path from the root of a tree. The root of a tree has no parent.
The exponential generating function for labelled rooted trees satisfies : remove the root and obtain an unordered set of smaller labelled rooted trees. For , the convergent series is the solution in of , rather than the larger real solution. Alternatively, tree-component expectation in the Erdős-Rényi model and subcritical exploration give for : their limiting probabilities for the order of the tree component of a uniform vertex sum to one. The component tail bound makes this passage through the infinite sum valid.
For finite rooted trees in the ancestor partial order, a rooted-tree homeomorphic embedding is an injective vertex map preserving lowest common ancestors: . The image of the source root need not be the host root. Edge paths and branching are preserved, while paths may be subdivided in the larger tree.
Give a leaf rank zero, and use Hessenberg natural sum over the immediate rooted subtrees. Every rank is below epsilon zero; conversely repeated exponentiation and finite summation encode every Cantor normal form below it. A rooted-tree homeomorphic embedding implies nondecrease of the rank. When roots match, child subtrees embed into distinct branches and exponentiation and natural sum preserve their inequalities. When the source root maps below the host root, its rank is bounded by that of a proper subtree, strictly below the host rank.
An adjacency-preserving rooted-tree embedding is an injective vertex map preserving the root and every adjacency. Because each root-to-vertex path maps to a simple path of the same length, vertex depths are preserved. This is more restrictive than a homeomorphic embedding of a rooted tree, which may stretch edges into paths. The branching-depth antichain of rooted trees shows that the adjacency relation is not a well-quasi-ordering.
Let consist of a rooted path of edges followed by two leaves at its far end. Its only vertex with two children has depth . An adjacency-preserving rooted-tree embedding must preserve this depth, so embeds into only when . This gives an infinite bad sequence, while rooted-tree homeomorphic embeddings can stretch the stems.
For rooted trees labelled in a preorder , a label-monotone tree embedding is a homeomorphic embedding of a rooted tree whose vertex map satisfies . The root need not map to the host root. For ordered child lists, require in addition that the map preserve the relative order of distinct branches.
The lowest common ancestor of two vertices is the common ancestor farthest from the root. In the ancestor partial order with the root least, it is their infimum, also called their greatest common ancestor.
For a label set , define inductively: choose a root label and a finite repetition-free sequence of rooted trees in as its children. Each object is a finite ordered rooted tree. Labels are distinct along each root-to-leaf path, and child rooted trees at a vertex are distinct as whole rooted trees. Labels may repeat across different branches; children need not have distinct root labels. For a finite pool of size , the exact number of rooted trees satisfiesThis follows by choosing the root and then an ordered repetition-free list from the finite pool of smaller rooted trees.
If is an infinite Dedekind-finite set, then is another such set. Single-vertex rooted trees inject into it. A countable sequence of distinct rooted trees gives finite lists of labels by the depth-first traversal of a tree in the prescribed child order. By countable union of explicitly ordered finite lists without choice, an infinite union of labels contradicts Dedekind-finiteness. A finite union is equally impossible, since every rooted tree then lies in the finite set , by mathematical induction on using the recursive child rule. Thus no countably infinite subset of rooted trees exists.
For an automorphism of a regular rooted tree and a first-level vertex , the section is the induced automorphism of the rooted subtree at , defined byAn automorphism fixing the first level is determined by the tuple of all its sections.
A forest is an undirected graph with no graph cycle; each of its connected components of a graph is a tree, including any isolated vertex. A finite forest with vertices and connected components of a graph hasIndeed, a connected component of a graph with vertices contributes edges; adding these counts gives . Equivalently, start with isolated vertices: every added edge must join different connected components of a graph, reducing their number by one. Joining vertices already connected would create a graph cycle. [ref]
https://ocw.mit.edu/courses/18-200-principles-of-discrete-applied-mathematics-spring-2024/mit18_200_s24_lec05-06.pdf. MIT, counting notes, p. 4: building forests by merging components
Deleting in our example gives , , and five edges: the two trees contribute . Deleting as well leaves isolated, so and four edges. A forest therefore describes separate hierarchies or the intermediate stages of building a spanning tree. The acyclic graph condition accounts for missing connections without assuming that all locations are mutually reachable.
A forest whose connected components of a graph are star graphs. In an inclusion-minimal edge cover, every edge has at least one endpoint of vertex degree one, forcing this structure with no isolated vertex.
A two-component spanning forest of a finite connected graph is an acyclic spanning subgraph with exactly two connected components of a graph. It has edges. For distinct terminals , a separating two-component forest places them in different components. Deleting an edge of the -to- graph path of a spanning tree produces such a forest; adjoining any original edge across its cut reverses this operation. This is the counting correspondence behind the mean spanning-tree path current.
A forest containing one minimum spanning tree of each connected component of a graph of a finite undirected weighted graph, including isolated vertices. For disconnected input, Kruskal's algorithm returns a minimum spanning forest.
Among all acyclic graphs contained in a finite weighted undirected graph, with no requirement to connect vertices, one optimum is obtained by keeping only strictly negative edges and computing their minimum spanning forest. Removing a nonnegative edge never worsens weight or creates a cycle. Within a connected component of the negative-edge subgraph, any disconnected candidate forest can be extended by a negative crossing edge, strictly improving its weight. Hence an optimum must span each such component and minimise its tree weight. Kruskal's algorithm on the negative edges therefore solves the problem. Zero-weight edges are optional when they preserve acyclicity.
A spanning tree of a connected graph is a subgraph that is a tree and contains every vertex of . Its edges must come from . For finite on vertices, every spanning tree has edges, the minimum possible number preserving reachability between all locations. This makes a spanning tree a compact certificate that the original graph is connected. A minimum spanning tree additionally minimizes a specified total edge weight; merely selecting a spanning tree supplies no such optimization. [ref]
Let be our seven-vertex tree with edge added. It has seven edges and a graph cycle. Removing gives the original spanning tree ; removing instead gives another spanning tree . Both retain all seven vertices and six edges, but their graph distances differ: , whereas . In , but , along , compared with . Preserving reachability permits longer journeys; breadth-first search can preserve graph distances from one chosen starting vertex.
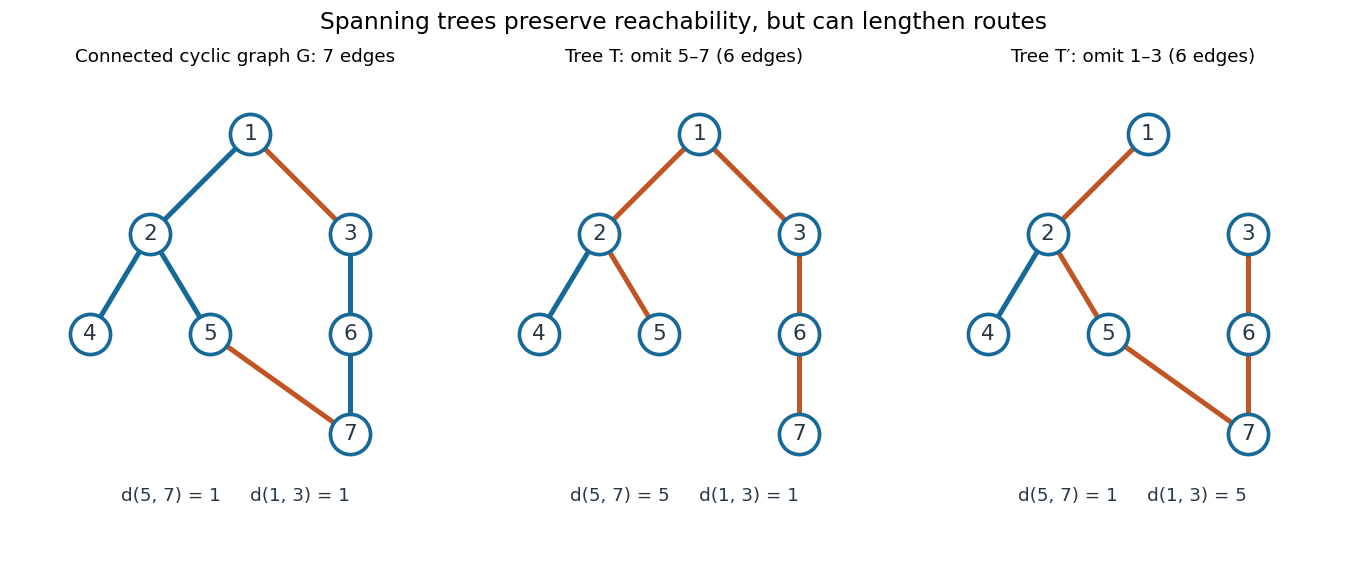
To construct a spanning tree, repeatedly delete any edge on a graph cycle. Its endpoints remain joined through the rest of that graph cycle, so the deletion preserves connectedness. Finiteness ensures that this stops at a connected acyclic graph. Conversely, adding an omitted edge to a spanning tree creates its unique fundamental cycle; deleting any other edge on that graph cycle produces another spanning tree. The displayed exchange replaces by . [ref]
https://www.maths.tcd.ie/~dwilkins/Courses/MA2C03/MA2C03Courseware_2014to15/MA2C03_S4_Yr1415.pdf. Trinity College Dublin, section 4.16: deleting cycle edges preserves connectivity
A spanning tree with greatest total edge weight. Apply Kruskal's algorithm in decreasing weight order, or negate every edge weight and compute a minimum spanning tree. Every graph path within a maximum spanning tree solves the widest path problem between its endpoints.
Suppose two spanning trees have the same first edges in nondecreasing weight order. If the first tree's next edge is no heavier than the second tree's next edge, it can be inserted into the second tree while preserving the common prefix and without increasing any sorted edge weight. If already occurs there, it ties for the next position. Otherwise its fundamental cycle contains an edge outside the prefix, since the prefix together with is acyclic. Every such is at least as heavy as . Exchanging for preserves the spanning tree. Replacing a multiset entry by a no-larger entry cannot increase any order statistic. Tied edges can be ordered to preserve the prescribed prefix.
Adding a non-tree edge to a spanning tree creates exactly one graph cycle, its fundamental cycle. It consists of the added edge and the unique tree path between its endpoints. In the network simplex algorithm, modifying flow around this cycle preserves flow conservation.
// Target: foundations-of-mathematics.bigb
A minimum spanning tree minimizes total edge weight among spanning trees of a connected weighted graph. It can be computed in polynomial time by repeatedly adding the least-weight edge joining two current components. The cut-exchange argument preserves the existence of an optimum containing every accepted edge. Removing an edge of a travelling-salesman tour gives a spanning tree, so its optimum is a lower bound on optimal tour cost.
Let an edge set be contained in some minimum spanning tree, and let a cut of a graph have no crossing edge in . Any least-weight edge crossing that cut of a graph can be added to while preserving its containment in some minimum spanning tree. Insert the chosen edge into an optimum containing , then remove another crossing edge from the resulting graph cycle; it is no lighter and cannot belong to . Ties imply existence of an optimum containing the chosen edge, rather than membership in every optimum.
Start with isolated vertices. In each round, determine the current connected components of a graph, choose a least-weight outgoing edge for each component, add their union, and recompute the components. With distinct weights, each chosen edge is the unique lightest edge across that component's graph cut. The minimum spanning tree cut property puts every such edge in every minimum spanning tree, so the selected edges remain acyclic. Every nonfinal component has an outgoing edge in a connected input, and merging makes progress until a spanning tree remains. Duplicate choices of the same edge are one set insertion.
Each new component contains at least two old components, so there are rounds. Scanning all edges per round gives time. Equal edge weights require a consistent secondary order to avoid choosing a cycle of tied edges.
Otakar Borůvka formulated the distinct-cost minimum-connection problem in 1926.[ref]
O jistém problému minimálním by Otakar Borůvka. pp. 37–38, opening formulation with positive distinct connection costs
Sort the edge weights of a minimum spanning tree and of any spanning tree in nondecreasing order. Then for every position. To prove it, fix a threshold and retain the graph's edges of weight at most . If this graph has connected components, contains a spanning forest of each component using those edges: otherwise a light edge joining two of its pieces could replace an edge heavier than on its tree path, decreasing total weight. Hence exactly edges of have weight at most . No other spanning tree can have more, since its retained edges form a forest inside those components. These threshold counts imply the coordinatewise inequality for sorted weights.
For a finite connected weighted graph with distinct edge weights, Kruskal's algorithm produces the unique minimum spanning tree. If another optimal tree existed, take an edge belonging only to the algorithm's tree and slightly increase its weight without changing the strict edge order. The algorithm then returns exactly the same tree, which must still be optimal, but the other tree's weight is unchanged and is now strictly smaller, a contradiction. Distinct weights are sufficient, not necessary: a triangle with weights has a unique optimum formed from the two weight-one edges.
Every path in a minimum spanning tree solves the bottleneck shortest path problem between its endpoints. If is a maximum-weight edge on the tree path, deleting it gives a graph cut separating the endpoints. A competing path with every edge lighter than would contain a crossing edge ; replacing with would decrease the tree's total weight, a contradiction. Equal weights cause no problem: the argument excludes a strictly smaller bottleneck and does not require a unique tree.
Process edges in decreasing weight and delete an edge whenever the remaining graph stays connected. Previously retained heavier edges are bridges in a graph and remain so under deletion. Thus a deletable edge is heaviest on a current graph cycle, and the minimum spanning tree cycle property excludes it from every minimum spanning tree. At termination the surviving connected graph has no graph cycle, so it is a minimum spanning tree.
Kruskal's algorithm constructs a minimum spanning tree of a finite connected graph with undirected edges and real edge weights. Start with all vertices and no edges, a forest of isolated vertices. Sort the edges by nondecreasing weight, then accept an edge exactly when its endpoints belong to different current connected components of a graph. Otherwise reject it: the existing graph path between its endpoints would close a graph cycle. Each acceptance merges two connected components of a graph. Stop after acceptances, when the forest has become one spanning tree.
This is a greedy algorithm for economical network connection: only the next affordable connection and the current connected components of a graph matter. Unlike Prim's algorithm, which grows one reached tree, Kruskal's algorithm can grow several separate trees before joining them. The essential safeguard is avoiding a graph cycle, rather than simply buying the cheapest fixed number of edges.
Joseph Bernard Kruskal described this rule as Construction A on page 49 of his February 1956 paper, On the shortest spanning subtree of a graph and the traveling salesman problem; page 50 gives an exchange argument for distinct weights.[ref]
https://langevin.univ-tln.fr/cours/graphe/bonus/Krukskal.pdf. Joseph B. Kruskal, Jr., Proceedings of the American Mathematical Society 7(1), February 1956, pp. 48–50; inspected scan, Construction A and final exchange argument
Consider this original connected graph on vertices . Its undirected edges, already in increasing weight order, areHere means the unordered pair ; the weights are dimensionless costs. Accept and , with total . Reject : its endpoints already have the graph path , so it would close the graph cycle . Accept and , reaching all five vertices with four edges. The resulting minimum spanning tree isStop here: and need not be examined. If processing continued, both would be rejected because their endpoints are already in the same connected component of a graph.
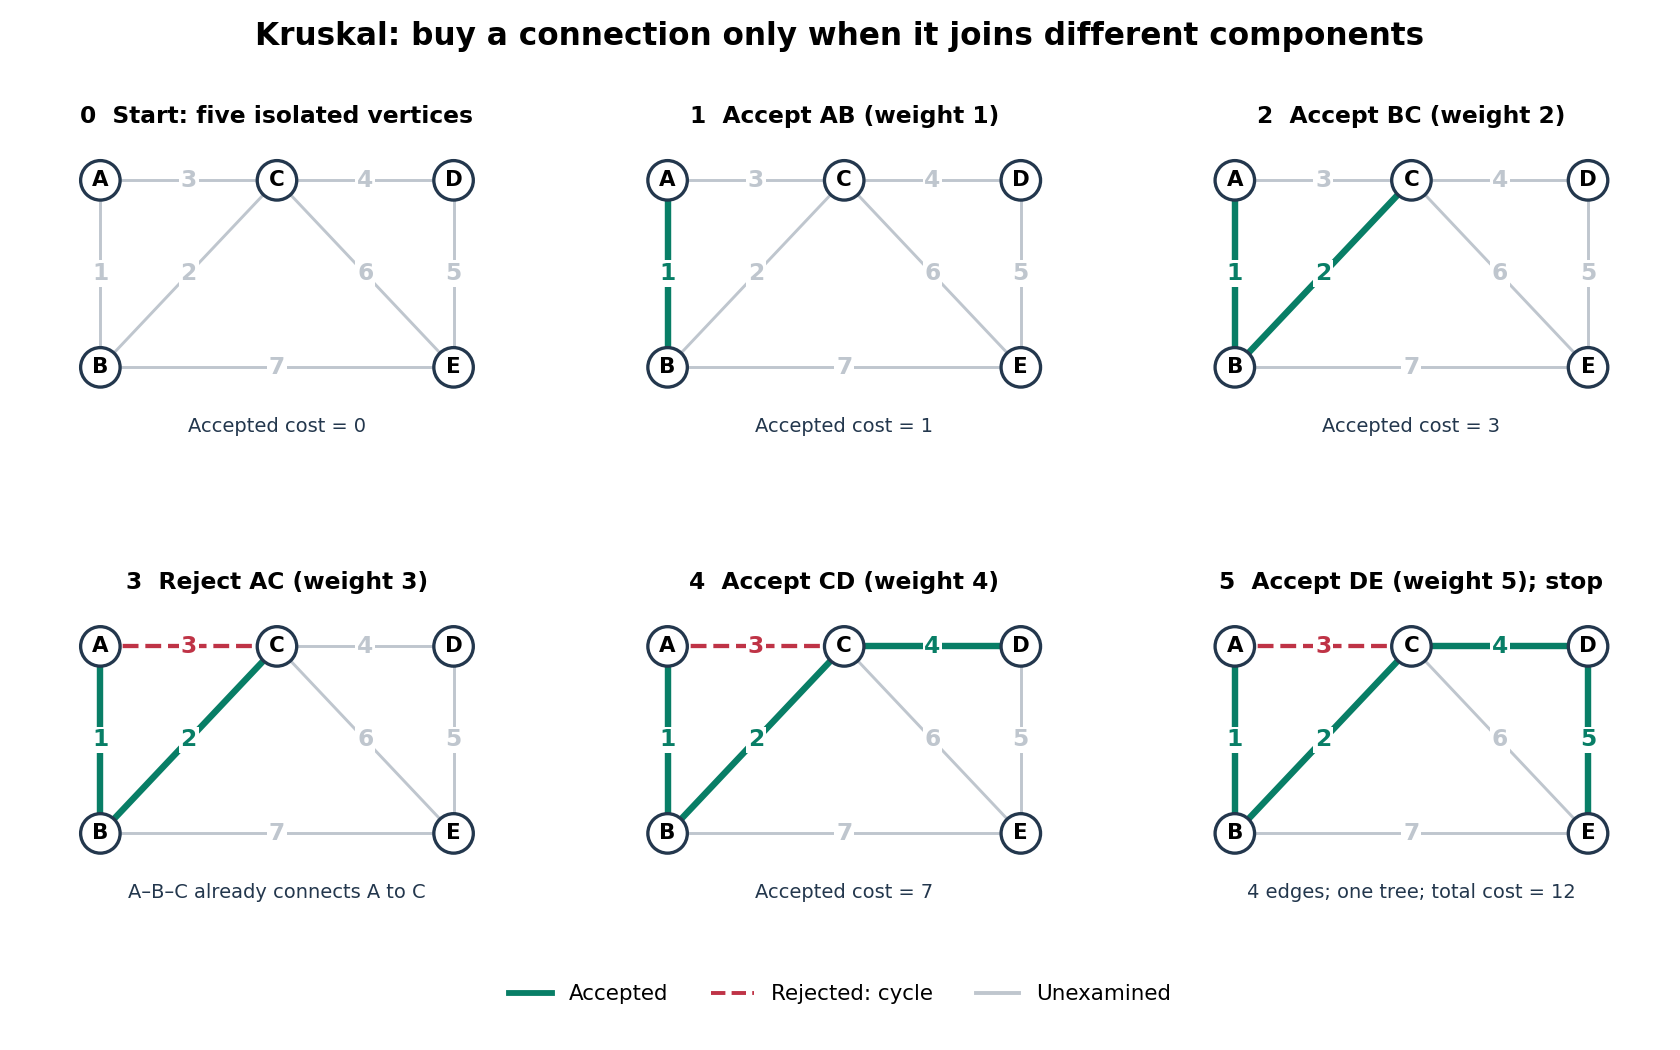
Taking the three cheapest edges instead gives a graph cycle on , leaving isolated: it is neither a forest nor a spanning tree. Even taking the four cheapest edges adds only and leaves isolated. A cheap infeasible selection cannot compete with a minimum spanning tree. For this small graph, checking all four-edge subsets gives a direct certificate: among those that are spanning trees, exactly one has minimum cost , namely . The general algorithm avoids this exhaustive search.
An edge is safe for the current accepted forest if some minimum spanning tree contains both and that edge. The loop invariant is that some minimum spanning tree contains every accepted edge. It holds initially for the empty edge set. Suppose the next accepted edge joins a current connected component of a graph to its complement. No earlier rejected edge crosses this cut of a graph: once its endpoints are in one connected component of a graph, subsequent merges never separate them. Thus is a lightest edge across that cut of a graph.
For the short exchange argument, take a minimum spanning tree containing . If is absent, adding it creates a fundamental cycle. This graph cycle contains another edge crossing the same cut of a graph. No edge of crosses the cut of a graph, so is not in . Replace by : the result is a spanning tree containing and , with no greater total weight because . It is therefore also a minimum spanning tree. This is the minimum spanning tree cut property in the form needed for tied weights.
In the example, is safe after rejecting : the current connected component of a graph has crossing edges of weights . Its cheapest connection is . The rejected is also the unique heaviest edge of the graph cycle , so the minimum spanning tree cycle property excludes it from every optimum.
Negative and zero edge weights are allowed: the comparisons and exchange argument still apply. Ties can give several minimum spanning trees, though they need not; any order among equal-weight edges remains valid. Distinct edge weights guarantee a unique minimum spanning tree. To see why, take the lightest edge belonging to exactly one of two proposed optima, say . Deleting from gives a cut of a graph; the other optimum has a graph path across it, containing an edge absent from . Hence , and replacing by improves that other optimum, a contradiction. For disconnected input, process all edges to obtain a minimum spanning forest, one minimum spanning tree per original connected component of a graph; no spanning tree of the whole graph exists.[ref]
KruskalMST.java. Robert Sedgewick and Kevin Wayne, Algorithms, 4th edition, companion KruskalMST.java, class documentation and constructor: arbitrary signed weights, ties, disconnected input and sorted processing
A disjoint-set data structure stores the current partition of a set of vertices into connected components of a graph. The operation returns a representative of the block containing . Two vertices are in the same block exactly when their representatives agree. For each candidate edge , compare and . Equal representatives mean reject; different representatives mean accept and perform , merging the two blocks. The representatives are bookkeeping choices, not preferred vertices of the minimum spanning tree.
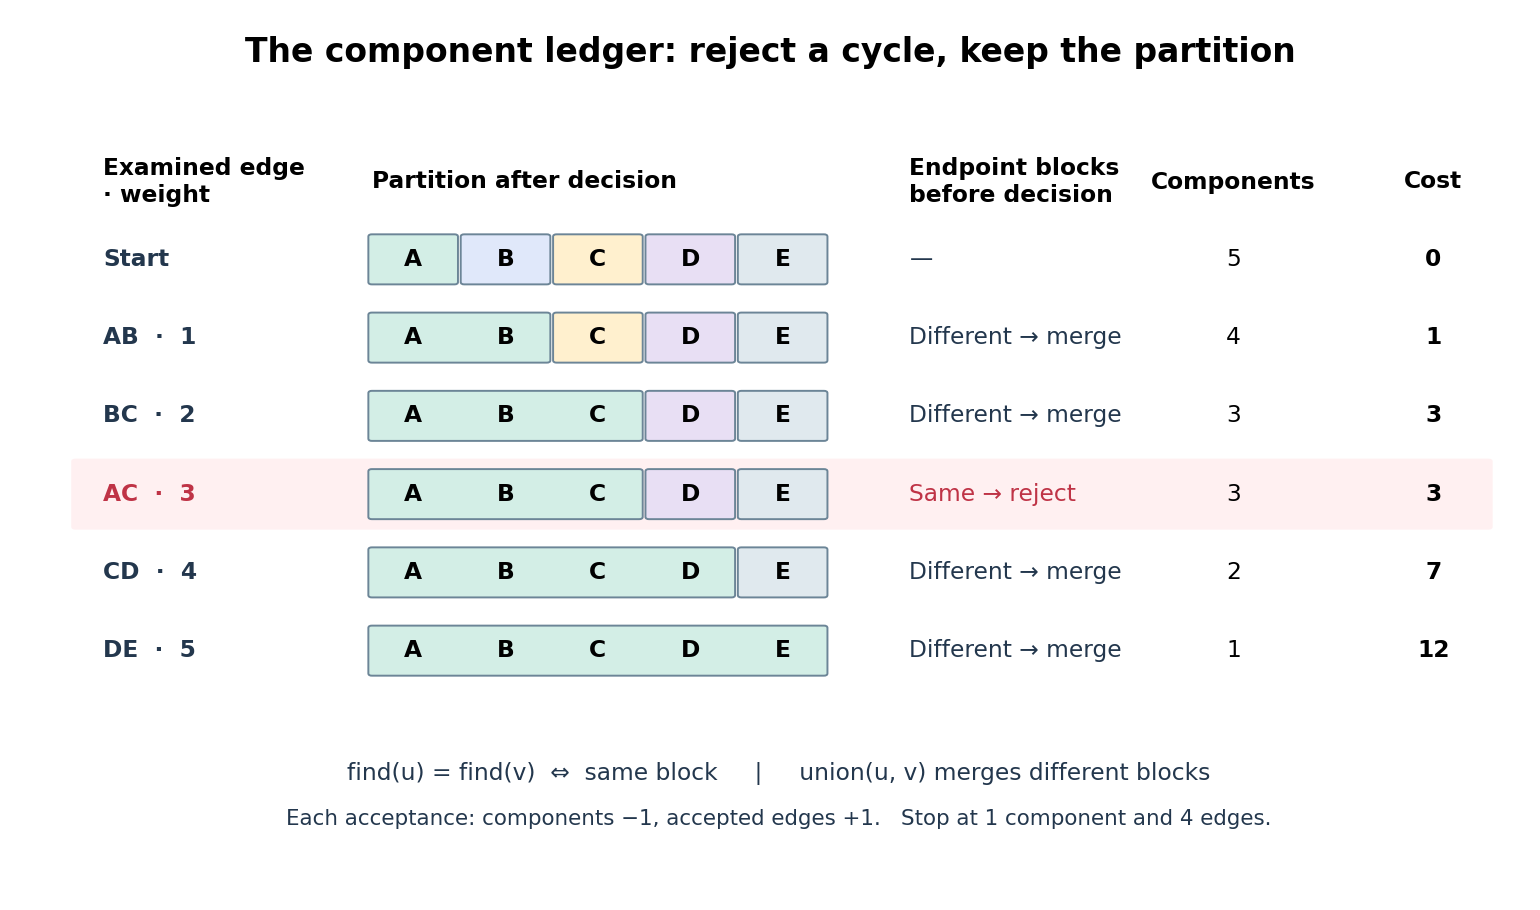
Connected components of a graph merge only when an edge is accepted
. The same example as a disjoint-set data structure ledger. Each coloured band is one block of the current partition of a set. The rejection of leaves both the partition of a set and the running cost unchanged. Bands show membership, not internal representative pointers. Details.Every acceptance reduces the connected component of a graph count by one and increases the accepted edge count by one, preserving . Thus the ledger reaches exactly when . Only ten representative queries and four merges are needed for the five examined edges, counting two queries per examination and using the already found representatives for each merge. Neither breadth-first search nor reconstruction of a graph path is needed for these connectivity queries.
For and , comparison sorting algorithm takes time for , using Big O notation. One simple disjoint-set data structure implementation stores each block as a rooted tree and attaches the smaller block's root below the larger block's root. Whenever a vertex's depth increases, its block size at least doubles, so its depth is at most . Consequently each representative query or merge takes time. Initialization plus the scan costs ; including sorting algorithm gives , hence for a connected input with . These are operation bounds, not measured timings.[ref]
WeightedQuickUnionUF.java. Robert Sedgewick and Kevin Wayne, Algorithms, 4th edition, companion WeightedQuickUnionUF.java: class documentation and union method; union by size without path compression, linear initialization and logarithmic operations
Start from one graph vertex. Repeatedly add the least-weight edge joining the reached graph vertices to an unreached graph vertex. Each step grows a tree and obeys the minimum spanning tree cut property. On a finite connected graph, the result is a minimum spanning tree.
The unique heaviest edge on a graph cycle belongs to no minimum spanning tree. If a spanning tree contains it, deleting it gives two components; the rest of the graph cycle has a lighter edge across that cut of a graph. Insert that edge to reduce the weight. This is the deletion certificate used by the reverse-delete algorithm.
The unique lightest edge across a cut of a graph belongs to every minimum spanning tree. If a spanning tree omits it, inserting it creates a graph cycle with another edge across that cut of a graph. Removing that heavier edge gives a lighter spanning tree, a contradiction. This proves the correctness of Prim algorithm and Kruskal algorithm for distinct weights.
On a connected locally finite recurrent graph, root Wilson's algorithm at a fixed graph vertex and process a countable enumeration of the graph vertices. Every walk hits the existing tree almost surely, since it contains . Each attached graph path is finite, and the union is a connected acyclic spanning subgraph. Its law is the infinite uniform spanning tree.
It is also the common free and wired finite-volume limit of a sequence along every graph exhaustion. For a finite edge set, run a finite initial segment of the chosen enumeration containing all its endpoints. Its membership is then permanently decided, because later attachments have new internal graph vertices. Only finitely many finite random-walk trajectories were used, and their graph vertices and graph neighbours fit inside all sufficiently large exhaustion sets. Coupling then gives convergence of those finite-dimensional edge laws for both boundary conventions. Finite Wilson's algorithm is root/order independent, so the limiting law is too. There is no uniform counting measure on all infinite spanning trees; the definition is this limiting probability law.
A uniform spanning forest is an infinite-volume limit of uniform spanning trees on finite graph approximations. Free and wired boundary identifications give the free uniform spanning forest and wired uniform spanning forest, respectively.
The free uniform spanning forest of an infinite locally finite graph is the weak limit of uniform spanning trees on finite induced connected exhaustions with free boundary. Every component is infinite almost surely.
For a uniform spanning tree, increasing events supported on disjoint sets of edges have nonpositive covariance. This negative association and the spatial Markov property imply monotonicity of free-boundary spanning-tree measures under exhaustion.
For oriented edges , the probability that their unoriented versions all belong to a uniform spanning tree is the determinant of the matrix of transfer currents between them. In particular, every finite forest that can be extended to a spanning tree has positive inclusion probability.
In a finite unweighted connected graph, take distinct graph vertices and orient the unique graph path from to in a uniform spanning tree and assign signed unit current to its edges. Its mean over trees is the electrical unit flow from to . The Kirchhoff node law follows by averaging graph path divergences. For the graph cycle law, let be the two-component spanning forests separating the terminals and the component containing . Deleting a tree-path edge and conversely adjoining an edge across a forest cut are inverse operations. Hence the mean signed current on an edge isThis is the gradient of , proving the graph cycle law. In particular . For an oriented existing edge , that edge is used by the tree graph path exactly when it belongs to the tree, and then has positive orientation. Thus its mean current is , giving the edge-inclusion formula for a uniform spanning tree by Ohm's law.
For an edge of conductance in a finite electrical network, its inclusion probability in the conductance-weighted uniform spanning tree is . The same formula holds for the wired limit using the limiting wired effective resistance.
On a transitive graph, the free and wired uniform spanning-forest measures are invariant and ergodic under the transitive automorphism group. Consequently every translation-invariant event has probability zero or one.
The Aldous-Broder algorithm runs a random walk and includes the edge by which each vertex other than the start is first entered. On a finite graph this yields a uniform spanning tree. The same first-entrance construction works on recurrent infinite graphs through the infinite-volume limit.
Wilson's algorithm samples a uniform spanning tree by starting from a root and successively attaching loop-erased random walks from vertices not yet in the tree.
The wired uniform spanning forest of an infinite graph is the weak limit of uniform spanning trees on finite exhaustions whose exterior vertices are identified to one wired boundary vertex.
Wilson's algorithm rooted at infinity builds the wired uniform spanning forest on a transient graph by successively adding loop-erased random walks, run forever when they never hit the forest already constructed.
The number of trees in a wired uniform spanning forest is almost surely constant. This follows from its tail triviality together with the fact that every component is infinite.
A directed spanning tree rooted towards a vertex is a spanning tree whose edges are oriented so that every other vertex has a unique directed path to .
The matrix-tree theorem expresses the weighted number of spanning trees of a finite graph as a cofactor of its Graph Laplacian. For a directed graph with out-Laplacian , deleting the row and column indexed by a root giveswhere the sum runs over directed spanning trees rooted towards .
For an integer , let be the set of labelled trees with fixed vertex set . Each tree is a finite simple graph, with no distinguished root of a tree, and two trees are different exactly when their sets of edges differ. ThenEquivalently, this is the number of spanning trees of the complete graph . The labelled combinatorial structure includes the fixed labels: drawings, positions, and the order in which edges are listed do not create extra trees. For , the single vertex with no edges is the unique tree; count it separately, since the Prüfer sequence construction requires . For , the unique tree has edge and corresponds to the empty Prüfer sequence. [ref]
https://users.math.msu.edu/users/magyarp/math481/. Peter Magyar, Michigan State University, Math 481: Cayley's theorem and inverse Prüfer transformations
For four fixed labels, there are labelled trees, but only two unlabelled trees: the star graph and the path graph. There are four star graphs, one for each choice of centre. There are path graphs: arrange the labels along a graph path, then identify each ordering with its reversal, which describes the same set of edges. Thus . For instance, star graphs centred at and at have different sets of edges even though they have the same shape.
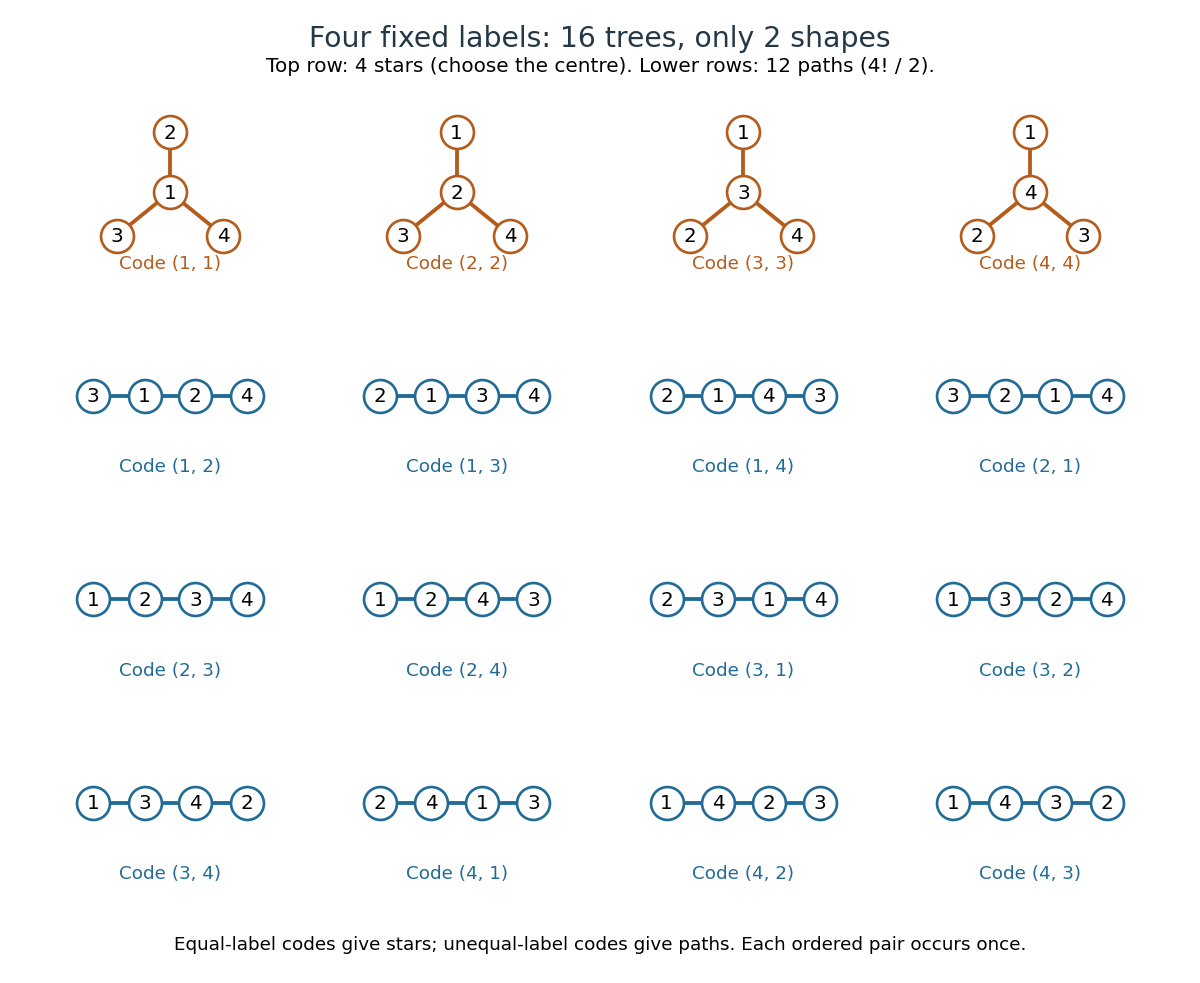
All sixteen labelled trees on four fixed vertices: four star graphs and twelve path graphs, each with its Prüfer sequence
. Details. The striking point is that connectedness and the absence of a graph cycle are global restrictions on edges, yet the answer is a power with no correction factor. The Prüfer sequence supplies a bijection that turns those restrictions into freely chosen labels. The rule of product then gives immediately. The same representation makes vertex degrees easy to count and supports uniform labelled tree generation for simulations and algorithm experiments.
Arthur Cayley's 1889 paper "A theorem on trees", published in the Quarterly Journal of Pure and Applied Mathematics, volume 23, pages 376–378, treats the counting problem and its refinement by vertex degrees. It was reprinted as paper 895 in volume XIII of his Collected Mathematical Papers, pages 26–28. This publication is the historical context for the name Cayley's formula; the name alone is not a claim of priority. [ref]
https://gdz.sub.uni-goettingen.de/id/PPN600494829_0023. Cayley, A theorem on trees (1889), original journal volume, pages 376–378
[ref]https://doi.org/10.1017/CBO9780511703799.010. Cayley, A theorem on trees, collected-paper reprint and publisher's first-page preview
For a fixed set of roots among labelled vertices, the number of forests with exactly one root in each graph component is . Orient edges toward their roots. Repeatedly remove the smallest nonroot leaf and record its parent. This gives a code of length whose last entry is a root. Conversely, for any such code choose the smallest remaining nonroot absent from the remaining code, join it to the first entry, and delete it. There is always a choice because the final entry is a root. These inverse operations give choices for the earlier entries and for the last. For , the empty forest is unique.
For , a Prüfer sequence is the encoding of a labelled tree on by a sequenceRepeated labels are allowed, and their order matters. To encode the tree, repeatedly remove its smallest-labelled leaf of a graph together with its incident edge, recording the label of its unique neighbour. Stop when two vertices remain; do not record their final edge. Removing a leaf of a graph leaves a tree, so the procedure makes exactly deletions. The choice of the smallest label makes the encoding deterministic. [ref]
https://users.math.msu.edu/users/magyarp/math481/. Peter Magyar, Math 481: Prüfer encoding with the smallest leaf
For a concrete example, take six vertices and the set of edgesInitially label the vertices of vertex degree one. Remove and record its neighbour . Now has become a leaf of a graph, so remove and record . Next remove and record again; then remove and record . The final edge joins and . Thus the Prüfer sequence isThe deletion order is : removing a leaf of a graph can make its neighbour a leaf of a graph, so the eligible labels change as the tree shrinks.
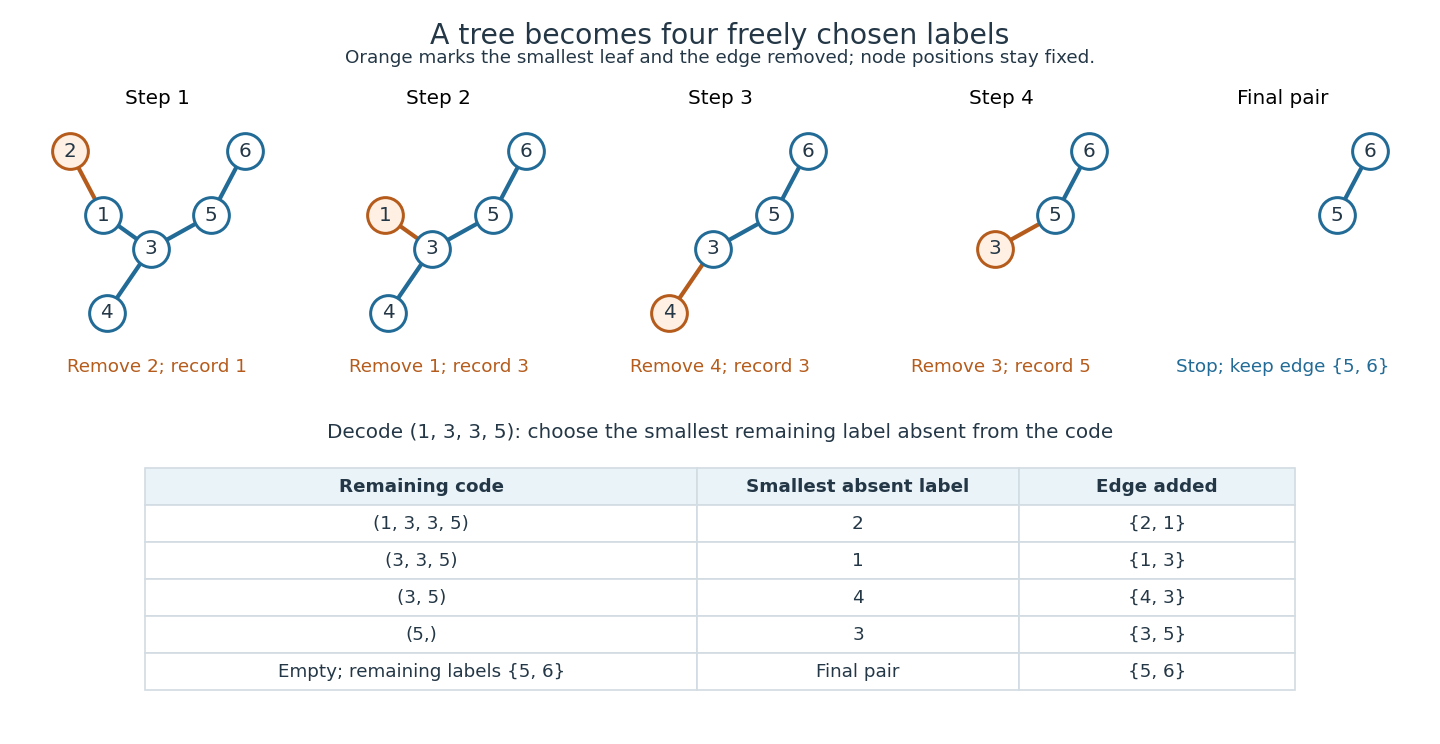


To decode, keep a set of remaining labels, initially , and the remaining sequence, initially . While the sequence is nonempty, let be the smallest label in absent from the entire remaining sequence. Add an edge between and its first entry, then remove from and delete that first entry. Finally join the two labels left in . For the example:
The decoder always has a choice: if the remaining sequence has length , then has labels, so at least two of them are absent. Its first entry is still in , and differs from the chosen absent label. Every removed vertex attaches to a vertex that survives longer; following these attachments eventually reaches the final pair. Consequently the decoded graph is connected, and its edges make it a tree. In this construction, each occurrence of contributes an incident edge, and gets one more edge at its final attachment. Thus a remaining label is absent from the remaining sequence exactly when it labels a leaf of a graph. Encoding and decoding choose the same smallest label at each step and undo each other. This bijection proves Cayley's formula and explains why every freely chosen sequence is valid. [ref]
https://www.cs.columbia.edu/~cs4203/files/GT-Lec4.pdf. Columbia University, Graph Theory Lecture 4: Prüfer degree identity, decoding algorithm, and bijection
For there is exactly one empty sequence, and decoding adds the sole edge. For there is one tree, with vertex degree zero, but no length- Prüfer sequence. This is the exception both to the encoding convention and to the Prüfer degree formula.
Heinz Prüfer's 1918 paper "Neuer Beweis eines Satzes über Permutationen" appeared in Archiv der Mathematik und Physik, third series, volume 27, pages 142–144. It gives an encoding proof of the labelled tree count. The historical title means "New proof of a theorem on permutations"; the modern Prüfer sequence permits repeated labels, so it is not a permutation. [ref]

https://i.sstatic.net/WDvxyMwX.png. Prüfer (1918), original opening-page scan, page 142
A tree on labels has one root of degree two, other interior vertices of degree three, and leaves precisely when its Prüfer code contains one label once, labels twice, and all other labels zero times. The Prüfer degree formula gives both directions, and identifies the root as the uniquely once-occurring label. Children are unordered unless a plane embedding is additional data.
For a labelled tree with vertices, the vertex degree of label is one plus the number of occurrences of in its Prüfer sequence:Each recording of corresponds to an incident edge removed when a neighbouring leaf of a graph is deleted. Exactly one incident edge remains when itself is deleted, or when it belongs to the final pair. In particular, is a leaf of a graph exactly when it never occurs in the Prüfer sequence. The same reasoning applies to each remaining tree and its remaining code. [ref]
https://www.cs.columbia.edu/~cs4203/files/GT-Lec4.pdf. Columbia University, Graph Theory Lecture 4, Proposition 7.1: degree equals occurrences plus one
For , the occurrence counts in label order are , giving the degree sequence . Its sum is , as required by the degree-sum formula. More generally, summing the occurrence counts gives , so summing the vertex degrees gives .
For and positive integers with , the number of labelled trees having vertex degree at label isBy the Prüfer degree formula, this is the multinomial coefficient counting sequences with occurrences of each label. If a degree is zero or the sum is wrong, there are no such trees. For the example degree sequence , there are labelled trees, one for each ordering of the labels . Knowing the vertex degrees thus constrains, but usually does not determine, the tree.
For , choose independent random variables, each with the uniform distribution on a finite set , and decode their values as a Prüfer sequence. Every sequence has probability , and the bijection gives each labelled tree the same probability. This produces a uniform spanning tree of the complete graph without repeatedly proposing sets of edges and rejecting those that fail to be trees. It supplies random inputs for testing implementations of breadth-first search and a tractable model of random connections. [ref]
https://sites.math.rutgers.edu/~zeilberg/Combo20/hw.html. Doron Zeilberger, Rutgers Math 454 (2020), Lecture 23: generate random labelled trees by sampling and inverting Prüfer codes
This distribution is uniform over fixed-label trees, rather than over unlabelled trees. With four labels, the star graph shape has probability and the path graph shape has probability . Also, for a fixed label , the Prüfer degree formula givesHere the binomial distribution counts the independent code positions equal to . The expected value agrees with the average vertex degree from the degree-sum formula. Individual labels have the same distribution by symmetry, though their vertex degrees are constrained together by their fixed sum. When , simply return the single isolated vertex.
Every infinite finitely branching rooted tree has an infinite branch. Starting at the root, repeatedly choose a child above which infinitely many vertices remain.
Breadth-first search is a graph search that explores successive layers of graph distance from a starting vertex . Here the graph is an undirected graph on a finite set of vertices, and distance counts edges, with no differing edge weights. Mark as discovered, assign , and place it in a FIFO queue. Repeatedly remove the front vertex and scan its adjacency list. Whenever a graph neighbour is still undiscovered, mark it immediately, record as its parent in a rooted tree in the discovery tree, assign , and enqueue at the rear. Marking on insertion ensures that another edge cannot enqueue the same vertex again. [ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/BreadthFirstPaths.java. Sedgewick and Wayne, Algorithms: BreadthFirstPaths queue and discovery rule
Use the same undirected graph as depth-first search, with vertex set and edgeswhere denotes the unordered pair . Start at and scan graph neighbours in lexicographic order of their one-letter labels. The diagram's generator computes the following layers and the parent in a rooted tree assigned to each discovered vertex; the source is the root of a tree and has no parent in a rooted tree.
| Graph distance from | Vertices in discovery order | Parent in a rooted tree in the same order |
|---|---|---|
| none | ||
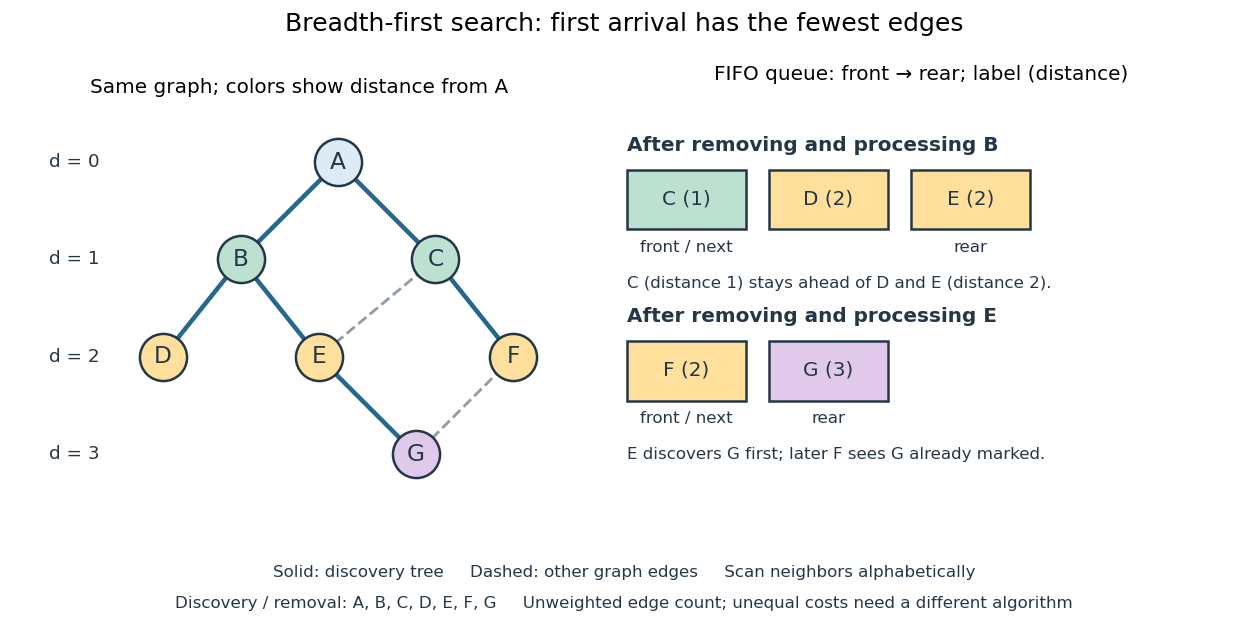

The discovery and removal orders both happen to be . After processing , the FIFO queue is : must be processed before the newer . Processing then skips the already discovered and enqueues , giving . Processing adds nothing. Processing discovers , giving ; later sees already marked and leaves its parent in a rooted tree unchanged. The discovery edges are , forming a rooted tree on all seven vertices even though the original graph contains graph cycles. The discovery tree contains six edges; it need not contain every examined edge.
First arrival is shortest because the FIFO queue keeps assigned distances in nondecreasing order, with entries from at most two consecutive layers. While processing distance , newly discovered vertices receive distance and join the rear. If an undiscovered vertex had a shorter graph path, its preceding vertex on that graph path would lie in an earlier layer and would already have discovered it. Thus is the minimum number of edges from to . This is a mathematical induction over the layers, not an assumption about the drawing. Following the parent in a rooted tree backwards at each step gives ; reverse that sequence to obtain the three-edge graph path . is another shortest graph path, but the specified graph neighbour order makes discover first. Changing that order can change the parent in a rooted tree without changing graph distances. [ref]
https://ocw.mit.edu/courses/6-006-introduction-to-algorithms-fall-2011/1208e162775f6f5cedfbb9f2b694ede0_MIT6_006F11_lec13.pdf. MIT 6.006, lecture 13: distance layers and shortest paths, pp. 4–6
The shortest-route guarantee concerns the shortest path problem measured by edge count. It also minimizes total cost when every edge has the same positive cost. With unequal edge weights, first discovery need not minimize total cost; nonnegative costs can instead be handled by the Dijkstra algorithm. Breadth-first search is useful for minimum-hop routes and for finding all vertices within a specified graph distance. Its FIFO queue finishes an older layer before the next one, whereas depth-first search uses a call stack or explicit LIFO stack to pursue one branch immediately.
With adjacency lists and constant-cost discovery checks, together with constant worst-case or amortized analysis cost for FIFO queue insertion and removal, the time complexity is in Big O notation. Every reached vertex is enqueued and removed once, each incident edge is scanned at most twice in an undirected graph, and initializing all marks and distances takes . The FIFO queue contains at most vertices; the example's maximum is three. Discovery marks, distances and the recorded parent in a rooted tree for each nonroot vertex also give auxiliary space complexity, excluding the graph. An array that shifts every entry on front removal can lose the linear time complexity; the FIFO queue abstraction alone does not make removal constant-cost. Ordering the adjacency lists is a separate preprocessing cost.
A single start reaches only its connected component of a graph. Unreached vertices retain distance and have no recorded parent in a rooted tree. Restarting at each still-undiscovered vertex, while preserving all discovery marks, produces a forest covering the graph; each new root of a tree gets distance zero, so these distances refer to that root of a tree, not to the original .
The tree search version of breadth-first search explores action histories in nondecreasing length without automatically removing repeated states. A finite branching factor ensures that every finite depth contains finitely many histories, so the method is a complete search algorithm for goals reachable at finite depth. With equal positive action costs it is an optimal search algorithm for total action cost. It need not terminate on an unsolvable instance with an infinite search tree, and it need not optimize a terminal reward unrelated to depth.
Maintain a FIFO queue of child iterators ordered by the breadth-first order of their parents. Consume a child from the front iterator and append a deferred iterator for that child's children; discard empty front iterators as needed. This enumerates descendants without first materializing a whole child list or level. On a locally finite tree, each node occurs after finitely many earlier outputs. If an earlier level is infinite, strict breadth-first order cannot put a deeper node at any finite output position; that obstruction is inherent in the requested ordering.
Articles by others on the same topic
There are currently no matching articles.