Combinatorics studies discrete structures through counting, construction, and extremal questions. Its objects include subsets, permutations, graphs, and set partitions. The question is often easy to ask: how many teams can we choose, how many arrangements avoid a collision, or how few connections are enough? The challenge is to organize the possibilities so that every permitted object is counted exactly as intended.
For example, choosing two people from five gives ten teams. Choosing a captain and deputy from those same five gives twenty assignments. The difference is whether order is part of the object: a team is a subset, while the two named roles distinguish an ordered pair. The binomial coefficient and the rule of product encode these two counting problems. Choosing the right objects comes before manipulating a formula.
The beauty is that a change of viewpoint can turn enumeration into an explanation. Double counting connects two descriptions of one collection; Pascal's identity splits a selection into cases; the inclusion-exclusion principle repairs overlapping counts. These methods also supply exact finite models for probability and help measure the possibilities an algorithm must handle. Richard Stanley's textbook introduces the subject through counting questions and then develops these general tools. [ref]
For finite sets, removing the elements of from leaves elements. Indeed is the disjoint union of and , so the rule of sum proves the formula. If , it reduces to .
A cyclically ordered collection of endpoints paired into chords of a circle. The crossing relation defines a circle graph; two chords with distinct endpoints cross exactly when their endpoints alternate.
The number of inversions of a word: pairs of positions with . Unlike an inversion of a permutation, this definition permits repeated letters in the word.
For slope and intercept , the lower mechanical word has letters . These letters are zero or one. Replacing floors by ceilings defines the upper mechanical word. An irrational slope gives a Sturmian word.
The floor-based mechanical word .
A nonempty finite word that is strictly smaller in lexicographic order than each of its nontrivial cyclic rotations. For example, is a Lyndon word, whereas is not because its rotation is smaller.
A prefix of a word that is itself a Lyndon word. The longest Lyndon prefix is useful when ranking necklaces and substrings of a De Bruijn sequence.
A polycube is a face-connected union of finitely many unit cubes in the three-dimensional cubic grid. Its exposed square faces determine its surface area.
Unranking constructs the object at a specified rank in a chosen ordering of a finite class. Lexicographic unranking uses lexicographic order.
Pólya enumeration counts objects under a group action, often by applying the Pólya enumeration theorem to colourings.
The subset zeta transform sends a function on subsets to . For subsets of an -element set, all values can be computed in additions by processing one element at a time. Reversing containment gives the superset transform.
The Pólya enumeration theorem counts colourings up to a finite group action using the action's cycle index. Substituting colour weights into each cycle variable groups colourings by their colour inventories.
Entringer numbers refine counts of alternating permutations. One standard convention uses , for , and for . Reversed-row prefix sums generate the triangle.
The Entringer triangle arranges Entringer numbers into rows. Each row is obtained from reversed-row prefix sums, with the boundary convention specified by the recurrence.
Lexicographic unranking constructs the object at a specified position in lexicographic order. At each step it counts valid completions for each possible next symbol, skips blocks preceding the desired rank, and continues within the selected block.
A transfer matrix stores the weights of allowed transitions between finitely many boundary states. Its powers sum weights of compatible sequences of transitions. For a cyclic boundary condition, the matrix trace counts weighted closed sequences of length .
A cyclic sequence over an alphabet of size in which every word of length appears exactly once as a cyclic window. Its length is . The De Bruijn graph converts its construction into an Eulerian cycle problem.
A finite connected union of unit squares on the square lattice, joined along whole sides. Counting conventions may identify shapes under translation, rotation, or reflection, so those conventions must be specified.
A choice of distinct elements from a set of elements, with order ignored. Equivalently it is a -element subset. The binomial coefficient counts such choices; choosing with repetition instead produces a multiset.
Allocate distinct objects to labelled bins of specified nonnegative sizes , with . Order within a bin is ignored. The number of allocations is the multinomial coefficientTo prove this, order all the objects in a permutation and assign the first to the first bin, the next to the second, and so on. Every allocation comes from exactly internal orderings. These disjoint classes exhaust the permutations, proving the formula by the multiplication principle. Empty bins are allowed because .
For two bins of sizes and , the count is and every allocation has multiplicity in the permutation sample space. Exchanging two equal-sized labelled bins generally gives a different allocation. In contrast, a set partition uses unlabelled nonempty blocks; forgetting bin labels changes the counting problem and must not be done silently.
Place objects into boxes, assigning each object to exactly one box. Here is a nonnegative integer and is a positive integer. The pigeonhole principle says that if , some box contains at least two objects. Equivalently, a function from an -element finite set to an -element finite set cannot be an injective function when . The boxes may stand for categories rather than physical containers. [ref]
https://ocw.mit.edu/courses/6-042j-mathematics-for-computer-science-spring-2015/mit6_042js15_textbook.pdf#page=581. Lehman, Leighton and Meyer, Mathematics for Computer Science, section 14.8, rule 14.8.1
For thirteen objects and twelve boxes, a box containing at least two is unavoidable. Thinking of thirteen people and their birth months gives the same conclusion: at least two share a birth month. Twelve people could occupy the twelve months one apiece, so thirteen is the smallest number that forces a shared month. The generalized pigeonhole principle quantifies how many objects must share a box when there are still more objects.
The useful surprise is that the pigeonhole principle proves existence without needing to locate the objects involved. Choosing a good assignment rule is often the creative step: equal labels can mean equal remainders, nearby points, or repeated states of an algorithm. Once the rule is chosen, a short count can force a relationship among a much larger collection of objects. The pigeonhole principle itself does not name the crowded box. When the objects and their assignments are explicitly available, a simple algorithm finds one: scan the objects, keep the first object seen in each box, and stop when a later object enters an occupied box. At most scanned objects are needed when .
A geometric example. Any five points in a square of side one contain two whose Euclidean distance is at most . Give each point Cartesian coordinates . Divide both ranges into the intervals and , making four cells. Thus belongs to the left half and to the right half; belongs to the lower half and to the upper half. This convention assigns every boundary point to exactly one cell.
The pigeonhole principle puts two of the five points in the same cell. Their differences in Cartesian coordinates have magnitude at most , so the Pythagorean theorem gives their Euclidean distance the boundFor the plotted points , , , and , the first two occupy the lower-left cell and have Euclidean distance . These Cartesian coordinates exhibit the forced pair; the argument applies to every placement of five points.
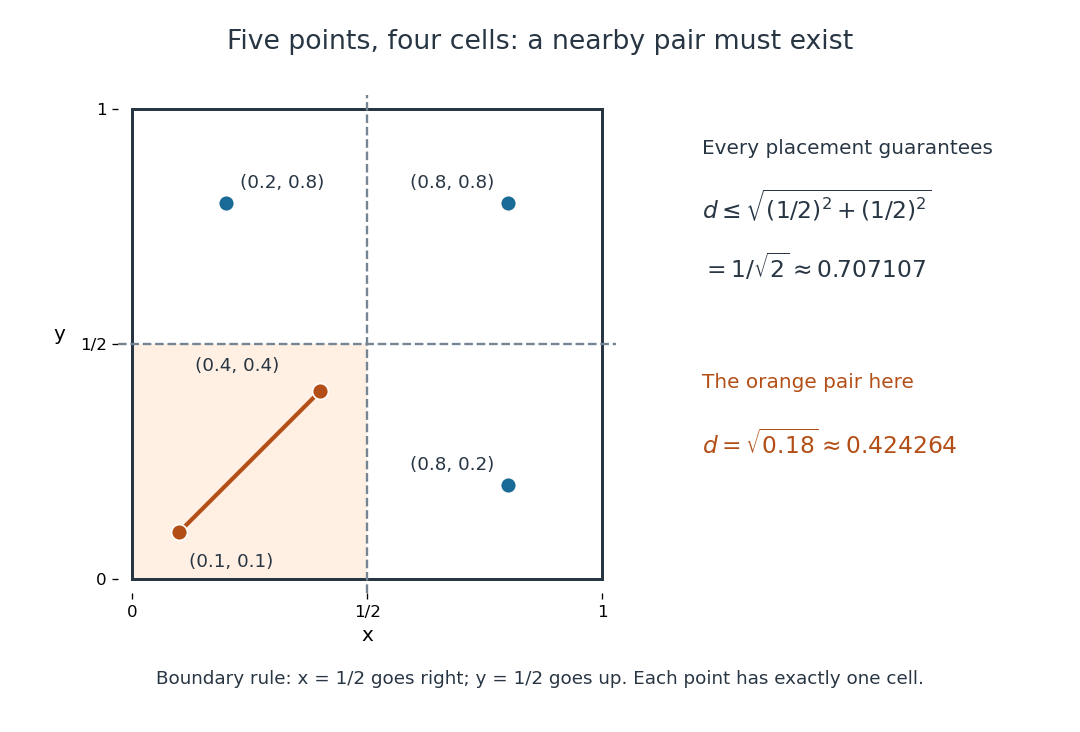
The pigeonhole principle places two of five points in one of four cells of a square, bounding their Euclidean distance by
. Details. An arithmetic example. Assign eight integers to their seven residue classes modulo the integer modulus . The pigeonhole principle gives two with the same residue class, so is an integer divisor of their difference. In , for example, and satisfy the integer congruence , and . Likewise, assigning fractional parts to short intervals gives the Dirichlet approximation theorem; its existing article explains the approximation bound.
For any sequence of integers, some nonempty consecutive block has sum divisible by . Form the prefix sums . There are only residue classes modulo , so the pigeonhole principle gives for some . Subtraction proves that is the required block sum. Negative entries and repeated entries cause no difficulty. Applied after any ordering of a finite set, it also gives a nonempty subset whose sum is divisible by the size of the set.
Suppose a subset of a metric space is covered by sets, each of diameter at most . Assign each point to one covering set containing it, choosing a single set at shared boundaries. Among points, the pigeonhole principle puts two in a common set, and their distance is at most . The pieces need not be equal or congruent. This freedom permits better distance bounds than dividing a region only into equal rectangles.
For objects assigned to boxes, let be the number in box . The generalized pigeonhole principle statesThe ceiling function rounds up because box counts are integers. An equivalent threshold formulation says: for a positive integer , if , some box contains at least objects. For , putting objects in each box shows why the strict inequality matters. [ref]
https://ocw.mit.edu/courses/6-042j-mathematics-for-computer-science-spring-2015/mit6_042js15_textbook.pdf#page=583. Lehman, Leighton and Meyer, Mathematics for Computer Science, section 14.8.1, rule 14.8.2
Computed examples. For and , . Counts attain this bound. For and , , and the balanced counts sum to and have largest count exactly . The threshold version agrees: . In contrast, seven boxes each containing three hold only objects.
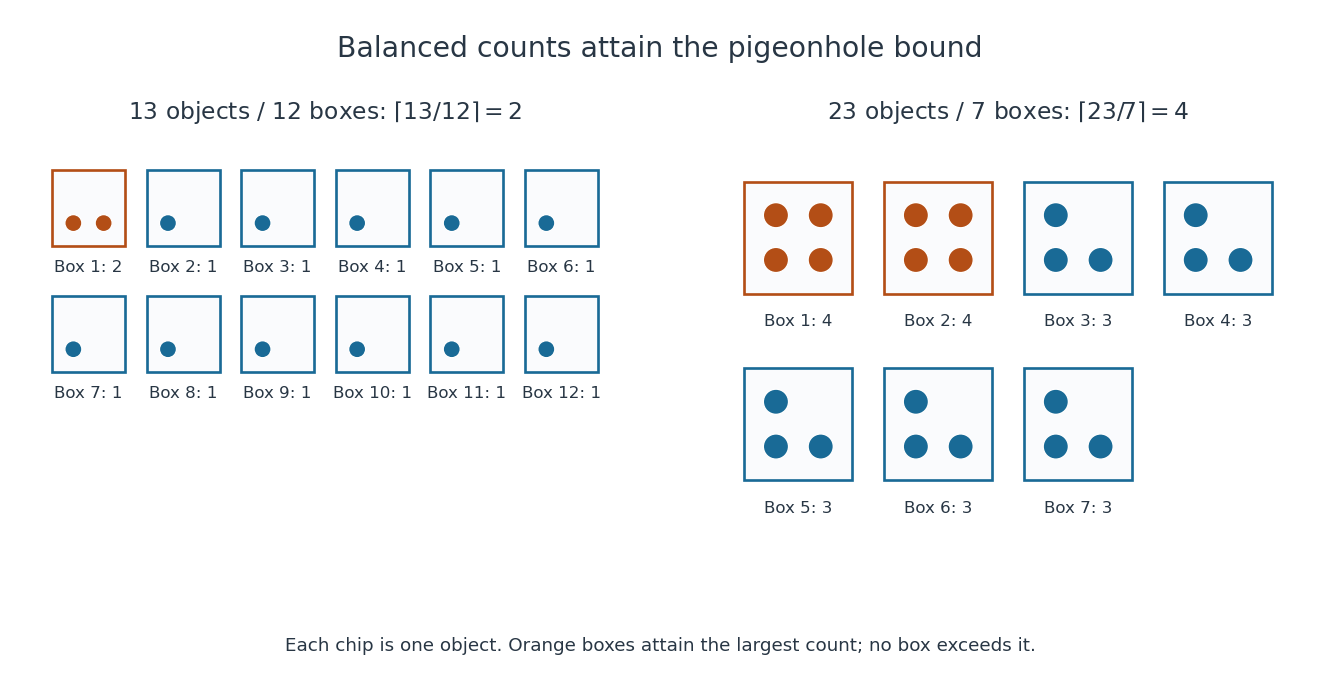
Two balanced arrangements attain the generalized pigeonhole principle bounds: thirteen objects in twelve boxes force two, and twenty-three in seven force four
. Details. The bound is sharp for every and . Use Euclidean division to write with integers and . Place objects in each of boxes and objects in each remaining box. The largest count is if , and if , exactly . This balanced arrangement makes the guarantee best possible even though other arrangements can be much more crowded.
Proof outline. If every count were at most , the total would be at most . This contradicts . Taking proves the displayed bound for ; for every count is zero.
The infinite pigeonhole principle says that if an infinite set has a partition of a set into finitely many parts, at least one part is an infinite set. Equivalently, assigning infinitely many objects to a finite number of boxes forces some box to contain infinitely many objects. For example, separating the natural numbers into their two residue classes modulo forces at least one class to be an infinite set; here both are, as the lists and show.
Proof outline. A union of finitely many finite sets is a finite set. If all the parts were finite sets, their union could not be the original infinite set.
The assumption of finitely many parts is essential. With one box labelled by each natural number, assigning to box puts exactly one object in every box. Infinitely many objects and infinitely many boxes therefore need not produce even a shared box. The infinite pigeonhole principle is useful whenever finitely many labels organize an endless collection: one label must keep occurring infinitely often, providing an infinite set on which that label is constant.
A parameter-dependent generalization which recovers a familiar object at a specified value or limit of the parameter. In enumerative combinatorics, a generating function can refine an ordinary count by retaining a statistic; Gaussian binomial coefficients are one example.
Covering a finite board with specified tiles without gaps or overlaps. Counting board tilings connects local placement rules to a recurrence relation and a generating function.
A combinatorial structure whose elements carry distinct labels from a prescribed finite set. For example, a rooted tree can have labelled vertices; assigning labels is part of the structure counted by an exponential generating function.
An independence system consists of a finite set and a nonempty family of subsets such that and imply . This is the hereditary condition: deleting chosen elements keeps a selection admissible. In particular, the empty set belongs to . An independence system becomes a matroid when it also satisfies the matroid independence axioms for exchange. The hereditary nonmatroid greedy obstruction shows why deletion alone does not justify a greedy algorithm.
The ground set is the set of labelled elements available for selection. An independence system specifies which subsets of this ground set are admissible; in a linear matroid the labels index vectors, whereas in a graphic matroid they index edges.
On the ground set , permit exactlyThis lists every admissible subset; the excluded subsets are , , and . It is an independence system: deleting elements from produces its listed singletons or the empty set, and deleting from a singleton produces the empty set. But and violate exchange: neither nor can be added to . Thus it is not a matroid.
The descending-weight greedy algorithm admits first, then rejects both and , returning with weight . Exchanging the tied order of changes nothing. The admissible pair weighs , exceeding every singleton and the empty set, so it is the true optimum. Both and are maximal elements under inclusion of subsets, but only the pair has maximum cardinality. This identifies exactly where the matroid greedy algorithm loses its guarantee: heredity preserves admissibility under deletions, while exchange prevents a locally maximal selection from being too small.
A matroid is an independence system in which a smaller admissible selection can always grow using an element of a larger admissible selection. This exchange rule abstracts linear independence of vectors and the selection of edges forming a forest. It forces all matroid bases to have the same cardinality and makes the matroid greedy algorithm correct for maximizing their total weight. The useful surprise is that local choices become globally optimal because of a structural rule about admissible subsets, rather than a special numerical coincidence.
The weighted three-vector matroid below lets us inspect every subset and every possible size comparison. Its three vectors give three two-element matroid bases, yet their total weights differ. The graphic matroid of a graph triangle has exactly the same admissible labels. A pregeometry is a finitary closure-theoretic extension to possibly infinite sets.
For a finite matroid , the convex hull of the indicator vectors of its matroid independent sets is exactly the displayed system, where . It is an integral polytope. The equality instead gives the face corresponding to matroid bases; independence does not require that equality.
Proof. If is independent, , so every independent indicator and every convex combination of them satisfies the inequalities. For the reverse inclusion, take an arbitrary real objective . List its positive coordinates in nonincreasing order as , put and let be the first elements in this ordering. Run the matroid greedy algorithm on these elements, obtaining an independent set . At every prefix the selected elements are maximal in : an earlier rejected element cannot become admissible after further additions, by heredity. The augmentation axiom implies that every maximal independent set in has size . Hence .
For every point satisfying the displayed system, nonnegativity and telescoping giveThus every linear objective is maximized by an independent indicator, with the empty set used if all coefficients are nonpositive. Singleton rank inequalities bound every coordinate between zero and one, making the system compact. If it contained a point outside the compact convex hull of independent indicators, the finite-dimensional separating hyperplane theorem would supply an objective strictly larger at that point than at every independent indicator, a contradiction. This proves equality and integrality without assuming the desired convex-hull description in advance. Negative objective coefficients are discarded explicitly; maximizing over independent sets differs from maximizing over bases when such coefficients occur.
For an undirected finite graph, its forest polytope is the matroid independence polytope of its graphic matroid. It has the exact inequality descriptionsHere counts all connected components of a graph, including isolated vertices, and denotes the edges internal to . A maximal forest has one fewer edge than vertices in each component, giving the rank . The matroid independence polytope theorem therefore proves the first description. It implies the second since the rank of is at most . Conversely, split any into its vertex components ; nonnegativity gives . No spanning requirement is imposed, so an optimum with negative edge weights can leave vertices isolated.
On labelled ground sets of sizes , there are respectively matroids, or up to matroid isomorphism. At rank of a matroid one, a nonempty subset of nonloops specifies all matroid independent sets of cardinality one. On three labels at rank of a matroid two, the three types are one matroid loop with an independent pair, no matroid loops with one pair of parallel elements of a matroid, and all pairs independent with the triple dependent.
The closure of a matroid obeys the displayed exchange rule. This is the finite pregeometry exchange principle: if adding newly makes dependent, then adding also makes dependent.
Proof. Write . The first hypothesis and the one-element bound on the rank of a matroid give . The second gives . Inclusion gives , so equality holds. This is exactly .
The closure of a matroid adds all elements that fail to increase its rank of a matroid. It abstracts the linear span in a linear matroid. It is extensive, preserves inclusion, preserves the rank of a matroid, and is an idempotent function:Proof. Extensivity follows from when . If and , submodularity of matroid rank gives . Thus an element in also lies in ; the case is automatic. Add the finitely many elements of one at a time. Inclusion preservation makes each addition have zero marginal increment of the rank of a matroid, proving rank preservation.
For completeness, nested subsets of equal rank of a matroid have the same closure of a matroid. If , apply submodularity of matroid rank to and to obtain ; monotonicity gives the reverse bound. The defining tests for membership in their closures are therefore equal. If , , so both closures contain . Apply this equal-rank result to to prove idempotence. In particular, every maximal matroid independent set of has the same closure of a matroid as .
For , the uniform matroid on an -element ground set has as its matroid independent sets exactly the subsets of cardinality at most . Heredity is immediate, and augmentation works because any smaller such subset can acquire an element of a larger one without exceeding . Its rank of a matroid on is .
Distinct nonloops are parallel elements of a matroid when their pair is dependent. Declaring each nonloop parallel to itself makes parallelism an equivalence relation on the nonloops. Transitivity follows directly from augmentation: if and are dependent but independent, the independent singleton could not be augmented from the independent pair , contradicting the matroid independence axioms. In a linear matroid, nonzero proportional vectors give parallel elements of a matroid.
A matroid dependent set is a subset of the ground set that is not a matroid independent set. By heredity, every subset containing a matroid dependent set is also dependent. Distinct nonloops are parallel elements of a matroid exactly when their pair is a matroid dependent set.
A nonloop is an element whose singleton is a matroid independent set. It is precisely an element that is not a loop of a matroid, and its singleton has rank of a matroid one.
An element is a loop of a matroid when its singleton is not a matroid independent set. By heredity, no matroid independent set contains it. Equivalently its singleton has rank of a matroid zero, or it belongs to the closure of a matroid of the empty set. In a graphic matroid, a self-loop is a loop of a matroid.
A matroid isomorphism between and is a bijection such that if and only if . It relabels the ground set without changing independence. The number of labelled matroids therefore differs from the number of types up to matroid isomorphism.
Let be a finite set and a family of subsets, where is the power set. The matroid independence axioms areThe second condition is heredity; the third is exchange, also called augmentation. The set difference matters: the new element must actually increase the cardinality of . Exchange adds one element without requiring any deletion from . Nonemptiness together with heredity is equivalent to the first condition. [ref]
A matroid independent set is a subset belonging to the family . Independence refers to the chosen matroid: for a linear matroid it means linear independence, and for a graphic matroid it means that the chosen edges contain no graph cycle. It is different from an independent set, which selects vertices with no edge between them.
A matroid basis is a matroid independent set that is a maximal element under inclusion of subsets: no additional element of the ground set can be admitted. Maximum cardinality means having the largest size among all matroid independent sets. Maximality tests whether this particular selection can grow; maximum size compares it with every selection. In a matroid the two conditions coincide, so all matroid bases have a common size. They need not have equal weight. [ref]
Matroid optimization by Michel Goemans. Michel X. Goemans, Matroid optimization, section 5.1, p. 1, maximal independent sets and bases
Proof outline. If a maximal matroid independent set were smaller than another matroid independent set , the matroid independence axioms would admit an element of , contradicting maximality. Finiteness allows every matroid independent set to grow to a matroid basis by successive admissible additions. In a general independence system, maximal selections can have different sizes, as in the hereditary nonmatroid greedy obstruction.
For a subset of the ground set, the rank of a matroid on is the maximum cardinality of a matroid independent set contained in :Thus is the common size of the matroid bases, and . The weighted three-vector matroid has , even though its ground set has three labels.
On a finite ground set , a submodular rank function is a normalised set function with , a monotone set function, and a submodular set function, such that for . Equivalently, require nonnegative integer values, monotonicity, submodularity and . The diminishing returns characterization of submodularity bounds each marginal by its singleton value. Thus .
These functions are precisely the rank functions of matroids. To see the converse direction, define . It contains the empty set. If , the unit marginal bounds give , so and heredity holds. For augmentation, suppose with . If every had zero marginal over , diminishing returns would keep each marginal zero as they are added successively. This would give , contradicting monotonicity. Some marginal is therefore one, giving an independent augmentation.
Finally any inclusion-maximal in this independence family has for every remaining . Successively adding them and using diminishing returns shows , so the resulting matroid really has rank . The forward direction is submodularity of matroid rank. These integer increment conditions distinguish matroid ranks from arbitrary real-valued submodular functions.
The rank of a matroid is a normalised set function, a monotone set function, and a submodular set function. Adding one element increases it by at most one.
Proof of submodularity. Choose a maximal matroid independent set in , extend it to a maximal matroid independent set in , then extend it to one in . The matroid independence axioms make their sizes , and . Every element of lies outside , since otherwise it could be added to inside . Hence is an independent subset of , so its size is at most .
The remaining assertions follow from the definition of the rank of a matroid. The empty set has maximum independent size zero, increasing the available subset cannot reduce that maximum, and deleting a newly added element from an independent subset decreases its size by at most one.
A linear matroid has a finite ground set indexing a family of vectors in a vector space over a specified field. A subset of labels is a matroid independent set precisely when its vectors are linearly independent. Labels distinguish repeated vectors; the ground set is not required to consist of distinct numerical vectors. The matroid bases correspond to bases for the linear span of all the supplied vectors.
Exchange outline. The linear span of linearly independent vectors has dimension . If , not all the linearly independent vectors indexed by can lie in that linear span. A vector outside it can be added to . Heredity follows because a linear dependence in a subset would also be a linear dependence in the full selection.
Take labels and vectors in the real vector space :Here is the complete independence check for all eight subsets. The empty set is independent. Each of is independent because its vector is nonzero. Every pair is independent: the determinants of the two-column matrices , , and are respectively , , and . The triple is dependent because . ThereforeDeleting elements from any listed subset stays in this list, verifying heredity. Every exchange comparison has sizes , , or . From the empty set, any element of the larger matroid independent set works: this covers three singleton targets and three pair targets. From any singleton to any pair, every element of the pair outside the singleton works, since every resulting pair is independent. This covers all nine singleton-pair comparisons, including disjoint ones. There are no other comparisons: all fifteen ordered size-increasing pairs satisfy exchange.
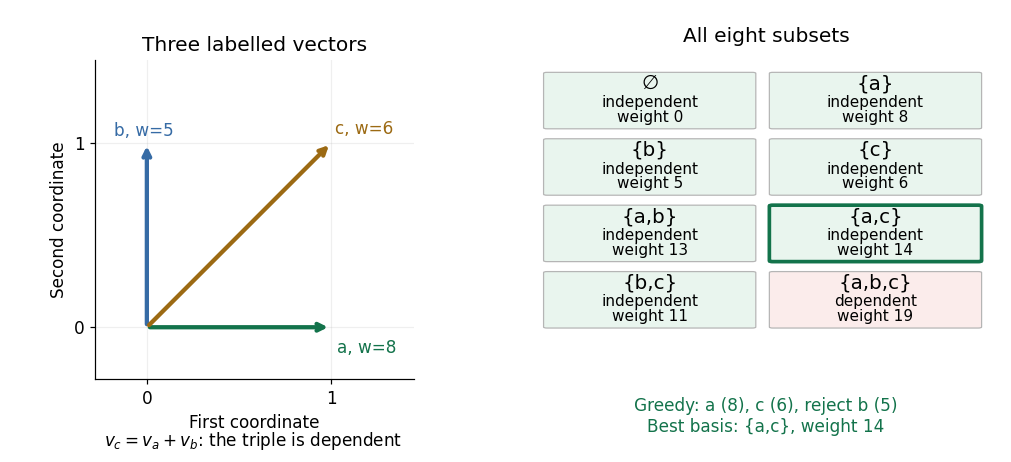
Three vectors have three independent pairs and one dependent triple; the heaviest matroid basis is with weight
. Details. The three matroid bases are , , and , all of cardinality two, with weights , , and . The matroid greedy algorithm considers , then , then : it admits , admits because their determinant is nonzero, and rejects because the triple is dependent. The resulting matroid basis has weight , the largest of the three totals. Every singleton can grow, so none is maximal; the three pairs are both maximal and maximum in cardinality.
For a finite undirected graph, the graphic matroid has its edges as the ground set. A subset is a matroid independent set when its edges form a forest on the original vertices, including isolated vertices. Its matroid bases give a spanning tree in each connected component of a graph; for a connected graph, each matroid basis is a spanning tree.
For a graph triangle on vertices , label the edges , , and , with weights . The empty set, all singletons, and all pairs are forests; the triple contains the graph cycle . Thus its eight subsets have exactly the independence pattern checked in the weighted three-vector matroid, and the same fifteen exchange comparisons pass. The matroid greedy algorithm chooses , chooses , and rejects , producing the heaviest spanning tree, of weight .
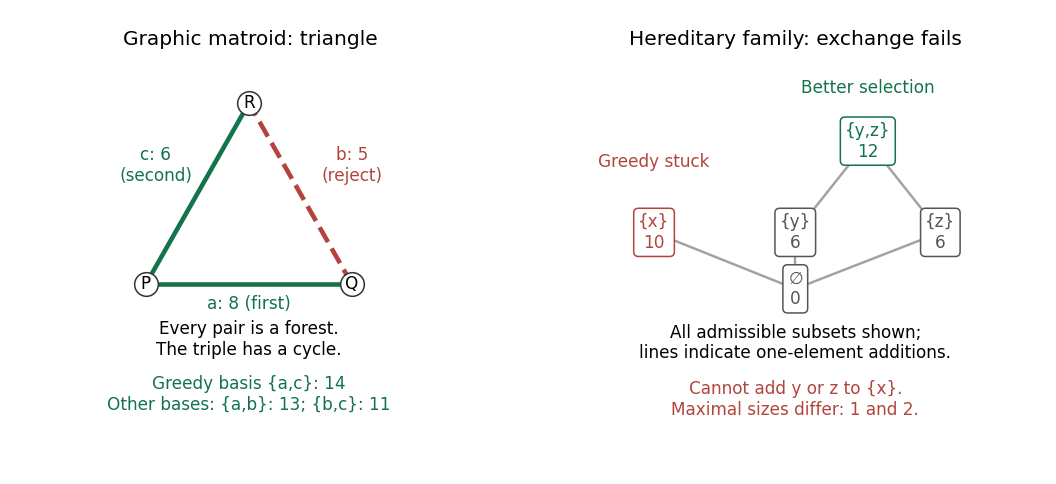
A weighted graph triangle admits greedy selection of a matroid basis; a hereditary independence system without exchange traps a greedy algorithm at weight instead of
. Details. Exchange outline. Deleting edges cannot create a graph cycle. If forests have , some edge of joins different connected components of a graph of : otherwise, within each such component, would have at most its number of vertices minus one edges, giving . Adding that edge keeps a forest. This is the matroid independence axioms expressed through connectivity.
Assign each element of the finite ground set a real number . The matroid greedy algorithm sorts elements by nonincreasing weight, starts with the empty set, and admits an element exactly when the enlarged selection is a matroid independent set. Ties can be resolved arbitrarily. After all elements have been considered, the result is a matroid basis of maximum total weight among all matroid bases. This holds even with negative weights: the task is to produce a full matroid basis. [ref]
Maximizing weight over all matroid independent sets is a different task when weights can be negative. For that task, skip negative elements; zero-weight additions are optional. With weights , , in the weighted three-vector matroid, the heaviest matroid basis is with weight , while the heaviest matroid independent set is with weight . For nonnegative weights, every matroid independent set can be extended to a matroid basis without reducing weight, so the optimum values coincide.
Proof outline. Let be the admitted elements in order, and order any competing matroid basis by nonincreasing weight. If , exchange would let one of augment . That element was considered before and, by heredity, was admissible even at that earlier stage, a contradiction. Hence for every , and summing proves optimality. Rejected elements remain inadmissible as the selection grows, by heredity, so the final selection is maximal. The guarantee depends on the matroid independence axioms and on weights adding independently across elements; interactions between chosen elements are a different objective.
For finite sets, the number of ordered choices of one element from each is the product of the individual numbers of choices. More generally, if stage has exactly possible choices after every permitted history of earlier stages, the total number of full choice sequences is , by mathematical induction on the stages. This counts functions between sets of sizes , and counts the injective functions by the falling factorial when .
With five people, choose a captain in five ways and a different deputy in four ways: ordered assignments. The second choice depends on the first because the captain is excluded, but its number of permitted options is always four. The rule of product therefore applies without any assumption about independent events. To count two-person teams instead, each subset has two possible role assignments, so division by gives ten teams. This division works because every team was counted equally often.
The rule of sum counts alternatives in disjoint finite sets by adding their sizes. For a disjoint union , each element belongs to exactly one alternative, so . Overlapping alternatives require accounting for repeated elements, as in the inclusion-exclusion principle. The groups indexed by first-return position in the Catalan recurrence are disjoint alternatives.
A Steiner system is a -point set with -point blocks such that every -point subset is contained in exactly one block. Necessarily the number of blocks is . This count is a necessary consistency check, not a substitute for proving exact containment. The small Witt design is .
A designated subset in a Steiner system is a Steiner block. In a system , each Steiner block contains points and each -point subset belongs to exactly one Steiner block. For , this is the pair-coverage condition used in a cyclotomic construction of a Steiner 2-design.
In a finite additive group, a family of -subsets is a difference family of index one if each nonzero group element occurs exactly once among all their ordered within-block differences. Translating its Steiner blocks by every group element gives a Steiner system with parameters -: the unique representation of a difference determines the unique translated Steiner block through two specified points.
Put , take odd , and let be the index- multiplicative subgroup. If a -set has its unordered pair differences in distinct -cosets, choose containing exactly one element from each pair . Then is a difference family for a Steiner 2-design. Indeed one unordered pair supplies each coset, and its two difference orientations multiplied by cover that coset once. Translations yield a - Steiner system. The cyclotomic pattern extension by a second-moment bound supplies suitable for all sufficiently large in this progression.
The small Witt design is a Steiner system with 132 blocks. A six-set duad-syntheme duality constructs it on two disjoint six-sets: two whole-half blocks, forty-five blocks of each of the types and , and forty corresponding-partition blocks of type . The internal-duad/cross-syntheme incidence rule proves that each five-set lies in exactly one of these blocks.
On a six-point set and its six totals of synthemes , each duad determines a partition of into three pairs according to their shared synthemes. Include both whole halves, the 45 blocks for these duad-pair incidences, and their complements. For each partition into triples, cross synthemes give two triangular components on ; include the four unions of a part of with a component. These 132 blocks form the small Witt design.
The complete graph on six points has fifteen edges and fifteen perfect matchings. Its six one-factorizations organize a dual incidence geometry exchanging points with factorizations and edges with matchings. The classical names are duads, synthemes and totals of synthemes. This geometry supports duad-syntheme duality on six points and a construction of the small Witt design.
The six pentads are the six one-factorizations of the complete graph on six points. Permuting the ground-set points permutes these factorizations. The action sends a transposition to three disjoint transpositions and a -cycle to two disjoint -cycles. Its restriction to is faithful by simplicity, and the full action of is faithful because an order-two kernel would be central. It is consequently an automorphism of . Its restriction preserves and changes -cycle type, so it cannot be induced on by any conjugation from .
A bijection from the points of one six-set to the totals of another extends by incidence to bijections from duads to synthemes, synthemes to duads, and totals to points. A duad maps to the intersection of its two point-totals. The same duality exchanges internal duads of a three-versus-three partition with cross synthemes of its corresponding partition. The latter rule follows by splitting the six cross perfect matchings into parity classes of three, yielding two triangles on the six totals.
A duad is an unordered pair of distinct points. On a six-point set there are duads. They are the edges of the complete graph and are grouped into synthemes.
A syntheme partitions six points into three duads, equivalently a perfect matching of the complete graph. There are synthemes. Every duad belongs to three. Two edge-disjoint synthemes extend to a unique total of synthemes: their union is a six-cycle, whose complement has a unique factorization into three matchings.
A total is a set of five edge-disjoint synthemes covering all fifteen duads of a six-point set. There are six totals; each syntheme belongs to two and every two totals share exactly one syntheme. Each total contains exactly one syntheme containing any prescribed duad. Totals are one-factorizations of the complete graph.
Two disjoint synthemes form a six-cycle, whose complement is a triangular prism. The prism has a unique partition into three perfect matchings, so the pair extends uniquely to a total of synthemes. Eight synthemes are disjoint from a fixed syntheme; grouping them four per total yields two totals through it, and double counting gives six totals in all.
// Target: combinatorics.bigb
The cycle lemma turns a constraint at every prefix into a choice of where to start reading a circular sequence. Think of a lattice path whose vertical increments record votes for two candidates: for one candidate and for the other. Its partial sums are the running lead. Rotating the increments preserves the final lead, but changes whether that lead stays strictly positive throughout. This makes rotation useful for counting lattice paths subject to prefix constraints; the sum-one cycle lemma also supplies the cyclic prefix condition in the cyclic Turán covering construction.
The sum-one form. Let be any nonempty sequence of integers with . A starting position means reading the rotated sequenceCall good when every nonempty partial sum of is strictly positive, including the full sum:The cycle lemma says there is exactly one good starting position. Negative entries, zero entries and positive entries larger than one are all allowed in this sum-one form. The empty partial sum is zero and is excluded from the positivity requirement. Douglas West's exercise 1.3.46(a) states a stronger result for arbitrary integer entries: take its case with all partial sums positive. [ref]
https://api.pageplace.de/preview/DT0400.9781108889520_A49236431/preview-9781108889520_A49236431.pdf#page=72. West, Combinatorial Mathematics, exercise 1.3.46(a), p. 50
A worked sum-one example. For , the partial sums starting at zero are . Starts fail: they have, respectively, a zero second partial sum, a negative first partial sum, and a zero first partial sum. Start reads and has nonempty partial sums , all positive. This example both allows an increment larger than one and shows why touching zero fails.
Why the last minimum works. Put and . Choose the last index attaining the minimum of the proper partial sums : include and exclude . After that index, later proper partial sums are strictly larger than ; also , since . Before wrapping, the new partial sums are therefore positive differences . After wrapping, they are . In the worked example the last minimum is at ; choosing the first minimum at would fail. Uniqueness takes one further observation: two good starts would split the circle into two nonempty arcs, each having a positive integer sum, yet their sum would be one.
A standard positive-total form of the Dvoretzky-Motzkin cycle lemma uses a nonempty sequence of integers satisfyingExactly starting positions have every nonempty partial sum strictly positive, using the same rotation convention as the sum-one cycle lemma. Negative entries can be arbitrarily large in magnitude, and zero entries are allowed. Addario-Berry's proposition 2.2.1 gives an equivalent form with increments at least and negative total; reversing the sequence and changing all signs gives the form here. [ref]
https://problab.ca/louigi/notes/ssprob2021.pdf#page=39. Addario-Berry, Lecture notes: 2021 CRM-PIMS Probability Summer School, proposition 2.2.1, p. 39
Four starts, two successes. For , the sum is . Starts and give partial sums and , respectively. Start gives and touches zero; start gives and begins below zero. Thus exactly two starts are good. The rotated sequence has the same positive total, but its first start is bad: a positive final lead alone does not control earlier partial sums.
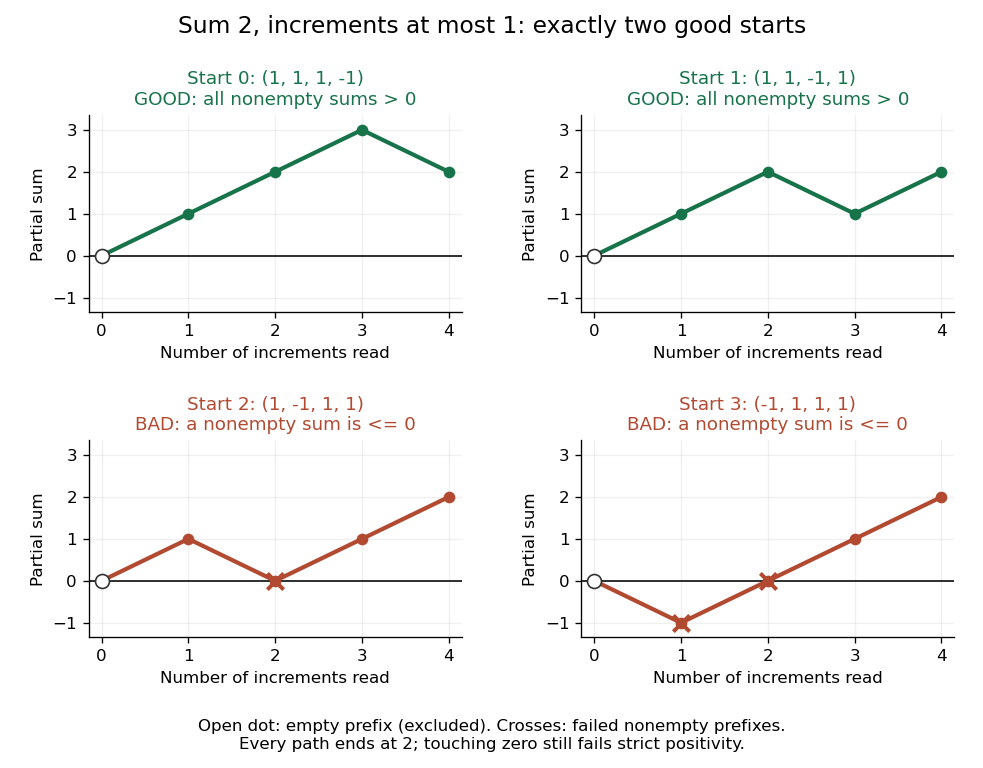
All four starts of : the cycle lemma with increments at most one counts precisely the two paths whose nonempty partial sums stay strictly above zero
. Details. Positions can give identical words. The sequence repeats a block of length three and has sum two. Its good starts are and , both giving the same word with partial sums . Starts and touch zero; starts and begin negatively. The cycle lemma with increments at most one counts two starting positions even though there is only one distinct good rotated word. Counting distinct words would lose the multiplicity that makes the statement true.
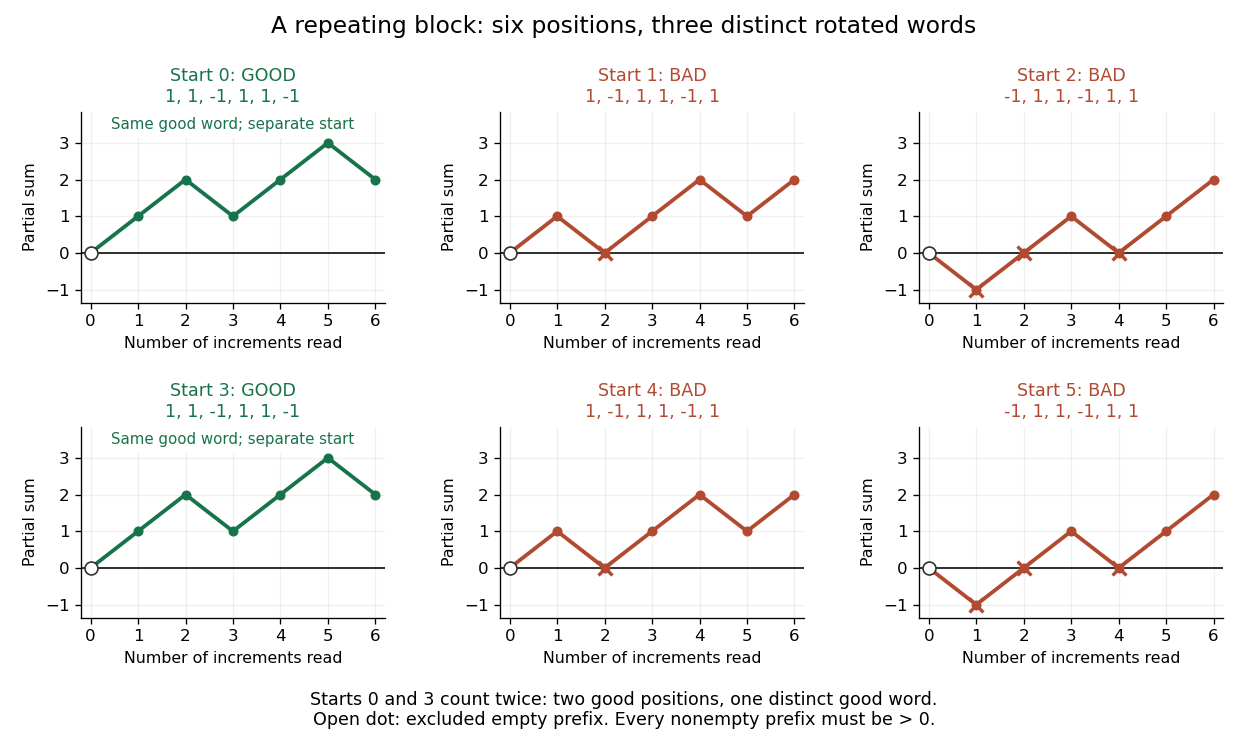
Six starting positions of the repeating sequence : starts and produce identical good words and count twice
. Details. The upper bound matters. The one-entry sequence has positive integer sum two, but only one starting position. Thus the sum- conclusion fails for arbitrary positive increments when . The sum-one cycle lemma above needs no such upper bound. Strict positivity also matters: counting paths that merely stay at or above zero would include additional starts in both diagrams.
From rotation to enumeration. For a fixed admissible sequence, a start chosen from a uniform distribution on a finite set of its positions is good with probability . More generally, let be any finite set of length- sequences satisfying the increment bound and total , closed under rotation. Double counting pairs consisting of a sequence and a good starting position givesFor each good output sequence and each of the positions, inverse rotation gives one such pair, even when several rotated words coincide. For example, the four sequences containing three votes and one vote have exactly vote orders with a strictly positive running lead: and . This is how the cycle lemma with increments at most one converts many prefix inequalities into a simple counting factor.
A cyclic digit run is a consecutive segment of a digit string whose successive digits all increase by one or all decrease by one modulo the base. For example, is an increasing decimal run. This refers to cyclic digit values, not to joining the final position of the string back to its first position. Overlapping run constraints can be counted with the inclusion-exclusion principle.
Finite geometry studies geometric incidence structures having finitely many points, such as finite projective and affine spaces.
An increasing subsequence of a finite sequence in a totally ordered set selects indices such thatHere “increasing” means weakly increasing, also called nondecreasing: equal values are allowed, but indices must increase strictly. This is the convention of [ref]
https://cs.carleton.edu/faculty/dlibenno/papers/lis-lcs/lislcs.pdf. Liben-Nowell, Vee and Zhu, Finding Longest Increasing and Common Subsequences in Streaming Data, section 1
. A strictly increasing subsequence instead requires . Always check which convention an algorithm uses, especially when values repeat.An increasing subsequence may skip positions; it neither rearranges values nor requires consecutive positions. Consider the deliberately constructed exampleThe indices select , an increasing subsequence of length four. The indices select , a strictly increasing subsequence of length three. In contrast, rearranges the input and is not a subsequence. The longest consecutive nondecreasing block is , of length three; requiring consecutive positions would therefore solve a different problem.
Think of an increasing subsequence as preserving ordered observations while skipping interruptions. For the example, discarding leaves four observations with no downward step. The longest increasing subsequence asks how much of the original order can be kept. This is an order comparison, rather than a claim about the size of upward or downward changes: replacing all values by their squares when the values are nonnegative leaves every allowed selection unchanged. More generally, any strictly order-preserving relabeling has this property.
A longest increasing subsequence is an increasing subsequence of maximum length. Write that length as , with for the empty sequence; a nonempty input has . Several selections can attain the same maximum. Here uses the weak convention ; write for the maximum length of a strictly increasing subsequence. For , these lengths are three and one respectively; for an input with distinct values they agree.
For , the answer is , attained at indices , while . One useful interpretation is the smallest number of deletions needed to make the surviving sequence nondecreasing:Indeed, keeping a longest increasing subsequence attains this bound, and any valid remaining sequence is an increasing subsequence, so cannot have more than terms. In this example the answer is . This makes a measure of how much order can be recovered without moving any observation.
A table that ends at each position. Let be the maximum length of an increasing subsequence ending specifically at position . The dynamic programming recurrence relation isThe zero covers a selection consisting only of . Otherwise its penultimate index is an eligible ; append to an optimal selection ending there. Fill entries in increasing index order. For strictly increasing subsequences, change the comparison to . The strict version and reconstruction are developed in University of Toronto, CSC373 tutorial 4 solutions (2018), exercise 2; the weak version follows by allowing equality at the append step.
In the worked input, the weak table is and the strict table is . At the second , equality extends the first in the weak table. The final entry is only one, although the optimum is four: the best increasing subsequence need not finish at the last input position. Record a maximizing predecessor whenever . Following these stored indices from any position maximizing , then reversing them, gives an actual longest increasing subsequence. For the weak example the backward chain is .
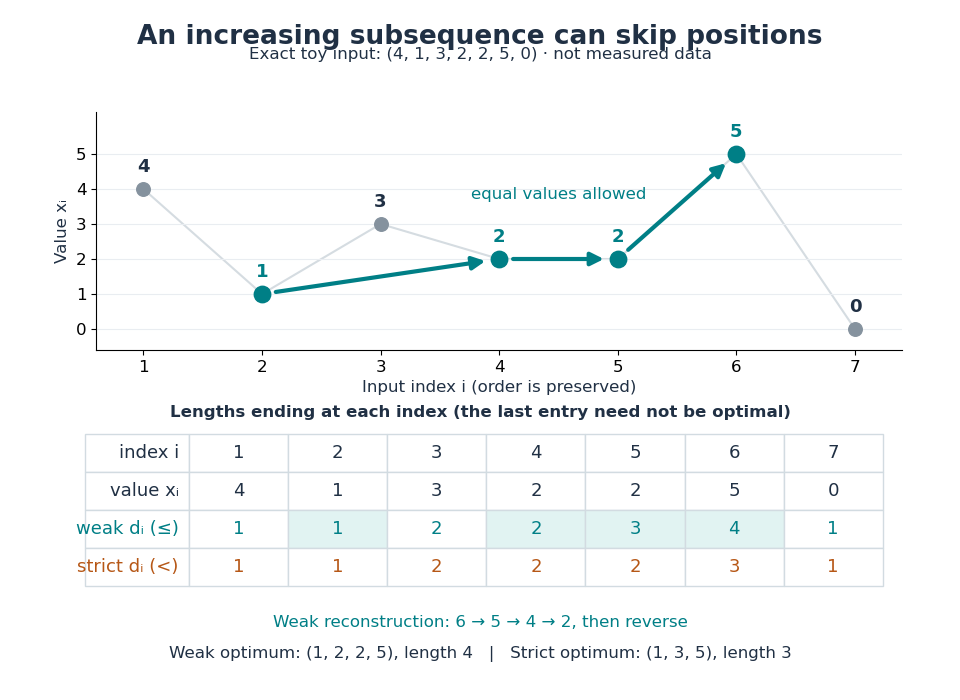
Skipping positions and allowing equal values changes the optimum
. An original toy input, not measured data. The colored selection keeps indices and values . The two dynamic programming rows give the best lengths ending at every position; the backward arrows reconstruct the weak longest increasing subsequence. Details.Scanning all earlier positions for each uses time complexity and space complexity for lengths and predecessors, using Big O notation and assuming constant-time comparisons and operations on indices.
Keep the easiest ending to extend. The faster algorithm maintains a minimum-tail table for increasing subsequences: is the smallest final value of any length- increasing subsequence in the processed prefix. For equal lengths, a smaller ending permits every future extension allowed by a larger ending. Thus only one best ending per length is needed. The table is nondecreasing, since removing the last term of a length- selection gives . Start with an empty table. On reading , use binary search to find the first entry strictly greater than : replace it by , or append if there is no such entry. Its position is one beyond the longest existing length whose ending is at most . See Liben-Nowell, Vee and Zhu, section 3.1 and Figure 1.
Duplicates determine the binary search rule: weak increase replaces the first , whereas strict increase replaces the first . In Python these positions are returned by
bisect_right(T, v) and bisect_left(T, v) respectively, counting positions from zero. Replace an entry or append; do not insert and shift the remaining entries. The documented equality rules are in Python documentation, bisect_left and bisect_right. Each search takes comparisons, giving time complexity , conventionally for , and space complexity for the weak length alone.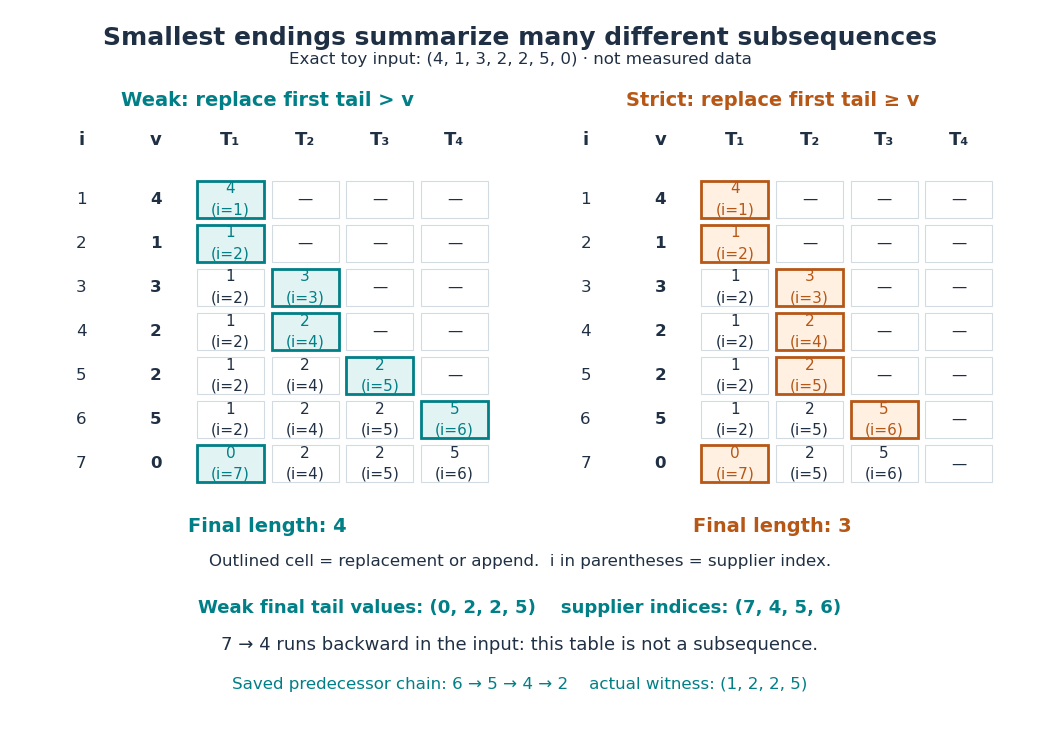
Two binary-search tie rules give different minimum-tail tables
. Original exact traces for the same toy input, not measured data. Each cell shows a tail value and the input index supplying it; the outlined cell was updated in that row. At the second , the weak algorithm appends and the strict algorithm replaces. The final weak table has length four, but its supplier indices are not in increasing order. Details.A length certificate needs separate reconstruction. The final weak tail values are , but they do not form an increasing subsequence of this input: the zero occurs last. Each table entry certifies a selection of its own length; the entries need not come from one compatible selection. To recover a longest increasing subsequence during the fast algorithm, store a supplier index for each tail and a predecessor index for each input position. Before replacing slot , save , or no predecessor if , then set . Later replacements leave saved unchanged. Follow predecessors from the final and reverse. This uses space complexity and returns indices for the weak trace. The same construction works with the strict comparator; compare the two auxiliary arrays in CP Algorithms contributors, restoring the subsequence after binary search.
Deleting or changing one term. If deletes position , thenDeleting cannot create a longer increasing subsequence; removing position from a previously optimal selection loses at most one term. If instead changes just the value at position , both inputs have the same deleted sequence, so their lengths each lie between its length and its length plus one. Consequently . These bounds also hold for strictly increasing subsequences. In the weak example, deleting either lowers the length to three, while deleting the final zero leaves it four. This is a Lipschitz bound for single-term edits, regardless of the numerical size of a replacement. Insertion has the same bound by reversing deletion, so insertions, deletions or replacements can change by at most .
For historical context, [ref]
https://doi.org/10.1016/0012-365X(75)90103-X. Fredman, On computing the length of longest increasing subsequences (1975)
studies the comparison count for distinct elements of a totally ordered set. Its distinctness assumption makes the weak and strict conventions coincide. No distinctness assumption is needed for the comparator-specific algorithms above.For a processed prefix , the minimum-tail table for increasing subsequences storesThere is no slot for an unattainable length. The table records minimum endings, rather than the terms of one longest increasing subsequence. Replacing the value comparisons by gives the corresponding table for strictly increasing subsequences, whose entries are strictly increasing.
For a permutation input, the first row of its RSK insertion tableau is the minimum-tail table for increasing subsequences: its th entry is the least attainable final value of a strictly increasing subsequence of length in the processed prefix. Inserting replaces the first entry larger than , or appends if none exists. In replacement position , the previous entry in position supplies a subsequence that can be extended by . Shorter minimum tails were already smaller, and a longer subsequence ending at would require an old tail in position at least smaller than , contrary to the replacement rule. This proves the invariant inductively. Consequently the first-row length is the longest increasing subsequence length. The row entries need not be a subsequence together: input gives first row , although one occurs after three. They are minima for different lengths, obtained from potentially different subsequences.
A strictly increasing subsequence selects indices of a sequence with . Equal values cannot both occur in it. Its maximum possible length is , with ; in general for the weak longest increasing subsequence. Use strict comparisons in the dynamic programming recurrence relation and replace the first tail at least as large as the next value in the binary search algorithm.
Additive combinatorics studies how the cardinalities and sumset representation functions of sumsets reveal structure in finite sets contained in abelian groups. Write the group operation as addition: the ambient abelian group may be the integers , a finite cyclic group, or another abelian group. The same definitions apply, but the ambient group changes which bounds are possible.
The basic experiment is to add every ordered pair of members of a finite set. The sumset records the distinct answers; the sumset representation function records how often each answer occurs; the additive energy counts coincidences between those answers. An arithmetic progression produces many repeated sums, so its sumset grows slowly and its additive energy is relatively large. The doubling constant measures that growth relative to the original cardinality.
The examples below compare the arithmetic progression with the more spread-out integer set . Their four members give sixteen ordered pairs in each case, but different numbers of distinct sums. This small comparison illustrates the definitions; it does not establish a claim about arbitrarily large sets. For a systematic introduction, see Tao and Vu's author page for Additive Combinatorics, with free sample chapters on sum set estimates and additive geometry.
The multidimensional Szemerédi theorem says that a subset with positive upper density contains a translated positive integer dilate of every finite set . In the finite formulation, for every and finite , all sufficiently large integer boxes have this property for every subset occupying at least an fraction of the box. The one-dimensional case for is the Szemerédi theorem. The general result follows from multiple recurrence for commuting measure-preserving transformations.
A frequency function built from an affine variable and its fractional part. Irrational and can give many exact additive relations because each pair sum has only two possible floor carries. For example , gives additive quadruples on , but agreement with every ordinary affine function occurs on only shifts. Integer floor points underlying affine agreement must be collinear.
Use four parts indexed by in a cyclic group , and include the triple missing part when . A transversal three-uniform tetrahedron then has the four values , where and , so it encodes a four-term arithmetic progression. Constant progressions give edge-disjoint tetrahedra. This is the bridge from the tetrahedron removal lemma to the Szemerédi theorem.
For every , every sufficiently long integer interval has a nonconstant three-term arithmetic progression in each subset of subset density at least . This is a theorem about additive combinatorics, distinct from the Roth theorem on approximation of algebraic irrational numbers. The Roth density-increment step proves it by repeatedly increasing subset density on a shorter arithmetic progression.
If a density- subset of a sufficiently long integer interval has no nonconstant three-term arithmetic progression, Fourier expansion of the progression count gives a large coefficient of its balanced indicator. Dirichlet approximation supplies a step at most on which that character varies slowly. Partitioning the interval into equal-length progressions of that step, and controlling the short tails, produces the displayed density increment. Iteration must terminate since density cannot exceed one. The same argument treats the three-point pattern with coefficients .
Embed in the odd cyclic group , so additive three-term relations in cannot wrap around. Form three copies of , putting edges when , when , and when . A triangle in a graph encodes in . If has no nonconstant arithmetic progression, every triangle in a graph has ; there are exactly triangles in a graph, and they are edge-disjoint. Thus at least edges must be removed to eliminate them. For fixed positive subset density of , this is a positive fraction of the squared vertex count, whereas the triangle in a graph count is only quadratic. The triangle removal lemma permits deletion of an arbitrarily small quadratic fraction when the cubic triangle in a graph subset density is sufficiently small. This contradiction establishes Roth theorem on three-term arithmetic progressions.
Write for the maximum cardinality of a subset of containing no nonconstant three-term arithmetic progression. There is an absolute constant such that every three-term-progression-free subset satisfies for . A quantitative Roth density-increment step gives, for subset density and , a arithmetic progression of length at least and increased subset density at least . The increment decreases reciprocal subset density by at least , so fewer than iterations are possible. If is the successive length, then , using the initial subset density to bound all later ones. Hence . If exceeds a sufficiently large absolute constant, all these intervals remain above the density increment threshold, a contradiction. This proves the displayed bound. The result is a classical quantitative version of Roth theorem on three-term arithmetic progressions, without asserting an optimal bound.
For fixed , a sufficiently large finite set of integers with additive energy at least has a nonconstant three-term arithmetic progression. The Balog-Szemerédi-Gowers theorem and Ruzsa modelling lemma reduce the problem to the Roth theorem on three-term arithmetic progressions in a dense cyclic model.
The product set of two sets of real numbers is . It is a multiplicative counterpart of a sumset, not the Cartesian product .
For finite sets of nonzero real numbers, the multiplicative energy is the number of quadruples satisfying . Swapping shows that it also counts quadruples with . Thus , where counts product representations. The Cauchy-Schwarz inequality yields .
For finite sets of positive real numbers with , , with natural or binary logarithm. Partition ray occupancies of into classes of multiplicative width , or width for the binary convention. Injectivity of sums on two distinct rays and disjoint open planar sectors bound each class's sum of squared occupancies by . A singleton class contributes at most . Combining this with the energy lower bound gives a sum-product inequality.
A corner consists of these three points in the integer grid, all contained in the set being studied. The displacement may be positive or negative, but must be nonzero, so the points are distinct. The corners theorem guarantees a corner in every subset of positive fixed density of a finite subset of a sufficiently large square grid.
For every , all sufficiently large integers have the property that every with contains a corner in an integer grid. The tripartite graph encoding of a grid turns the absence of a corner into a family of many edge-disjoint triangles but only quadratically many total triangles in a graph, contradicting the triangle removal lemma.
For a real-valued function on a nonempty finite Cartesian product , its normalized cut norm is the maximum of over . It measures all rectangular subset discrepancies. The convention using arbitrary test functions bounded by one is equivalent within a factor of four, by decomposing their positive and negative parts into indicator functions.
Non-abelian additive combinatorics studies product sets and configuration counts in noncommutative groups. Fourier analysis on a finite group and quasirandom groups connect small-dimensional group representations with multiplicative mixing.
For on a finite group, use uniform expectation over the solutions of and the ordinary, unnormalized trace to define the displayed fourth-order quantity. If is its matrix Fourier block, this quantity equals , so it is real and nonnegative. For a scalar function on an abelian group, it reduces to the usual fourth power of the Gowers uniformity norm of order two. The unnormalized trace means a unitary matrix-valued function can have fourth-order quantity as large as .
Articles were limited to the first 100 out of 977 total.
Articles by others on the same topic



Combinatorics is a branch of mathematics that deals with counting, arrangement, and combination of objects. It involves studying finite or countable discrete structures and provides tools for analyzing the ways in which various elements can be selected, arranged, and combined under specific constraints. Key areas of study within combinatorics include: 1. **Counting Principles**: This involves basic techniques like the rule of sum and rule of product, permutations (arrangements of objects), and combinations (selections of objects).