Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Variance
Independent observations with known errors add a positive-semidefinite Fisher information matrix to the existing information . Writing shows its inverse covariance cannot increase in any parameter direction. Improvement can be zero along an uninformative direction. This statement does not assume that data-dependent residual variance estimates or model systematic errors must decrease.
For independent standard normal random variables , define the displayed errors for . Each has mean zero and variance one. Nonadjacent errors depend on disjoint sets of independent variables. Adjacent covariances vanish because their product contains an independent centered factor. Thus their covariance matrix is .
They are nevertheless dependent: the Gaussian fourth moment gives , and hence . Constant variance and zero pairwise covariance can conceal dependence in magnitudes. This is useful when interpreting a residual plot in linear regression.
Adjusted coefficient of determination 2026-10-14
In a normal linear model with an intercept, observations and independent mean coefficients, adjusted isIt compares the residual variance estimate with the unmodelled sample variance, adjusting the raw coefficient of determination for fitted dimension. It can be negative and is not guaranteed to increase when another regressor is added. In penalized regression a related convention uses the fit's effective degrees of freedom instead of ; the precise smoothing-software variance convention should be specified.
Affine invariance of kurtosis 2026-10-14
Changing units or shifting the origin preserves kurtosis. For real constants and , the mean of is , its variance is , and its fourth central moment is . The factors cancel in the ratio, even for negative . Hence excess kurtosis is also unchanged. For example, and have the same kurtosis, although their means and variances differ. The case produces zero variance and is excluded.
Amplitude-squared squeezing 2026-10-20
A field-squared quadrature variance below the equal-variance coherent-state reference in this normalization. Its conjugate variance must remain compatible with the state-dependent commutator bound. This is not the same observable as ordinary field-amplitude squeezing or a reduction of mean intensity.
Anderson–Darling test Created 2026-10-14 Updated 2026-10-18
The test rejects for large values of this tail-weighted empirical discrepancy. For a specified continuous null, its standard limiting statistic is , using a Brownian bridge. The reciprocal variance weight gives tail deviations more influence than the Cramér–von Mises criterion. If null parameters are estimated, fitting must be included when computing or simulating its reference law.
For standard Cauchy distribution probability density function and , this estimates its upper-tail probability without sampling a heavy tail. The function decreases on , while increases, so their covariance is nonpositive. The paired estimator is unbiased and has no larger variance than an estimator using the same number of independent probability density function evaluations.
Antithetic variates 2026-10-14
Antithetic variates deliberately couple unbiased estimators of the same expectation with negative covariance. Their average can have smaller variance than an average using independent draws. For example, evaluating a monotone integrand at and , where has a uniform distribution, gives opposite fluctuations while preserving both marginal distributions.
For total source electrons , aperture pixels, sky-plus-dark rate , time , reads with rms , and an independent mean-background estimate of variance per pixel, the aperture variance is before additional calibration terms. The last factor is because one uncertain background mean is subtracted from all aperture pixels. Pixel correlations require covariance terms.
Approximate experimental design 2026-10-14
An approximate design is a probability measure on the design region, with weight specifying a proportion of observations at . For independent observations and common error variance , a linear regression with vector has normalized information matrix of an experimental design ; its least-squares estimator has covariance when the allocations realize these proportions. Exact designs restrict to integers.
Arcsine distribution on a bounded interval 2026-10-18
Specify whether two parameters mean endpoints or location and width. With endpoints , define for a standard arcsine distribution variable . ThenThis is a location-scale family with location and width . Its mean is and its variance is . A convention using parameters for location and width instead has right endpoint , so it must not be read as having endpoints .[ref]
The Arcsine Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Arcsine Distribution, Definition, Distribution Functions and Moments: location-plus-width convention and alternative endpoint parametrization
For example, a chosen interval gives mean and variance , while its density still concentrates toward both endpoints. It is a bounded probability distribution; its endpoint singularities do not make its support infinite.
Arcsine quantiles and moments 2026-10-18
Inverting gives the quantile functionConsequently, inverse transform sampling uses with uniform on . The quartiles are , and .[ref]
The Arcsine Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The Standard Arcsine Distribution, Distribution Functions and Related Distributions: quantiles, quartiles and random quantile construction
The first and third quartiles are about and , so the central half of the probability spans about of the unit interval. Under a uniform distribution, its width would be .
The symmetric probability distribution gives . The angle representation gives a short calculation of the second moment:Use to evaluate the integral. A uniform distribution on has variance ; the larger variance quantifies the greater spread toward the ends.
More generally, for a nonnegative integer , the beta function yieldsFor this is one; for it reproduces the values above. The central binomial coefficient thus appears in an exact moment calculation for a continuous probability distribution.
Arithmetic stock model with constant volatility Created 2026-10-06 Updated 2026-10-14
This additive price model has constant absolute volatility and can take negative stock values. With constant cash interest rate , its market price of risk is . Under an equivalent risk-neutral measure, its drift becomes , so its conditional law is Gaussian with mean and variance . It is distinct from a multiplicative Black–Scholes diffusion.
Asymptotic mean integrated squared error 2026-10-14
For a second-order kernel density estimator, write and . Under the usual smoothness and shrinking-bandwidth assumptions, the leading mean integrated squared error is the displayed sum of integrated variance and squared bias of an estimator. Its minimizer is , giving order . An added integrated covariance term is lower order at this bandwidth and does not change its leading constant.
Asymptotic mean squared error 2026-10-14
The asymptotic mean squared error is the leading large-sample approximation to the sum of variance and squared bias of an estimator. Minimizing it balances stochastic variation against systematic error; the resulting choice must still satisfy the assumptions used in the approximation.
For a normal sample of variance , define . The exact chi-squared distribution identity and the central limit theorem for independent squared standard normal random variables implyThe delta method for , with derivative , therefore gives the displayed limit for . Exact independence of the normal sample mean and sample variance also makes independent of . The resulting joint limit supports combining location and scale estimates when a model relates their parameters.
Asymptotic normality of a weighted regression slope Created 2026-10-25 Updated 2026-10-31
Suppose are independent and identically distributed with mean zero and finite variance . For deterministic weights , put . Ifthen the Lindeberg-Feller central limit theorem givesThis is the condition that no observation dominates the weighted error sum. In a centered linear regression with orthogonal explanatory columns, , so the result justifies a normal approximation with variance .
To verify the Lindeberg condition, write and . For each ,The inequality uses , and the limit follows from the finite second moment. Without the maximum-weight condition, adding observations with zero explanatory value can leave the slope determined by a fixed number of nonnormal errors for every sample size.
For fixed , a geometric mutation count in a coalescent epoch with mean has third moment . The centered absolute third moment is at most , so its sum is . The total variance is asymptotic to , making the Lyapunov condition with hold. Rescaling by the harmonic sum gives the displayed limit. At the estimator is identically zero and the limit is degenerate. The variance of the Watterson estimator decreases only logarithmically with sample size at a fixed nonrecombining locus.
Atomic compound Poisson process with drift 2026-10-06
With finitely many nonzero marks and independent Poisson processes of rates , the displayed process is a Lévy process with no Gaussian component. Its Lévy measure is , its mean is , and its variance is . Its paths have finitely many jumps on every bounded interval and deterministic slope between jumps. Coincident mark sizes combine their rates; zero marks have no effect. The drift here uses the uncompensated finite-sum convention, which differs from the drift parameter in a compensated Lévy–Khintchine formula.
Autocorrelation Created 2026-09-28 Updated 2026-10-14
The autocorrelation function of a real weakly stationary process with positive variance is its normalized autocovariance:It is dimensionless, with , , and by the Cauchy-Schwarz inequality. It is unchanged by replacing with for fixed . This makes autocorrelation useful when comparing records measured on different scales. The ACF is a property of the model; the sample autocorrelation function estimates it and will generally not reproduce theoretical zeros exactly.
An AR(1) with coefficient has autocorrelations at lags one through three. With these become : the same diminishing magnitude, alternating in sign. An MA(1) with instead has lag-one autocorrelation and zero at every higher lag. Equal numerical coefficients in an autoregressive model and a moving-average model do not mean equal dependence. See Bartlett, lecture 3: theoretical ACFs and prediction.
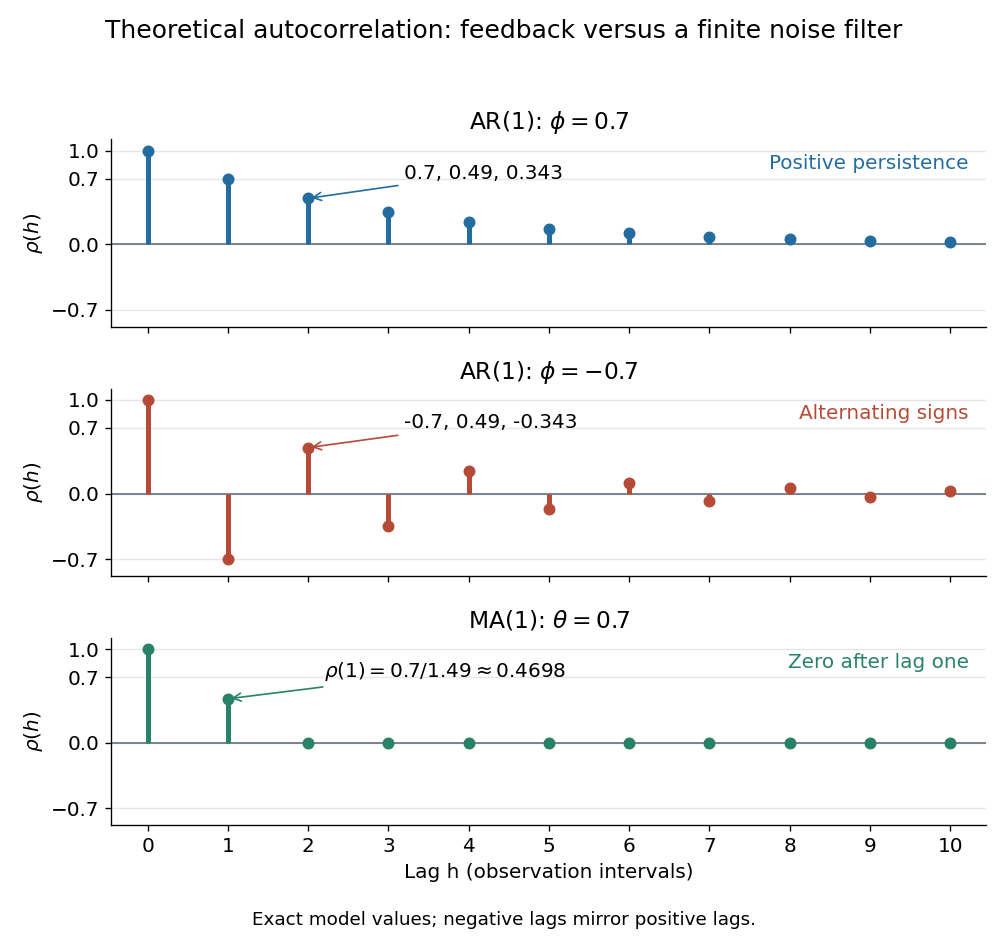
Theoretical autocorrelation: AR(1) with coefficients 0.7 and -0.7, compared with MA(1) with coefficient 0.7
. Details. 
The bars show exact model autocorrelations, not estimates from the illustrated sample paths in time series. The AR(1) retains a diminishing trace of a disturbance at arbitrarily large lags; the MA(1) stops sharing driving noise after lag one. A zero autocorrelation means uncorrelated random variables, and does not generally imply independent random variables. For a Gaussian process it does imply independence of the two coordinates.
There is a direct prediction interpretation. Among affine predictions based on just , the best linear predictor of is , with mean squared prediction error . Thus negative autocorrelation is also useful predictive information. A prediction using the whole observed past can do better; best linear prediction from a finite past describes that problem. Interpreting the affine prediction as a conditional expectation requires additional assumptions, such as a joint normal distribution.