Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article

Heteroskedasticity-consistent standard errors use an estimated regression covariance that remains consistent when error variances vary across observations. For ordinary least squares, the basic sandwich estimate is . The resulting standard errors are square roots of its diagonal entries. This is a regression application of a sandwich covariance matrix.
A chi-squared test rejects a null hypothesis for a statistic whose null distribution is a chi-squared law, exactly or asymptotically. Pearson tests compare observed and expected counts; both goodness-of-fit and chi-squared tests of independence are instances.
In a regular one-parameter statistical model, equality in the Cramér-Rao lower bound for an unbiased estimator implies the score function . Integrating in the parameter on a regular connected interval gives , with and . Thus efficiency for every parameter value forces an exponential family structure, under the usual common-support and differentiation assumptions.
All evidence in observed data about a parameter is contained in its likelihood function; proportional likelihoods carry the same evidence. If a stopping rule contributes only a positive factor independent of the parameter to the complete observed-sample likelihood, that factor does not change likelihood-based inference. Recording only a coarsened part of the sample produces a different likelihood and is not covered by the same invariance claim.
The one-sample Kolmogorov-Smirnov test checks goodness of fit by comparing an empirical distribution function with a specified cumulative distribution function . Its Kolmogorov-Smirnov statistic is the largest vertical gap anywhere between the two curves. Every threshold asks the same concrete question: what proportion of the observations are at or below it, and what probability does the proposed probability distribution assign there? A large discrepancy supplies evidence against the null hypothesis.
For example, four stipulated observations compared with the uniform distribution on give . Just before , only two observations have been counted, so the empirical distribution function approaches , while approaches . The Kolmogorov-Smirnov statistic section calculates every jump-side gap. These are exact illustrative numbers, not experimental measurements or a claim of statistical significance.
The ordinary one-sample calibration assumes independent and identically distributed real observations and a simple hypothesis , with a continuous function fixed before inspecting these observations. All statistical parameters of must be specified.[ref] Under that null hypothesis, the probability integral transform gives with the uniform distribution on , retaining independence. Consequently the sampling distribution of depends on the sample size , but not on the particular continuous . This is the useful sense in which the calibration is distribution-free.
For the exponential distribution of rate one, for . Take for the four stipulated above. The probability integral transform changes the horizontal coordinates but preserves both the order statistics and their cumulative heights, so the same Kolmogorov-Smirnov statistic appears on both scales. More generally, for continuous , the jump-side formulas depend only on . Strict increase everywhere is unnecessary: intervals on which is constant have probability zero under the null hypothesis. This explains the invariance without assuming a strictly positive probability density function.
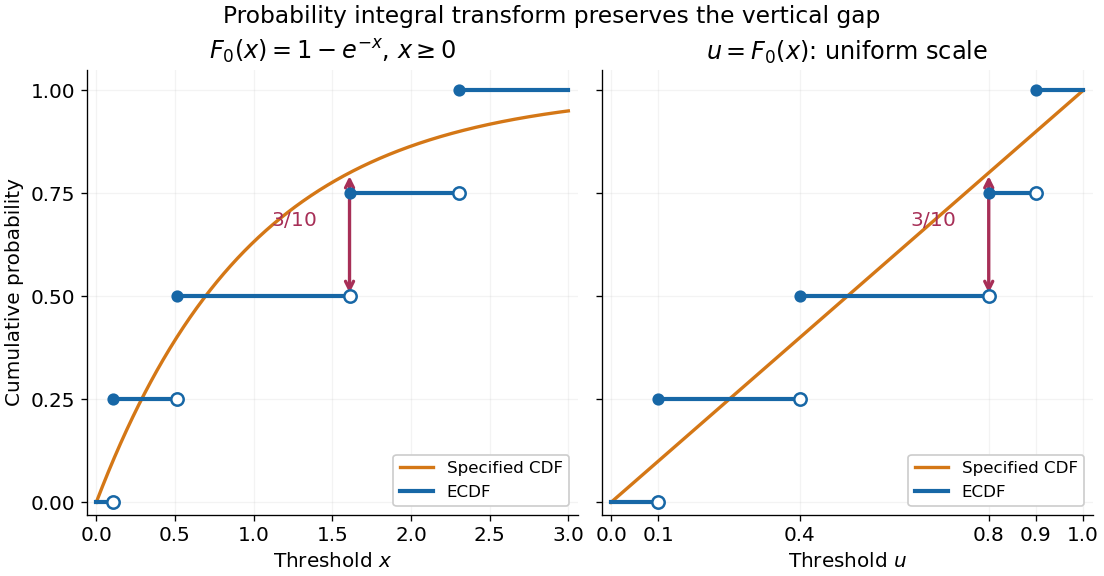
The probability integral transform preserves the Kolmogorov-Smirnov gap on exponential and uniform scales
. The same four stipulated points are shown as on the left and on the right. Open circles indicate left limits of the empirical distribution function, filled circles its values. The gap is approached from below the third observation on both scales. Details.The observed Kolmogorov-Smirnov statistic is a discrepancy, whereas its p-value is a tail probability under the null hypothesis:Here is computed from a fresh sample of the same sample size. Choose a significance level before the test and reject when the calibrated p-value is at most . The value alone supplies neither a p-value nor a rejection decision. Failure to reject does not establish that the null hypothesis is true. A finite-sample calibration and the asymptotic Kolmogorov-Smirnov theorem are distinct; a cutoff for must be rescaled before use with .[ref]
Fitting statistical parameters on the tested observations replaces by the random . The resulting transformed observations need not be independent and identically distributed uniforms, so the ordinary reference law fails. The Lilliefors test addresses a particular fitted normal distribution. More general parametric bootstrap calibration must simulate from the fitted statistical model and repeat the fitting in every replicate; holding the fitted statistical parameters fixed during those comparisons calibrates a different procedure. Such a parametric bootstrap requires its own validity justification rather than inheriting exactness from the simple-null test.
For a discrete probability distribution, is generally not uniform. Equal observations also arise from rounding, so tied data require a calibration that accounts for the discrete probability distribution or the rounding rule. The discrepancy remains meaningful, but continuous-null p-values are not automatically valid. Statistical dependence likewise changes the reference law. The two-sample Kolmogorov-Smirnov test compares two empirical distribution functions and has a different calibration.[ref]
In a parametric statistical model, the likelihood function compares parameter values, while sampling distributions calibrate tests and confidence intervals. A sufficient statistic retains the parameter information. Conditioning on an observed ancillary statistic restricts that calibration to experiments with the same ancillary configuration, instead of averaging over configurations whose distribution is unrelated to the parameter. Since the ancillary's marginal law is parameter-free, conditional and unconditional likelihoods have the same parameter-dependent factor. With a nuisance parameter, a conditional law or pivotal quantity must remove it before inference for the parameter of interest can use a nuisance-free reference law.
The delete-one form of jackknife resampling recalculates a statistic after deleting each observation in turn. It uses one observed statistical sample to investigate how sensitive an estimator is to its individual observations, and supplies both a jackknife variance estimator and jackknife bias correction. The calculations are deterministic once the data are fixed: no random draws are needed.
In the basic setting, are independent and identically distributed random variables, with sample size . Let be the observed values and a scalar estimator of an estimand . Apply the same estimation rule to each reduced statistical sample, using its new sample size wherever the rule requires it:Every index is deleted exactly once; an unusual value is treated by the same rule as every other value. The mean summarizes the deletion estimates. They overlap in observations, so they are generally not independent random variables representing fresh repetitions of the original experiment. Cosma Shalizi's [ref]
https://stat.cmu.edu/~cshalizi/490/23/2023-11-29-jackknife.pdf. Carnegie Mellon jackknife notes, Sections 1–3 and 5
explain this construction and its scaling.For a concrete sample mean, use the data , whose full sample mean is . The five deletion sample means, in observation order, areDeleting raises the sample mean by , while deleting lowers the sample mean by . Thus has the largest deletion effect in this statistical sample. This is a descriptive sensitivity calculation, not a rule for removing that observation: the full sample mean remains .
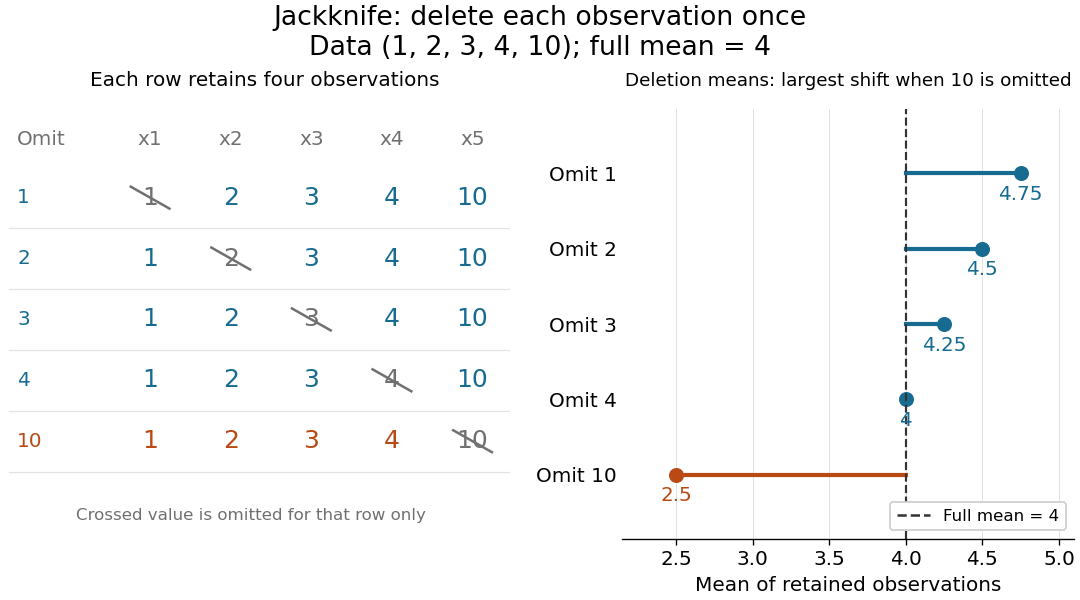
Delete each observation once and recompute the sample mean
. The left panel shows all five reduced statistical samples from ; each crossed entry is omitted only for that row. The right panel shows their sample means against the full sample mean . The orange row makes the deletion effect of visible. Details.Early literature includes M. H. Quenouille's [ref]
https://academic.oup.com/jrsssb/article/11/1/68/7026551. Approximate Tests of Correlation in Time-Series, JRSS B 11(1), 68–84 (1949)
and John W. Tukey's one-paragraph abstract [ref]https://www.jstor.org/stable/2237363. Bias and Confidence in Not-Quite Large Samples, Annals of Mathematical Statistics 29(2), 614 (1958)
, within the issue's collected abstracts. Shalizi's [ref]https://stat.cmu.edu/~cshalizi/490/23/2023-11-29-jackknife.pdf. historical notes and bibliography
discuss the later development of jackknife bias correction and the jackknife variance estimator.Statistical process control compares observed process outcomes with a stable reference model and control limits reflecting expected sampling variation. An observation outside those limits is a signal to investigate, not proof of a specific cause. Varying sample volumes require varying limits, and multiple testing changes the chance of a chance signal somewhere in the display.
An effect size measures the magnitude of an observed or modeled relationship. A standardized mean difference expresses a mean contrast in standard-deviation units; other effect sizes include a correlation coefficient or odds ratio. Magnitude is distinct from the evidence against a null hypothesis supplied by a p-value: a small effect size can have a small p-value in a sufficiently large sample.
The pressure obtained by bringing a flow to rest without losses; in compressible flow the usual definition specifies an isentropic process for stopping. For the constant-mass density, same-height Bernoulli equation discussed under dynamic pressure, .
Pressure referred to an ideal vacuum, rather than to atmospheric pressure or another chosen reference. Gauge pressure instead subtracts atmospheric pressure.
A best affine state estimate minimizes mean squared error among estimates formed from the available observation vector . With finite second moments and invertible observation covariance matrix, it isThis follows from the orthogonal projection of centered state components onto the linear span of centered observation components. For Jointly Gaussian state and observation it equals the conditional expectation; for general laws a nonlinear estimate can have lower mean squared error.
Process noise is the random contribution to a state transition in a state-space model. It represents uncertainty in how the state evolves. Measurement noise instead affects the observed value of the state. In the local-level state-space model , , the first disturbance changes the state itself; the second changes its measurement.
State prediction estimates a future state of a dynamical system using observations already available. A state-space model supplies the transition law. Unlike causal state filtering at the next time, the prediction has not yet incorporated that next observation; a Kalman prediction step therefore includes uncertainty from new process noise.
Causal state filtering estimates the current state of a dynamical system from observations up to the current time. Under quadratic loss, the conditional expectation is an optimal estimate. A Kalman filter obtains this estimate recursively for a linear Gaussian state-space model, without using future observations.
A composition of an integer is an ordered tuple of positive integers with sum . Its length counts the parts. For example, and are different compositions of an integer, though they give the same integer partition. Stars and bars counts compositions of an integer with fixed length. [ref]
https://math.mit.edu/~fgotti/docs/Courses/C.%20Combinatorial%20Analysis/6.%20Compositions/Compositions.pdf. Gotti, Lecture 6, definition of a composition
For a sufficiently smooth vector field at a hyperbolic equilibrium, the sums of generalized eigenspaces with negative and positive real parts are tangent to local invariant stable and unstable manifolds of the same dimensions. Their points converge to the equilibrium in forward and backward time respectively. Hyperbolicity excludes eigenvalues with zero real part; center manifolds require a separate theorem.
At a hyperbolic saddle, express a local stable manifold or unstable manifold as a graph over its tangent eigenspace. Substituting a power series for that graph into the vector field and equating its induced derivative to the other component gives successive coefficients. For , , this gives on the stable graph and on the unstable graph. These are local expansions, not globally invariant polynomial curves.
Starting at with , the next two iterates are the maximum and its image . Since and the squared-denominator population map decreases on , its image there lies in . Thus the displayed interval is invariant after the initial step, and both bounds are attained. The initial value itself is below , so it must not be included in the lower-bound assertion.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact