Binomial thinning 2026-10-31
Retain each of objects independently with probability , independently of the nonnegative integer-valued random variable . The retained count has the displayed conditional binomial distribution. The probability generating function of an independent random sum gives . If has finite variance, the law of total expectation and law of total variance give
The first term is the average conditional variance of the independent retention decisions; the second is the variance in their conditional expected value.
Conditional expectation choice invariant Created 2026-10-18 Updated 2026-10-31
Let be a real-valued objective function of finitely many choices, with finite expected value. Suppose a prefix has positive probability. Write . If the next choice is a fair bit, the law of total expectation gives
At least one child is at least this average. Choose a child with the larger value, using a fixed rule for ties. The resulting loop invariant is . At a complete assignment , there is only one completion left, so and therefore .
For a biased choice or more than two possibilities, use the corresponding weighted average:
Some positive-probability child is at least the weighted average. For minimization, choose a child at most the current conditional expectation and reverse the invariant. The averaging identity is the same in both directions.[ref]
The word "probabilities" in the method's name also covers an indicator random variable for an undesirable outcome: keeping its conditional expectation, which is its conditional probability, strictly below one eventually forces that indicator to be zero. Optimizing an ordinary numerical objective function is the method of conditional expectations formulation used below.
Conditional independence Created 2026-09-24 Updated 2026-10-14
Random variables and are conditionally independent given when, for every pair of Borel sets , the following identity holds almost surely:
Here conditional probabilities are conditional expectations of the corresponding indicator random variables given the sigma-algebra generated by . This defines the condition even when . In terms of regular conditional distributions, the conditional joint law is the product of the conditional marginal distributions for almost every conditioning value.
For discrete random variables, at every with , the condition becomes
Where , this is equivalent to . Once is known, observing provides no further information about .[ref]
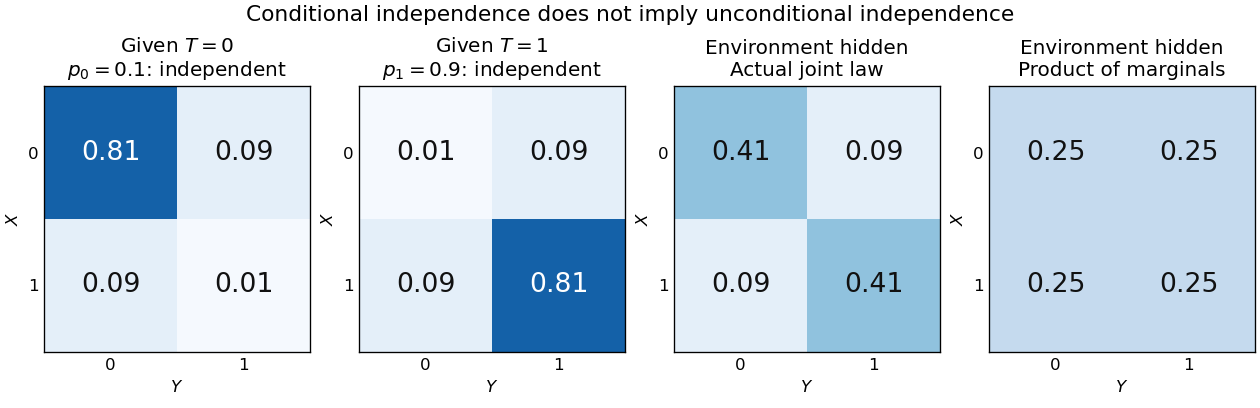
For a worked example, suppose a latent variable chooses between two environments with . Given , take to be independent and identically distributed with a Bernoulli distribution of parameter , where and . Think of two separate trials run under the same quiet or active environment. Their conditional joint probability mass functions, with rows and columns , are
Each is exactly the product of its own conditional marginal distributions: for , and for . Thus are conditionally independent given .
If the environment is unobserved, the law of total probability averages the two tables:
Both unconditional marginal distributions are fair, but . The law of total expectation gives
Figure 1.
An unobserved shared environment creates statistical dependence between conditionally independent trials
. The first two tables show independent Bernoulli trials at conditional success probabilities and . Averaging them with equal weights gives the third table. The fourth table is the product of the resulting unconditional marginal distributions, which differs from the actual joint table. These are stipulated model probabilities, not observed frequencies. Details.
Observing makes the active environment more plausible, so it raises to . Knowing the actual environment removes this source of statistical dependence. The covariance induced by a shared latent variable lemma explains the calculation without listing all the outcomes.
This is why conditional independence is useful in statistical modelling: a model can multiply simple conditional laws and then average over a shared latent variable. The resulting observations can remain statistically dependent. Conditional independence graphs organize such information relations; their interpretation as causes requires additional assumptions from causal inference. Conditioning describes the information available to an observer. It does not, by itself, describe what would happen if an experimenter changed a variable.
Conditional variance Created 2026-09-28 Updated 2026-10-14
The conditional variance measures the remaining squared uncertainty after specified information has been used to form a conditional mean. For a real square-integrable random variable and a sub-sigma-algebra , let . Then
It is a -measurable random variable, nonnegative almost surely, rather than necessarily a single number. With the information , its value is the variance in the group identified by . Its expected value is the mean squared error of predicting by its conditional mean.[ref]
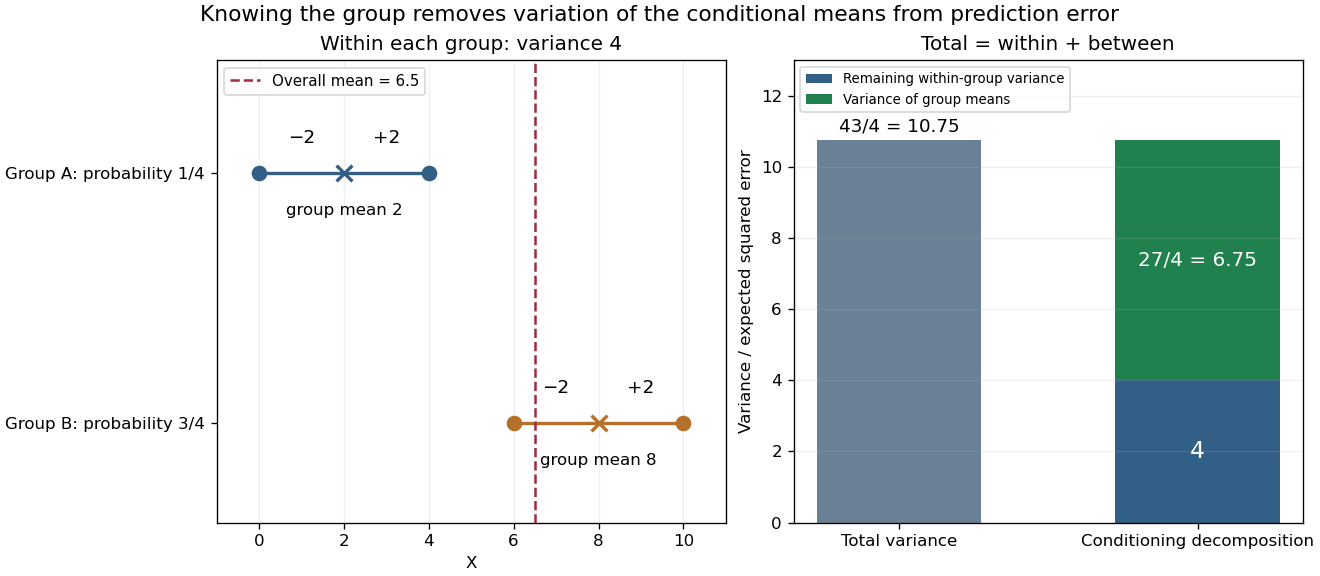
In the exact mixture distribution in law of total expectation, group contains around mean two, and group contains around mean eight. Both groups have conditional variance four because their deviations from their own means are with equal probabilities. Therefore . Meanwhile, the two group means have variance . The law of total variance gives
Direct calculation gives and , checking the decomposition.
Figure 1.
Total variance separates remaining within-group error from variation of group means
. Left: in the stipulated finite mixture distribution, each group's values deviate by from its conditional mean. Right: the total variance separates into expected conditional variance four and variance of the conditional mean . Knowing the group removes the latter part from the average squared prediction error. Values and weights are exact model choices, not measured data. Details.
For any square-integrable -measurable predictor , the error identity is
The cross term vanishes because . Thus using the conditional mean minimizes mean squared error, while conditional variance quantifies what this information still cannot predict. This is the orthogonal projection interpretation in L2 space.[ref]
Covariance induced by a shared latent variable Created 2026-10-06 Updated 2026-10-14
Let be indicator random variables with conditional independence given a latent variable , and suppose . Then
For a short proof, conditional independence gives . The law of total expectation gives and . Subtract their product to obtain the claimed variance. Since , all the required expected values exist.
In the two-environment example of conditional independence, is or with equal probabilities. Hence and . The two trials have zero conditional covariance in either environment, yet their unconditional covariance is positive because their success probabilities rise and fall together.
More generally, square-integrable conditionally independent random variables satisfy
by the law of total covariance. Equal conditional means reduce this to the displayed variance; unequal conditional means need not give a nonnegative covariance. The equal-mean result explains correlated component evolutionary states in a coeval binary population without correlation between initial masses: variation in a shared environment can supply the entire covariance.
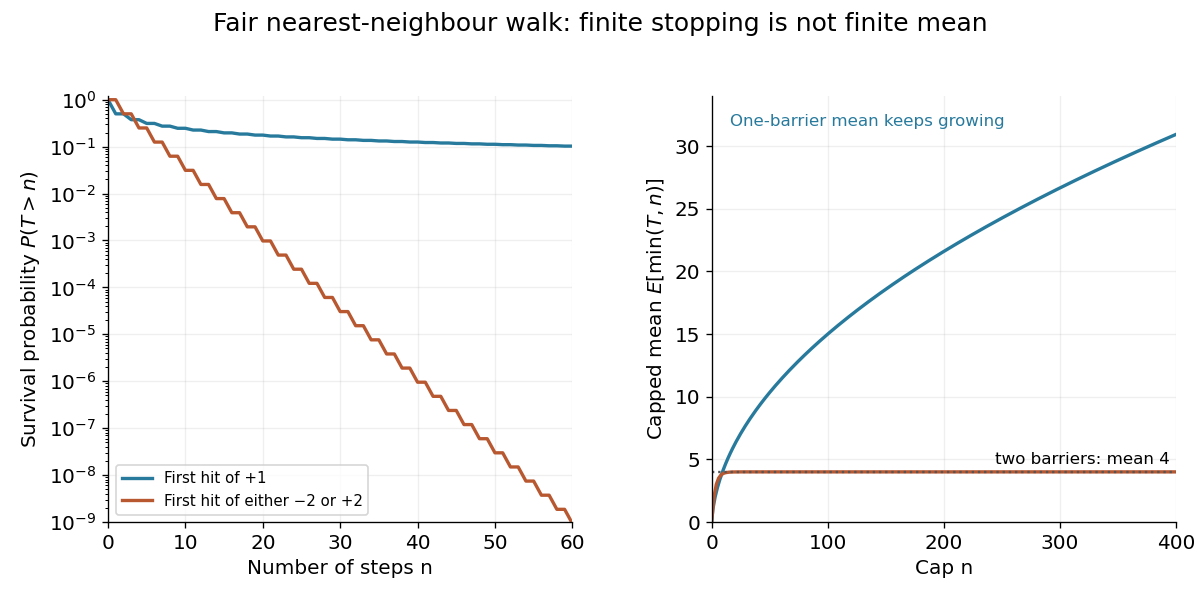
For a simple symmetric random walk starting at zero, let be its first hitting time of . The infinite mean first passage of a simple symmetric random walk shows that almost surely but . Since , assuming a finite expected value for would let Wald's equation assert , a contradiction. The formal expression is not an allowed use of the theorem.[ref]
Compare . From every surviving position in , three consecutive positive increments force absorption within three steps. Each fresh block has probability of this event, so and . This establishes finiteness before invoking the theorem. If is the average remaining time from position , the law of total expectation gives
so . Symmetry gives equal exit probabilities at and , and , as Wald's equation predicts. This is a small gambler's ruin problem with two absorbing barriers.
Figure 1.
Almost sure stopping can have either a finite or an infinite mean
. Original exact simple symmetric random walk calculation from zero. The left compares survival probabilities for first hitting and first hitting either or ; the right sums these tails to obtain capped average waiting times . These are calculated laws, not simulated measurements. Details.
Even for , each bounded stopping time satisfies . The stopped process tends to almost surely, but its expected value does not tend to . Rare long negative excursions retain the balancing contribution. The existing stopped-walk martingale with almost sure but not L1 convergence explains the related failure of uniform integrability; almost sure convergence alone does not permit exchanging a limit and an expected value.
Law of total covariance Created 2026-10-07 Updated 2026-11-05
For square-integrable random variables, expand and into their conditional expectations and their centered conditional residuals. The cross terms vanish by the law of total expectation, giving the displayed covariance decomposition. conditional independence can therefore coexist with positive unconditional covariance from a shared latent variable.
Law of total variance Created 2026-09-24 Updated 2026-10-14
The law of total variance separates the spread of a population into spread inside groups and spread between their means. For a real square-integrable random variable , so that , and another random variable on the same probability space,
The first term averages the conditional variance over the possible information ; the second measures how much the conditional mean changes with that information. There is no independence assumption, and need not be numerical or have finite variance. Conditioning is useful precisely when knowing tells us something about . See MIT tutorial on using conditional expectation and variance.
More generally, the available information can be a sub-sigma-algebra of the ambient probability space. With , the existing conditional expectation definition gives
Taking recovers the displayed formula. The conditional mean and conditional variance are themselves random variables: before learning the group, we do not yet know which group average or group spread will apply. Their outer expectation and variance turn these varying quantities into numbers.
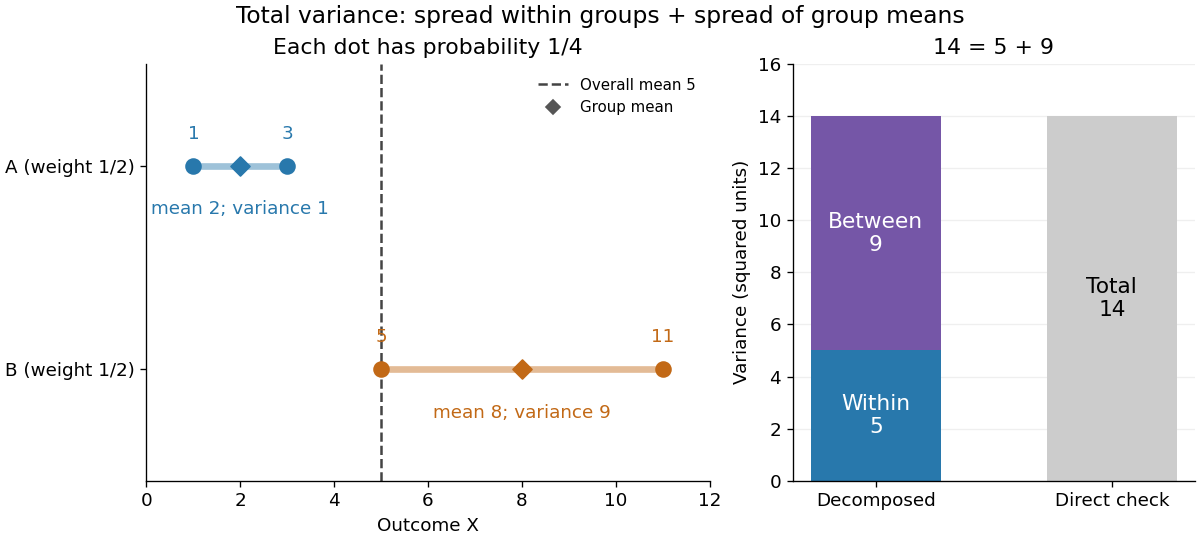
For a fully explicit mixture distribution, choose a group or with equal probabilities. In group , choose or with equal conditional probabilities; in group , choose or with equal conditional probabilities. Thus the complete joint probability distribution consists of , each with probability , and no other outcomes. The conditional means are and . Squaring the deviations and gives conditional variances and , respectively. The law of total expectation gives the overall mean .
The within-group contribution to variance is
For the between-group contribution, the conditional mean takes values and , each three units from the overall mean. Consequently,
We can check this without any conditioning: the discrete random variable takes values with equal probabilities, so
Equivalently, its second moment is , and subtracting the squared mean gives . These are population variances, with the stated probabilities as weights, rather than estimates using the corrected denominator of a sample variance.
Figure 1.
Four equally likely outcomes split total variance into within-group 5 and between-group 9
. Details.
The figure makes the two sources of spread visible. The outcomes in group cluster tightly around , while those in group sit farther apart around . Replacing every outcome by its conditional mean removes the internal spread but leaves the separation between groups. Conversely, subtracting each group's conditional mean aligns the two groups around zero. Averaging only the conditional variances would miss nine units of variance; retaining only the conditional means would miss five. Neither summary alone describes the whole population.
Two modifications clarify what each contribution measures. Shift group to outcomes and group to outcomes , keeping all four probabilities equal. Both conditional means are now , while the conditional variances remain . The between-group contribution vanishes, and total variance is just . Group membership still tells us how uncertain an outcome is, even though the best point prediction stays the same. Alternatively, let every outcome in group equal and every outcome in group equal . Now both conditional variances vanish, and all nine units of total variance come from group separation. Knowing the group predicts the outcome perfectly. These limiting cases distinguish differences in average outcome from differences in internal spread; the original mixture distribution contains both.
The same calculation answers a prediction question. If the group is hidden, the best constant prediction is the overall mean , with mean squared error , by variance as the minimum mean squared error of a constant. If the group is revealed, predict for and for . The errors become , and their mean squared error is . Knowing the group therefore improves the best achievable mean squared error by , exactly the between-group contribution. This is an interpretation relative to the information available: the remaining uncertainty could shrink further if additional information were revealed.
For any square-integrable measurable function used as a predictor, write . The prediction identity is
Thus predicting with the regression function gives the conditional expectation and minimizes mean squared error over every permitted predictor, including nonlinear ones. This minimizes average squared error, not the error for each individual outcome. See Berkeley Statistics 201A notes, sections 36–37.
Why do the two pieces add cleanly? Put . Its conditional expectation given is zero, so and for every square-integrable measurable function . In particular, and are uncorrelated random variables. Splitting and squaring therefore leaves no cross term after taking expectation. Geometrically, the conditional expectation is an orthogonal projection in the L2 space, and the law of total variance is its Pythagorean theorem for centered random variables.
Figure 2.
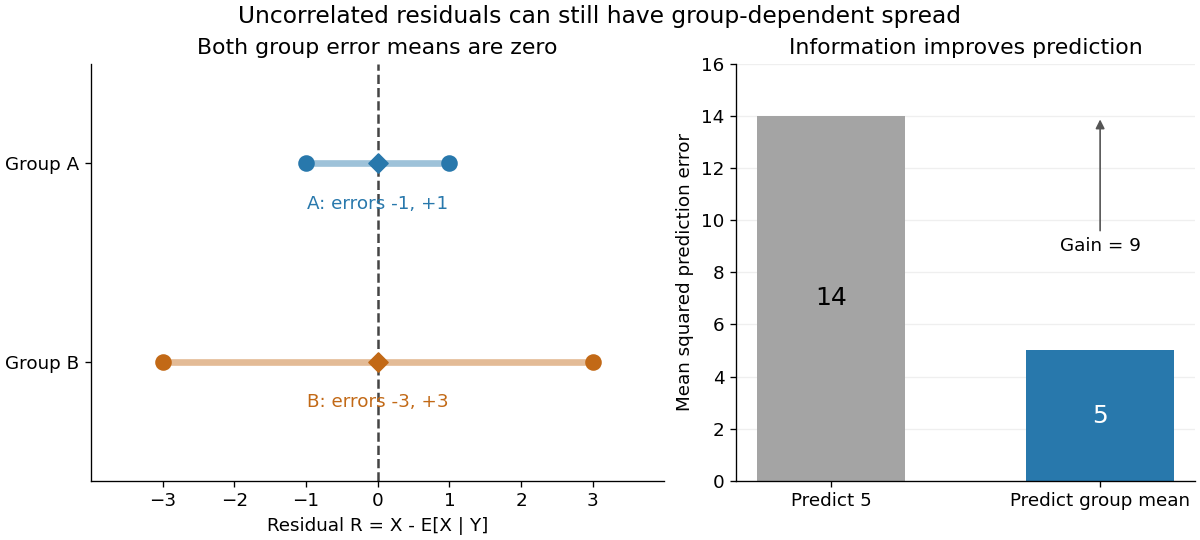
Conditional prediction leaves zero group means but different residual spreads
. Details.
In our example, the four products are , which average to zero. Yet and are not independent: observing identifies group , while observing identifies group . This is a concrete instance of heteroscedasticity, with different conditional variances despite zero conditional means of the errors. A group can predict uncertainty even when it cannot predict the error's sign.
The law of total variance is useful whenever aggregated data conceal distinct groups. Changing mixture weights changes both contributions, so the weighting must match the population being described. For example, giving group weight changes the overall mean to , the within-group variance contribution to , and the between-group contribution to , making the total . Group differences account for spread and prediction gains; assigning them a causal explanation requires a separate causal inference argument.
Mean absorption time of a lazy symmetric random walk Created 2026-10-25 Updated 2026-11-05
Consider a random walk on with absorbing states . At each interior state it stays in place with probability , and moves one position in either direction with probability , where . Its mean absorption time from is
Proof. A sequence of at most consecutive leftward moves ensures absorption, with probability at least . Dividing time into blocks of length gives a geometric series bound on the survival probabilities, so the expected value is finite. Let . The law of total expectation and first-step analysis give
Thus . A particular solution of this linear recurrence relation is ; its homogeneous solutions are . The two boundary conditions give , , proving both the formula and its uniqueness. Holding slows the usual symmetric random walk by the factor .
Nested conditioning keeps the coarser information Created 2026-10-14 Updated 2026-10-31
For integrable random variable and nested sub-sigma-algebras , the tower property says
The finer-information conditional mean can be averaged within each coarser group, recovering the coarser-information conditional mean. Conversely, conditioning an already -measurable conditional mean on leaves it unchanged. Both orders therefore recover when the information is nested.[ref]
For the finite example in law of total expectation, exact knowledge of gives the finer mean itself. Averaging within the groups recovers two and eight. Forgetting the group then gives . The nesting condition is essential; iterated conditional expectation over nonnested sigma-algebras describes why arbitrary successive conditioning cannot simply be replaced by conditioning on an intersection.
Neyman Type A distribution Created 2026-10-31 Updated 2026-11-05
Let have a Poisson distribution with parameter , and let be independent random variables with a Poisson distribution of common parameter , independent also of . Then has a compound Poisson distribution, with . The law of total expectation yields the displayed probability generating function and expected value . The law of total variance gives variance , exceeding the mean when both parameters are positive. This extra variation comes from the random number of groups. Jerzy Neyman is the statistician for whom the distribution is named.
A family of disjoint events whose union is the sample space. For the countable law of total probability and law of total expectation, use a finite or countably infinite family. Conditioning formulas sum only positive-probability parts, or interpret zero-probability contributions as zero without assigning a conditional expectation there.
There is no proof of the printed assertion: it is false for the stated expectations. The original explicitly defines as the expected remaining count, so replacing it by a deterministic upper envelope changes the problem.[ref]
Let be the actual count after rounds and . The union bound gives the valid conditional estimate
By the law of total expectation, the resulting unconditional bound is
Discarding the variance term is an expectation closure error for a nonlinear recurrence. In particular, Jensen's inequality says , which cannot justify the requested upper bound.
For an exact counterexample, start with two balls and two bins. A round serves both balls if they land separately and serves neither if they collide. Each outcome has probability , independently in successive rounds while both balls remain. Consequently
At , the requested inequality would say , but
If the bound in part (c) were available, the intended answer would be
Indeed , so that bound would give . Its growth is in Big O notation. Because (c) is false, this substitution alone does not prove the result for the actual repeated singleton-removal allocation.
The requested order can nevertheless be established for the actual process. Here is a concrete, deliberately generous replacement, with for the empty system:
The large cutoff makes the numerical estimates below simple. A finite initial range does not affect the asymptotic analysis.
First, whenever , a ball is served with probability at least
Thus part (a) gives , also for . The law of total expectation yields . This proves for the small- branch, including , whose single ball is served immediately.
For the large- branch, we need control of the random count, rather than an unjustified recurrence for its expectation. If balls are allocated in a round, changing one chosen bin changes the number of singleton bins by at most two. The surviving count therefore has the bounded differences property with constants . McDiarmid's inequality gives
This can be applied conditionally after any history, since the next allocations are fresh independent random variables.
Use this concentration inequality in three stages. Write .
  • For the first eight rounds, whenever , the conditional expectation is at most . Taking shows that the next count is at most , except with probability at most . If the count has already fallen below , it stays there. Since and , this gives outside the stated exceptional events.
  • Starting with , set . If and , part (a) and the union bound give . Taking gives a next count at most , except with probability at most . The deterministic solution is . It falls below within steps. After reaching that threshold the count cannot increase, so outside the exceptional events.
  • From , the next conditional expectation is at most . A deviation leaves at most balls except with probability . From at most balls, the next conditional expectation is at most . Taking leaves at most balls except with probability . Conditional on this final count bound, one more round has expectation at most .
Every exceptional probability above is at most , and there are at most opportunities for an exception. For , the elementary bounds and give, by the union bound, total exceptional probability at most . The first numerical inequality holds at the cutoff and remains true because is increasing there. On an exceptional history there are at most balls. Taking the last round's conditional expectation and then averaging gives
This proves the displayed replacement for the literal process without relying on either false assertion.
Order the edges arbitrarily and fix their colours one at a time. After a partial assignment , regard all unassigned edges as independent fair red/blue choices, and compute
The conditional expectation of a monochromatic clique count is easy to compute. For each four-vertex subset , let be the number of its six edges still unassigned. Its contribution to is
In the second case, every remaining edge must match the already fixed colour; this includes a completely fixed monochromatic copy, for which and the contribution is one. In the last case, the six unassigned edges may become either all red or all blue. By linearity of expectation,
For the next unassigned edge , compute and . The law of total expectation gives
Choose the colour with the smaller value, resolving a tie by a fixed rule. At least one is at most their average, so the loop invariant is that never increases. Initially ; once every edge is fixed, there is no randomness left and . Therefore the method of conditional expectations guarantees
A direct implementation recomputes both sums over all four-vertex subsets for each of the edges, requiring arithmetic operations. The comparisons can be exact: every contribution is a multiple of , so store as an integer with bits. This gives bit complexity with elementary arithmetic, and hence a deterministic polynomial time construction. No random sampling is performed by this derandomization.
Where the moment-generating function is finite in a neighborhood of zero, define the cumulant-generating function and the th cumulant by . Differentiation gives
since . Thus the first two cumulants are the mean and variance.
Conditional on , independence gives . Summing over the Poisson distribution yields
Hence the compound Poisson cumulants give
For the moment statements, finite second moments suffice even when a moment-generating function does not exist near zero: conditioning gives . This distinguishes the raw second moment from the variance of an individual claim.
For a single flood, the law of total expectation and law of total variance similarly give
Condition on the number of floods and apply the same laws once more. All floods have these moments and are independent of , so the annual total satisfies
The additional term is the variation in the number of entire flood clusters; it would be lost by treating individual claims as an ordinary Poisson stream.
For the annual count , its probability generating function is
This is the nested Poisson flood count. Differentiating, or conditioning on , gives and . Thus is not Poisson when , since its variance exceeds its mean. If either parameter is zero it is identically zero, a degenerate Poisson distribution.
Let be the number of valid claims in flood . Independent validity marking gives . Its generating function is
so Poisson thinning gives . With validity independent also of claim amount, each claim contributes expected paid amount . Therefore the annual expected payment is . The independent-mark assumption is needed for this multiplication; a size-dependent invalidity rule would require the joint expected value of amount and validity instead.
A credibility factor is the weight assigned to a particular risk's observed experience when blending it with a population or manual premium. In the Bühlmann model, the blend is the best affine mean-square predictor, rather than automatically the full posterior mean.
Let , the expected process variance, and assume the displayed second moments are finite. The law of total expectation gives . The law of total variance and law of total covariance give
For the second formula, the conditional covariance is zero by conditional independence, while the covariance of the conditional means is , the variance of hypothetical means. Likewise
because .
To derive the Bühlmann credibility premium, minimize . Differentiating in sets the predictor's mean to . The remaining normal equations are
For , subtracting any two rows forces all to be equal, then gives . Thus the premium and factor are
The same affine premium predicts : conditional independence makes , so minimizers agree. If , every year's amount equals almost surely, and gives the exact risk mean even though the coefficient vector need not be unique.
For fixed , . Thus more within-risk variation decreases credibility: individual experience becomes less informative, as , and the premium tends to . Increasing the number of observed years has the opposite effect.
For numerical estimation from a balanced panel, assume the risks are independent draws from the same risk population, with comparable exposures, and . Set
Conditionally, each within-risk sample variance has mean ; hence . The risk sample means have variance , so . Therefore is an unbiased method of moments estimate of . For a usable nonnegative variance estimate take , noting that this truncation sacrifices exact unbiasedness.
The balanced-panel method-of-moments credibility estimate for risk is consequently
If and , use zero credibility. If both estimates are zero, the within and between sums of squares are zero and all the observed amounts coincide; any blend gives that same premium. With only one year per risk or only one risk, these within/between estimators are unavailable, so external structural estimates or additional assumptions are necessary.
Conditional on , the type indicators are independent random variables with the Bernoulli distribution of parameter . Thus has the binomial distribution and its probability generating function is . The general rule used here is that for a nonnegative integer-valued random variable , ; for a sum of independent such variables, their probability generating functions multiply, since the expected value of the product factors. The law of total expectation then averages the conditional result:
This calculation uses the given independent labeling of objects, including conditional on their number.
Condition on the claim count. The empty random sum of independent claims is zero, and independence gives . Therefore the random-sum transform identity is
wherever the composition is finite. This follows directly from the law of total expectation, rather than replacing the random count by its mean.
Put . For the specified negative binomial distribution, the negative binomial series gives . A rate- exponential distribution has moment-generating function . Hence
The last expression is exactly the moment-generating function of a compound binomial distribution with independent count and severities
The moment-generating function exists in a neighborhood of zero, so its uniqueness identifies the distributions. In particular, the new claim sizes have mean , not , and both aggregate distributions have an atom at zero. This is the negative-binomial sum of exponential claims representation with the severity rate explicitly retained.
Conditional on , the aggregate has Erlang distribution with density on . Repeated integration by parts of its tail gives
Indeed, after substituting , the integral reduces recursively to the corresponding integral with exponent , terminating at . Applying the law of total probability yields the original infinite mixture distribution tail
Applying the same argument to the compound binomial distribution gives instead the finite Erlang-mixture tail for a negative-binomial exponential aggregate:
The two tails are equal. The binomial representation replaces an infinite sum by a finite exact calculation, eliminating the need to choose a claim-count truncation and control its omitted tail. The inner sums can be evaluated recursively, using for their exponential-weighted terms.
The first approach specifies marginal means, variances and an exchangeable correlation for each student's repeated counts. It is a moment model suitable for a generalized estimating equation; equality of the mean and variance alone does not specify a full Poisson joint distribution. Different students supply independent sampling clusters, while the three counts within a student are dependent.
The second approach is a Poisson generalized linear mixed model with a positive shared random multiplier . Conditional on it, the three counts are independent Poisson variables; integrating over it gives a fully specified dependent joint law. The gamma random-intercept Poisson model uses Gamma shape and rate , so and . Treat the covariates as fixed, with the same multiplier distribution across covariate/treatment groups, as required by this model.
Let and . The law of total expectation, law of total variance and law of total covariance give
Thus each marginal is a negative binomial distribution by the Poisson-gamma mixture, rather than generally a Poisson variable. Put . Its variance is , and the marginal correlation is
It is positive but usually depends on the two marginal means, so it need not be the common exchangeable correlation proposed in the first approach. The first method focuses on population mean effects with a chosen working correlation matrix; the second models latent student heterogeneity and separates conditional Poisson variation from additional marginal variation. Correctly specified likelihood inference for the second uses more distributional assumptions, while the first can retain valid mean inference despite a wrong working covariance by using a cluster-level sandwich variance.