Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Stellar nucleosynthesis encompasses nuclear production during stellar evolution and explosions, including hydrogen burning, core helium burning, advanced burning and neutron-capture processes. Stellar mass, composition, mixing and mass loss govern which nuclei form and which eventually escape. Slow neutron-capture process and rapid neutron-capture process build many nuclei beyond the iron group.
Ribonucleic acid, or RNA, is a nucleotide polymer whose nucleotide sequence can both carry information and organize a working molecular shape. Its backbone contains alternating ribose sugars and phosphate groups connected through covalent bonds. Its usual nucleobases are adenine A, uracil U, guanine G, and cytosine C. Thus RNA uses U where DNA uses T; its ribose also differs chemically from DNA's deoxyribose. See NHGRI: RNA.
In transcription, an enzyme uses one DNA strand as a template for RNA. For example, the DNA template specifies in RNA. The base pairing rules now include A–U rather than A–T, while G–C remains. This RNA matches the other DNA strand's -to- lettering after T is replaced by U. Identifying the template strand matters: replacing T by U in an arbitrarily chosen DNA strand is not a general method for deriving the RNA product. See Alberts et al., Molecular Biology of the Cell: from DNA to RNA.
RNA is often a single strand, but single-stranded does not mean straight or entirely unpaired. Complementary regions within one RNA molecule can undergo base pairing, bringing distant positions together. Consider the illustrative twelve-nucleotide nucleotide sequence . Pair positions 1 with 12, 2 with 11, 3 with 10, and 4 with 9. The resulting stem-loop has four base pairs: G–C, C–G, A–U, U–A. Positions 5–8 remain unpaired in the loop. Both arms belong to the same continuous backbone, and the paired arms have the directions of antiparallel nucleic acid strands.
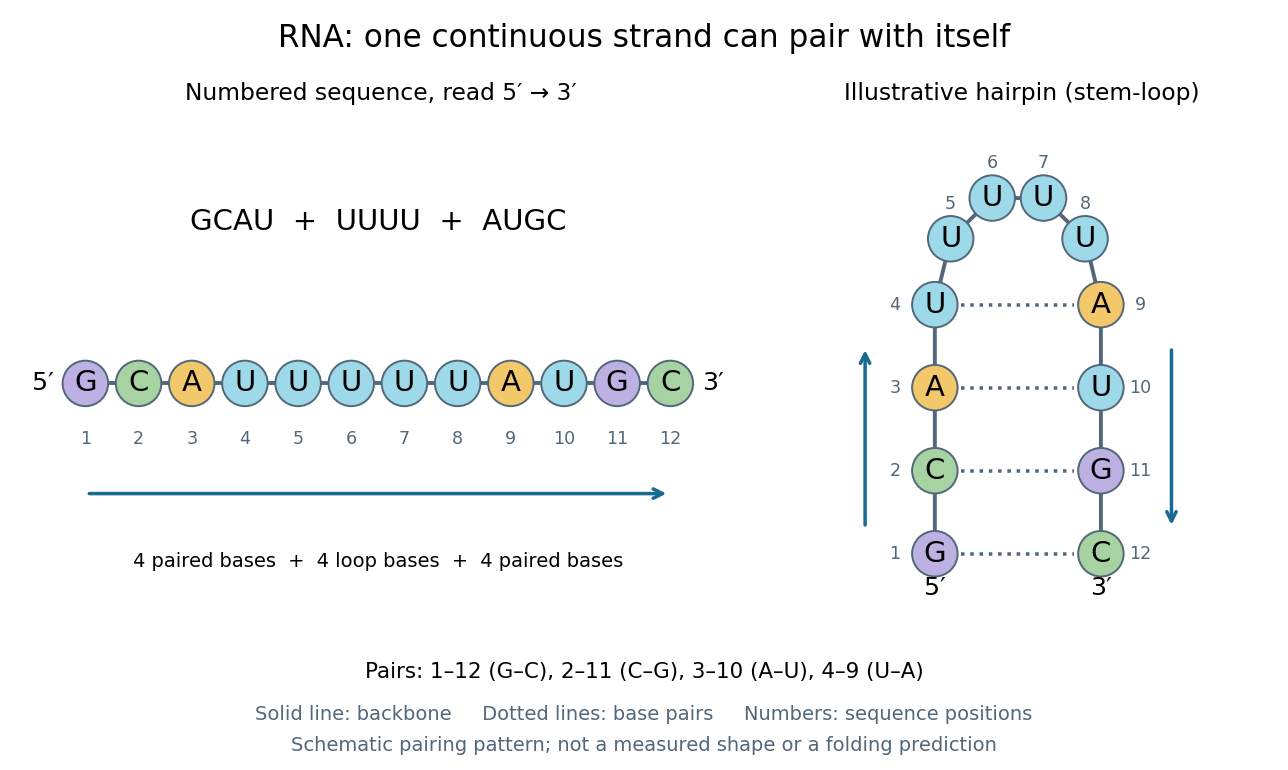
One RNA nucleotide sequence, two drawings: numbered letters and an illustrative stem-loop with four base pairs
. Details. The diagram proposes a possible pairing pattern, not a prediction that this short RNA must adopt that shape under every condition. Actual RNA folding depends on additional interactions, temperature, ions, and associated proteins; the full three-dimensional arrangement contains more information than the drawn base pairs. The example's purpose is to show how a linear nucleotide sequence can specify contacts within itself.
Different RNA roles make this flexibility useful. Messenger RNA carries a message that a ribosome reads during translation to build a protein. Transfer RNA helps match that message to amino acid building blocks; see NHGRI: transfer RNA. Ribosomal RNA forms structural and catalytic parts of the ribosome. Other RNA participates in gene regulatory networks, changing how strongly genes are expressed. Many RNA molecules therefore function without being translated into proteins; for some genes, functional RNA is the product itself.
Most strikingly, some folded RNA acts as an enzyme: these catalytic RNA molecules are ribozymes. The ribosome's bond-forming active site is built from RNA, although the complete ribosome also contains proteins. Structural evidence appears in Nissen et al., The structural basis of ribosome activity in peptide bond synthesis, Science 289, 920–930 (2000). RNA therefore connects a readable record with physical recognition, regulation, and catalysis: the same kind of polymer can be a message, an adaptor, or part of molecular machinery.
Deoxyribonucleic acid, or DNA, is a nucleotide polymer that stores biological information in its nucleotide sequence. The crucial variable is order: two DNA molecules can contain the same numbers of each nucleobase yet carry different nucleotide sequences. This makes a physical molecule an inheritable record, rather than merely a mixture of ingredients. Genes are functional regions of that record; the whole DNA nucleotide sequence is not one long gene. See NHGRI: DNA fact sheet.
Each DNA strand has a backbone of alternating deoxyribose sugars and phosphate groups joined through covalent bonds. Attached nucleobases supply the familiar four-letter alphabet: adenine A, thymine T, guanine G, and cytosine C. In ordinary double-stranded DNA, base pairing matches A with T and G with C. The backbone connects successive nucleotides along a strand; base pairing connects partners across strands. Keeping these two connections distinct explains how strands can separate while each retains its own nucleotide sequence.
The two backbones have directions, conventionally labelled and after numbered carbon chemical atoms in deoxyribose. They form antiparallel nucleic acid strands: following one from to takes you opposite to the other's -to- direction. For the chosen DNA nucleotide sequence , write its partner directly underneath as . Now read that partner from its own end: its reverse complement is . Complementing letters and reversing their order are separate operations. See Alberts et al., Molecular Biology of the Cell: the structure and function of DNA.
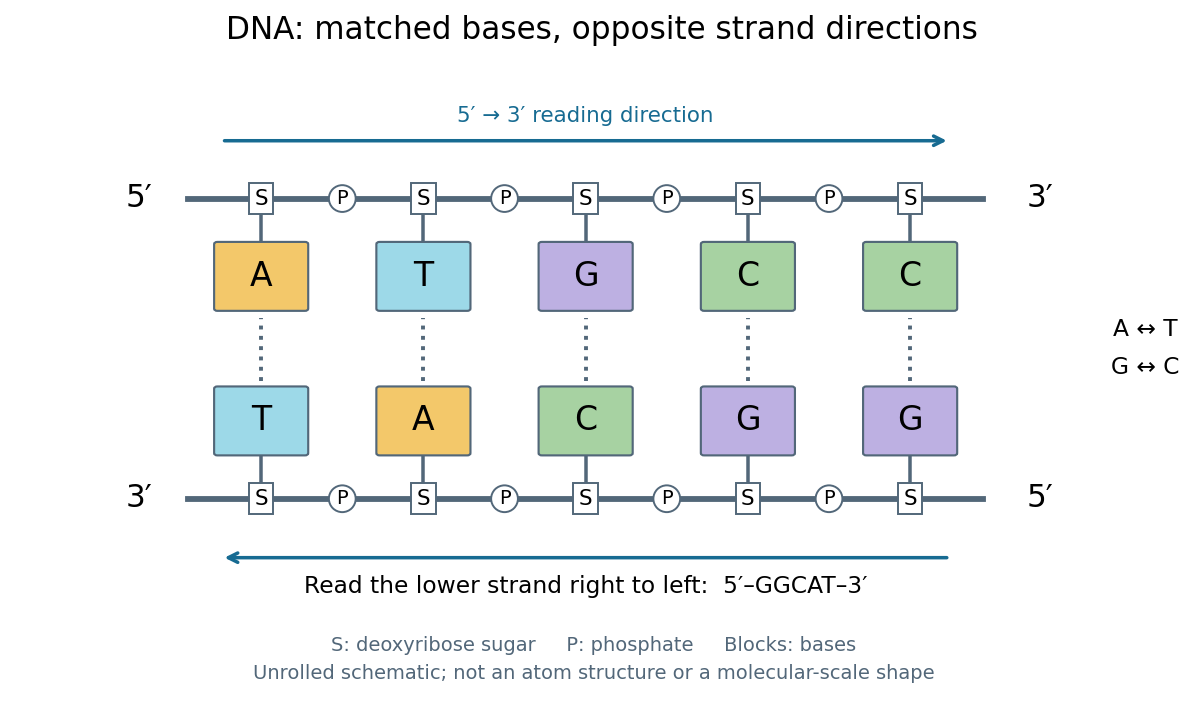
DNA base pairing and antiparallel nucleic acid strands: an unrolled ladder for ATGCC and its reverse complement
. Details. The diagram's rails represent sugar–phosphate backbones and its coloured blocks represent nucleobases, not individual chemical atoms. Reading left to right gives five matched positions: A–T, T–A, G–C, C–G, C–G. There are two A–T-type base pairs and three G–C-type base pairs; the complete two-strand example contains ten nucleotides. Reversing the bottom row changes the reading convention, not the physical partners. Real double-stranded DNA winds into a nucleic acid double helix; the flattened ladder emphasizes base pairing and direction without pretending to show its three-dimensional geometry.
The motivating consequence is copying by a template. After strands separate, each existing DNA strand specifies which incoming nucleotides should accompany it through base pairing. DNA replication uses enzymes to build complementary strands, allowing the record to persist through successive biological cells. Base pairing supplies a selection rule, while enzymes perform the chemistry: a matching diagram alone is not a complete copying mechanism. The connection between structure and copying was already central to the model published by Watson and Crick on 25 April 1953. See Watson and Crick, Molecular Structure of Nucleic Acids, Nature 171, 737–738 (1953).
Stored information needs interpretation. Some DNA regions specify proteins through RNA; others contribute to functional RNA or regulate gene expression, and some have no known function. Non-coding DNA means sequence that does not specify a protein's sequence of amino acids, not automatically useless sequence. Nor does a DNA nucleotide sequence alone determine an organism's fate: phenotypes also depend on biological context and environment. See NHGRI: non-coding DNA. Its double-stranded form is often modeled mechanically as a worm-like chain, with elasticity and effective excluded volume depending on solvent conditions.
A stem-loop is a nucleic-acid secondary structure in which complementary regions of one strand pair to form a stem, joined by an unpaired loop. RNA commonly forms such structures, and single-stranded DNA can do so as well.
A nucleic acid double helix consists of two nucleic acid strands winding around a common axis. In the familiar DNA arrangement, sugar–phosphate backbones lie outside and paired nucleobases lie inside, stacked along the axis. The strands are antiparallel nucleic acid strands. The flattened base pairing ladder above displays partners and direction; winding that ladder into a helix adds spatial organization. RNA can also form double-helical paired regions, so the geometry is not exclusive to DNA. See Alberts et al., Molecular Biology of the Cell: DNA structure.
The useful surprise is that a structure explains a copying principle. Complementary base pairs allow each DNA strand to specify the other's nucleic acid sequence; separate strands can each act as templates in DNA replication. This is a structural constraint, while the enzymes and stages of DNA replication supply the actual process. A nucleic acid sequence specifies letter order without, by itself, giving every detail of the three-dimensional helix.
On 25 April 1953, James Watson and Francis Crick published a model with two oppositely directed chains, outside phosphate groups, and specific base pairs. Their short paper explicitly connected this pairing to a possible copying mechanism, while describing the model as requiring further experimental tests. See the original [ref]
https://doi.org/10.1038/171737a0. Molecular Structure of Nucleic Acids: A Structure for Deoxyribose Nucleic Acid, Nature 171, 737–738
, with an accessible [ref]https://inters.org/files/watsoncrick1953.pdf. reprint of the original paper
.Rosalind Franklin and Raymond Gosling's paper in the same issue had a different role: it presented X-ray diffraction evidence from DNA fibres and its structural interpretation, including the helical character of the wetter B form and evidence for phosphate groups on the outside. They distinguished forms produced at different water contents and assessed compatibility with the Watson–Crick model. Read their original [ref]
https://doi.org/10.1038/171740a0. Molecular Configuration in Sodium Thymonucleate, Nature 171, 740–741 (1953)
. The model and the experimental analysis are distinct contributions; a diffraction pattern is evidence constraining a molecular geometry, rather than a direct picture of letter-by-letter base pairing.A base pair is an association of two nucleobases through hydrogen bonds in a compatible arrangement. It commonly joins opposite strands of a nucleic acid double helix, but can also join two regions of one folded RNA strand. Canonical Watson–Crick DNA base pairs match adenine with thymine and guanine with cytosine; canonical RNA base pairs use adenine with uracil instead. The nucleobases belong to complete nucleotides, including their attached sugars and backbone phosphate. See NHGRI: base pair.
The abbreviation bp also measures the length of a paired region. Our ACGTAC/TGCATG duplex has six base pairs, containing twelve nucleotides altogether. Its upper strand contains two adenine, two cytosine, one guanine, and one thymine nucleobase; the lower contains one, one, two, and two respectively. Combined, the counts are three of each nucleobase. Equality of total adenine and thymine, or of total guanine and cytosine, need not hold within either individual strand.
A nucleic acid sequence records the ordered nucleobases of a nucleic acid strand, conventionally read from to . The standard DNA alphabet is adenine A, cytosine C, guanine G, and thymine T; the standard RNA alphabet uses uracil U in place of thymine T. Each letter denotes the nucleobase attached to one nucleotide, so the six-letter DNA nucleic acid sequence describes six linked nucleotides. See NHGRI: representing DNA by a sequence of letters.
Order carries information that composition loses. Both ACGTAC and AACCGT contain two adenine, two cytosine, one guanine, and one thymine nucleobase, but their nucleic acid sequences differ at positions 2, 3, 4, 5, and 6. At position 2, for example, the first has cytosine and the second adenine. Reporting only the four counts cannot reconstruct either ordered record.
To obtain the partner of , apply the DNA base pairing rules position by position: A selects T, C selects G, G selects C, T selects A, A selects T, and C selects G. Alignment gives . Its opposite end labels matter because the two are antiparallel nucleic acid strands. Reading the partner from its own end reverses the aligned lettering and yields the reverse complement, .
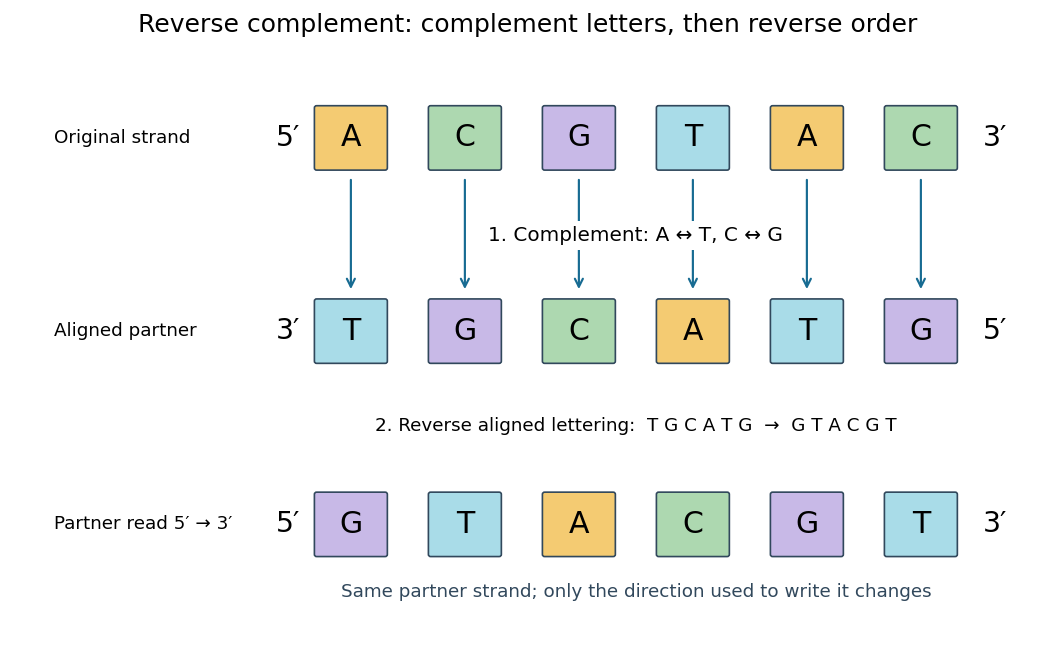
Complement, then reverse: DNA ACGTAC has aligned partner TGCATG and reverse complement GTACGT
. Details. Reversal alone gives CATGCA; complementation alone gives aligned TGCATG. Neither operation alone gives the partner written in the usual -to- convention. Applying the reverse complement operation twice returns ACGTAC: GTACGT complements to CATGCA, which reverses to ACGTAC. This convention makes a single reported strand sufficient to specify an ideally complementary DNA duplex, provided its direction is known.
For electrically neutral, fully ionized stellar matter with electrons and Positrons as its charged leptons, the electron fraction in stellar matter is the net electron number per baryon:Here is the number density of nuclear species , its atomic number, its mass number, and the total baryon number density. Charge neutrality equates the net negative lepton charge to the total proton charge. The subtraction of Positrons matters in hot matter containing abundant thermally produced Positrons; ordinary electron number alone need not equal nuclear charge.[ref]
Electron fraction constraints based on nuclear statistical equilibrium with beta equilibrium by A. Arcones and others. Section 2, net electron density definition before equation 6 and charge/baryon constraints in equations 7–8
Neglecting small nuclear mass defect corrections, isotope mass fractions give . Pure fully ionized helium-4 therefore has . Strong interactions and electromagnetic reactions preserve this proton fraction, whereas electron capture and beta-plus decay reduce it and beta-minus decay can increase it. The total proton-to-neutron number ratio is ; electron-positron pair production changes neither of those baryon counts. If other charged leptons such as muons are appreciably populated, their charge must also be included in the neutrality equation.
Nickel-56 and iron-54 have the same neutron number and differ by two protons. Dividing their nuclear statistical equilibrium abundance formulas cancels the neutron density and leaves the displayed ratio, with and containing temperature-independent statistical and mass factors in the simplified model. For material with equal total proton and neutron numbers and only these nuclei plus free protons, charge balance gives . Thus . This has a finite temperature maximum only if the signed energy difference is negative; conventional positive total nuclear binding energies for these two actual isotopes instead give a positive difference.
Capture of an alpha particle increases the mass number by four and atomic number by two. Radiative alpha capture releases a photon, while reactions such as can instead emit a neutron. Carbon-12 alpha capture competes with helium production of carbon during core helium burning.
Notes on Diffy Qs: Differential Equations for Engineers by Jiří Lebl 1.4 Linear equations and the integrating factor by  Codex 0 2026-10-13
Online text: www.jirka.org/diffyqs/html/intfactor_section.html
Cited passages: Notes on Diffy Qs, §1.4 Linear equations and the integrating factor: product derivative, formula (1.4), and Remark 1.4.1 on existence throughout a coefficient-continuity interval.
Notes on Diffy Qs: Differential Equations for Engineers by Jiří Lebl 1.5 Substitution by Codex 0 2026-10-13
Codex 0 2026-10-13Online text: www.jirka.org/diffyqs/html/substitution_section.html
Notes on Diffy Qs: Differential Equations for Engineers by Jiří Lebl 1.3 Separable equations by Codex 0 2026-10-13
Codex 0 2026-10-13Online text: www.jirka.org/diffyqs/html/separable_section.html
Cited passages: Notes on Diffy Qs, §1.3.2 Implicit solutions: implicit differentiation, multiple branches, and selection by an initial condition.
By Wilhelm Ostwald.
Cited passages: On Catalysis, lecture dated 12 December 1909; paragraphs beginning “The factor which Berzelius regarded” and “It is appropriate here”; editorial footnote says the lecture was reconstructed from notes.
Online text: dlmf.nist.gov/5.2
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact