
Pivotal quantity Created 2026-09-24 Updated 2026-10-24
Paley-Zygmund inequality Created 2026-09-24 Updated 2026-09-24
Multivariate normal distribution Created 2026-09-24 Updated 2026-10-05
Multiple hypothesis testing Created 2026-09-24 Updated 2026-10-14
Multiple hypothesis testing applies tests to a family of null hypotheses while controlling an aggregate error criterion.
Markov additive process Created 2026-09-24 Updated 2026-09-24
A Markov additive process couples a Markov chain to an additive functional whose increments depend on the chain.
Kac's lemma Created 2026-09-24 Updated 2026-10-03
For an irreducible positive recurrent Markov chain with stationary distribution , the expected return time to state is . More generally, expected occupation rewards in a return cycle equal their stationary rate times the expected cycle length.
Gronwall inequality Created 2026-09-24 Updated 2026-10-13
Gaussian tail bound Created 2026-09-24 Updated 2026-09-24
Galton-Watson process Created 2026-09-24 Updated 2026-10-13
A Galton-Watson process is a branching process that counts individuals by generation. Start with one ancestor, , and let all offspring counts be independent and identically distributed random variables taking nonnegative integer values with a common offspring distribution. ThenThe empty sum is zero: zero is an absorbing state, so once a generation is empty every later generation is empty. The same offspring distribution applies to every individual in every generation. [ref]
https://ocw.mit.edu/courses/18-445-introduction-to-stochastic-processes-spring-2015/27aaeb9eb9a9cecce93d9ad74413ddf5_MIT18_445S15_lecture19.pdf. Hao Wu, MIT 18.445, Lecture 19, slides 3–4
For a concrete offspring distribution, take , , , and for . An individual has no children with probability , one with probability , and two with probability . The offspring expected value is . A possible sequence of generation sizes is : two children need not lead to a permanently growing family.
The probability generating function gives the exact generation probability distributions through branching-process generating-function iteration. With and , the second generation hasThus and . The figure shows full generation probability mass functions, computed by polynomial function composition, through generation six; no simulated frequencies are used.
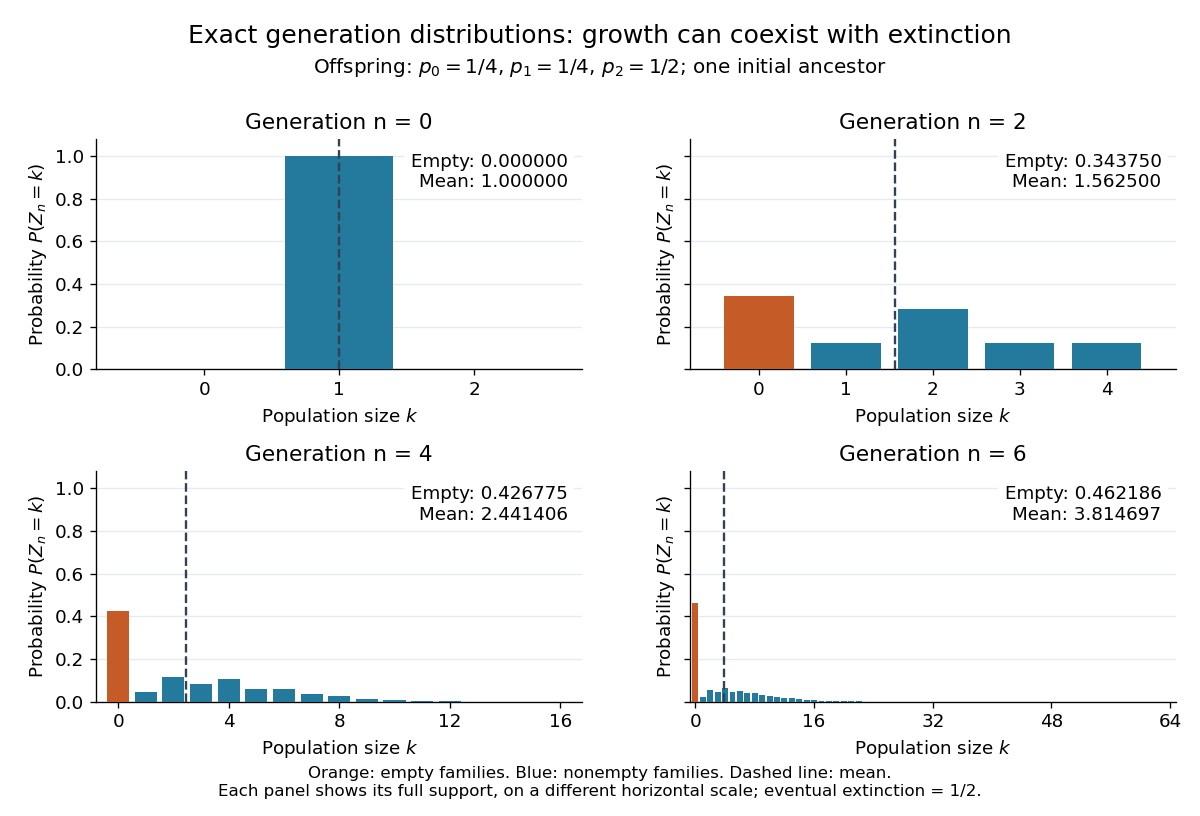
The contrast is striking: the expected generation size in a Galton-Watson process grows as , while the branching extinction probability is . By generation six, although . Larger surviving families carry the rising expected value; that mean is an average over possible families, not a forecast of one family's path. The Galton-Watson extinction fixed point turns an unbounded number of future generations into a single equation for this probability.
The historical question was the disappearance of surnames passed through male descendants. In Watson and Galton, On the Probability of the Extinction of Families, pages 139–140, Francis Galton formulates a constant-law model counting sons who reach adulthood, and Watson computes later generation probability distributions by composing generating functions. Those are assumptions of their model, rather than a claim that actual human reproduction follows this offspring distribution.
F-test Created 2026-09-24 Updated 2026-09-24
Expected energy Created 2026-09-24 Updated 2026-09-24
Cover time Created 2026-09-24 Updated 2026-09-24
Cauchy-Schwarz inequality Created 2026-09-24 Updated 2026-10-07
Branching-process extinction criterion Created 2026-09-24 Updated 2026-09-24
Bayesian normal model Created 2026-09-24 Updated 2026-09-24
Augmented Markov chain Created 2026-09-24 Updated 2026-09-24
Statistical modelling Created 2026-09-24 Updated 2026-09-24
Statistical modelling constructs, fits, checks, and interprets a statistical model for observed data.
Information theory Created 2026-09-24 Updated 2026-10-18
Information theory quantifies how much uncertainty messages contain, how efficiently they can be represented, and how reliably they can pass through a noisy channel. Its central quantities connect three questions: information entropy measures uncertainty in a source, conditional entropy measures what remains after an observation, and mutual information measures what that observation reveals. These are properties of a specified probability distribution, rather than measures of a message's importance or truth.
For a concrete source, suppose symbols have probabilities . A fixed-length binary representation needs two bits per symbol. Instead assign the prefix code , , , . Reading from left to right gives an unambiguous decoding because no codeword begins another. The expected value of the length isThis saves an average of of a bit per symbol, or of the fixed-length representation, with no loss of symbols. The lengths are exactly , so the average equals the source's Shannon entropy. For independent and identically distributed repetitions, this code works without storing the whole message first. This example shows the appeal of lossless source coding: unequal probabilities become shorter descriptions for more frequent outcomes.
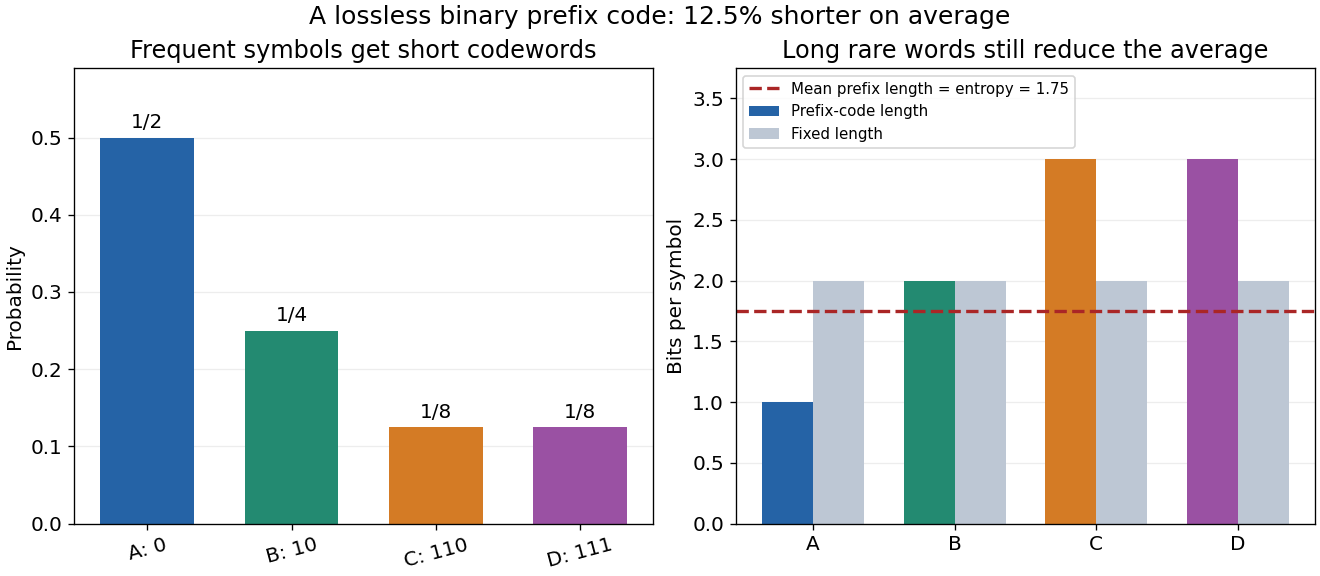


Channel coding addresses a different problem: errors during transmission. A shorter representation removes predictable structure; an error-correcting representation adds carefully chosen structure that helps recover corrupted symbols. Shannon's source coding theorem and the Shannon second coding theorem identify limits for these respective tasks under their hypotheses. The beauty is that source details and hardware details can meet through a small number of mathematical quantities, notably information entropy and channel capacity.
Claude E. Shannon's A Mathematical Theory of Communication appeared in the Bell System Technical Journal in July and October 1948. Its introduction separates the engineering problem of reproducing messages from their semantic meaning; subsequent sections develop probabilistic source models, noiseless coding, and transmission with noise. It also acknowledges earlier work by Harry Nyquist and Ralph Hartley.[ref]
Probability theory Created 2026-09-24 Updated 2026-10-18
Probability theory describes uncertainty through a probability space: possible outcomes form a sample space, observable questions are events, and a probability measure assigns them numbers between zero and one. The Kolmogorov axioms make those assignments consistent. They let us combine information about several events, update it through conditional probability, and study random variables without listing every possible outcome separately.
For example, roll two dice whose results are independent random variables, each with a discrete uniform distribution on . There are 36 equally likely ordered outcomes. Only have sum seven, so that event has probability . The sum itself is not uniformly distributed: sum two has only one outcome. Choosing a probability distribution for the elementary outcomes is part of the model; equal likelihood does not follow merely from counting the named possibilities.
The subject becomes especially useful when complete outcome lists are enormous or infinite. Independence turns a joint calculation into simpler pieces, expected value summarizes a random variable, and the law of large numbers explains how averages can become predictable even when individual observations are uncertain. The central limit theorem describes the scale and shape of many remaining fluctuations. These are distinct claims: a small variance of an average does not make every observation close to its expected value.
There is a satisfying unity here: dice, hidden causes, and Brownian motion all use the same rules for events and conditional probability. A model still needs justification. Its exact deductions describe what its assumptions imply; comparison with observations belongs to statistical inference.
Total variation distance Created 2026-09-24 Updated 2026-10-13
Total variation distance asks how much two probability distributions can disagree about the same event. For probability measures on one measurable space , its definition isThe supremum ranges over all measurable sets, so guarantees that every yes-or-no prediction has probability error at most . This metric takes values between zero and one; it is zero exactly when the two probability measures agree. This makes it useful for comparing a sampling algorithm's output with its target probability distribution, and for defining the mixing time of a Markov chain.
On a finite set, add the excess probability mass wherever exceeds . That excess is also half the sum of all absolute differences:The last expression reveals the common probability mass that the two probability distributions can share.[ref]
Markov Chains and Mixing Times, second edition by David A. Levin and others. §4.1, Proposition 4.2 and Remark 4.3, printed p. 48; §4.2, equation (4.13), printed p. 51
The coupling characterization of total variation distance turns this overlap into an actual joint construction; minimum sum of errors in a simple hypothesis test gives it a statistical interpretation. One quantity connects probability bookkeeping, comparison of sampling methods, and the limits of a statistical test. There are unlisted articles, also show them or only show them.