
Knot Created 2026-09-24 Updated 2026-10-14
A knot is the image of a smooth embedding , considered up to ambient isotopy. The circle supplies a closed loop with no free ends; the smooth embedding condition rules out self-intersections and requires a nonzero tangent vector in a regular parametrization. The equivalent convention uses the three-sphere: removing a point outside the knot identifies the remaining space with three-dimensional Euclidean space by stereographic projection.
More precisely, knots are equivalent if there is a smooth family of diffeomorphisms of the ambient space, for , such that is the identity and . Every intermediate remains a smooth embedding. This ambient isotopy allows bending, stretching and moving a loop, but neither cutting it nor letting strands cross through each other. We compare the embedded images rather than their parametrizations; an oriented knot additionally remembers a direction of travel.
For a worked example, start with , where is taken modulo , and useBoth scale factors stay positive, so each is a diffeomorphism. At the circle becomes the ellipse , yet its knot type is still the unknot. Exact lengths and angles are therefore irrelevant to knot type; self-intersection is the obstruction that the deformation must avoid.
Linearized boundary condition Created 2026-09-24 Updated 2026-09-24
For a small boundary displacement and weak disturbance, evaluate boundary data on the undisturbed surface and discard products of small quantities.
Kinematic boundary condition for a free-surface graph Created 2026-09-24 Updated 2026-09-24
Geodesic conserved quantity from a Killing vector Created 2026-09-24 Updated 2026-10-14
Each Killing vector field supplies a conserved quantity for freely moving test particles: it turns a geometric symmetry into a first integral of the geodesic equation. Let be a geodesic with affine parameter , tangent vector , and . Wherever a Killing vector field is defined along the geodesic,The statement applies to Riemannian manifolds and to timelike geodesics, null geodesics and spacelike geodesics in a Lorentzian manifold. It requires an affine parameter; for a massive test particle, proper time is one choice. See Tong, section 4.3.2, equation (4.32).
For a worked example in the Euclidean plane, take with affine parameter and velocity . The Euclidean Killing vector fields for translation and rotation giveThe rotational field along the geodesic is : it changes from at to at , yet its pairing with stays . With toy mass and interpreted as time, the first constant is the component of linear momentum, and the second is the signed component of angular momentum about the origin. Their numerical values use toy units. The geodesic is straight; the rotation flow orbits are circles.
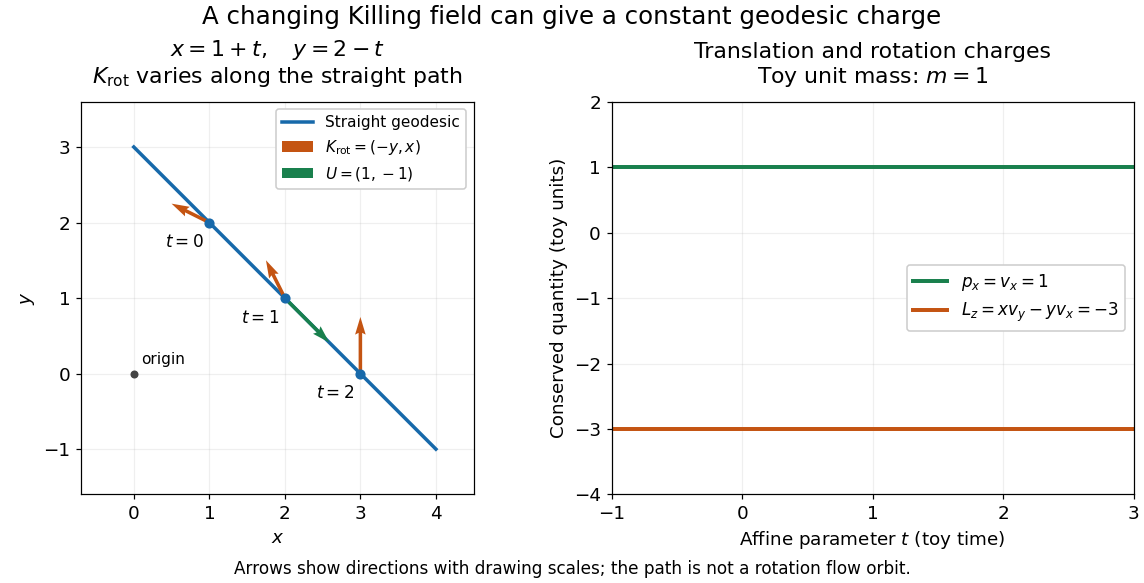
One straight Euclidean geodesic: the rotational Killing field varies while translation momentum and angular momentum stay constant for toy unit mass
. Details. This conservation law follows from metric compatibility and the Killing equation:The geodesic equation kills the acceleration term, and the symmetric product selects the vanishing symmetric derivative. This tensor contraction is the whole proof outline; see Carroll, equation (5.43).
In a stationary spacetime, a chosen time-translation Killing vector field gives Killing energy. With metric signature , , and a massive test particle's four-momentum , the physical normalization isHere generates the axial rotational symmetry when one exists. In coordinates with and , these are and . Both are conserved quantities along the geodesic, even if the metric has a time-angle cross term. A future timelike makes positive for a future massive particle; the scale of depends on the normalization of . Not every spacetime has a global timelike Killing vector field, and a stationary field can become spacelike in an ergoregion of a stationary spacetime. Conservation on the field's domain does not imply a universal global positive energy; see Tong, sections 4.3.1-4.3.2 on the timelike-domain qualification and conserved charges.
Active-set transition in capped resource allocation Created 2026-09-24 Updated 2026-10-14
Discrete scattering data Created 2026-09-24 Updated 2026-10-14
Discrete scattering data consist of the discrete eigenvalues and norming constants associated with bound states of the auxiliary spectral problem. Their simple time evolution reconstructs solitons and breathers through the inverse problem.
Mountain-wave cutoff Created 2026-09-24 Updated 2026-10-14
A steady hill pattern seen by a uniform flow of speed has intrinsic frequency magnitude . It radiates a propagating internal wave only for ; above this cutoff the vertical wavenumber is imaginary and the disturbance is evanescent.
Vertical trapping of an internal gravity wave by planar strain Created 2026-09-24 Updated 2026-10-14
Buoyancy frequency Created 2026-09-24 Updated 2026-10-14
The buoyancy frequency is the natural angular frequency of small vertical oscillations in a stably stratified fluid.
Square-free integer Created 2026-09-24 Updated 2026-10-14
A positive integer is square-free when no square number greater than one is a divisor of . It suffices to exclude squares of prime numbers; equivalently, every prime valuation is zero or one:Thus the prime factorization of a square-free integer is a product of distinct prime factors, with no repetitions. One is included: its prime factorization is an empty product and all its prime valuations are zero. These equivalent tests are stated in Grinberg's notes. [ref]
https://darijgrinberg.gitlab.io/floor.pdf. Darij Grinberg, MIT 18.781, Floor and arithmetic functions, Definition 2.1.2 and footnote 6
For signed integers, extend the definition by requiring to be a square-free integer, where denotes absolute value. Hence and both qualify. Zero does not: every prime number has its square as a divisor of zero. The Möbius function and radical of an integer below use their existing positive integer domains, so apply them to when handling a negative integer.
For example, is a square-free integer, whereas is not, because and . Being a composite number causes no problem: are all square-free integers. A square-free integer need not be coprime to another integer: and are both square-free integers but have greatest common divisor two. In fact the only signed integers coprime to every integer are , since .
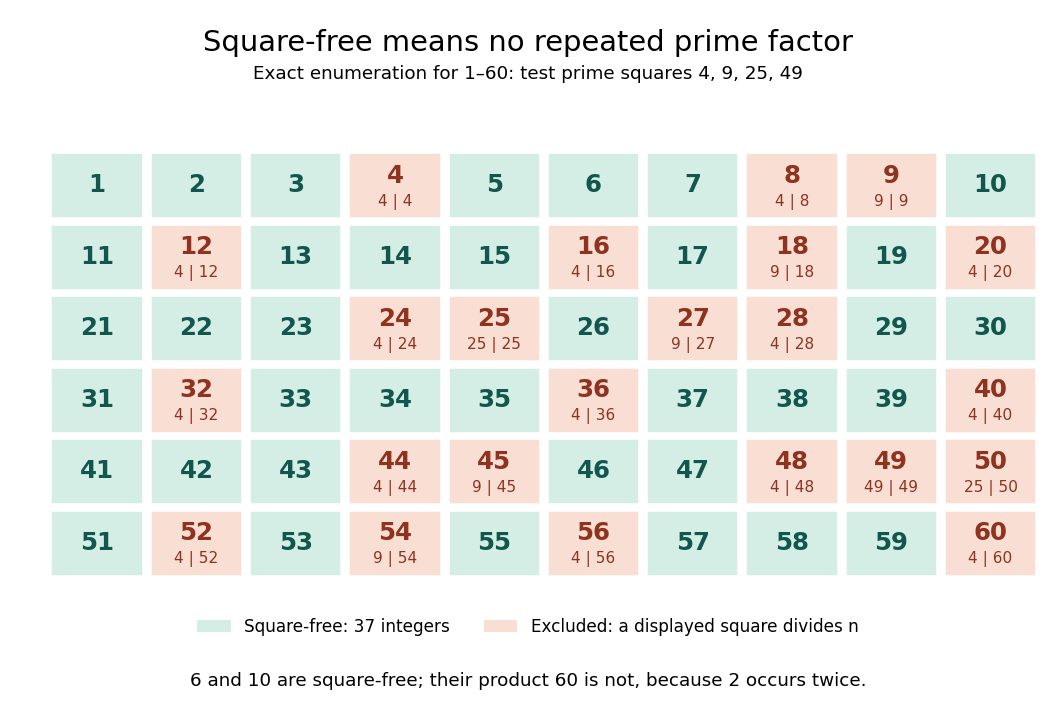
Exact square-free integer classification of the integers from one to sixty
. Green cells are square-free integers; each red cell displays a prime number square that divides its label, choosing the smallest such prime number. Only need testing in this range. There are green cells. This original finite arithmetic diagram is an exact enumeration, not a measurement or an assertion about a limiting frequency. Details.For positive integers , the useful product criterion isThe proof outline is just addition of prime valuations: can stay at most one only if neither input repeats a prime factor and no prime factor occurs in both. Thus is a square-free integer, but is not. An equivalent characterization is that every factorization into positive integers has coprime factors. If , the factorization supplies two factors sharing ; conversely, a shared prime factor forces its square to divide . For , the unordered factor pairs all have greatest common divisor one; for , the pair fails.
Two existing arithmetic functions turn the definition into practical tests:The radical of an integer keeps one copy of each prime factor, so it changes precisely the integers with a repeated prime factor. Its definition is given in Evertse's exercise sheet. [ref]
https://pub.math.leidenuniv.nl/~evertsejh/dio12-ex4.pdf. Jan-Hendrik Evertse, Diophantine approximation, Homework IV, Exercise 20
The Möbius function assigns to a square-free integer with distinct prime factors and zero otherwise; squaring forgets the sign. Consequently counts exactly the green cells. This connects a restriction on repeated prime factors with weighted counting and inclusion-exclusion. [ref]https://darijgrinberg.gitlab.io/floor.pdf. Darij Grinberg, MIT 18.781, Definition 2.1.2: the Möbius function
Odd number Created 2026-09-24 Updated 2026-10-03
An integer is odd when it is not divisible by two.
Even number Created 2026-09-24 Updated 2026-10-14
An integer is even when it is divisible by two.
Odd integer Created 2026-09-24 Updated 2026-10-03
An odd integer is not divisible by two; equivalently, it has the form .
Positive integer Created 2026-09-24 Updated 2026-10-03
Unicity distance Created 2026-09-24 Updated 2026-10-14
Unicity distance is the ciphertext length at which key equivocation reaches zero and the key becomes uniquely determined under the source model.
Asymptotic equipartition property Created 2026-09-24 Updated 2026-10-14
The asymptotic equipartition property explains why a long message from a source can usually be described using its information entropy per symbol. Individual messages can have very different probabilities, but the messages carrying almost all the total probability have similar logarithmic costs per symbol. The Bernoulli typical-set example makes the distinction between an individual message and a large collection explicit.
For independent and identically distributed random variables on a finite alphabet, let be their probability mass function and . ThenHere means the probability mass of the realized word, evaluated under the source law. The product rule for independent random variables turns its information content into a sum:The strong law of large numbers gives the limit. Zero-probability symbols do not occur; on the positive-probability support of a finite alphabet, these information costs are finite. The corresponding typical set consists of words whose cost per symbol is within a chosen tolerance of .
For a strictly stationary process with a finite alphabet, the constant-limit extension requires ergodicity. The Shannon-McMillan-Breiman theorem then replaces the one-symbol information entropy with the information rate. Stationarity without ergodicity in an information source shows why stationarity alone is insufficient.[ref]
6.441 Information Theory (Spring 2016 lecture notes) by Yury Polyanskiy and others. §8, Theorem 8.1 and Corollary 8.2, printed p. 90: stationary ergodic sources and typical sets
Bernoulli source Created 2026-09-24 Updated 2026-09-24
Huffman coding Created 2026-09-24 Updated 2026-10-14
Huffman coding makes frequent symbols cheap to store by giving them short codewords, while allowing rare symbols longer codewords. For a known probability distribution on a finite alphabet with at least two positive-probability symbols, binary Huffman coding constructs a prefix code minimizing expected codeword length among binary prefix codes that encode one source symbol at a time. The objective is an average under that probability distribution; it does not promise to shorten every message. Encoder and decoder must agree on the resulting Huffman code. [ref]
The construction grows a binary tree from its leaves towards its root of a tree. Start with one leaf per symbol, weighted by its probability. Repeatedly join the two currently smallest weights beneath a new parent in a rooted tree, whose weight is their sum, and replace the pair by that subtree. Include newly formed subtrees when choosing the next pair. When one tree remains, label the two outgoing edges at every internal vertex with and ; the labels on the graph path from the root of a tree to a symbol give its codeword. This is a greedy algorithm: each step makes a locally cheapest merge, yet the result is an optimal prefix code.
For a concrete example, use probabilities , , , . First join and , creating weight . The remaining weights are for , for the subtree, and for . Join the two weights to make , then join with that subtree to make . The merge weights are therefore . Each merge adds one bit to every codeword below it, so their sum is the expected codeword length: bits per source symbol. The diagram fixes the edge labels to produce the Huffman code used below.
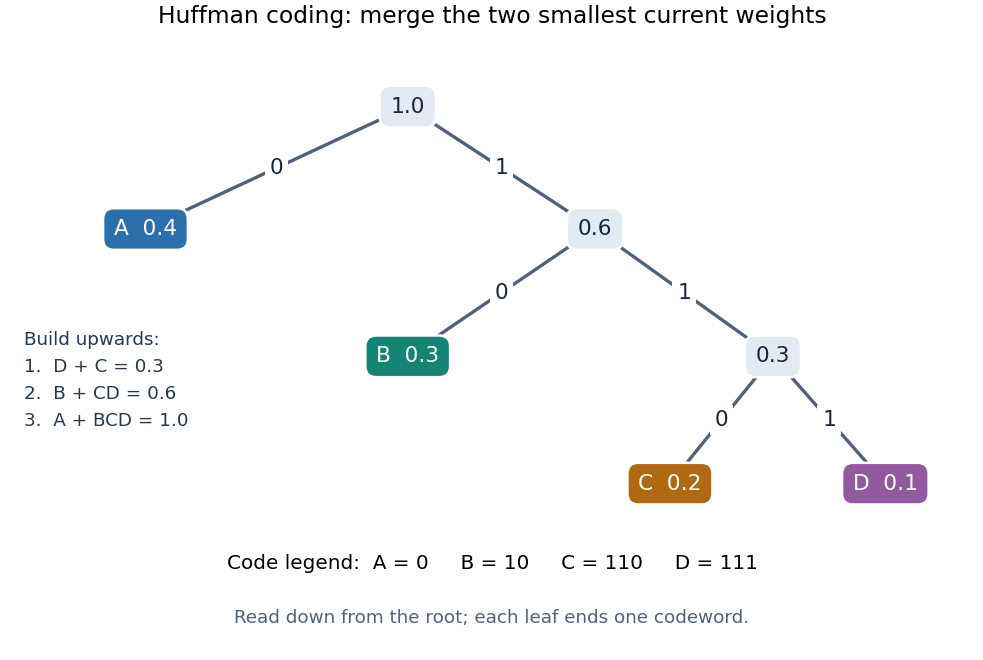


The useful insight is that choosing short codewords is a resource allocation problem: the prefix code condition constrains the available codeword lengths through the Kraft inequality. Huffman coding solves this one-symbol problem exactly for the supplied probability distribution. For repeated emissions of a memoryless classical information source, the same Huffman code can be applied symbol by symbol. More general compression can exploit dependencies or encode groups of symbols; the one-symbol optimality statement does not compare all such methods.
One-to-one source code Created 2026-09-24 Updated 2026-09-24
A one-to-one source code is an injective function from source symbols to finite codewords. Unlike a prefix code, it need not permit instantaneous decoding of concatenated codewords.
Information entropy Created 2026-09-24 Updated 2026-10-14
For a finite discrete random variable with probability mass function , its information entropy is the expected value of its information content:Base-two logarithms give bits; choosing a different base rescales the units. The convention is justified by a limit, so outcomes of zero probability contribute nothing. The definition also applies to countable distributions, but the sum may be infinite.
A fair bit has . A certain outcome has . A Bernoulli random variable that is one with probability has bits, because most of its outcomes are predictable. A rare outcome still has large information content: the outcome of probability contributes bits of surprise when it occurs. Entropy is the average surprise, rather than the surprise of each outcome.
For possible outcomes, , with the upper bound attained exactly by the uniform distribution on a finite set. The Gibbs inequality proves this by comparing with the uniform distribution: . Thus increasing predictability reduces the required average description length. The four-symbol prefix code in information theory attains bits exactly; for general probabilities, integer codeword lengths prevent such a perfect match for every individual symbol. Shannon's source coding theorem explains how coding sufficiently long independent blocks approaches the entropy per symbol.
The logarithm is especially natural because independent outcomes have additive surprise: . Taking expected values gives additive information entropy for independent random variables; for dependent ones, the chain rule for information entropy replaces the second term by conditional entropy. This is why the same quantity can govern both a single observation and a long message.
There are unlisted articles, also show them or only show them.