
The first-kind Chebyshev polynomial converts a multiple-angle cosine into a polynomial:The cosine addition formula gives the recurrence relationThis constructs polynomials valid for every real , including outside , where the real-angle description is unavailable. For example,For , has polynomial degree and leading coefficient . On its uniform norm is one, even as its oscillations become more numerous.[ref]
https://dlmf.nist.gov/18.5#i. T. H. Koornwinder and collaborators, NIST Digital Library of Mathematical Functions, §18.5(i), equation 18.5.1: trigonometric representation
[ref]https://dlmf.nist.gov/18.9#i. Koornwinder and collaborators, NIST DLMF, §18.9(i), Table 18.9.1: recurrence coefficients
The polynomial roots of are especially simple:They correspond to equally spaced angles, but their locations in cluster near and . For , the polynomial roots are . For , the positive polynomial roots are approximately , with their negatives completing the set. The distance from the right endpoint to the nearest polynomial root is ; central neighboring polynomial roots are separated on the larger scale . The small change of cosine near angles zero and explains the clustering.
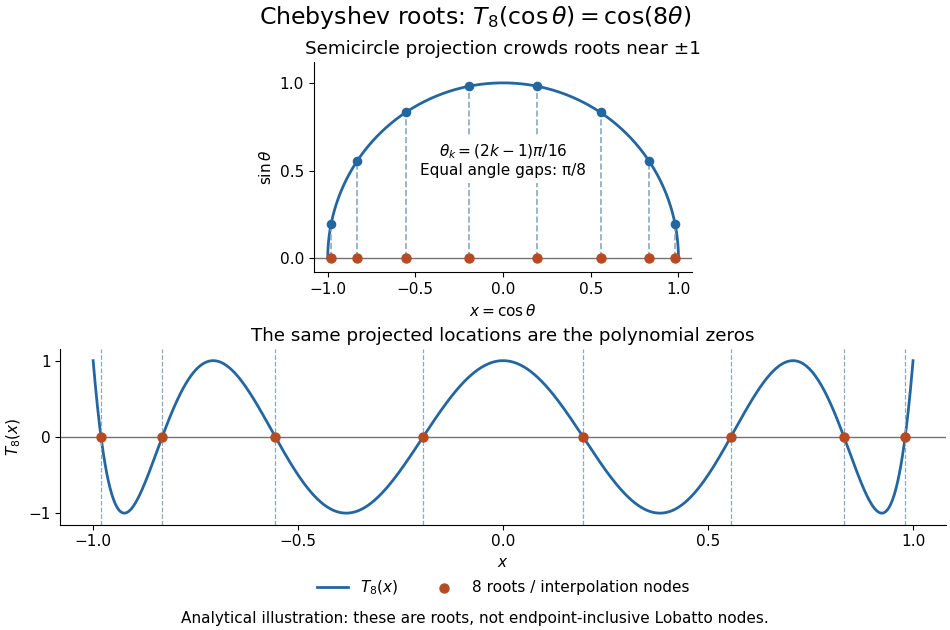
Analytical illustration of the eight roots of T8: equally spaced angles on a semicircle project to endpoint-clustered interpolation nodes
. Details. These polynomial roots supply interpolation nodes for a polynomial interpolation of polynomial degree at most . They differ from the Chebyshev-Lobatto nodes , which include both endpoints. This choice of polynomial roots has nodal polynomialThe monic Chebyshev extremal polynomial minimizes the uniform norm of this product among monic polynomials of polynomial degree on . Consequently, if has continuous derivatives, the usual polynomial interpolation error gives the useful boundThis optimizes the nodal factor in that bound, not the actual error for every function. Endpoint clustering helps control the large endpoint oscillations of equally spaced interpolation associated with Runge's phenomenon. The two node conventions and their geometric construction are discussed in Trefethen's authored text.[ref]
https://people.maths.ox.ac.uk/trefethen/ATAP/ATAPfirst6chapters.pdf. Lloyd N. Trefethen, Approximation Theory and Approximation Practice, Chapters 2–3 and Exercise 2.4: endpoint clustering, first-kind roots and polynomials
The same cosine substitution for polynomial approximation explains the weighted orthogonality:The endpoint singularities of the weight are integrable. Thus the Chebyshev polynomials are orthogonal polynomials for this weight, making coefficients in a least-squares polynomial in an orthogonal-polynomial basis separate cleanly. Their polynomial roots also give Chebyshev–Gauss quadrature, connecting polynomial interpolation to Gaussian quadrature.[ref]
Accuracy still depends on the target function. The absolute value function has a corner at zero, so the hypothesis requiring continuous derivatives in the displayed polynomial interpolation error bound fails. Endpoint clustering cannot remove that corner. A jump poses a stronger obstruction: polynomials are continuous functions, so they cannot converge in the uniform norm to a discontinuous function on the whole interval. Chebfun's documented examples show persistent overshoot for such jumps; these are a limitation of global polynomial interpolation, not a universal promise of rapid accuracy from Chebyshev polynomials.[ref]
https://www.chebfun.org/docs/guide/guide04.html#4.3. Chebfun development team, Chebfun Guide, §4.3: polynomial interpolation of discontinuous functions
Gaussian quadrature is a quadrature rule that chooses both sample locations and coefficients to achieve unusually high polynomial exactness. For a finite interval with , assume the integration weight is integrable and positive almost everywhere. DefineLet be the monic orthogonal polynomial of polynomial degree for the inner product : it satisfies for every polynomial of polynomial degree below . The polynomial roots of are distinct and inside ; take them as the nodes . Integrate the Lagrange cardinal polynomials to obtain . These coefficients are positive, andThe integration weight and the discrete coefficients play different roles: specifies the integral being approximated, while tell us how much each sample contributes.[ref]
https://dlmf.nist.gov/3.5#v. Nico M. Temme, NIST Digital Library of Mathematical Functions, §3.5(v), Gauss quadrature: nodes, coefficients and exactness
A proof outline explains the gain over simply integrating an arbitrary polynomial interpolation. Use polynomial division to write , with and . Orthogonality makes , and sampling at the polynomial roots of makes . The Lagrange cardinal polynomials recover exactly, so both expressions agree. Also , since has polynomial degree . This is the mechanism behind positive weights of Gaussian quadrature.
For a concrete two-node example, set on . The Legendre polynomial has polynomial roots . Its monic polynomial version has zero integral against both and , as required. Symmetry and exactness for the constant polynomial give . Thus the Gauss–Legendre instance of Gaussian quadrature isDirect evaluation on gives , exactly their integrals. For the polynomial , two samples therefore give exactly. But for the rule gives , whereas the integral is : the error is .
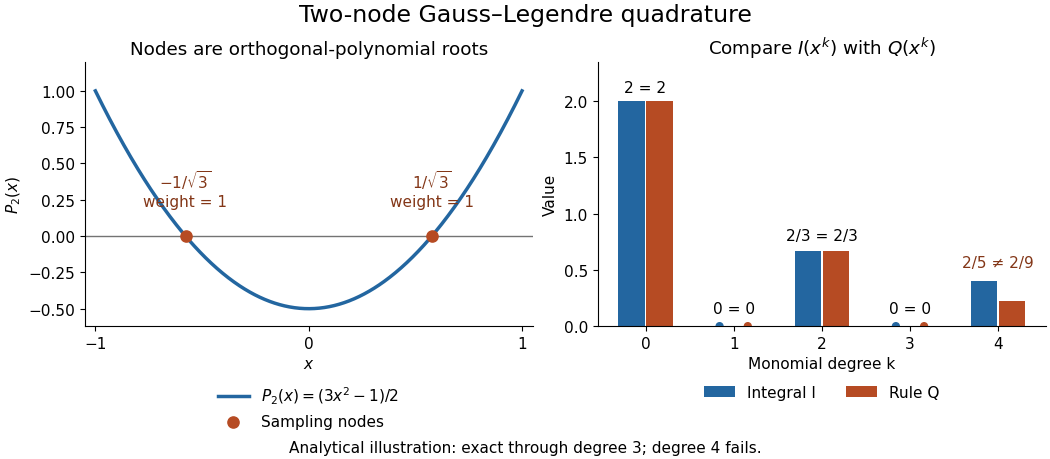
Analytical illustration of two-node Gauss–Legendre sampling: exact monomial integrals through degree three and failure at degree four
. Details. The ceiling is sharp for distinct real nodes under the positive-weight assumptions. Their squared nodal polynomial has polynomial degree , is zero at every sample, and has a strictly positive weighted integral. Thus no such quadrature rule integrates every polynomial of polynomial degree exactly. Nor does Gaussian quadrature integrate every nonpolynomial function exactly: the same two-node example gives , while .
Gaussian quadrature is useful when evaluations are costly and a modest polynomial captures the integrand well. More precisely, for a continuous function and any polynomial of polynomial degree at most , positivity and constant exactness giveThe uniform norm on measures the approximation between samples. This bound connects quadrature rule accuracy to uniform approximation, rather than promising an error from sample count alone. Corners, sharp unresolved features and roundoff error require their own assessment; the absolute value function example already shows why polynomial exactness is a qualified guarantee.
A finite difference method approximates a differential equation by replacing derivatives with weighted combinations of nearby sampled function values. Finite difference coefficients are chosen by matching low-degree polynomials or a Taylor expansion. The resulting unknowns live on a grid, where the differential equation becomes a system of algebraic update or boundary equations.
For the one-dimensional heat equation with , a forward Euler method in time and a second-order central difference in space giveFor , the coefficients are nonnegative and sum to one, so each new value is a convex combination of neighboring values. This yields a maximum norm contraction for compatible homogeneous boundaries.[ref]
Finite Difference Computing with PDEs by Hans Petter Langtangen and Svein Linge. Chapter3, section3.1, Forward Euler discretization of one-dimensional diffusion
Consistency of a numerical method measures how accurately the grid equation reproduces a smooth exact solution; stability of a numerical method controls propagation of perturbations. Both matter for numerical convergence. A correct interior formula also needs a compatible boundary closure of a difference scheme and suitable initial conditions.
The Gershgorin circle theorem locates every eigenvalue of a square matrix using only its entries. A diagonal entry supplies a centre in the complex plane, and the sum of the off-diagonal absolute values in its row supplies a radius. Small off-diagonal couplings therefore confine the eigenvalues near the diagonal entries. This turns a global eigenvalue problem into a picture built one row at a time.
Precisely, let , with , and define the closed Gershgorin discsEvery eigenvalue of satisfies , including eigenvalues on the boundaries. No symmetry or diagonalizability is required. Despite the name, the theorem uses filled disks, not just their circular boundaries.[ref]
https://www.stat.uchicago.edu/~lekheng/courses/302/notes2.pdf. Gene H. Golub, CME 302: Numerical Linear Algebra, Lecture 2, §6, 2005; notes by James Lambers, edited by Lek-Heng Lim
The short reason is the triangle inequality. For a nonzero eigenvector with , choose with . The th row givesThus the largest eigenvector coordinate identifies a Gershgorin disc containing , even though that eigenvector need never be computed to use the bound.
This is useful when a full eigenvalue computation would be expensive: forming the Gershgorin discs needs one pass over the nonzero entries of a sparse matrix. If lies outside every Gershgorin disc, then is an invertible matrix, since zero is not an eigenvalue. The condition is exactly in every row, namely strict diagonal dominance. This connects diagonal dominance to solvability of a linear system; the inverse infinity-norm bound from diagonal dominance adds a quantitative bound. It is a sufficient test: failure to exclude zero does not prove singularity.
For a concrete symmetric matrix, takeThe three Gershgorin discs have centres and are pairwise disjoint. The finite-dimensional spectral theorem makes the eigenvalues real, so their possible locations reduce to the intervals , , and . Gershgorin eigenvalue counting gives exactly one eigenvalue in each. Independently, the characteristic polynomial iswhose numerical polynomial roots are , , and , rounded to six decimal places. All are positive, as Gershgorin bounds for symmetric matrices already guarantee without finding those polynomial roots.
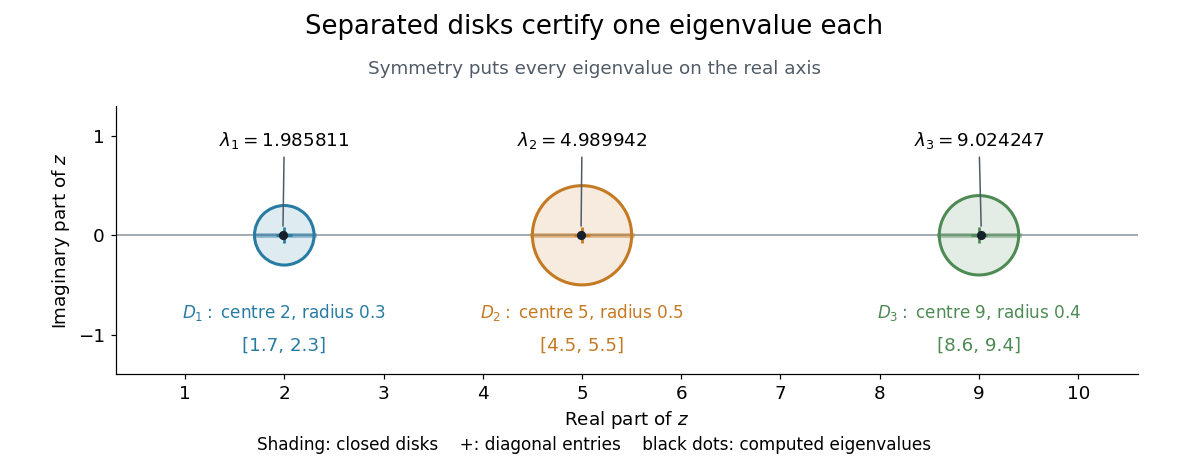
Three separated Gershgorin discs, each containing one real eigenvalue of the symmetric example
. Details. S. Gerschgorin published the result in 1931 in Über die Abgrenzung der Eigenwerte einer Matrix, in the Bulletin de l'Académie des Sciences de l'URSS, issue 6, pages 749–754. The original paper's §2 states both eigenvalue inclusion and counting in separated groups of Gershgorin discs; §3 already discusses column bounds and transformations preserving the eigenvalues. Thus both the localization picture and ways to sharpen it were part of the original development.[ref]
https://www.mathnet.ru/php/getFT.phtml?jrnid=im&paperid=5235&what=fullt&option_lang=eng. S. Gerschgorin, Über die Abgrenzung der Eigenwerte einer Matrix, 1931, pp. 749–754; original German paper in the journal archive
The discrete Fourier transform turns a finite list of samples into the weights of its discrete Fourier modes. The goal is to reveal a simple oscillatory recipe hidden in complicated-looking data, while retaining enough information to reconstruct every sample exactly. In signal processing, those weights identify sampled frequencies and wave phases; in numerical analysis, they simplify circular convolution and the discrete sine transform Poisson solver.
Start with eight real samples, indexed by :Writing , the actual list isThe discrete Fourier transform recovers the recipe asThe constant contributes ; the cosine contributes ; the half-sized sine contributes and . All other coefficients vanish exactly. The imaginary coefficients carry the sine's wave phase, which a plot of absolute values alone would hide.
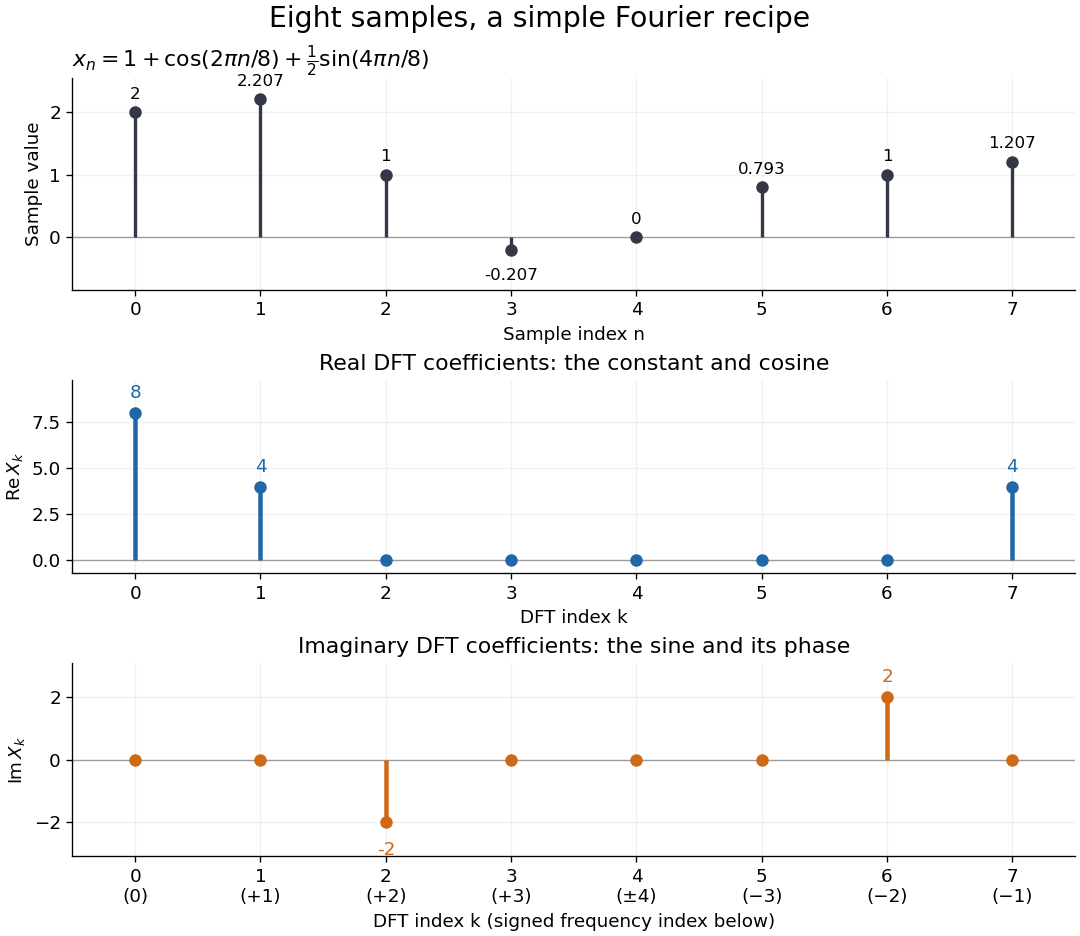


Precisely, for a positive integer and a vector , the forward discrete Fourier transform and inverse discrete Fourier transform used here areThus the forward exponent has a minus sign and no scale factor; the inverse exponent has a plus sign and the factor . The coefficients in the reconstruction are , rather than . In the example, , the pair reconstructs the cosine, and the pair reconstructs the half-sized sine. These conventions agree with the scaled Fourier coefficients in MIT's authored notes.[ref]
https://ocw.mit.edu/courses/6-02-introduction-to-eecs-ii-digital-communication-systems-fall-2012/06d7972059805d20e6a7db3a52ec23f2_MIT6_02F12_chap13.pdf. Hari Balakrishnan, Christopher Terman, and George Verghese, MIT 6.02 notes, Chapter 13, equations (13.15)–(13.16), 2012
The proof idea is orthogonality of roots of unity: for integers ,Distinct discrete Fourier modes cancel in this finite geometric series. Substituting the forward formula into the inverse discrete Fourier transform leaves only the desired sample. The same orthogonality makes the normalized discrete Fourier modes an orthonormal basis and gives the discrete Parseval identity, in the present convention,For the eight-sample example, direct squaring gives , while , so . This identity preserves the squared L2 norm after accounting for normalization. The existing discrete Parseval identity instead scales the forward discrete Fourier transform by , producing a unitary matrix and equal squared L2 norms without the factor .
For real input, discrete Fourier conjugate symmetry pairs positive and negative frequencies. The label is a residue modulo : when represents the same discrete Fourier mode as , since . It therefore represents negative frequency cycles per sample. If samples are seconds apart, the corresponding signed frequency is cycles per second. Similarly, index represents , while index is its own negative modulo .
The discrete Fourier transform is an invertible map between two finite vectors. The continuous Fourier transform instead describes a function on the real line by an integral over a continuous frequency variable. A finite list of samples does not determine the full continuous frequency spectrum: aliasing of discrete Fourier modes already supplies distinct waveforms with identical observations. Applying the inverse formula at arbitrary integer indices gives the periodic extension of a finite sequence, repeating the recorded block every samples. This is a property of that representation, rather than evidence that the physical signal repeats beyond the recording. Laurent Demanet's MIT notes place the discrete Fourier transform alongside the continuous Fourier transform and Fourier series to explain the role of sampling and repetition.[ref]
https://math.mit.edu/icg/resources/teaching/18.330/18.330-Mar21.pdf. Laurent Demanet, Introduction to Numerical Analysis, MIT 18.330, §§6.2–6.3, pp. 57–60, March 22, 2012
The beauty is that a change of basis exposes cancellation and structure without losing data. Direct evaluation needs sums of terms; a Fast Fourier transform computes the same discrete Fourier transform with far less work. Computational speed and the mathematical meaning of the coefficients are separate questions.
Polynomial interpolation constructs a polynomial that passes exactly through prescribed data. Given distinct interpolation nodes and values , there is exactly one interpolation polynomial of polynomial degree at most with for every . The values may be samples of a function, but no knowledge of that function between the interpolation nodes is needed to construct . The Lagrange polynomial and Newton polynomial are two representations of this same answer.[ref]
For example, the three data points give the quadratic polynomialThus polynomial interpolation supplies as an intermediate value. Whether this approximates an unknown underlying function well is a separate question about polynomial interpolation error.
Both hypotheses in the uniqueness statement matter. The Lagrange cardinal polynomials prove existence constructively. If two polynomials of polynomial degree at most fit the data, their difference has distinct roots of a polynomial, so it must be zero. Repeated interpolation nodes with conflicting values have no solution, and repeated equal values provide no additional independent condition; prescribed derivatives instead lead to Hermite interpolation. Without the polynomial degree restriction there are infinitely many solutions:where is any polynomial. By the factor theorem, this describes every polynomial fitting the same data. In the example, fits for every , but at its value is ; exact agreement at the three interpolation nodes alone says nothing about that intermediate value.
The usefulness of polynomial interpolation is that data become an explicit function whose values, derivatives, and integrals can be calculated. Differentiating or integrating the Lagrange cardinal polynomials produces differentiation weights from nodal evaluations or a quadrature rule. Exact passage through observations is the defining constraint. In polynomial regression, linear least squares instead chooses a polynomial degree and minimizes a sum of squared residuals, generally without passing through every observation. Interpolating noisy values reproduces their errors at the interpolation nodes and can amplify them between interpolation nodes; polynomial interpolation does not itself smooth measurement noise. A linear least squares problem with distinct interpolation nodes and polynomial degree at most does happen to attain zero residual at the same interpolation polynomial.
For , divide into cells of widths and midpoints . The composite midpoint quadrature rule is . Taylor's theorem around each midpoint givesThe odd linear term integrates to zero; integrating gives . Consequently, with ,Thus each cell has a cubic quadrature error, while the composite error is second order in the largest cell width. For the constant is attained, since the second-order Taylor expansion is exact. Endpoint singularities that make unbounded require a separate estimate or a smoothing change of variables.
For bounded matrices,Commutativity removes this splitting error, though first-order substeps such as Backward Euler method retain their own quadratic local errors.
For a real monic quadratic polynomial , both polynomial roots lie in the closed unit disk exactly whenBoth polynomial roots lie in the open unit disk exactly when all three inequalities are strict. For the strict case, substitute . Multiplying by givesThe strict inequalities make its coefficients positive, so both real polynomial roots are negative or its conjugate pair has negative real part. The substitution maps that half-plane to the open unit disk. The boundary cases follow by continuity; necessity also follows from the root product and .
Root location and recurrence stability are separate. The polynomial satisfies the nonstrict inequalities and has both polynomial roots in the closed unit disk, but its repeated unit-circle root permits solutions . Boundedness for every starting pair requires simplicity of unit-circle roots. That extra condition belongs to the recurrence root condition, not to the algebraic disk-location criterion.
An arithmetic operation is one scalar addition, subtraction, multiplication, or division. Counting such operations gives a basic model of an algorithm's computational cost.
A trapped surface is a closed spacelike codimension-two surface whose two future-directed orthogonal null congruences both have negative expansion.
In four-dimensional spacetime, “closed” here means compact without boundary; “spacelike” means that the induced metric tensor is positive definite. Let be the two future null vector normals and the induced metric tensor. Their null expansions areHere is an infinitesimal transverse area element and an affine parameter along the respective normal null geodesics. A future trapped surface has and everywhere: even the outward-directed light front initially loses area. Multiplying either future normal by a positive function multiplies its initial null expansion by that function, preserving the sign. A small inward-converging patch is insufficient: the entire closed surface must satisfy both strict inequalities.
The Penrose singularity theorem states that a globally hyperbolic spacetime with a noncompact Cauchy hypersurface, a closed trapped surface, and the null convergence condition is future null-geodesically incomplete. Time reversal replaces the trapped surface by an anti-trapped surface and gives past incompleteness.
In his 1965 paper Gravitational Collapse and Space-Time Singularities, Roger Penrose used trapped surfaces and global causal structure to address whether nonspherical perturbations could avert a breakdown during gravitational collapse. Quasars supplied the opening astrophysical motivation. The paper used metric signature and a stronger timelike local-energy assumption; the statement above uses the modern null convergence condition.[ref]
Gravitational Collapse and Space-Time Singularities by Roger Penrose. pp. 57–58, motivation and trapping
For this version, take a smooth connected four-dimensional spacetime with a time orientation. A Cauchy hypersurface meets every inextendible causal curve exactly once; its existence expresses global hyperbolicity. The hypersurface must be noncompact, meaning not compact; this is a global spatial condition, not an assumption about the size of the collapsing body. The null convergence condition is for every null vector . Through the Einstein field equations it follows from the null energy condition; a cosmological constant drops out of the null contraction.[ref]
The conclusion is that at least one future-inextendible null geodesic has a finite upper endpoint of its affine parameter. It neither asserts infinite mass density or divergent curvature at every endpoint, nor says that such an endpoint is visible. Locating an event horizon requires additional global information; the theorem is not a horizon-finding rule for arbitrary spacetimes. Weak cosmic censorship conjecture is an additional issue.[ref]
The 1965 Penrose singularity theorem by José M. Martín Senovilla and David Garfinkle. section 4.1, printed pp. 11–12; section 6.1, cosmic censorship
The supermassive black hole account describes the motivating observational evidence from stellar orbits at the Galactic centre. Such measurements infer a compact gravitating mass. They do not observe a trapped surface, measure a geodesic's complete future, or experimentally prove the Penrose singularity theorem.
The term antisymmetric molecular vibration requires a stated symmetry convention. For the longitudinal normal modes of three collinear atoms, exchanging the labels of the two outer displacement coordinates makes the pattern odd: the outer atoms move oppositely and the central atom remains stationary. A mechanics treatment can call this an antisymmetric displacement mode.[ref]
Newtonian Dynamics by Richard Fitzpatrick. Coupled Oscillations, Triatomic Molecule, equations 843 and 853–856 and the description of the first mode
In the usual molecular-spectroscopy naming, that same pattern is a symmetric stretch, because both bond lengths increase or decrease together. The antisymmetric stretch has outer displacements in the same direction and central displacement opposite. For equal outer masses and central mass , its displacement pattern is proportional to in the center of mass frame.[ref]
Bonds and spectra solutions by TU Delft. Exercise 1, parts 3–6: symmetric and antisymmetric stretching displacement vectors and zero total centre-of-mass displacement
Writing the actual displacement vector avoids confusing exchange parity of coordinate labels with the symmetry of bond-length changes. Both descriptions can be checked directly in a three-mass, two-spring model.
For ,For a null curve, the last term drops from the geodesic equation; the remaining acceleration is parallel to the tangent and can be removed by reparametrization.
A conformally flat metric is locally , where is a smooth conformal factor and is a flat metric tensor. Its domain is a conformally flat manifold. The conformal factor preserves null cones and unparametrized null geodesics, but can change curvature.[ref]
Lecture Notes on General Relativity by Sean M. Carroll. Chapter 3, equation 3.97 and conformal invariance of the Weyl tensor, printed p. 82
For example, has Ricci scalar in the usual general relativity curvature convention, so conformal flatness need not mean flatness.Nonlinear Schrödinger blowup analysis asks whether a solution remains in its local well-posedness class or concentrates so strongly that continuation fails in finite time. For the mass-critical focusing nonlinear Schrödinger equation in the standard theory, finite-time failure forces the gradient L2 norm to diverge, even though Mass conservation for the nonlinear Schrödinger equation keeps the total squared L2 norm constant.
Concentration and total size are different. The mass-preserving scaling leaves while . Thus a fixed amount of mass can occupy smaller spatial scales with larger gradients.
The Sharp Gagliardo-Nirenberg inequality gives coercivity below the NLS ground-state mass, while a virial identity can force finite-time failure for suitable negative-energy, finite-variance data. Near the threshold, profile decomposition modulo translations separates a concentrating profile from dispersive remainder. These arguments track the structure of a solution rather than merely the maximum of a plotted wave.
The Emden-Fowler transformation turns radial scaling into translation in a logarithmic variable. For a radial Generalized Lane-Emden equationput , and . Direct differentiation givesThe primes in the second equation are derivatives with respect to . The choice makes every term carry the same power of , leaving an autonomous ordinary differential equation.
A constant nonzero equilibrium becomes a singular power law , explaining the Singular homogeneous solution of the Lane-Emden equation. Phase-plane trajectories instead describe profiles whose behavior changes with radius. The transformation is useful because dilation of becomes a shift of , which an autonomous equation handles naturally.
An Ore localization of a noncommutative ring at a right denominator set is a ring in which each element has the form . Its canonical map sends every member of to a unit and is universal among ring homomorphisms doing so. The right Ore condition provides common denominators, and denominator reversibility makes fraction equality and multiplication well-defined.
The kernel is . Thus the map is injective when every denominator is a regular element of a ring, but it can kill elements when zero divisors are inverted. In a right Noetherian domain, localizing at all nonzero elements produces a division ring, the noncommutative counterpart of a field of fractions. A left Ore fraction construction uses denominators on the other side.
There are unlisted articles, also show them or only show them.