Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
For , put . The influence function of the mean, influence function of the sample median, and influence function of a Huber location estimator with fixed are respectivelyThe first grows without bound, the second jumps at the median, and the third clips continuously. For , and the normalized Huber tail is about . This illustrates the optimal bounded influence function for normal location without asserting that this cutoff is optimal for every contamination model.
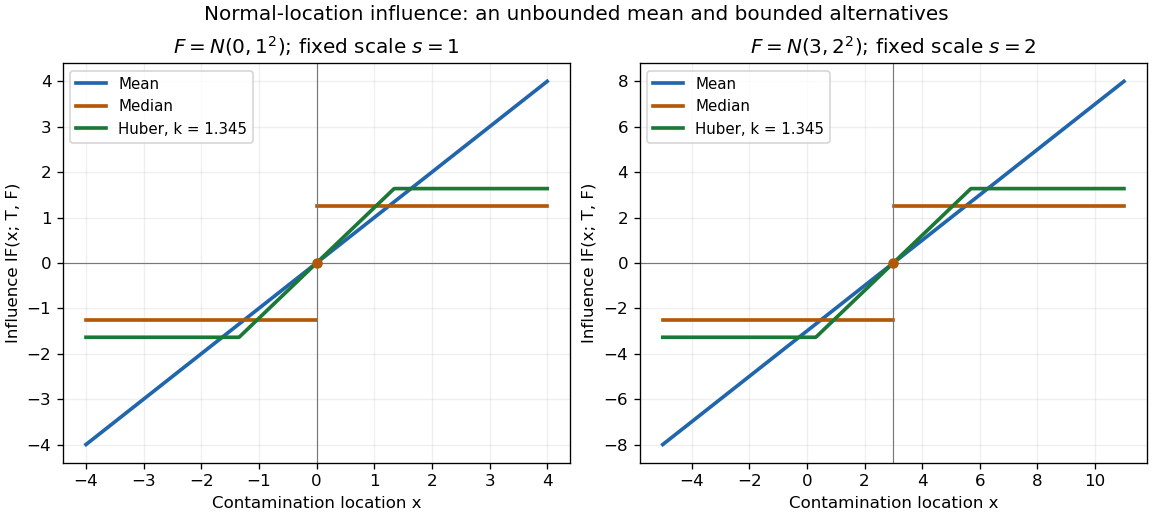
Both panels are theoretical normal distributions, with no sampled or observed data. Doubling doubles the vertical influence function scale and the horizontal clipping distance. Changing translates the curves. The isolated dot marks the actual median derivative at the center; connecting its two tails by a vertical segment would misrepresent that value. Bounded influence does not mean every small residual has less effect than on the mean: the central Huber slope is , a price paid for reducing sensitivity in the tails.
Fix a scale and cutoff . Define the population Huber location estimator by the rootHere is the Huber score. It has Lipschitz continuity, so dominated convergence justifies differentiation when puts no mass at . Then , and the nonzero derivative identifies the local population root. The implicit function theorem applies away from the contaminating score's kinks; its Lipschitz continuity also gives the first-order expansion at those kinks. Differentiating its contaminated equation yieldsThe normalization matters: the Huber score alone is not the influence function. The gross-error sensitivity is , while the rejection point of an influence function is infinite because the clipped tails stay nonzero. The original clipped estimating criterion and its derivative normalization also appear in the population analysis of M-estimators.[ref]
Robust Estimation of a Location Parameter by Peter J. Huber. Peter J. Huber, Robust Estimation of a Location Parameter, §3, p. 78: derivative normalization; §4(iii), p. 79: clipped location criterion and central-mass denominator
Scale sets what counts as a large residual. For a normal distribution with fixed , symmetry gives and , where is the standard normal distribution function. If the scale is instead a statistical functional , differentiation of the joint equation adds the scale contribution:Under a symmetric baseline and an odd Huber score, , so scale estimation drops out at first order. This cancellation needs regularity of and does not protect finite contamination changes: an inflated standard deviation enlarges the physical cutoff . A robust choice, such as a suitable Scale M-estimator, needs its own influence function and breakdown point checked. Fixing a numeric cutoff in raw units also sacrifices scale equivariance when units change.[ref]
Robust Estimation of a Location Parameter by Peter J. Huber. Peter J. Huber, Robust Estimation of a Location Parameter, §11, pp. 95-96: estimating location when normal-component scale and contamination fraction are unknown
For the statistical functional , assuming , the contaminated mean is exactlyThus the influence function of the mean is , and its gross-error sensitivity is infinite on an unbounded sample space. The linear approximation is exact here: any fixed positive contamination fraction allows an arbitrarily large change by moving far enough. No finite second moment is needed for this derivative, although a finite variance is needed for the usual central limit theorem for the sample mean.
For comparison, the influence function of the sample median iswhen the median is unique and the probability density function is positive and continuous at . The sign function records which side of receives the contaminating mass. The influence function of a quantile supplies the short derivation. With the generalized-inverse quantile convention, contamination exactly at leaves the median at , giving derivative zero there. If is very small, this bounded influence function can still be large; if , the displayed formula is unavailable.
For a Markov process with infinitesimal generator and a suitable test function , the displayed process is a local martingale. With integrability it is a true martingale and yields the corresponding expectation identity at admissible stopping times. For bounded in the semigroup generator domain, . The Markov property applies this identity conditionally over each interval, proving the martingale increments have zero conditional expectation. Localization gives the local version. For a continuous diffusion, these identities are the martingale problem for .
Semigroup commutation with its unbounded generator by  Codex 0 Created 2026-10-14 Updated 2026-10-25
For a strongly continuous semigroup, apply the bounded operator to the difference quotient defining its semigroup generator. The limit proves domain invariance and commutation on the generator domain. This is not an assertion that the unbounded generator acts on every vector.
// Target: analysis.bigb
In a turn-based game on a set of positions, Player I wins if the play visits a specified set infinitely often. Such games are determined even on infinite arenas. With meaning positions where I can force the next position into , the winning region is the greatest fixed point of . Inner ordinal ranks force the next visit; outer removal ranks give Player II only finitely many visits outside the winning region.
A covering consists of a new game tree, a length-preserving prefix map to the original tree, and maps taking strategies of each player to strategies of that same player. Every play following a projected strategy lifts to a play following the original strategy, with identical projection or a premature terminal loss for that strategy's player. Terminal outcomes inherited from the original tree are respected. The strategy maps are local in depth. These conditions transfer every winning strategy, for any payoff pulled back by the prefix map. A -covering leaves all positions, outcomes and strategy choices through depth unchanged.
Let be nonempty and bounded below. A lower bound equals exactly when every admits with . Otherwise would be a larger lower bound. Taking tolerances gives a sequence of members converging to . For a real-valued objective with finite infimum, this supplies a minimizing sequence without assuming that a global minimizer exists.
Let be the current fibre direction and . Inextensibility fixes the first column of the deformation gradient to , and incompressibility fixes the second to . Commuting mixed derivatives gives and . Thus , and curves tangent to map to straight transverse curves with constant .
For two distinct reference fibre directions , with , consider the volume-preserving deformation with right stretch tensor , with positive . The inextensible fibre constraint gives . Setting gives a quadratic with the displayed roots. There are two distinct positive branches for . The smallest possible axial stretch is , at which and . Since both image fibres have unit length, their mutual area cannot exceed one; their area is , which gives the same lower bound. Coincident or antiparallel fibres at the angle endpoints do not give the two-family orthogonality conclusion.
In a uniform-density incompressible flow inside a smooth rigid sphere rotating at angular speed , a normal mode with phase has intrinsic frequency . For , eliminating velocity from the linearized Euler equations gives the displayed pressure equation, with . Impermeability gives on the sphere. There is no condition : the rigid wall supplies variable normal pressure. These inertial waves are restored by Coriolis acceleration, and their pressure equation is hyperbolic for .
For torque-free rigid-body motion, the kinetic-energy ellipsoid fixed in the body rolls without slipping on the invariable plane perpendicular to the conserved angular momentum. Its point of contact is the angular-velocity vector.
If is the center of mass and , expanding the defining inertia tensor about gives the displayed formula. The cross terms vanish because in coordinates centred at . Contracting with a unit axis gives the parallel axis theorem, with the squared distance between the parallel axes equal to .
PASCO's PASPORT Rotary Motion Sensor Experiment Guide, Experiment 1, specifies a PS-2120A sensor, a rod carrying two equal-radius weights, a three-step drive wheel, a thread and hanging mass, a clamp-on guide wheel, a support, a balance and calipers. The thread leaves the drive wheel tangentially. The sensor records angular velocity against time; a linear regression over the accelerating interval supplies angular acceleration . The guide measures the drive radius with calipers and repeats the run with the weights removed to subtract the apparatus's own moment of inertia. Its tables are blank: it prescribes a measurement and does not report an observed numerical agreement. [ref]
With hanging mass including its hanger, effective drive radius , no thread slip and negligible guide-wheel inertia, Newton's second law gives thread tension . The axial torque is . Under negligible friction, the inference is thereforeRepeat the inference for the unloaded assembly and subtract: . Omitting the term incorrectly treats thread tension as the hanging weight. Comparing with tests the point mass approximation; finite-sized weights also have their own moments of inertia about their centres of mass. [ref]
Useful proposed checks go beyond that ideal inference. Verify the rotary encoder's angle scale by turning the shaft through a marked full revolution; check the recorded time against an independent clock and the balance against a known mass. Measure at the thread's running surface, including thread thickness; avoid overlapping wraps that change . Release without a push, inspect the angular velocity record for a straight interval, and stop before the hanger lands or the thread runs out. Repeat with several hanging masses, weight radii and rotation directions. A consistent inferred moment of inertia across drive torques supports the model; curvature, direction dependence or drift indicates a limitation rather than a new principal moment of inertia.
For approximately constant resisting torque in one rotation direction, an original calibration model isFit the left-hand quantity against across several drives: the slope estimates the axial moment of inertia and the intercept estimates . This calibration is conditional on friction remaining constant over the fitted angular speeds; a freely slowing run can expose speed dependence. Sensor differentiation noise, guide-wheel moment of inertia, thread slip, flexing connectors and uncertain weight radii limit the inference. Removing weights can also change bearing loads, so empty-apparatus subtraction does not automatically cancel friction. These are proposed controls and a model extension, not results claimed by PASCO.
A fixed-axis readout measures , not the full inertia tensor. In a proposed generalization, repeat about , , and the three diagonal directions , , , all through the same . For example,Six independent scalar readings then determine the six entries of a symmetric matrix. Each mounting needs its own apparatus correction, and different reference points require the tensor parallel-axis theorem before the readings can be combined.
An exact planar example makes the off-diagonal entries tangible. Join four equal point masses with negligible-mass rigid connectors at , , and , where is a length. Their centre of mass is . Summing , and gives , and , respectively, soThe axis is a principal axis, and illustrates the perpendicular axis theorem. The axis is not a principal axis: angular velocity gives angular momentum , which points in a different direction. A bearing can enforce fixed-axis rotation despite this difference, supplying the necessary transverse torque.
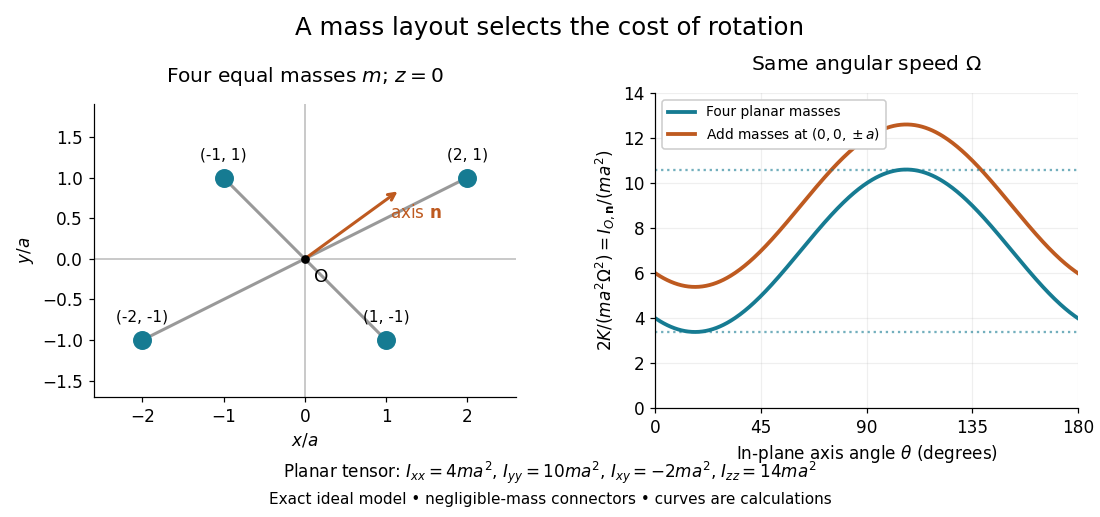
Paired point masses and direction-dependent rotational kinetic energy
. Original exact model. Four equal point masses lie in the plane with negligible-mass connectors. The curves use angular velocity and plot . Adding two more equal point masses at raises this curve by two. Markers depict ideal point masses, not finite-sized weights; no experimental data are plotted. Details.For an in-plane unit vector , the planar model hasIts extrema are the principal moments of inertia and ; the remaining principal moment of inertia is . These values follow from the two-by-two characteristic polynomial , so they can be checked without trusting a numerical eigenvalue routine. At a stipulated angular speed , with and , rotation about , or has rotational kinetic energy , or , respectively.
A truly three-dimensional example adds two more equal point masses at and . Each contributes to the inertia tensor, givingThe in-plane principal axes stay the same while their principal moments of inertia each increase by . The moment of inertia stays unchanged because the added point masses lie on that axis. This comparison changes the total mass from to ; it holds the original four point masses fixed rather than redistributing a fixed total mass.
For two point masses, a perfectly inelastic collision is an inelastic collision in which they stick and share one outgoing velocity. In the absence of appreciable external impulse, momentum conservation givesThe centre of mass decomposition of kinetic energy shows exactly how much translational energy is lost:At fixed total momentum, the common outgoing velocity minimizes translational kinetic energy. Thus sticking removes all relative translational motion for these two point masses; the energy can become deformation, heat or other internal motion.
Extended rigid bodies may remain joined while the combined object rotates. Their different material points then need not share one velocity, and angular momentum and rotational kinetic energy must also be included. Zero normal coefficient of restitution alone likewise does not assert sticking in every tangential direction.
An index-two subgroup is normal. Conjugation by an outside element gives an involution on its irreducible characters. If , the squared norm of induction is one, so induction is irreducible of twice the degree and restriction is . If , the squared norm is two, so induction has exactly two distinct constituents, each once. Each restricts to a representation containing , and their total degree is twice that of , forcing both degrees to equal that of . This proves the fixed-orbit versus two-element-orbit classification without assuming extension of in advance.
Extend a class function on by zero outside . For coset representatives of , . Each summand has squared normalized -norm . Pointwise Cauchy-Schwarz inequality and summation give . If is an irreducible character, its norm is one, and the sum of squared induction multiplicities is at most the subgroup index.
A monomial character is a character induced from a linear character of a subgroup. When discussing monomial finite groups, this property is required for every irreducible character.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact