Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Binary entropy
An observation can increase entropy 2026-10-14
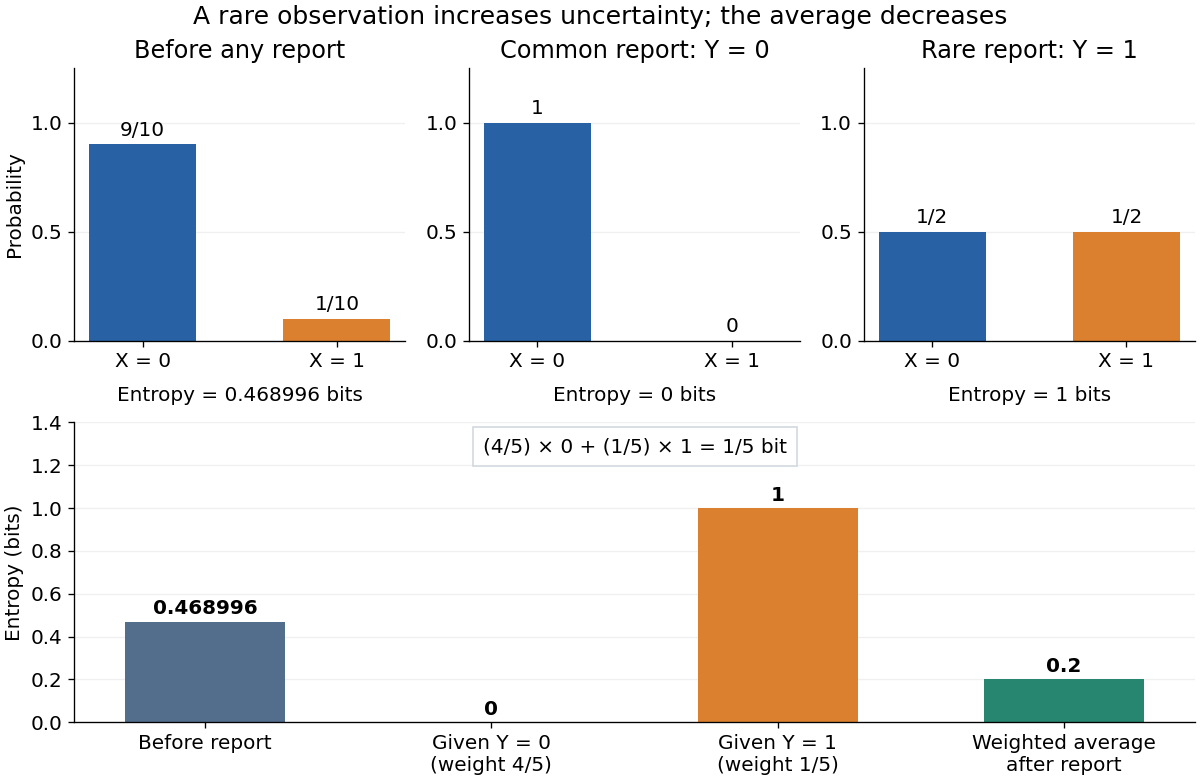
Consider a binary state and a report with the following joint probability mass function:Before the report, is strongly favored: its information entropy is bits, where is binary entropy. A report makes the two states equally likely, so bit, strictly larger than before. This report occurs with probability . The more common report determines , giving . Therefore the averaged conditional entropy isThe resulting mutual information is bits. The rare report increases uncertainty about the state; that increase does not make the report useless. Together the reports remove uncertainty on average. These are stipulated probabilities in an exact model, not measured frequencies.
Bernoulli typical-set example 2026-10-14
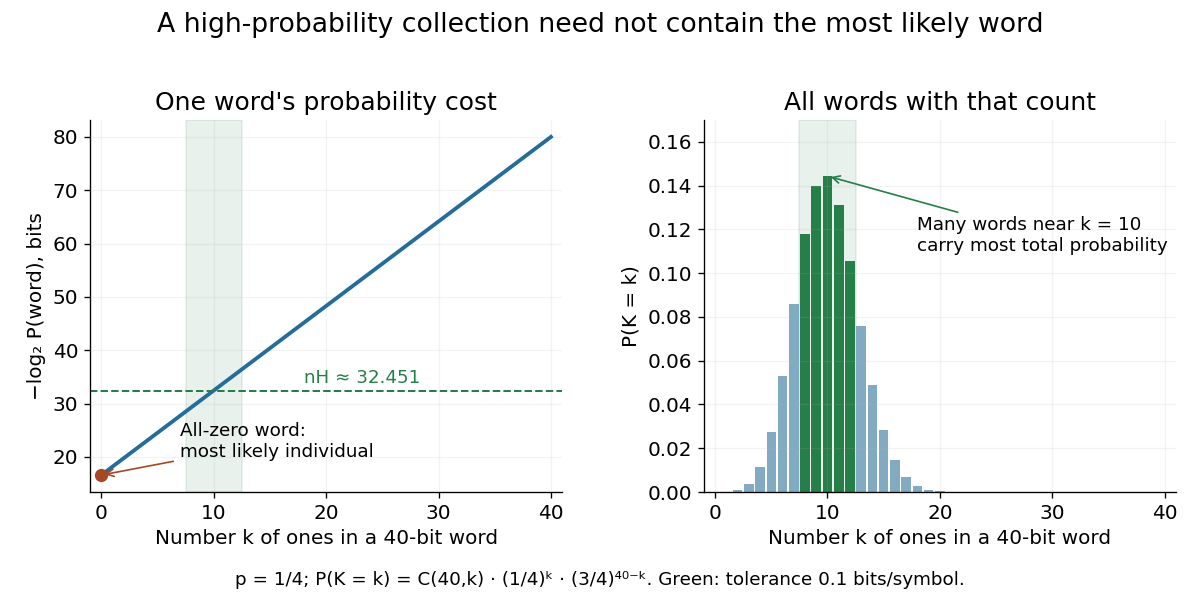
Take an IID random variable source of bits with . Its binary entropy isA word of length containing ones has probability . Its information content per symbol isThus weakly typical sequences for this biased source have near . With tolerance bits per symbol, the exact condition isFor , this includes exactly . There are words with each count: a type class with that many possible orderings. Summing the counts and their probability masses givesThese are fewer than one percent of the possible words, yet they carry nearly 64 percent of the probability. The most likely individual word is all zeros, with probability ; it is outside this typical set. No contradiction is involved: the type classes near ten ones each contain many more individual words.
The most likely individual word differs from the counts carrying most probability
. The left plot gives the information content of one word with each number of ones. The right includes the binomial coefficient counting every such word, giving the exact binomial distribution of the count. Both use , ; the green band marks the typical set with tolerance bits per symbol. Details. Binary cross-entropy 2026-10-14
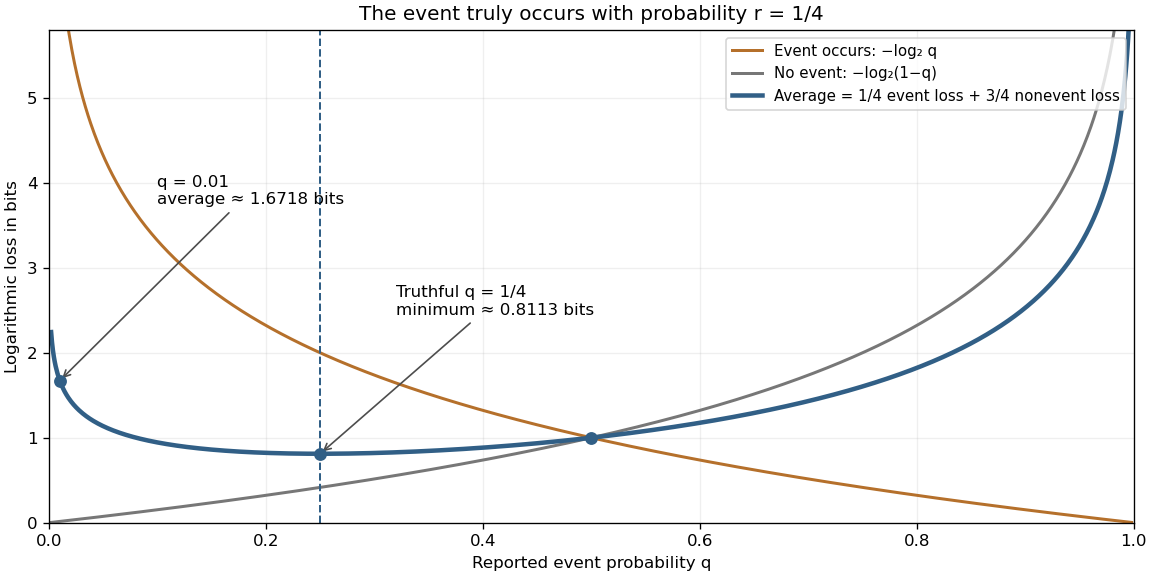
Let follow a Bernoulli distribution with true event probability , and let the model report event probability . The binary cross-entropy is its expected logarithmic loss:For , it is minimized at , where the value is binary entropy . An individual outcome has loss when and when ; the binary cross-entropy averages those two cases using the true probabilities.
For , truthful reporting gives bits. Reporting gives one bit. Reporting givesBoth and select zero if one predicts only the more likely binary outcome. Their predicted probabilities are very different, however, and cross-entropy reveals the cost of underestimating the event that occurs a quarter of the time. Endpoint losses are computed using the realized outcome rather than multiplying zero by an undefined logarithm.
The expected logarithmic loss is minimized by reporting the true event probability
. The true Bernoulli distribution has parameter . The blue curve averages the orange event loss and gray nonevent loss with weights and . Its minimum is at , while both endpoint limits diverge because both outcomes have positive probability. These are calculated expectations, rather than measurements. Details. Binary entropy product inequality Created 2026-09-24 Updated 2026-09-24
Binary rate-distortion function 2026-10-14
For a stationary source of independent and identically distributed fair bits, with Hamming distortion and binary reconstruction alphabet,The binary entropy convention is . Once , always reconstructing zero meets the distortion constraint without sending any bits. The formula must not be extended to : a looser constraint cannot increase the required rate.[ref]
Chapter 25: Evaluating R(D). Lossy Source-Channel Separation. §25.1.1, Bernoulli Source, printed p. 255
The short argument identifies both sides of the optimum. For any feasible binary reconstruction, put , using exclusive or. Knowing makes and determine one another, so the conditional entropy obeyswhen . The last step uses the increase of binary entropy on that interval. Hence . Conversely, choose with an independent Bernoulli random variable of parameter . This binary symmetric channel has expected distortion and mutual information , attaining the bound.
Binary symmetric channel capacity Created 2026-09-24 Updated 2026-10-14
A binary symmetric channel independently flips each transmitted bit with crossover probability . Its channel capacity isin bits per use, where is binary entropy and the endpoint convention is . Knowing the input leaves just the uncertainty of the flip, so for every input probability distribution. Since the output is a bit, , and thus . A fair input produces a fair output and reaches the bound. This is the two-symbol case of weakly symmetric channel capacity; Eytan Modiano, MIT 16.36, Channel Capacity and Coding, slides 4–5 gives this calculation.
For crossover probabilities , the resulting channel capacities are approximately , , and bits per use. At , the communication channel is noiseless; at , the output is independent of the input and the capacity is zero. At , every bit is inverted, a known reversible rule, and capacity is one again. More generally , because inverting every received bit exchanges the two crossover probabilities. The existing mutual information figure shows this full symmetric curve.
An uncoded transmission illustrates why the raw bit-error probability is not itself channel capacity. At , transmitting 100 uncoded bits succeeds on all of them with probability . The probability of at least one error is therefore approximately . A suitable block code changes which received words count as recoverable evidence of a message; simply repeating uncoded transmission at rate one does not obtain the reliability promised at rates below .
Bit-position information in a binary channel Created 2026-10-25 Updated 2026-10-31
Suppose a fair input bit is independent of a publicly known channel-position label . At position , let the channel be a binary symmetric channel with error probability . Forgetting gives a binary symmetric channel with error . ThereforeThe chain rule for mutual information and show that their difference is the nonnegative conditional mutual information . Equivalently, the inequality follows from concavity of binary entropy. For with equal position weights, the known-position value is bits and the pooled value is bits. These quantities answer different statistical questions.
For two-qubit pure states with smaller squared Schmidt coefficients , optimal stochastic conversion of a two-qubit pure state succeeds independently with probability . The asymptotic pure-state entanglement conversion rate of collective LOCC is instead , where is binary entropy. The difference is strict: differentiating gives . Hence . Independent filtering loses entanglement in its product-state failure branches, whereas collective concentration and dilution preserve entanglement asymptotically.
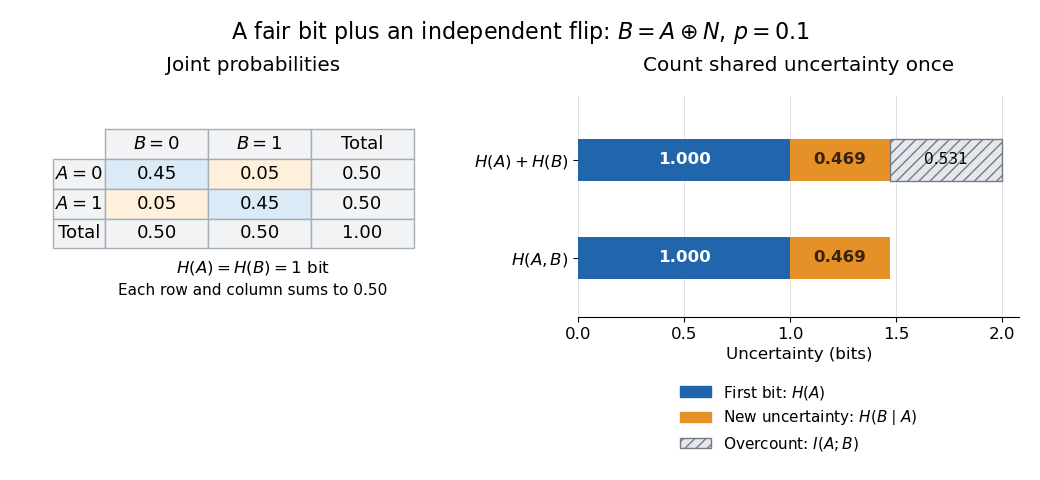
Correlated binary variables 2026-10-18
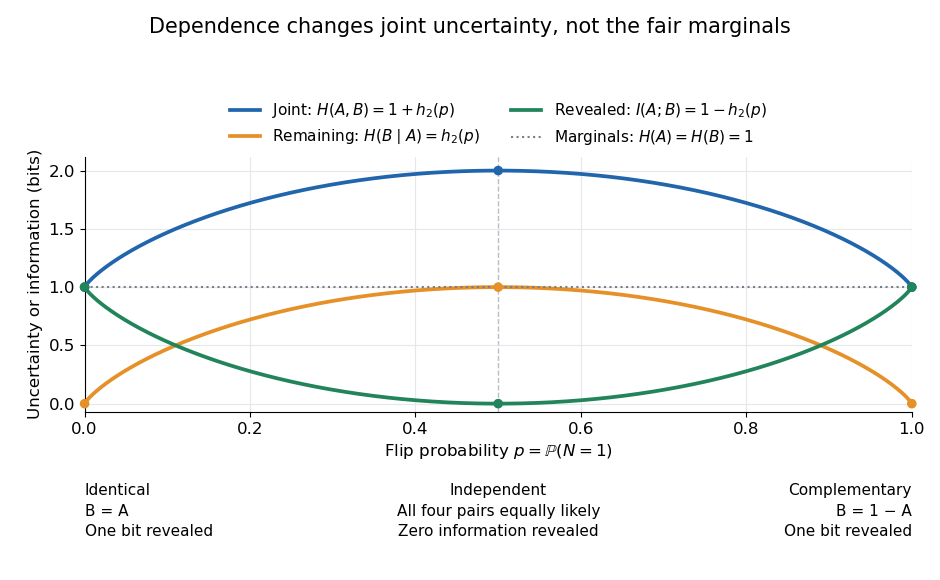
Data processing inequality 2026-10-14
For finite discrete random variables, suppose is a Markov chain: the final channel uses only , so and have conditional independence given . In terms of the joint probability mass function,and hence . Then the two data processing inequalities areAll mutual informations here use base-two logarithms. Thus deterministic or randomized processing cannot increase the information shared with an unprocessed variable.[ref]
https://web.stanford.edu/class/cs229t/scribe_notes/12_05_final.pdf. Stanford CS229T/STATS231, Theorem 2.1 and its chain-rule proof
For a concrete cascade, take a fair bit and Bernoulli random variables with probabilities , of being one. Assume are jointly independent random variables, and pass through two binary symmetric channels:The second noise is independent of both and , so this is a Markov chain. Both and are fair bits. The net exclusive or error is one exactly when one noise flips the bit and the other does not:Using the binary entropy , the three mutual informations are fully determined:All numbers are in bits. The two losses are and . Thus the cascade retains less information about the original source than either individual channel shares between its own input and output.
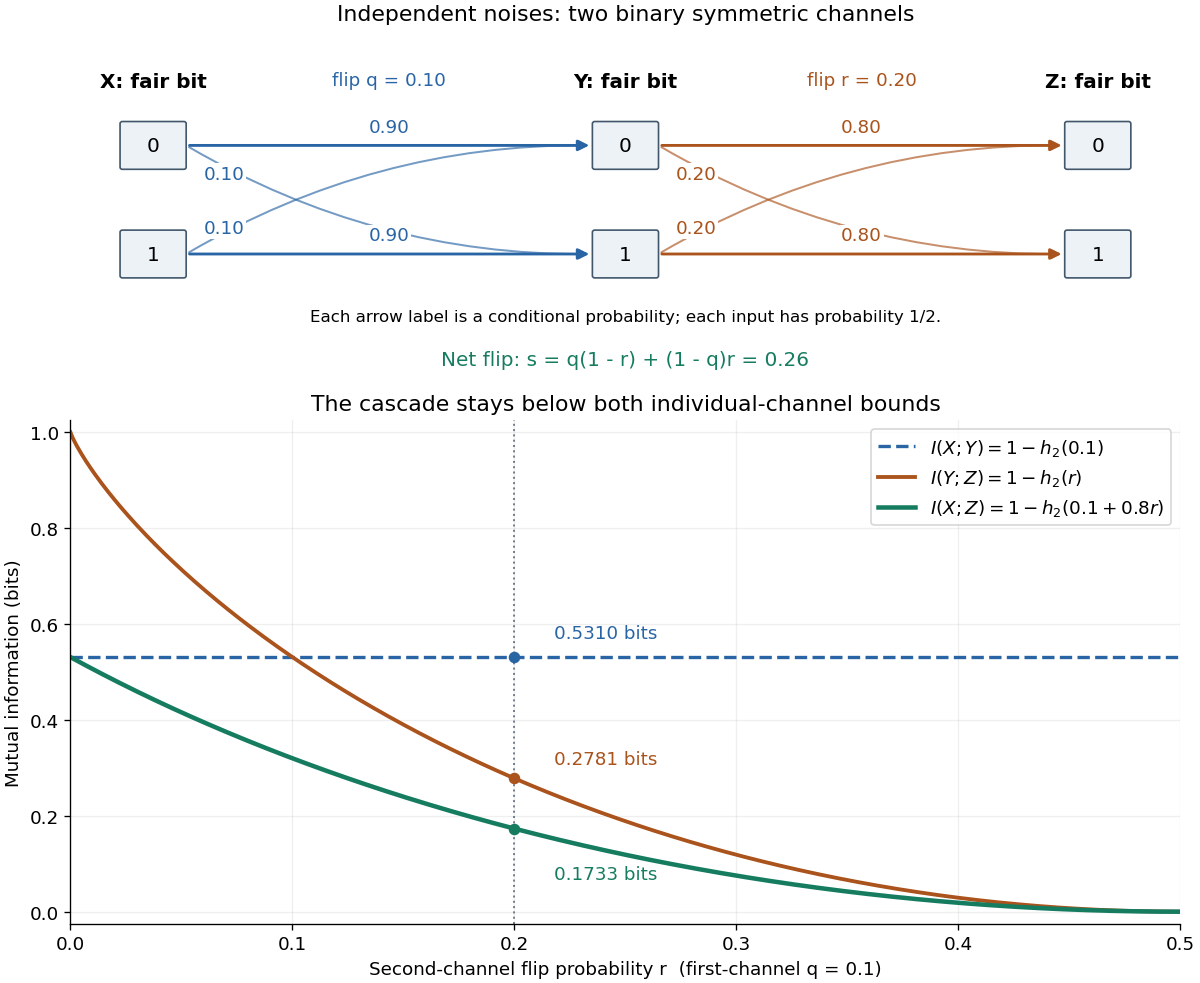
With fixed and , the effective error is . At , and ; at , is independent of the previous variables and . The diagram plots these endpoints and the computed example.
The data processing inequality is useful for testing what a proposed decoder or data summary could possibly reveal: if its only input is , even randomized processing cannot provide more mutual information about than already contains. The Markov chain hypothesis matters. In the exclusive or example from conditional mutual information, allowing a processor to use both and reveals exactly; that processor has additional input, so the conclusion for processing alone does not apply.
The chain rule for mutual information proves both inequalities and identifies their exact gaps. First expand the information about in the two observation orders:Therefore . Next use as the variable being learned:Symmetry of mutual information gives . Both signs follow from the nonnegativity of conditional mutual information; the first gap also gives equality in data processing inequality.
Entropy bound for a binary mixture Created 2026-09-24 Updated 2026-11-05
The entropy of a binary mixture also satisfieswhere is binary entropy. This follows by applying the operator monotonicity of logarithm to and its counterpart for .
Entropy bound for a union-closed family Created 2026-09-24 Updated 2026-11-05
Let be a finite union-closed family whose union is nonempty. Some ground element belongs to at least a proportionof its members. Requiring a nonempty union excludes both the empty set family and , for which no element can be chosen.
Here is the entropy mechanism. Choose independent uniform random members of . Then and , because the union still belongs to . If every element had probability at most of belonging to , Will Sawin's binary entropy estimate would givea contradiction when . A singleton set family with nonempty union satisfies the conclusion directly.[ref]
An improved lower bound for the union-closed sets conjecture by Will Sawin. Theorems1–2 and proof of Theorem1
Entropy bound with one prescribed probability Created 2026-10-06 Updated 2026-10-14
If one probability in a -point distribution equals , normalize the remaining probabilities to . Then . Equality for means that the remaining probabilities are equal. This combines the binary entropy of the distinguished event with the largest residual Shannon entropy.
Entropy function for a q-ary alphabet 2026-10-14
This is the entropy in base of the distribution with one symbol of probability and each of the other symbols of probability . It increases on from zero to one, and governs the exponential volume of a Hamming ball. For it is the binary entropy function.
// Target: algebra.bigb
Entropy lower bound from the largest atom 2026-10-31
For a finite probability distribution with largest atom , its base-two Shannon entropy satisfies . If , coarsen the distribution to the indicator of a largest atom: Shannon entropy cannot increase under a deterministic function, so . The concavity of binary entropy places it above the chord from to , giving . If , every nonzero probability has , so . The function vanishes at and has negative derivative on , proving the same bound. Equality in the combined bound occurs for a point mass or a distribution uniform on two points.
Entropy of a binary diagonal qubit mixture Created 2026-10-07 Updated 2026-11-05
A mixture of two orthogonal pure qubit states has Von Neumann entropy equal to the binary entropy of its weights. Its entropy difference from the first pure state is exactly and its trace distance from that state is . The elementary bound gives ; entropy also never exceeds one bit. For small , the leading term is .
Entropy rate and coding length 2026-10-14
Consider a binary Markov source with fair initial bit and flip probability . Its exact -symbol information entropy is . At ,This includes the uncertainty of the initial bit; the entropy rate itself is bits per symbol. The finite-block difference is .
For any finite block distribution, the entropy lower bound for prefix codes gives expected codeword length , while Shannon coding achieves . These bounds apply to each block as one source symbol, without requiring consecutive blocks to be independent. Here Huffman coding on all possible 16-symbol words gives the independently calculated value bits per block, or bits per symbol. The noninteger value is an expected value; each actual codeword has an integer length. As the block length grows, the prefix code bounds squeeze towards the entropy rate when an optimal code is used.
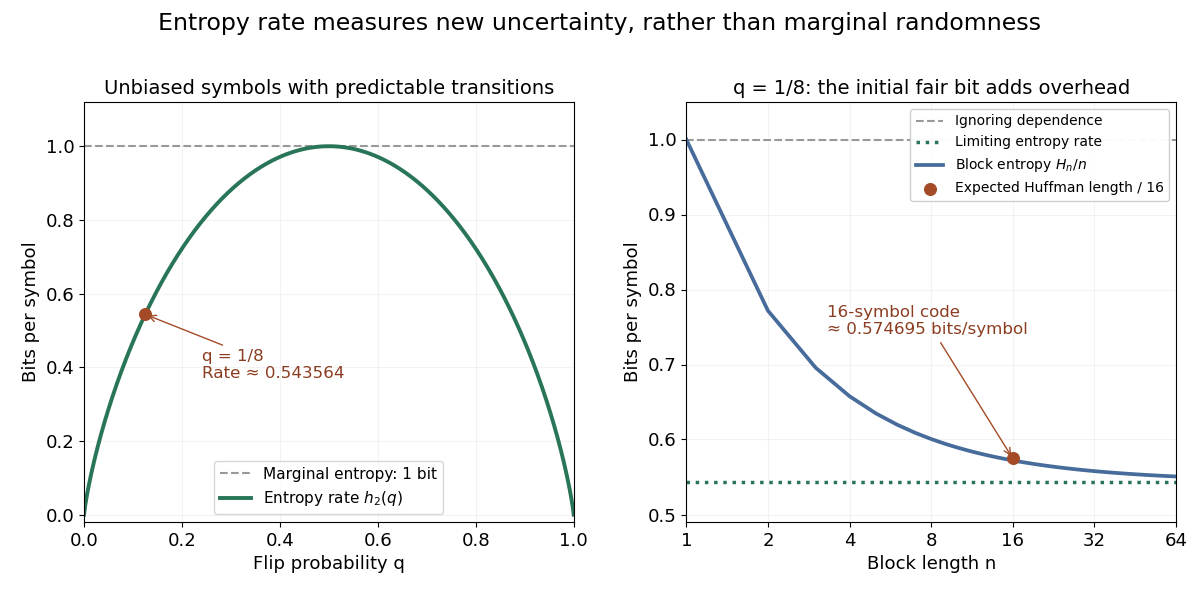
An entropy rate below one does not allow every word to fit into a shorter fixed binary word with zero error. For , all binary words are possible, so an injective fixed-length code needs at least bits. Compression instead exploits variable codeword lengths, or the vanishing-error convention in reliable source encoding at a rate. These are different guarantees.
Exact dilution obstruction from Schmidt rank Created 2026-10-14 Updated 2026-11-05
Let three parties share the normalized quantum stateFor copies, group each party's qubits together. Across any nontrivial division of these three parties, the Schmidt decomposition has one nonzero coefficient for every binary string of length , so its Schmidt rank is . Similarly, copies of the standard GHZ state have Schmidt rank across the same division.
Every recorded LOCC branch acts by a product of local Kraus operators. Schmidt-rank contraction under product operators therefore rules out an exact successful conversion when , even if success need only have nonzero probability. This is a rank obstruction for the full target, not merely a bound on its entanglement entropy.
Approximation changes the question. In the expansion of , squared coefficients have the binary-product distribution with parameter . A quantum typical subspace retains weight tending to one while using only strings, where is binary entropy. The normalized truncation approaches the full target in quantum fidelity, although its Schmidt rank can be far smaller than . Consequently, the exact finite-copy rank argument does not forbid an asymptotic entanglement dilution protocol with vanishing approximation error.
Fano's inequality Created 2026-09-29 Updated 2026-10-14
Fano's inequality turns remaining uncertainty into a constraint on decision errors. If an observation leaves many plausible answers, a decoder cannot usually recover the answer reliably. Its elegant idea is to separate two uncertainties: whether the guess was wrong, and which alternative was correct when it was wrong.
Let be discrete random variables, with taking values in a finite alphabet of cardinality . Choose any deterministic decoder whose output lies in , and define its average error probability . With base-two logarithms, Fano's inequality statesHere is conditional entropy and is binary entropy, with at the endpoints. Both sides are measured in bits; using natural logarithms throughout gives the same inequality in nats. No uniform source, independence of , or optimality of the decoder is assumed. Requiring its output to belong to the same alphabet is what leaves at most alternatives after an error.[ref]
For an exact toy example, give the discrete uniform distribution on . A channel reports with probability and reports each of the other three symbols with probability , where . Use the decoder . The output is uniform, and the conditional probabilities after any report areThus and direct calculation of the conditional entropy givesThis is equality in Fano's inequality for every . At , each report leaves probabilities , up to their order, and bits. The two contributions are bits for the error flag and bits for identifying the correct alternative after an error. These are theoretical probabilities, not measured data.
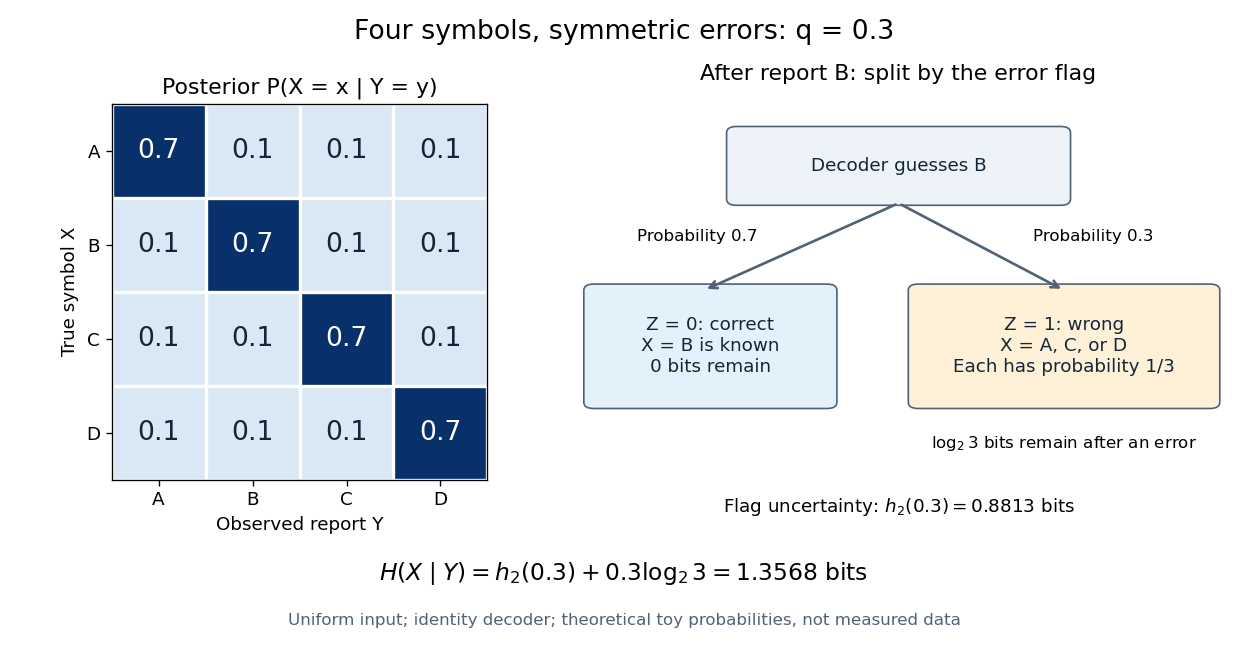


The identity decoder in this example minimizes error only for : its guessed symbol has the largest posterior probability exactly when . At , are independent random variables and all four guesses tie. For , guessing any one of the three other symbols has error probability . Equality in Fano's inequality therefore does not certify an optimal decoder.
For usefulness, combine with to obtain the simpler consequenceFor a uniform , , so this becomes . This connects mutual information to unavoidable decision error in channel coding or classification in statistical learning; it can rule out reliable recovery regardless of the chosen decoder.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_notes.pdf. Weissman, Ochoa and Tatwawadi, EE376A course notes, Sections 5.7–5.8
The sharper right-hand side increases from zero to on , then decreases: in the interior, . When interpreting the inequality by inverting a curve, use its increasing branch to obtain a lower error threshold. A decoder that chooses a largest posterior probability, as in maximum a posteriori decoding, always has , since the largest of conditional probabilities is at least . Arbitrary decoders can have larger error. In particular, low conditional entropy does not force every decoder to work well: with a fair binary and , the rule has even though . Fano's inequality supplies a constraint, not an exact error prediction for each rule.
Fano's inequality via an error indicator Created 2026-10-06 Updated 2026-10-14
Under the hypotheses of Fano's inequality, let , , and let be the indicator random variable of an error. Its probability of being one is . The in the displayed bound denotes binary entropy in bits. Since is a deterministic function of , . Applying the chain rule for conditional entropy in both orders gives the exact decompositionThe first term is bounded by , because conditioning reduces entropy. For the second term, fix a report : if , then is known; if , then lies among at most other symbols. Maximum entropy on a finite alphabet bounds the latter uncertainty by . Averaging over the reports and the error flag givesThis proves Fano's inequality. Events of zero probability contribute zero to this average, so the proof also covers without assigning a conditional distribution to an impossible event.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_notes.pdf. Weissman, Ochoa and Tatwawadi, EE376A course notes, Section 5.7, proof of Theorem 46
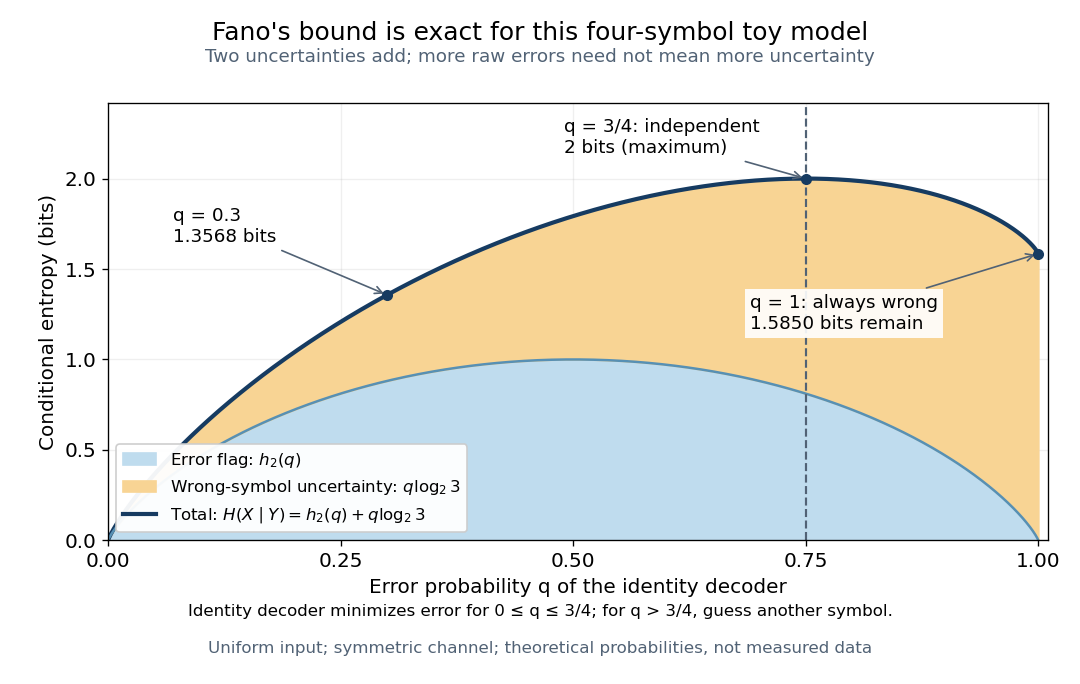
The four-symbol entropy budget peaks at chance-level error and separates the error flag from the three alternatives
. Details. 
The decomposition also explains equality. The first bound is exact when the indicator random variable and are independent random variables: knowing the report does not change the error probability. The second is exact when, for every report with positive error probability, the wrong-symbol conditional distribution is uniform on all alternatives. Both conditions hold in the four-symbol toy channel of Fano's inequality. At , the second condition is vacuous; at , the flag is constant but three alternatives remain, giving . For , there is just one alternative after an error, so the second term vanishes: all remaining uncertainty is whether the single alternative must replace the guess.