Measure theory studies measures, which assign sizes to measurable sets, and the Lebesgue integral, which accumulates values weighted by those sizes. The same framework describes Lebesgue measure on the real numbers, counting measure on discrete collections, and probability measures on possible outcomes. The choice of measure determines what counts as large; the choice of sigma-algebra determines what can be measured.
A striking example separates size from proximity: the rational numbers in form a dense set with Lebesgue measure zero, although the whole interval has Lebesgue measure one. This distinction makes almost everywhere statements useful: exceptional null sets can be ignored in a Lebesgue integral even when they meet every open subinterval. The monotone convergence theorem and dominated convergence theorem then give precise conditions for passing a limit through an integral.
A historical starting point is Lebesgue's 1902 thesis, [ref]
https://www.ime.usp.br/~glaucio/mat5798/textos/aula1.pdf#page=2. Intégrale, Longueur, Aire (original title page reproduced in USP lecture notes)
. Its title connects integration with the geometric task of assigning sizes.A sequence of real measurable functions converges in measure to when the displayed condition holds for every positive threshold. It controls the measure of the exceptional set at each index, rather than requiring eventual closeness on each sample path. On a probability space it is exactly convergence in probability. On a finite measure space, almost-everywhere convergence implies convergence in measure by continuity of measure on the decreasing tail events. The converse need not hold for the full sequence, but convergence in measure always admits an almost-everywhere convergent subsequence.
Modulo equality almost everywhere, the displayed metric induces convergence in measure and is complete. A sequence Cauchy in measure has a strictly increasing subsequence with . Subadditivity makes the limsup of these exceptional sets null, so the subsequence has summable pointwise successive differences almost everywhere. It therefore has a finite measurable limit. Almost-everywhere convergence implies convergence in measure for finite measure, and the triangle inequality plus the original Cauchy property extends convergence to the full sequence.
For the metric equivalence, for , while . The same estimates compare the two Cauchy properties. Define the subsequence limit as zero where no finite limit exists; that exceptional set is measurable by the countable Cauchy criterion, so completeness of the underlying measure is unnecessary.
A subset of a measurable space is non-measurable when . On the real line, unless another sigma-algebra is specified, this commonly means that is not a Lebesgue measurable set. By completeness of Lebesgue measure, such a set cannot be contained in a Lebesgue null set.
For an example, use the axiom of choice to select one representative from each equivalence class of under if , and call the resulting set . The translates , for , are pairwise disjoint, their union contains , and their union is contained in . If were a Lebesgue measurable set, translation invariance and countable additivity would make that union have measure zero when and infinite measure when . Both conclusions contradict these inclusions. Thus is non-measurable.
A finite collection of Euclidean open balls has a disjoint subcollection whose concentric triples cover the original union. Greedily retain a largest remaining ball and discard all intersecting ones. Each discarded ball has radius no greater than the retained one and lies in its triple. Lebesgue measure consequently bounds the original union by times the sum of the retained volumes. This covering lemma is distinct from inverse-closedness results for the Wiener algebra.
Every open set of finite Lebesgue measure in Euclidean space is covered, up to a null set, by countably many pairwise disjoint open balls contained in it. At each stage cover a compact subset of the open remainder, choose a packing with the Wiener covering lemma, and remove its closed balls. A fixed positive fraction of the remaining measure is removed each time, while sphere boundaries are null.
Geometric measure theory uses measures and analysis to study geometric objects that need not be smooth. Its measuring rules can distinguish a curve from its surrounding plane or capture the fine structure of a fractal. Hausdorff measure supplies size adapted to an exponent, while Hausdorff dimension identifies the exponent at which that size changes character.
The Cantor set is an elementary starting point: it has zero Lebesgue measure but positive Hausdorff dimension. In Hausdorff dimension of the Cantor set, explicit small covers give an upper bound and a distributed probability measure supplies the matching lower bound. This combination of geometric coverings and analytic control is useful even before more advanced tools for irregular surfaces are introduced.
For a scalar smooth map , integration can be decomposed into its level surfaces with the gradient weight displayed in the title. Near a regular level, using as the normal coordinate gives the volume element , which explains the formula by integration by substitution. In particular, when the zero level is regular and the integrals are well-defined. General versions allow Lipschitz functions and maps into higher-dimensional spaces.
Hausdorff measure measures the geometric size of a set using covers by increasingly small pieces. The exponent chooses the measuring scale: is length-like, is area-like, and noninteger exponents can measure fractals. Unlike a count of occupied grid cells, the construction allows pieces of different sizes and considers every admissible cover.
For and a subset of a metric space, use the diameter-cost conventionThe first quantity is scale-restricted Hausdorff content. Shrinking removes options from the infimum, so these contents increase to a limit, possibly infinite. The resulting outer measure restricts to a measure on the Borel sets. For , counting each nonempty covering piece with cost one gives counting measure.
A different common convention multiplies these quantities by , using the Gamma function. At integer , that normalization agrees with ordinary Euclidean -dimensional volume. Here , so both conventions make agree with arc length on smooth curves in Euclidean space. Positive normalization constants never change Hausdorff dimension. A definition must specify this constant when numerical values of Hausdorff measure matter.
For a line segment of length , splitting it into equal pieces gives the cover costIt tends to zero for , stays at for , and grows for . The matching lower bound comes from the fact that any interval cover must have total length at least . The exponent one is therefore the transition between a measuring rule too coarse to see the segment and one that assigns it infinite size. For a Cantor set, the transition is instead at , as shown in Hausdorff dimension of the Cantor set.
This makes Hausdorff measure useful when ordinary Lebesgue measure sees too little: a curve in the plane has zero planar area but can have positive arc length, and the Cantor set has zero line length but positive geometric size at its own dimension. It also separates local covering estimates from global cardinality: a countable dense set has zero Hausdorff dimension, despite meeting every open region of its closure.
An original source for the construction is Felix Hausdorff's [ref]
https://link.springer.com/article/10.1007/BF01457179. Dimension und äußeres Maß, Mathematische Annalen 79, pp. 157–179
. The modern covering and Hausdorff dimension framework is developed in Bishop and Peres, Fractals in Probability and Analysis, §1.2.For , scale-restricted Hausdorff content is the infimum of over countable covers of by sets of diameter at most , using the convention in Hausdorff measure. It increases as decreases; its limit is Hausdorff measure. Unrestricted Hausdorff content imposes no diameter bound and can behave differently.
Any explicit cover supplies an upper bound on scale-restricted Hausdorff content, rather than its exact value. The level- intervals of the Cantor set, for example, giveIf this right-hand side tends to zero, then . If it grows, that alone proves no positive lower bound: a different cover might be cheaper. The mass distribution principle addresses precisely this gap by bounding the cost of every sufficiently small cover.
The Hausdorff dimension is the critical exponent at which Hausdorff measure changes from infinite to zero:with the standard endpoint convention for an empty supremum. This measures fine-scale geometric size rather than the number of coordinates used to describe the set. A line segment has Hausdorff dimension one; a square has dimension two; the middle-third Cantor set has dimension .
Why can a dimension be fractional? At a scale reduced by a factor of three, the Cantor set needs twice as many construction intervals. The balance gives , between the growth rates of finitely many points and a whole interval. Making this argument rigorous requires a cover upper bound and the mass distribution principle lower bound, as in Hausdorff dimension of the Cantor set.
At the critical exponent itself, Hausdorff measure can be zero, finite and positive, or infinite; dimension does not specify that endpoint value. For example, finite sets and countably infinite sets both have dimension zero, although their counting measures differ. Dimension is also different from a finite-resolution estimate: box-counting dimension is another asymptotic definition, and fitting a scaling slope over a handful of observed scales does not establish either dimension.
The metric matters. Multiplying every distance by a fixed positive constant multiplies by that constant to the power and preserves Hausdorff dimension. A Lipschitz map cannot increase it, because mapped cover diameters increase by at most a fixed factor. A bi-Lipschitz map therefore preserves it by applying this fact in both directions. These properties make Hausdorff dimension useful for comparing geometric models while controlling how their measurements change.
The mass distribution principle converts a diffuse measure into a lower bound on Hausdorff dimension. Let and let a Borel probability measure give a Borel set full mass. If, for some , every ball centered in satisfiesthen in the diameter-cost convention, and consequently .
The idea is to keep unit mass from being crowded into cheap covering pieces. For a piece of positive diameter meeting , choose . A ball of radius contains ; letting gives , where is the associated outer measure. Zero-diameter pieces have zero mass by the same estimate. For any sufficiently small cover,Thus every cover costs at least . This is the lower-bound counterpart to the explicit covers in scale-restricted Hausdorff content. The Cantor distribution supplies the needed mass in Hausdorff dimension of the Cantor set. [ref]
https://www.math.stonybrook.edu/~bishop/fractalbook.pdf. Bishop and Peres, §1.2: the mass distribution principle
.The middle-third Cantor set has Hausdorff dimensionIts Lebesgue measure is zero, yet . These assertions measure different aspects of size: interval length is too coarse to distinguish this set from a null set, while the critical fractional measuring rule captures its remaining structure.
At level , the construction covers by intervals of diameter . Their total -cost isFor it tends to zero, proving the upper dimension bound. At it equals one, giving . For this particular cover's cost grows, but that alone would not prove a lower bound on Hausdorff measure.
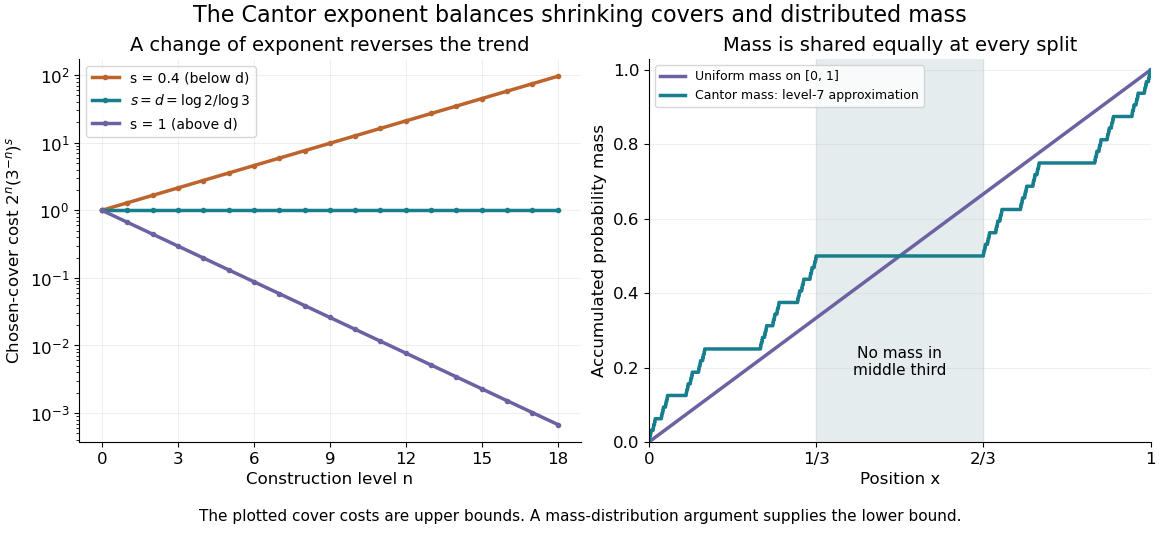
Cantor cover costs change trend at the critical exponent, and distributed mass supplies the lower bound
. Details. For the matching lower bound, use the Cantor distribution, which assigns mass to each level- Cantor cylinder. An interval of length with meets at most two level- construction intervals, since their gaps are at least . Its mass is therefore at mostEvery covering set of diameter in the line lies in an interval of length , so any small cover must have total -cost at least . This is the mass distribution principle in its interval form: , sufficient to prove the claimed dimension. The constants are convenient bounds, rather than an assertion of the exact critical Hausdorff measure. In the diagram, the right panel is a finite-stage approximation to the Cantor function, showing how probability is shared while the middle third receives none.
The reusable pattern is to obtain an upper bound by constructing covers and a lower bound by distributing mass. The same strategy underlies Cartesian powers of the Cantor set and the dimension formula for a finite similarity iterated function system satisfying the open set condition.
Suppose shrinking interval covers of have length-power sums with logarithmic growth rate , and is strictly decreasing with zero . For every those sums tend to zero exponentially. The definition of Hausdorff measure then gives , hence the displayed upper bound. A matching lower bound requires additional information and does not follow from this covering argument alone.
A connected subset of Euclidean space containing distinct points has Hausdorff dimension at least one. The Lipschitz map maps onto a set containing , since continuous images of connected spaces are connected. A Lipschitz map cannot increase Hausdorff dimension, whereas an interval has Hausdorff dimension one. Consequently any set of Hausdorff dimension less than one is totally disconnected.
A finite-dimensional vector measure has scalar measures as components and a total variation norm of a measure defined using their joint vector norm. Finite variation controls every pairing with a bounded continuous vector test. Derivatives in the bounded-variation space are examples.
A vector Radon measure has Radon measures as components. The vector form of the Riesz-Markov-Kakutani representation theorem identifies finite such measures with bounded functionals on .
Each component of a finite vector measure is absolutely continuous with respect to its variation measure. The Radon-Nikodym theorem gives a vector density . Taking the variation measure of this representation gives , hence the unit-length property. For a BV derivative this separates the magnitude of variation from its local direction.
A probability space whose measurable space is isomorphic to a Borel subset of a complete separable metric space with its Borel sigma-algebra. This supplies a countable generating algebra and permits the disintegration theorem for a probability measure. Completions can be handled modulo null sets; conditional kernels are chosen on the underlying Borel model.
A measurable space is a set equipped with a sigma-algebra of measurable subsets. A measure space additionally specifies a measure on that sigma-algebra.
A standard Borel space is a measurable space isomorphic to a Borel set of a Polish space, with its Borel sigma-algebra. This measurable regularity permits the usual constructions of random samples and random counting measures, without requiring a particular compatible topology.
A measurable set is a null set for a measure when . A property holds almost everywhere when its exceptions lie in a null set. With a complete measure, every subset of a null set is measurable and is itself a null set.
A Lebesgue null set has zero Lebesgue measure. Since Lebesgue measure is complete, every subset of one is also measurable and null. The Cantor set is an uncountable example with positive Hausdorff dimension; the rational numbers form a countable, dense example with Hausdorff dimension zero. Being null does not imply being empty or having finitely many points.
A Borel set of Lebesgue measure zero. Every Lebesgue-null set is contained in a Borel null set, by outer regularity; consequently testing all Borel null sets suffices in the definition of a Sierpiński set.
A random measure assigns a measure to each outcome so that is a random variable for every measurable . A finite-variation process gives pathwise signed random measures through Lebesgue–Stieltjes integration.
A countable measurable partition is a countable family of pairwise disjoint measurable sets whose union has full measure. Its members are its atoms; null atoms can be discarded in statements made almost everywhere.
A partition atom is a member of a measurable partition. For a finite or countable partition, each cell is an atom of a sigma-algebra generated by that partition, whose measurable sets are unions of cells. A partition atom need not be an atom of a measure: an interval cell with positive Lebesgue measure can be split into smaller positive-measure sets that lie outside the generated partition sigma-algebra.
For a countable measurable partition, its entropy is , with . This extends entropy of a finite measurable partition and is allowed to be infinite.
For a measurable partition and a sigma-algebra , the conditional information function isThe conditional expectation in this formula is positive almost everywhere on . Without conditioning, the information is .
For increasing sigma-algebras , put and . For each atom and ,Together with the bound by and the tail integral formula for moments, this yields . The inequality follows by stopping the conditional-expectation martingale the first time it falls below .
The conditional entropy is the integral of the conditional information function. Its chain rule expresses the entropy of a join of measurable partitions as unconditional entropy plus conditional entropy. Conditioning reduces entropy, also for countable partitions of finite entropy.
The join is the common refinement of two measurable partitions, with atoms given by their nonempty intersections. For a measure-preserving transformation, the block partition is .
A Boolean algebra of subsets contains the empty set and is closed under finite unions and complements. It is consequently closed under finite intersections, differences, and symmetric differences.
A semiring of sets contains the empty set, is closed under intersections, and has the property that the difference of two members is a finite disjoint union of members. Predictable rectangles form a semiring generating the predictable sigma-algebra.
A monotone class of sets is closed under increasing countable unions and decreasing countable intersections.
The monotone class theorem says that the smallest monotone class containing an algebra of sets equals the sigma-algebra generated by that algebra. It extends identities proved on a generating algebra to the full sigma-algebra.
A vector space of bounded functions containing constants and indicators of a generating pi-system, and closed under uniformly bounded monotone pointwise limits, contains all bounded functions measurable for the generated sigma-algebra. This function version extends identities established on elementary integrands to every bounded measurable integrand.
// Target: probability-and-statistics.bigb
A Lebesgue measurable function has a Lebesgue measurable set as the preimage of every open subset of . Equivalently, use every Borel set in the target: the sets whose preimages are measurable form a sigma-algebra containing all open sets. The source carries the Lebesgue sigma-algebra and the target its Borel sigma-algebra. A Borel measurable function on instead requires the preimages to be Borel in the source as well. Restricting the source to a Lebesgue measurable set uses its induced sigma-algebra.
For real random variables , if is measurable with respect to the sigma-algebra generated by a random variable , there is a Borel measurable function with . To prove the bounded case, approximate pointwise by finite-valued simple functions . Each level set is for a Borel set , so each approximation factors as with a Borel measurable function. Apply scalar clipping to with a common bounded interval and use its limit superior to obtain . For unbounded finite , apply the bounded case to the one-to-one bounded continuous function , then invert on and assign arbitrary values elsewhere. Exact measurability gives exact factorization; assumptions after adjoining null sets give an almost surely equal version.
The essential range of a real or complex measurable function consists of the values whose every neighborhood receives inputs of positive measure:It depends on the measure as well as the function. This definition concerns values arbitrarily near , not necessarily inputs at which exactly. It therefore retains meaningful limiting values while ignoring values occurring only on null sets. [ref]
https://www.mat.univie.ac.at/~gerald/ftp/book-schroe/schroe2.pdf. Teschl, Mathematical Methods in Quantum Mechanics, §2.4, equation (2.77): essential range
.For on with Lebesgue measure, the ordinary image of a function is , but the essential range is . Neither endpoint is attained, yet inputs with or have positive measure for every . Every interior value also belongs to the essential range, although its exact fiber is a singleton of zero measure. Positive measure of a fiber is sufficient, but is not necessary, for a value to belong to the essential range.
The two-sided example from essential infimum and essential supremum illustrates what disappears. It follows on , except and . Its ordinary image of a function is , whereas its essential range remains . The missing ordinary values and still have arbitrarily close neighbors with positive measure; the exceptional values and can each be isolated by a sufficiently small neighborhood whose preimage is a null set.
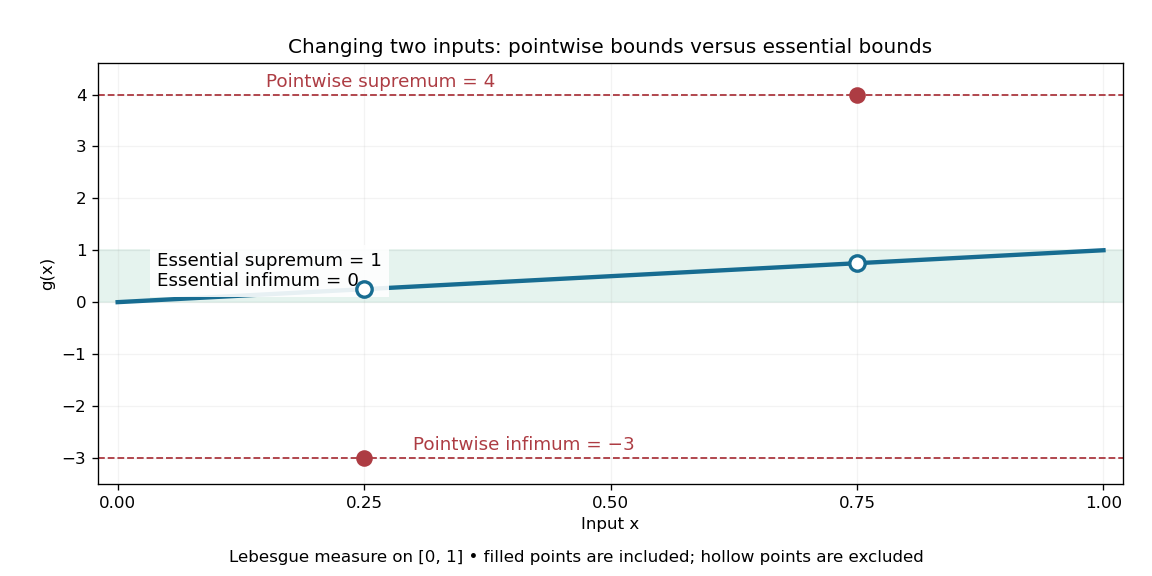
The essential range of the modified identity function remains , while its ordinary image of a function includes two isolated outliers
. For Lebesgue measure, the filled outliers and fail the criterion of positive measure in every neighborhood. The hollow values and still belong to the essential range because nearby outputs occur on intervals of positive measure. Details.For the three-point example in L-infinity norm, the values are . With weights the essential range is ; with weights it is . A small but positive probability retains ten, so an essential range does not discard a value merely because it is rare. For a real function on a space of positive total measure, the essential infimum and essential supremum are the lower and upper edges of its essential range, allowing infinite bounds. The L-infinity norm instead takes the upper edge of the essential range of .
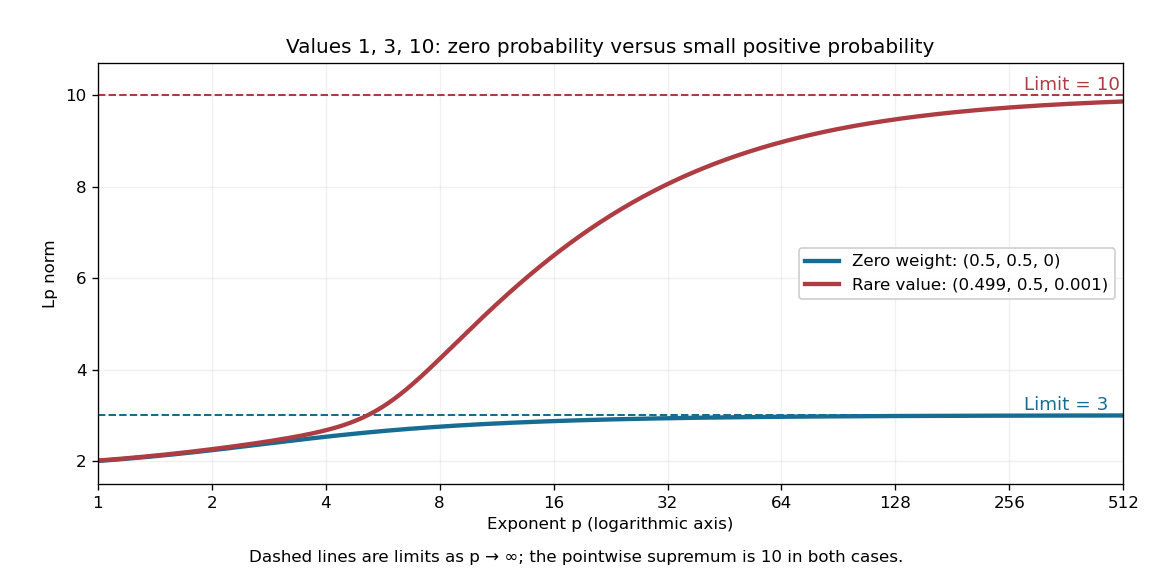
Including ten in the essential range changes the limiting Lp norm, even when its probability is only
. The blue case has essential range , while the red case has essential range . These finite positive-valued examples make their largest essential values equal to their L-infinity norms. Details.A useful operator connection is the spectrum of a real multiplication operator: on a nonzero L2 space over a sigma-finite measure, multiplication by a real measurable function has spectrum equal to its essential range, with the natural domain when is unbounded. Outside that range, has a positive lower bound almost everywhere, so multiplication by gives an inverse function that is a bounded linear operator. Near an essential value, this lower bound fails. Thus discarding null sets is precisely what makes the range match an operator acting on almost everywhere equivalence classes. [ref]
https://www.mat.univie.ac.at/~gerald/ftp/book-schroe/schroe2.pdf. Teschl, Mathematical Methods in Quantum Mechanics, §2.4, equations (2.74)–(2.77): multiplication-operator spectrum
.Measurability is the property that inverse images of measurable target sets are measurable in the source space. For a stochastic process, joint measurability in time and sample is a different condition from the separate adaptedness condition at each fixed time. The predictable sigma-algebra and progressive measurability encode particular joint measurability requirements.
For topological spaces , a Borel measurable function is a measurable function for the Borel sigma-algebras on both spaces. Equivalently, the preimage of every open set in is a Borel set in . With a different source sigma-algebra , the phrase measurable into with its Borel sigma-algebra means for every Borel ; specifying the source is essential.
If is a Lebesgue measurable function and is a Borel measurable function, then is a Lebesgue measurable function. For an open set , is a Borel set. By measurability of , is a Lebesgue measurable set, and it equals . This is composition of measurable functions with the intermediate Borel sigma-algebra stated explicitly. Merely knowing both functions are Lebesgue measurable would not ensure that the intermediate sigma-algebras match.
For a measurable set , its density at with respect to a locally finite measure iswhen this limit exists.
The spherical derivative compares the mass of shrinking centered open balls with their Lebesgue measure, when the limit exists. This is a density of one measure relative to Euclidean volume, rather than the relative density of a set within one fixed measure. A singular finite Borel measure has spherical derivative zero Lebesgue almost everywhere.
For a finite singular Borel measure, choose compact subsets of a Lebesgue-null carrier whose omitted mass is arbitrarily small. Outside any such compact subset, sufficiently small balls see only the omitted measure. The uncentered maximal weak-type inequality bounds the volume of points where the omitted measure has large density. Letting its total mass tend to zero shows that the upper spherical density is zero almost everywhere. This argument does not require the null carrier itself to be closed or separated from every point outside it.
Let and, in angular coordinates near zero, take a bounded indicator alternating between one and zero on the rings . Since , the mean over approaches the value of the outermost ring. Its even and odd subsequences approach one and zero. Thus an integrable function can fail to have a limiting centered average at a specified point, although Lebesgue differentiation theorem ensures convergence almost everywhere.
A point is a Lebesgue point of a locally Lebesgue integrable function whenThe Lebesgue differentiation theorem says that almost every point is a Lebesgue point.
For every Lebesgue measurable set , its Lebesgue density is at almost every point of and at almost every point of its complement.
A point at which a measurable set occupies an asymptotically full fraction of small balls, as expressed above with Lebesgue measure. The Lebesgue density theorem says that almost every point of a measurable set is a density point. On the real line, the same limiting conclusion holds for arbitrary shrinking intervals containing that point, since each interval lies in a centered interval of at most twice its length.
If a measurable set has positive measure, then for every there is a bounded interval such thatChoose a density-one point of a finite positive-measure portion of using the Lebesgue density theorem, and take a sufficiently small interval centred there.
A subset is a Lebesgue measurable set when it satisfies Carathéodory's criterion for Lebesgue outer measure: for every subset ,These sets form the Lebesgue sigma-algebra, the completion of the Borel sigma-algebra with respect to Lebesgue measure. Equivalently, differs from a Borel set by a subset of a Borel null set.
The sigma-algebra of all Lebesgue measurable sets, equivalently the completion of a measure of the Borel sigma-algebra under Lebesgue measure. It contains every subset of every Lebesgue null set. Applying Carathéodory's criterion to Lebesgue outer measure gives another construction of this same sigma-algebra.
Every Lebesgue measurable set of finite measure can be approximated arbitrarily closely in measure from outside by an open set and from inside by a compact set. On a bounded interval it can consequently be approximated in symmetric-difference measure by a finite union of intervals.
A property holds almost everywhere with respect to a measure when the set of points where it fails has measure zero.
If is Lebesgue integrable and is measurable on the same measure space, then is integrable exactly when is integrable. One implication follows from ; the other follows from . Thus adding a function with finite integral of its absolute value cannot remove a failure of absolute integrability. This is the vector space property of L1 space stated as a useful test for a sum of terms with different decay rates.
A real or complex measurable function is integrable for a measure when its absolute value has finite integral. For a random variable, this is integrability with respect to its probability measure, and makes its expectation finite.
The conditional expectation is the average of a random variable that can be predicted using specified information. It is itself a random variable: the average appropriate to one observed group may differ from that appropriate to another group. The sigma-algebra records which events can be distinguished with the available information.
For a real integrable random variable on a probability space and a sub-sigma-algebra , the conditional expectation is the almost surely unique integrable random variable that is measurable with respect to and satisfiesIts average therefore agrees with that of on every distinguishable event. The integral characterization handles discrete observations, continuous observations, and information that is not given by a single numerical value.[ref]
If the information tells us which member of a finite measurable partition contains the outcome, then on every member of positive probability,Here is an indicator function. Zero-probability members do not determine a unique value, which is why uniqueness is only almost surely. For square-integrable , this same conditional mean is the best predictor among -measurable random variables under mean squared error; the conditional variance describes its remaining error. A conditional mean is generally not the same as the actual observed value of .[ref]
If almost surely and for integrable , conditional expectations converge almost surely and in . Conditional Fatou lemma applied to and bounds the conditional liminf and limsup by the same limit. For convergence, the contraction estimate and dominated convergence theorem finish the proof. This also permits taking an unbounded measurable factor out of a conditional expectation by clipping it, provided the original product is integrable.
Let a probability space have countable measurable partitions of positive-measure cells, each partition refining its predecessor. An exceeding point has a first level where its cell average of exceeds . The cells at those first crossings are disjoint: intersecting cells at different levels are nested, and an earlier exceeding cell prevents any of its descendants from being a first crossing. They cover exactly the maximal superlevel set. Summing their strict average inequalities gives the displayed weak type (1,1) estimate with constant one. The same proof works on a general measure space when every relevant cell has positive finite measure.
Assume in addition that the probability space is a metric space, continuous integrable functions are dense in , and the diameters of its partition cells tend to zero at each point. For a continuous , the oscillation average tends to zero because every point in is within its diameter of . For , the upper limit of the oscillation of is bounded by the partition maximal function of plus . The first-crossing maximal inequality for refining partitions and Chebyshev's inequality bound the measure where this exceeds by . Approximation proves the displayed almost everywhere assertion. Refinement supplies the maximal estimate; shrinking diameter supplies the approximation argument. Without shrinking diameter, a constant partition generally converges only to its cell averages.
Let be a martingale with and let on a finite horizon. Its restriction to has Radon-Nikodym derivative . If is Q-integrable and , then for every ,Also is P-integrable because . The defining uniqueness of conditional expectation gives the displayed formula. In particular, if is a P-martingale and is Q-integrable, conditioning first at an intermediate time proves is a Q-martingale.
Let belong to L2 space, and suppose and almost surely, for two possibly nonnested sigma-algebras. Then almost surely. No independence or inclusion between the sigma-algebras is required.
The identities supply -measurable and -measurable versions of and . The measurable-factor rule for conditional expectation and Cauchy-Schwarz inequality giveExpanding the square shows , and hence the required almost sure equality. Equivalently, each conditional expectation is an orthogonal projection in L2 space, and the two projection identities force equality in the equality case for conditional second moments.
Equality after applying a function need not identify its original input. For instance, on four equally likely outcomes let take and set . Their squares are the same nonconstant random variable, even though and differ everywhere. Injectivity of the function would rule out this loss of information.
For nonnegative random variables , the corresponding nonnegative conditional expectations increase almost surely to , allowing the extended value . When is an integrable random variable, all conditional expectations can be taken in their ordinary finite sense.
To prove this integrable case, choose versions simultaneously ordered outside a single null set, and put . This limit is -measurable. For every , the ordinary monotone convergence theorem twice givesIn particular , and this is exactly the defining property of conditional expectation. For a general nonnegative , define its extended conditional expectation by increasing bounded truncations; the same nonnegative integral argument proves the statement.
Let be an integrable random variable, let be a finite -measurable random variable, and suppose is an integrable random variable. Then a known factor can be taken outside the conditional expectation:For a bounded , first verify the defining integral identity when is the indicator function of a measurable set in , extend by linearity to simple functions, and then use bounded approximation and the dominated convergence theorem. For nonnegative , truncating and using the conditional monotone convergence theorem proves the identity with extended nonnegative conditional expectations. In particular,For general under the stated integrability assumptions, the conditional Jensen inequality bounds by that integrable random variable. Apply the bounded-factor result to truncations of , then use the dominated convergence theorem on the products and the L1 contraction of conditional expectation. This proves the identity without assuming itself is an integrable random variable.
The product-integrability condition is essential to the ordinary finite conditional expectation statement. An unbounded factor cannot be moved through an expected value simply because its partner is an integrable random variable.[ref]
Let be the probability of first success on attempt , conditional on reaching that attempt. Then the chain rule for probabilities gives ; no assumption of independent attempts is needed when these are the specified conditional probabilities. The chance of success by attempt is . Divide the truncated first moment by that probability to obtain the displayed conditional expectation, provided its denominator is positive. This is different from counting all unsuccessful cases as though they succeeded on the last permitted attempt.
For a real integrable random variable , a conditional expectation with the same probability distribution as must equal almost surely. No second moment is needed. For any real , the nonnegative random variable has expected value zero, by conditioning and equality of the two absolute moments. Thus implies , implies , and implies , outside a null set. Using a countable family of rational separates any unequal real values and proves the claim. Equality of the probabilities of and also gives equality of their zero sets and hence equality of the two sign functions for every fixed .
For an integrable function on , average on each dyadic interval of length . The resulting step function converges to almost everywhere and in the L1 norm. If has the uniform distribution on , then , where rounds down to a dyadic endpoint. Refinement makes these conditional expectations a uniformly integrable martingale. The uniformly integrable martingale convergence theorem gives almost-sure and convergence in L1 to a limit .
Since , the generated limiting sigma-algebra contains up to null sets. For every event in any finite-stage sigma-algebra, convergence in the L1 norm gives . The pi-lambda theorem extends this equality to the limiting sigma-algebra, identifying . The uniform distribution of translates the two convergence conclusions into the assertions for . Choosing a Borel representative of and assigning arbitrary values at the endpoint one makes all random variables well defined without changing either conclusion.
If a finite group acts by measure-preserving maps on a probability space, let be its invariant sigma-algebra. For an integrable random variable , the displayed group average is -measurable. For , changing variables under each group element gives . The average therefore satisfies the defining integral identity for conditional expectation. For permutations of exchangeable coordinates, averaging a product attached to distinct indices yields the sum over all ordered distinct -tuples divided by the falling factorial .
For arrays of values in , let average a product of entries over all ordered index tuples from coordinates, and let average it over the tuples with distinct indices. Decompose the first average as , where and the repeated-index average lies in . This gives . For uniformly sampled indices, a union bound over the pairs bounds the collision probability by . This deterministic estimate is the bridge between empirical-product limits and the De Finetti theorem.
For nonnegative integrable , the finite measure restricted to a sub-sigma-algebra is absolutely continuous with respect to the restricted base measure. Its Radon-Nikodym derivative is -measurable and has the required integral identities. Positive and negative parts extend the construction to real integrable functions; real and imaginary parts extend it to complex functions. The result is unique almost everywhere.
If is a real square-integrable random variable and , then and the displayed identity follows by expansion. Thus equality of the second moments forces as an almost sure equality. This is the equality case of the conditional Jensen inequality for the strictly convex function .
Disintegrate over a factor map and take the norm using the conditional probability on each fiber. Its square integrates to the global squared norm. The uniform conditional L2 norm takes the essential supremum of these fiber norms.
For invertible probability systems linked by a factor map, invariance and uniqueness of disintegration identify the pushforward of each conditional measure with the conditional measure on the transformed fiber. The displayed norm identity follows for all integer times on a common full-measure set. It transports uniform conditional error bounds along whole orbits.
The essential supremum over the base of the conditional L2 norm. It may be infinite for a globally square-integrable function. For probability fibers, ; the uniform norm controls all fibers outside a null set rather than only their average.
For an integrable random variable , a sub-sigma-algebra , and a convex function with suitable integrability, almost surely. One proof writes as a supremum of supporting affine functions and applies monotonicity and linearity of conditional expectation to each. This proves the convex-loss form of the Rao-Blackwell theorem.
For an integrable random variable , the conditional expectation satisfies almost surely. Taking expected values gives the L1 contraction of conditional expectation. Applying it to shows that convergence in L1 is preserved by conditional expectation with respect to any fixed sigma-algebra.
For independent and identically distributed random variables that are integrable random variables, with , symmetry gives . The decreasing sigma-algebras generated by these future sums permit application of the reverse martingale convergence theorem.
The law of total expectation makes averaging in stages reliable, provided the outer stage uses the actual probabilities of the groups. For an integrable random variable and a sub-sigma-algebra ,Replacing each outcome by its group's conditional mean preserves the overall expected value. In the definition of conditional expectation, take the event to obtain this identity.[ref]
For a complete finite example, choose a group with probability and with probability . Within group , is or with equal conditional probabilities; within group , it is or with equal conditional probabilities. Thus the joint probability distribution puts probabilities on . The conditional means are two and eight. Consequently,Direct averaging of the four values gives the same . Taking the unweighted average of the two group means instead gives five, which describes a different choice of group probabilities. This is why the outer weighting matters.
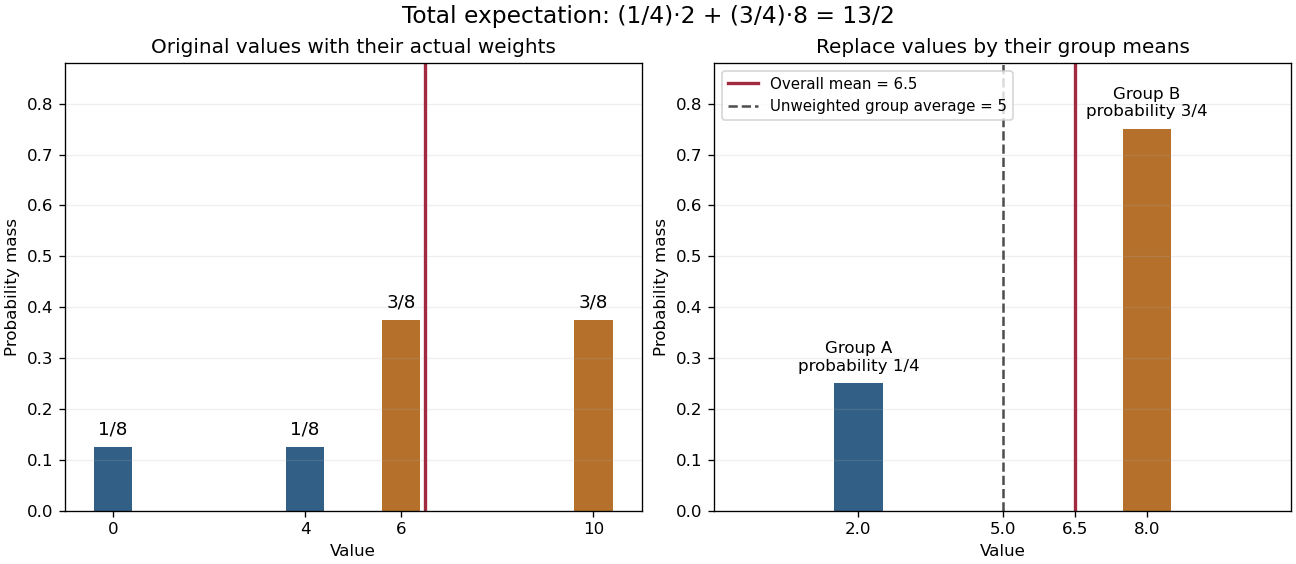
The formula is useful when conditioning on a first choice makes the remaining experiment simple. It can replace a large outcome enumeration by smaller calculations within groups. In a mixture distribution, it combines component means using mixture weights; in a random sum of independent claims, it separates the number of summands from their individual expected values under the stated independence assumptions. The same averaging step appears in the law of total variance.
A bound implies . It does not by itself imply . For , Jensen's inequality goes in the opposite direction. The missing contribution is the variance: .
For integrable random variable and nested sub-sigma-algebras , the tower property saysThe finer-information conditional mean can be averaged within each coarser group, recovering the coarser-information conditional mean. Conversely, conditioning an already -measurable conditional mean on leaves it unchanged. Both orders therefore recover when the information is nested.[ref]
For the finite example in law of total expectation, exact knowledge of gives the finer mean itself. Averaging within the groups recovers two and eight. Forgetting the group then gives . The nesting condition is essential; iterated conditional expectation over nonnested sigma-algebras describes why arbitrary successive conditioning cannot simply be replaced by conditioning on an intersection.
If sub-sigma-algebras and are independent, every event in is independent of itself and consequently has probability zero or one. Thusalmost surely for every integrable random variable .
In general,Equality does hold when either sigma-algebra contains the other or when they are independent.
For nonnegative random variables and a sigma-algebra ,almost surely. It follows from the ordinary Fatou lemma after testing both sides on every event in .
For nonnegative measurable functions,
If are random variables bounded above by an integrable function , with all relevant expectations well defined, Fatou's lemma applied to the nonnegative variables gives . In particular, bounded indicator random variables that tend almost surely to zero have probabilities tending to zero.
Let be Lebesgue measurable functions on a Lebesgue measurable set , converging almost everywhere to , with . The limit has a measurable representative: use off the exceptional null set and zero on it. The completeness of Lebesgue measure makes any alternative values on that null set measurable as well. Fatou's lemma applied to gives the displayed bound, so is finite almost everywhere and Lebesgue integrable. A uniform L1 norm bound alone does not imply convergence in L1 space; the strict inequality in Fatou lemma supplies a shrinking-spike example.
On , the functionsconverge pointwise to zero but satisfy . Hence the two sides of Fatou lemma can be zero and one.
A point is generic for an invariant measure of a continuous map on a compact metric space if the displayed convergence holds for every continuous function . Its empirical probability measures converge against continuous test functions to . The same test-function condition may be used before invariance is known: the telescoping identity for then proves that the limiting Borel probability measure must be invariant. If almost every point is generic for the same measure, continuous approximation of invariant-set indicators proves that this measure is ergodic.
For a measurable transformation , a measure is invariant if the pushforward measure equals the original measure, or equivalently for every measurable . This is the measure used in a measure-preserving system.
A Borel probability measure is invariant for a Markov kernel semigroup if every transition preserves it. For a Feller semigroup on a compact metric space, it suffices to test the displayed identity on continuous functions. Kernel Jensen inequality gives contraction on , and sup-norm strong continuity followed by density gives strong continuity there for .
For a Feller semigroup on a compact metric space, time-averaged transition laws have weakly convergent subsequences by compactness of probability measures on a compact metric space. Shifting a time interval of length by changes a bounded test-function average by at most . A weak subsequential limit is therefore an invariant probability measure for a semigroup. More generally, tightness of the time averages supplies the required compactness.
Cutting and stacking constructs measure-preserving transformations from towers of equal-measure levels. Cut a tower into equal-width subcolumns, add new spacer levels, and stack the resulting columns. Map each level to the one above by a measure-preserving identification; subsequent stages extend the partial map. When uncovered and top-level measures tend to zero, the limiting map is defined modulo null sets.
Articles were limited to the first 100 out of 390 total.
Articles by others on the same topic

Measure theory is a branch of mathematics that deals with the systematic way of assigning a numerical "size" or "measure" to subsets of a given space. It provides a foundational framework for many areas of mathematics, particularly in integration, probability theory, and functional analysis.



Main motivation: Lebesgue integral.
The Bright Side Of Mathematics 2019 playlist: www.youtube.com/watch?v=xZ69KEg7ccU&list=PLBh2i93oe2qvMVqAzsX1Kuv6-4fjazZ8j