Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Measurable function
The sigma-algebra generated by a random variable is the smallest sigma-algebra on making a measurable function into . Equivalently, it is the intersection of all sigma-algebras containing the inverse images of Borel sets .
Let . This collection is already a sigma-algebra: ,The right-hand sets are in , since the Borel sigma-algebra is closed under the indicated operations. Any sigma-algebra making measurable must contain every member of . Conversely makes measurable by definition. HenceThis equality holds exactly as a collection of sets, without completing the sigma-algebra.
For each real ,The final strict-superlevel set is measurable by part 1 and the given criterion for measurable functions. A complement relative to the measurable domain is measurable, so is measurable.
A real measurable function is one whose inverse image of every open subset of is Lebesgue measurable. Equivalently,These upper rays generate the Borel sigma-algebra, making this equivalent to requiring measurable inverse images of all Borel sets.
Let . It vanishes outside the null set , so part (e) proves is a measurable function, regardless of its values on . Since the sum of two measurable functions is measurable, is measurable. This is the completeness of Lebesgue measure under changes on null sets.
On the product of two sigma-finite measure spaces, Tonelli's theorem states that a nonnegative measurable function has measurable iterated-integral functions andwith values allowed to be infinite. Fubini's theorem states that if is measurable and , then its sections are integrable almost everywhere, both iterated integrals exist as finite integrals, and the same equality holds, also for real or complex signed functions. Tonelli applied to can first be used to verify the absolute-integrability hypothesis of Fubini.
For product measure spaces, Tonelli's theorem states that for a nonnegative measurable function the product-space integral equals either iterated integral, allowing the value . Fubini's theorem states that if a measurable function has finite integral of its absolute value, then its sections are integrable almost everywhere, both iterated integrals exist and equal the product-space integral. The absolute-integrability hypothesis is what permits this conclusion for a signed function. These statements apply to the Lebesgue product spaces used here, which are sigma-finite.
The partial sums are nonnegative measurable functions and increase pointwise to the extended-valued sum . The monotone convergence theorem and finite linearity giveA nonnegative measurable function with finite integral is finite almost everywhere; if it were infinite on a positive-measure set, its integral would be infinite. Define it arbitrarily on the null exceptional set if a real-valued representative is desired. Hence the series converges almost everywhere to an integrable function and
Past exam of the real and harmonic analysis course of the University of Oxford 2007 1 a Solution 2026-10-31
The absolute continuity of measures condition isThe Radon-Nikodym theorem says that if both positive measures are sigma-finite measures, then this condition is equivalent to the existence of a nonnegative measurable function , unique up to equality -almost everywhere, such thatOne writes , the Radon-Nikodym derivative. Under these hypotheses is finite -almost everywhere. If is finite, then . A finite signed measure absolutely continuous with respect to a sigma-finite positive measure likewise has an integrable signed Radon-Nikodym derivative.
The sigma-finiteness hypothesis on the dominating measure cannot simply be omitted. On the Borel subsets of , let be counting measure and Lebesgue measure. Absolute continuity holds because the only -null set is empty. A Radon-Nikodym derivative would satisfy at every point, contradicting . Here counting measure is not sigma-finite.
Let . Applying the same measurable function separately to independent and identically distributed random variables preserves those two properties, andIn particular, these bounded random variables are integrable random variables. The weak law of large numbers givesIf , then , whose probability tends to zero. If , then , whose probability also tends to zero. Taking a complement in the second case provesThe positive gap from is essential to this argument. Convergence in probability alone does not determine the answer at the excluded threshold .
Point process Created 2026-10-07 Updated 2026-10-14
A point process records random locations by a random measure that counts them. Examples include arrival times of a queue, positions of stars, and the finite eigenvalue configuration of a random matrix. The count in an observation window is a random variable; its expected value is supplied by the intensity measure of a point process, while its fluctuations and relationships with other windows require more information.
For a precise spatial convention, take with its Borel sigma-algebra and a probability space . A locally finite point process is a measurable function from to the space of locally finite point measures, equipped with the sigma-algebra generated by evaluations for Borel sets . Each realization has the formwhere is finite or countable and repeated locations are allowed; is a Dirac measure. Here a point measure is a counting measure with possible multiplicities, rather than the counting measure of a set of distinct locations.[ref]
Lectures on the Poisson Process by Günter Last and others. Section 2.1, Definition 2.1, printed pp. 10-11: point measures and the sigma-algebra generated by evaluations
Local finiteness means for every bounded Borel set , on a single almost sure event. In it suffices to check the countable collection of balls of integer radius centered at the origin, and this is equivalent to finiteness on every compact set. On a general measurable space there is no notion of boundedness without additional structure: state a metric or an explicit family of observation windows. Another convention on locally compact spaces requires finiteness on compact sets; this need not coincide with finiteness on all bounded sets outside . Local finiteness does not require finitely many points in all of .[ref]
Lectures on the Poisson Process by Günter Last and others. Section 2.4, Definitions 2.11 and 2.13, printed pp. 16-17: bounded-set local finiteness and the countable ball exhaustion
Poisson factorial moment measure Created 2026-10-14 Updated 2026-11-05
For a Poisson point process of intensity measure , its th Poisson factorial moment measure is . Writing its counting measure as , the identity means that for nonnegative measurable function ,The indices select distinct point occurrences. Their locations need not be different when has an atom of a measure. For a simple point process, the locations are different as well.[ref]
Lectures on the Poisson Process by Günter Last and others. Section 4.4, Corollary 4.10: Poisson factorial moment measure is the tensor power of its intensity
For example, if all intensity is concentrated at one point , with , then has Poisson distribution. There are ordered pairs of distinct occurrences there, with expected value , even though both locations equal . Counting only pairs of different locations would give zero and fail the identity.
For , separating equal-index terms from distinct-index terms gives the second-moment calculation in Campbell's theorem. Dividing the distinct-pair sum by two instead counts unordered pairs, as in the intersection point process of a Poisson line process.
Poisson thinning Created 2026-09-24 Updated 2026-10-14
Poisson thinning splits a Poisson process by independently marking each arrival as retained or rejected. Let the original Homogeneous Poisson process have rate , and let be a deterministic measurable function of time. Attach independent uniform distributions on , independent of the entire original Poisson process. At arrival time , retain the arrival if . Given all arrival times, these decisions are independent and have the specified retention probabilities. Define the two counting processes using an indicator function:The Poisson thinning theorem gives independent retained and rejected Inhomogeneous Poisson processes. Their rates are and , respectively, in the sense of the intensity function of a point process. In particular, for ,The independence is of the two whole processes: every finite collection of retained counts is independent of every finite collection of rejected counts. It is not merely zero covariance for one interval. For constant , the streams are Homogeneous Poisson processes of rates and ; the endpoints include the identically zero stream.[ref]
Lectures on the Poisson Process by Günter Last and others. Definition 5.7, Proposition 5.5, Theorem 5.8 and Corollary 5.9, printed pp. 42-44: location-dependent independent marking, intensities, and independence of the split processes
For an exact toy calculation, take per minute and retain with on and on . In the first two minutes, the retained and rejected expected values are and . In the next two minutes they are and . Over all four minutes, are independent Poisson distributions with mean each, and their sum has mean . ThusThese probabilities and expected values describe the model, not empirical measurements. In the diagram, the original nine synthetic arrivals split into five retained and four rejected arrivals; those realized counts need not equal their expected values.
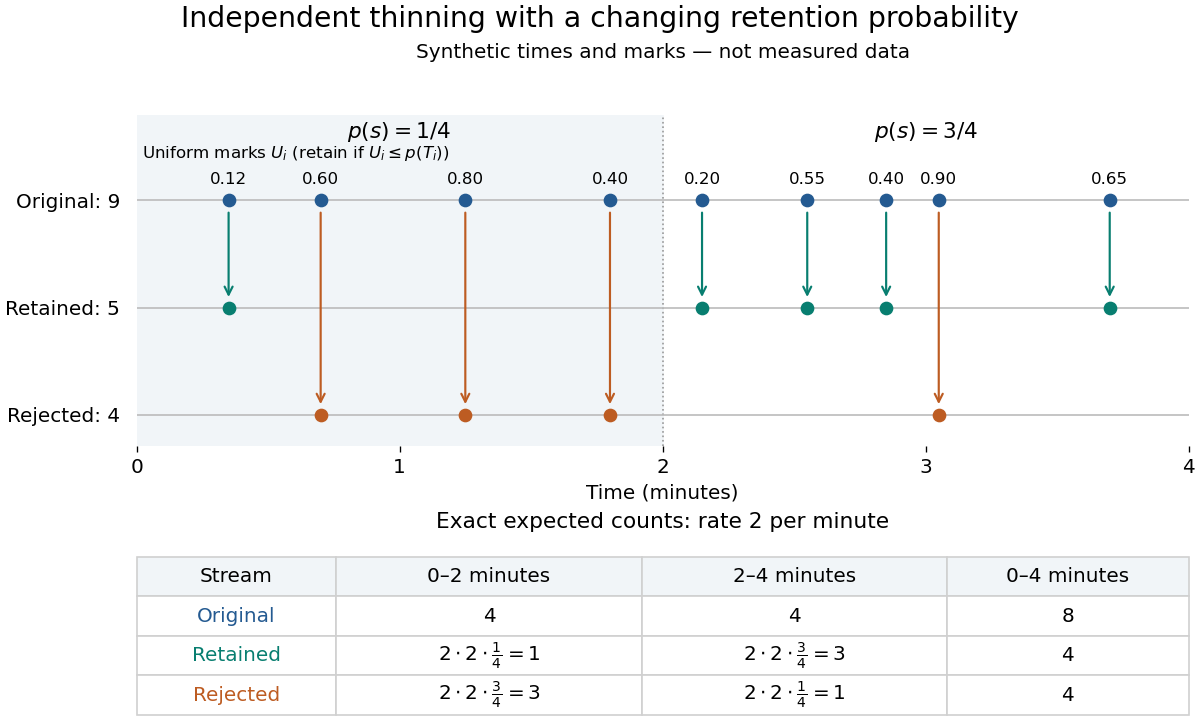
Independent marks split a synthetic Poisson arrival path, with exact expected counts for two time-dependent retention probabilities
. Details. The mechanism explains why mutually exclusive labels can yield independent counts: randomness of the original total offsets the dependence from allocating a fixed total. For constant and an interval with original mean , the conditional retained count has a binomial distribution given . The joint probability generating function isThis factorization proves the two independent Poisson distributions; disjoint original intervals give independent pairs. For varying , the Independent marking theorem for Poisson point processes gives the same conclusion with the two integrated intensities. The joint red and green Poisson count formula gives the corresponding direct calculation with probability mass functions.
Independence here is unconditional. After conditioning on , the identity gives covariance for constant . Thus the retained and rejected counts are dependent for and , even though their unconditional covariance is zero. Poisson thinning can model independent routing of arrivals, or independent detection of arrivals with a known efficiency schedule; using only a retention fraction without checking the marking mechanism can give a wrong count law.
Portmanteau theorem Created 2026-09-24 Updated 2026-11-05
The Portmanteau theorem gives equivalent formulations of weak convergence, including inequalities on open and closed sets and convergence of expectations for every bounded measurable function whose discontinuity set has zero limiting Probability.
Preimage 2026-10-14
For a function and a subset , its preimage isIt is a subset of the original domain of a function. The notation does not require an inverse function: the preimage of a singleton set can have no members, one member, or many members. In the finite example, , and . The preimage of a singleton set is also its fiber of a function.
For subsets , preimages preserve both unions and intersections:For the intersection, the same input belongs precisely when its single output belongs to both and . There is no opportunity to choose different witnesses, which is what made the image counterexample fail. The identities also hold for arbitrary families of output subsets.
In the finite example, choose and . ThenThe intersection of the two preimages is exactly the same set . Complements are preserved with respect to the appropriate source and target sets:For example, the unused output three contributes no extra input: with , both sides of the complement identity are . See Lebl, Proposition 0.3.15: preimages of unions, intersections and complements.
This makes preimages useful for transporting conditions. The solution set of is , and a zero set is a preimage of zero. Requiring two output conditions takes the intersection of their preimages. In topology, a continuous function pulls every open set back to an open set; a measurable function pulls the specified measurable sets in its codomain back to measurable sets in its domain of a function. These definitions use preimages because their set operations remain consistent even when the function is noninjective.
Prékopa–Leindler inequality Created 2026-10-06 Updated 2026-11-05
In the finite, nonzero normalization, let , let be nonnegative integrable functions on with , and let be a nonnegative measurable function. If they satisfy for all , then their Lebesgue integrals obeyThe quantile derivative identity and monotone substitution inequality prove the one-dimensional case; Tonelli theorem extends it by induction. It implies the Brunn–Minkowski inequality.
Probability density function Created 2026-09-24 Updated 2026-10-25
A probability density function represents probabilities as areas under a nonnegative measurable function. For a real random variable with an absolutely continuous probability distribution, it satisfiesfor every Borel set . Its height is probability per unit of the outcome variable, not the probability of that exact outcome. Thus a probability density function may exceed one, while the probability of a singleton is zero. NIST describes the interval-probability interpretation through integration. [ref].
For the example on , , but and . The cumulative distribution function is within that interval, connecting density height to the local accumulation rate.
Changing the scale changes the density height. If , then on . At the corresponding value , its height is , while is unchanged. The factor compensates for the wider integration variable. This is a change of variables, not a change in the underlying probabilities.
A probability density function is determined only almost everywhere: changing its values on a Lebesgue measure zero set changes no probabilities. The Cantor distribution has no such representation, and a mixed probability distribution can have both a point mass and a density component, so differentiating its cumulative distribution function does not recover all its mass.
Product measure Created 2026-09-24 Updated 2026-11-05
For sigma-finite measure spaces and , the product measure is the unique measure on the product sigma-algebra satisfyingHere is interpreted as zero. Sigma-finiteness supplies the usual existence and uniqueness theorem. For Lebesgue measures on two real lines, the product is planar Lebesgue measure and the formula assigns a rectangle the product of its side lengths. Tonelli's theorem identifies integration of nonnegative measurable functions with iterated integration; Fubini's theorem gives the integrable signed version.
For a countable family of probability spaces , the product probability measure is characterized by finite-coordinate cylinder sets:This constructs independent coordinate random variables with the specified marginal laws. The infinite-coordinate statement uses probability measures; it is not an unrestricted existence claim for arbitrary infinite products of measures of infinite mass.
Random element Created 2026-10-14 Updated 2026-10-14
A random element is a measurable function from a probability space to a measurable space . Its law is the pushforward measure for . Real-valued random variables and vector-valued random variables are examples; a stochastic sample path can also be a random element when its path-space sigma-algebra is specified. For a Polish space , the usual choice is its Borel sigma-algebra. A large deviation principle concerns the laws of a family of such random elements.
Random variable Created 2026-09-24 Updated 2026-10-14
A real-valued random variable is a measurable function from a probability space to the real numbers with their Borel sigma-algebra. More general targets give random elements. For every Borel set , measurability ensures that is an event, so the question "does the observed value lie in ?" has a defined probability.
The function is fixed; its input outcome is uncertain. This separates what we measure from how the uncertainty is modeled. A probability distribution is the resulting pushforward measure, . A cumulative distribution function, probability mass function, or probability density function describes that measure in an appropriate setting. The random variable and its probability distribution are different objects: the former also retains its relationship to other measurements on the same sample space.
For two independent uniform dice, let record their results and define and . The 36 ordered pairs are equally likely, but the resulting probability mass functions differ:For the sum, count the diagonal of the outcome grid having total . For the maximum, subtract the pairs with both results below from the pairs with both results at most . These examples show how a deterministic function transforms a simple input probability distribution into a nonuniform output one.
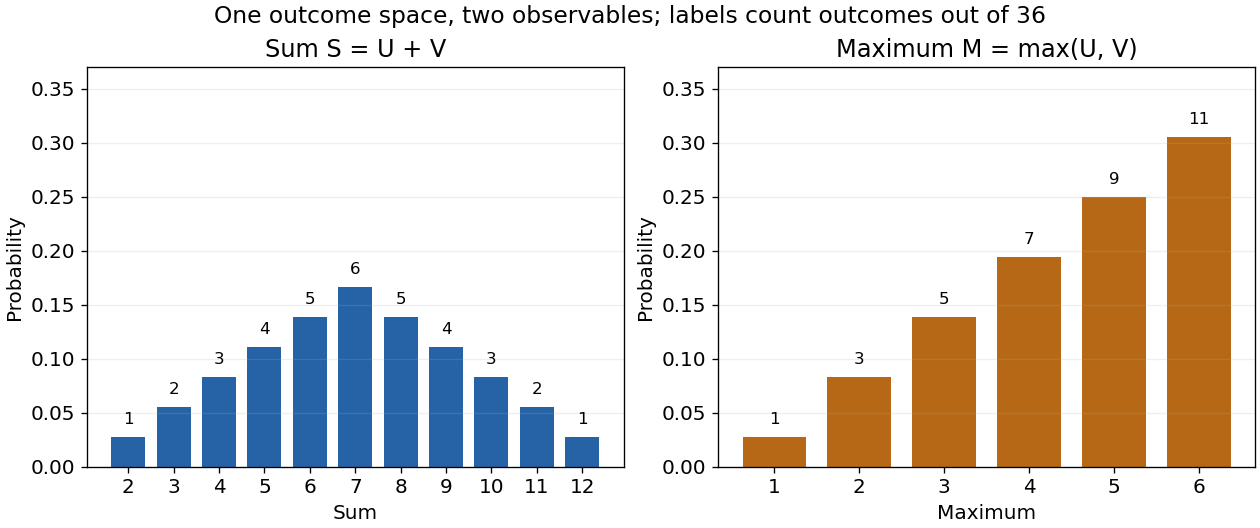


The corresponding expected values are and . The first follows immediately from linearity of expectation; the second follows from . Neither number must be an attainable result. An expected value describes an average under the probability measure, not a prediction that the next observation will equal it.
The distinction between a random variable and its probability distribution matters for dependence. and have the same discrete uniform distribution and are independent random variables. and a second copy of also have that same marginal probability distribution, but they always agree. Their joint probability distribution is concentrated on the diagonal; the marginals alone cannot say which relationship holds. This is why a model for several measurements must specify their joint law or an appropriate independence assumption.
Indicator random variables turn events into numbers: equals one on and zero elsewhere, and . This connects event counting with expected value and variance, and lets tools for random variables answer questions about probabilities. More complicated functions of observations can describe totals, waiting times, or estimation errors using the same framework.
Reachable set 2026-10-14
The reachable set collects all endpoints attainable from at exactly by admissible control inputs. If arrival any time up to is allowed, use , with . These definitions differ: a general dynamical system may drift away after early arrival, so waiting need not preserve the target. The reachable set is always relative to a declared input class and any constraints on the entire path.
For the double integrator starting from , now require measurable functions as control inputs with almost everywhere. Write for its endpoint at . Two integrals determine the endpoint:Our mathematical example has the exact reachable setTo see the upper boundary, fix : put first and last, switching at . This maximizes the weighted integral for position because early commands have the largest weight ; the required net velocity fixes . Formally, has the same sign as this maximizing command, so changing to any other admissible command with the same integral cannot increase . Reversing the order gives the lower boundary. Pointwise convex combinations of these two commands preserve and attain every intermediate , so the formula describes the whole region, not merely a bound. The extreme commands are bang-bang control.
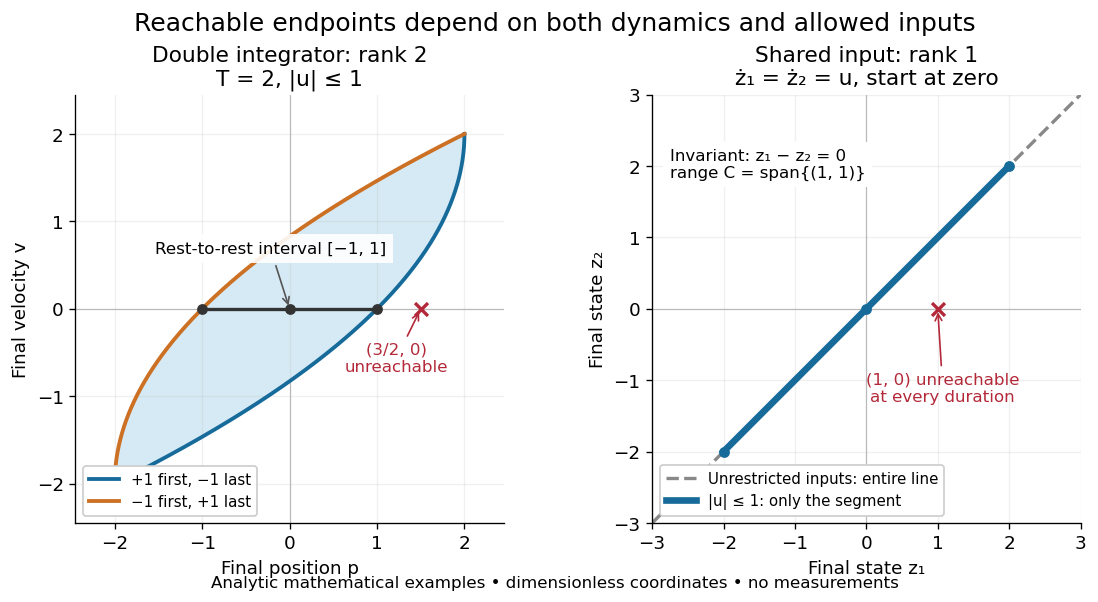

In particular, the bounded double integrator can move from rest to position and rest again exactly when . Its minimum duration is therefore in these normalized units. With freely chosen time every rest-to-rest distance is attainable; with a fixed deadline many are excluded. Changing the amplitude bound to with scales this condition to . This shows why specifying the controls matters even when the Kalman rank criterion gives full rank of a matrix.
In closed quantum control, a density operator reachable set lies inside its unitary orbit of a density operator, since coherent evolution preserves the spectrum. That orbit need not be fully reachable under the available control inputs.