Substitution of gives the characteristic equation of a linear recurrenceThe repeated characteristic root of a linear recurrence supplies the solutions and , while the simple root supplies . They are linearly independent: their values at three consecutive indices have nonzero determinant. A third-order linear recurrence relation is uniquely determined by three consecutive initial values, so these three solutions span its solution space. The general solution is
Let . For the exponential trial sequence ,Thus gives a particular solution. The difference of any two solutions of the inhomogeneous linear recurrence satisfies the homogeneous linear recurrence relation in part (i). Therefore
The forcing base is a root of the characteristic equation of a linear recurrence, so a constant multiple of cannot be a particular solution. For , direct substitution givesFor the resonant case of exponential forcing in a linear recurrence, at , and . Hence is a particular solution of the inhomogeneous linear recurrence. The general solution is
The superposition principle applies because the recurrence operator is linear. Add the particular solutions from parts (ii) and (iii), then add the general homogeneous linear recurrence relation solution from part (i). This gives
The first-order chain rule, with regarded as functions of , isApply the product rule when differentiating the first identity in , and apply the chain rule to . Equality of mixed partial derivatives for a function givesThus . These terms record the second derivatives of the coordinate transformation, not of .
For the given transformation,The mixed-derivative coefficient is zero, while , , and . The required partial differential equation is therefore exactly . Integrating first in and then in on a coordinate rectangle giveswhere are arbitrary twice continuously differentiable functions. The Jacobian determinant of the transformation is , so this calculation uses patches with . On a positive-quadrant patch we can take and , obtainingChanging branches merely redefines the arbitrary functions.
For completeness, the original equation also makes sense in quadrants with , where that particular real square-root transformation is unavailable. Multiplying the equation by givesOn any quadrant with , put , ; then set , . The equation becomes . Thus an equivalent general local answer on every such quadrant isHere are arbitrary functions on the relevant intervals. If a solution is required across , its quadrant expressions must extend with matching derivatives; on that line the equation itself imposes , so its trace is on each interval with . The displayed coordinate transformations do not assert invertibility at .
For , on , so is a convex function; for it is linear and also convex. The equally weighted random variable has expected value . Applying Jensen's inequality givesMultiplying by provesFor equality requires all , by strict convexity; for equality holds for every admissible vector.
For a fixed horse , independence of the race results gives probability of winning every race. The events that different horses win every race are disjoint, soThis is a homogeneous polynomial of degree . Apply part (a) to the nonnegative numbers , whose sum is one, to obtain . For the smallest probability occurs when every horse has winning probability ; for a single race regardless of these probabilities.
Put and . Their second moments are the finite positive variances of . The Cauchy-Schwarz inequality for square-integrable random variables givesDivide by the positive product of variances and take square roots. The correlation bound is . As usual, non-constant here means not almost surely constant, so that the denominator is nonzero.
Zero correlation means that the variables are uncorrelated: , or equivalently . It does not imply independence. For example, if is uniform on and , symmetry gives , hence zero covariance, although is determined by . Both random variables are non-constant and have finite positive variances.
Perfect correlation means an affine relation almost surely: there are constants such that almost surely. The sign of is the sign of the correlation coefficient. More precisely, equality in the Cauchy-Schwarz inequality gives
Interpret the random choice as an independent selector with , and write . Its distribution is again uniform on , so and . By independence,Consequently . The independent selector is the standard meaning of the stated mixture; a choice depending on the signs would describe a different model.
Let and write the constant-coefficient linear ordinary differential equation as . Since ,The exponential never vanishes, so .
For the second claim, the product rule givesfor , with the term treated separately. Summing the coefficients yieldsA root of multiplicity at least two has , proving is also a solution. This directly establishes the repeated-root contribution without assuming a solution formula. If the displayed coefficient list has leading zeros, the exponential calculation still applies to its actual polynomial degree.
Set . The resulting second-order linear differential equation is . A polynomial particular solution requires and , hence . The homogeneous characteristic roots of a constant-coefficient differential equation are , soIntegrating twice and renaming constants gives the general real solutionThe four independent homogeneous terms account for the four initial data of the fourth-order linear ordinary differential equation.
For the substitution , repeated use of the chain rule, with , givesThereforeFor , the map is invertible, and the transformed equation is exactly the equation just solved. Hence the general real solution on isThere is no requirement that extend as an even function through : only the branch is needed, so the sine and square-root terms must be retained.
Substitute the power series and compare coefficients. The constant coefficient gives . For , the coefficient of givesThus , while the equation places no restriction on . For ,The power series therefore sums toRenaming the two arbitrary constants gives .
Both functions solve the equation by direct substitution. Their Wronskian, in the order , is , which is nonzero for . Hence they give the full two-dimensional solution space on either interval away from the singular point. Both are entire, and the displayed formula also gives every twice continuously differentiable solution through zero: matching and fixes the same on the two sides.
For two solutions , define their Wronskian byDifferentiation and substitution of the second-order linear differential equation giveThis proves the Abel identity and hence
On an interval where the known solution does not vanish,Integrating gives the reduction of order formulaChoosing the normalization makes the Wronskian nonzero, so this solution is linearly independent of . To verify it really solves the equation, write . Its equation reduces tothe integrand gives , which satisfies this equation on differentiation. Adding an integration constant only adds a multiple of . The formula is local where ; at a zero of with regular coefficients, the actual solution can be continued by initial-value existence and uniqueness, even if its integral representation has an apparent singularity.
Multiply the equation by to obtain . The leading terms after a Frobenius method trial arethe term involving first appears at order . The indicial equation is therefore
To obtain the first correction to a regular singular solution by reduction of order, start from the assumed solution and use the Abel identity:We work initially on near zero; since is a positive integer, the resulting expansion is an ordinary power series. Also , so the reduction of order integral has integrandChoose its integration constant to be zero, eliminating an added multiple of . Integrating and multiplying by givesWith the requested normalized answer isIts nonzero Wronskian makes it independent of . The existence of the asserted also forces ; there is no need to introduce into the normalized second coefficient.
Write the coefficient matrix as . Its characteristic polynomial is . Corresponding eigenvectors arewith eigenvalues respectively, as direct multiplication verifies. Distinct eigenvalues make these vectors a basis. Expanding a solution as decouples the linear ordinary differential equations into , , . Thus the general solution is
The forcing vector has the eigenvector decompositionThere is no component in the zero eigenvalue direction. The scalar inhomogeneous linear differential equations in this basis areFor the first, a particular solution is . For the third, multiplying by the integrating factor gives . Consequently for every real When , the resonant component vanishes and a particular solution is , of the stipulated constant-vector form. If , substituting would require . In the eigenbasis the left side has zero component, while the right side has component . This is impossible. The factor is therefore unavoidable: it is resonance in a differential equation.
At the forcing vanishes and the forcing coefficient is . The initial vector decomposes asThus , , in part (b), and the requested solution isEquivalently,These expressions have the required initial values and solve all three linear ordinary differential equations.
At a critical point of a twice continuously differentiable function, the linear term in the Taylor expansion vanishes:The real symmetric Hessian matrix has an orthonormal basis of eigenvectors. If all its eigenvalues are positive, its quadratic term is bounded below by a positive multiple of , giving a strict local minimum. If all are negative, it gives a strict local maximum. If positive and negative eigenvalues both occur, directions along their eigenvectors give values on both sides of , so the point is a saddle point of a scalar function. The non-singularity assumption excludes zero eigenvalues; with them the quadratic test may be inconclusive and higher-order terms are needed.
The gradient components areIf or , their simultaneous zeros give . If , solving , gives . These are all the critical points. The Hessian matrix isAt each of its determinant is , so its two eigenvalues have opposite signs. All three are saddle points of a scalar function. At ,This point is a strict local maximum, of value .
The zero level set is exactlyThese three lines form a triangle containing the maximum. Inside it ; near the maximum positive level sets are nested closed curves, with their leading shapes elliptical because the Hessian matrix is negative definite. At each vertex the zero lines cross, separating alternating signs, and nearby nonzero level sets have hyperbolic branches. For example, the leading quadratic terms are at , for at , and for at .
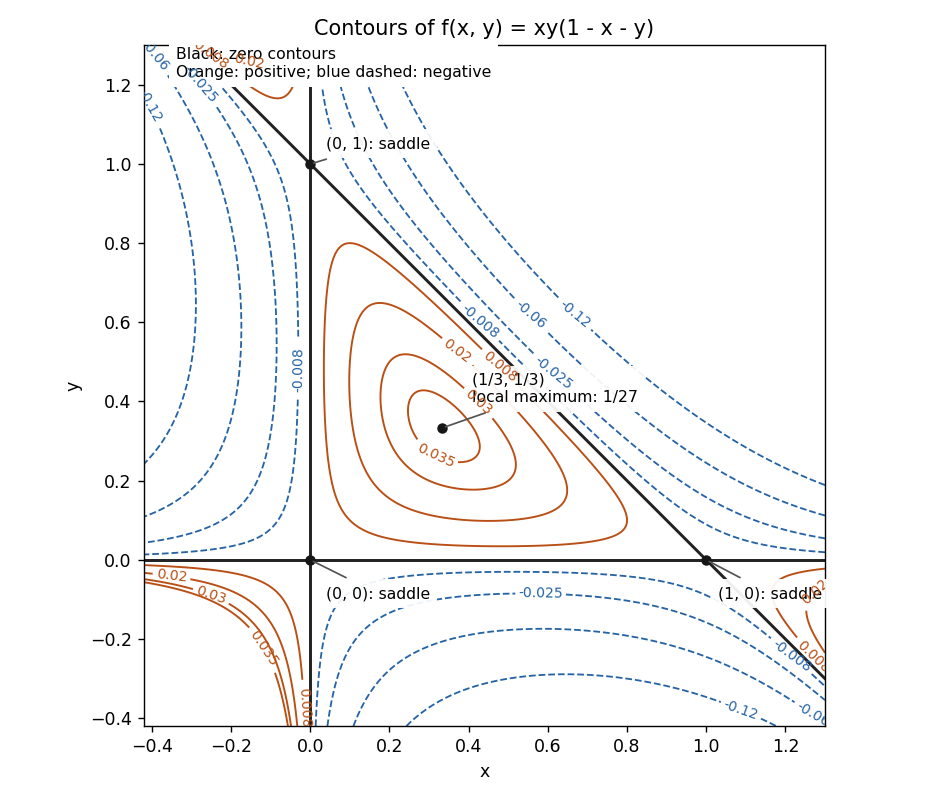

Put and . The polynomial becomesThere are no terms of degree one or two, so the gradient and the entire Hessian matrix vanish at . It is a critical point with singular Hessian matrix. The lowest nontrivial approximation isunderstood as the fourth-degree leading term rather than a uniform ratio asymptotic along its zero directions.
On the path the exact value is for . On the path it is for sufficiently small nonzero . Both paths approach the point, where . It is neither a local maximum nor a local minimum; it is a degenerate saddle point of a scalar function. The higher-order saddle test supplies the conclusion the singular Hessian matrix cannot supply.
A geometric distribution with parameter on has probability mass functionIt counts the trial on which the first success occurs in independent trials with success probability . Its probability generating function is . Differentiating at givesThis support convention is important: a count of failures before the first success would start at zero.
This is the waiting time to observe both Bernoulli outcomes. Write , and let record the sex of the first captured animal. That first capture is always needed. If is male, every subsequent trial independently produces the required female with probability , so has a geometric distribution with parameter . If is female, has a geometric distribution with parameter . By the law of total expectation,Since , this simplifies to , orThe expectation includes both the first capture and the final capture completing the pair.
Use the same first-sex conditioning as in part (b). The conditional variances are after a male first capture and after a female first capture. ThusThe conditional expected values are and , with probabilities . A variable taking two values with probabilities has variance , soThe law of total variance now givesAt this gives variance , consistent with being one plus a geometric waiting time of parameter .
The event occurs precisely when every one of the first levels is at most . Their independence gives the cumulative distribution functionFor any nonnegative random variable, the pointwise identity and the Tonelli theorem allow interchange of expectation and integral. HenceThis identity holds as an extended nonnegative integral; finiteness of the mean is not guaranteed by continuity of .
The future levels are independent of the observed maximum. Given , the first future levels must be at most , and the th must exceed . Each non-overflow has probability and an overflow has probability . ThereforeThis is a geometric distribution of parameter when . Since has a continuous distribution, conditioning on an exact value is understood via a regular conditional distribution, rather than division by . The formula specifies its usual version. If there is no possible overflow at that threshold, but such thresholds have probability zero for the random observed maximum.
The continuity of the cumulative distribution function gives the probability integral transform: is uniform on . Strict monotonicity or a probability density for is not required. Since is nondecreasing,By independence, for , so has probability density function . Average the conditional probability in part (b) using this distribution:Thus . The expression telescopes to total mass one, so the waiting time is finite almost surely.
For the waiting time for a new record after a fixed sample, given , no overflow in the first subsequent years has probability . Averaging as in part (c) yieldsThe tail-sum formula for expectation therefore givesThe answer is . This does not contradict almost-sure finiteness: the tail probability tends to zero, but too slowly for its sum to converge.
Conditional on , the next generation is the sum of independent offspring counts, each with probability generating function . HenceThis also holds for , when the empty sum is zero and the empty product is one. The law of total expectation givesFor complex , the expectations are absolutely bounded because . This proves the branching-process generating-function iteration, with .
The eventual extinction probability is the smallest solution . This is the Galton-Watson extinction fixed point result for one initial individual. Equivalently,since having an empty generation is an absorbing event and the extinction-by-generation events increase. In particular extinction is certain when the smallest fixed point is one. With , an offspring mean at most one implies this, whereas a mean greater than one gives a fixed point below one. The fixed-point statement itself requires no finite-mean assumption.
Summing the geometric series for the offspring probability generating function givesThe fixed-point equation is , whose only root in is one. The Galton-Watson extinction fixed point result therefore proves extinction is certain.
For the explicit iterates, the proposed formula at is , so the base case holds. If it holds at , part (a) givesThis is exactly the same formula with replaced by . By induction,Evaluating the probability generating function at zero selects the mass of an empty generation:These probabilities increase to one, also confirming the extinction conclusion directly.
The nonsingular bivariate normal distribution has and . Put and . Completing the square givesConsequently the joint probability density function factors asFor fixed , the second factor is a normalized normal distribution density in , with mean and standard deviation . Its integral is one; explicitly substitute in the Gaussian integral. Thus the marginal density is
The other marginal is by the same square-completion argument with the indices exchanged. Its moment-generating function is therefore
Now complete the square in the other order:Divide the joint probability density function by the positive marginal densityThe factor cancels, giving the conditional probability densitySincethis is a normalized normal distribution density. HenceConditioning on an exact observation is interpreted through this conditional probability density, rather than conditioning by a ratio of event probabilities.
Articles by others on the same topic
There are currently no matching articles.