
Nash equilibrium Created 2026-09-24 Updated 2026-10-14
A Nash equilibrium is a strategy profile in which every player's strategy is a best response to the others. For a finite game and mixed strategies, its precise condition isThe opponents' strategies are held fixed while testing each unilateral deviation. Equality is allowed: a player may have other equally good best responses. Because expected payoff is a linear function of the player's own mixture, it suffices to test every pure strategy. Equivalently, every choice in the support of a mixed strategy must attain the largest pure-choice expected payoff, and no unused choice may exceed it.
The two worked examples illustrate different uses of this condition. Matching pennies has no pure strategy Nash equilibrium, but its unique mixed strategy Nash equilibrium removes each player's vulnerability to predictable play. The asymmetric coordination example has three Nash equilibria, and its mixed one fails Pareto efficiency. A Nash equilibrium tests individual incentives, whereas Pareto efficiency compares feasible outcomes that may require several players to change together. In the prisoner's dilemma, for example, mutual defection is a Nash equilibrium even though mutual cooperation gives both players a larger payoff because .
Existence in a finite game is guaranteed by Nash's theorem. The theorem does not select one Nash equilibrium, promise Pareto efficiency, or assert convergence of a learning process. Nash's [ref] used the Kakutani fixed-point theorem; his [ref]
https://cs.uwaterloo.ca/~klarson/teaching/F04-886/papers/nash51.pdf. 1951 paper, section Existence of Equilibrium Points
gave a proof using the Brouwer fixed-point theorem. The connection to a fixed point captures the idea of choices that remain mutually optimal when considered together. Inertia of a bilinear form Created 2026-09-24 Updated 2026-10-03
The inertia of a real symmetric bilinear form is the triple giving the numbers of positive, negative, and zero squares in a diagonalization. Sylvester's law of inertia makes it independent of the chosen basis.
Nondegenerate bilinear form Created 2026-09-24 Updated 2026-10-14
A bilinear form is nondegenerate when its left radical and right radical are both zero: every nonzero vector can be detected by some pairing, whichever input slot it occupies. On a finite-dimensional vector space, either condition implies the other, and the following tests are equivalent:Here is the matrix of a bilinear form, and is the dual space. The linear map has matrix in the chosen basis and its dual basis, so its kernel is the right radical. The map has matrix . An invertible matrix has zero kernel on both sides, proving the finite-dimensional equivalence. In infinite dimensions, zero left radical and right radical imply these maps are injective, but do not generally make them surjective.[ref]
For the real symmetric bilinear form , the determinant is . Its isotropic vector has zero self-pairing but pairs to with , so it is detected. The alternating bilinear form with matrix has determinant and detects every nonzero vector even though all self-pairings vanish. Neither zero self-pairings nor the absence of positive definiteness implies degeneracy.
Nondegeneracy is useful because it turns a linear functional into a unique vector. For , the linear functional is ; solving for that representing vector amounts to solving an invertible system of linear equations. The analogous identification underlies bilinear orthogonal complements and the dual isomorphisms induced by a nondegenerate pairing.
Radical of a bilinear form Created 2026-09-24 Updated 2026-10-14
For a symmetric bilinear form or an alternating bilinear form, the radical is the linear subspaceThese vectors are invisible to all pairings, and the bilinear form is nondegenerate exactly when this linear subspace is . In coordinates, for both kinds of bilinear form, since or . Thus has radical of a bilinear form .
Passing to the quotient vector space removes precisely the invisible directions. The rule is well-defined because adding a vector in the radical of a bilinear form to either input changes no pairing, and the resulting bilinear form is nondegenerate. For , this quotient vector space retains just the direction and its form is ordinary multiplication.[ref]
https://www.math.ucla.edu/~rse/oldbook/Kniga.pdf. Elman, Karpenko and Merkurjev, The Algebraic and Geometric Theory of Quadratic Forms, §1: radical and nondegenerate quotient
For a general bilinear form, distinguish the left radical of a bilinear form from the right radical of a bilinear form; they can be different linear subspaces even though their dimensions agree in finite dimensions.
Degenerate bilinear form Created 2026-09-24 Updated 2026-10-14
A bilinear form is degenerate if some nonzero vector pairs to zero with every vector on at least one side. For a symmetric bilinear form or an alternating bilinear form, this says its radical of a bilinear form contains a nonzero vector. On a finite-dimensional vector space, it is equivalent to a singular matrix of a bilinear form, or .
For , . The nonzero vector is invisible to every pairing, and changing never changes . The quadratic form therefore has two parallel lines as its unit level set. This is a lost direction, a stronger condition than being an isotropic vector: with , but .
Coercive bilinear form Created 2026-09-24 Updated 2026-10-14
A real bilinear form on a normed vector space is coercive when there is one constant such thatThe lower bound uniformly controls every direction in the chosen norm. Unlike the upper bound defining a bounded bilinear form, it forces positive diagonal values at every nonzero vector. No symmetry is assumed. For complex Hilbert spaces, the usual analogue uses a sesquilinear form and ; it is not the same assertion for a complex bilinear form.
A concrete bounded and coercive example on , with the Euclidean norm, isIts quadratic form isThe best lower constant is , attained at . Nevertheless, and , so coercivity does not imply a symmetric bilinear form. The symmetric part of a matrix determines , while the skew-symmetric matrix part changes mixed pairings without changing . This is the symmetric and alternating parts of a bilinear form decomposition.[ref]
For the upper constant, direct multiplication gives . Its eigenvalues are , so the optimal upper constant, the spectral norm, is . The two constants answer different questions: how large a mixed pairing can be, and how small a self-pairing can be relative to squared norm.
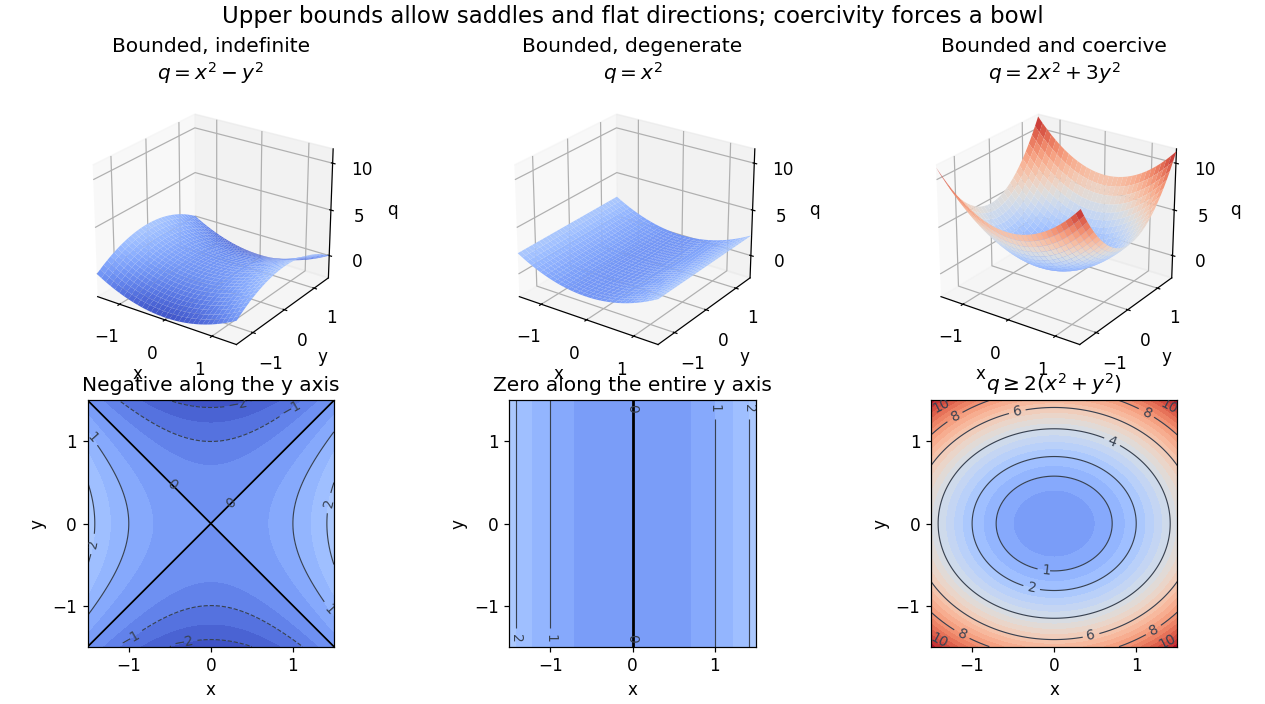
Bounded saddle and flat-direction quadratic forms contrasted with a uniformly coercive bowl
. Details. 
The plotted quadratic forms show the mechanism: descends in one direction, leaves one direction uncontrolled, and controls both. These are self-pairings; their level sets cannot reveal the skew-symmetric matrix part. Calling a quadratic energy here refers to this diagnostic quantity, not to a claim that a nonsymmetric equation comes from minimizing an energy functional.
On a real finite-dimensional vector space with any norm, strict positivity for every nonzero does imply coercivity. Indeed the quadratic form is continuous, and its positive minimum on the compact unit sphere supplies . If is also a symmetric bilinear form, this is positive definiteness. For general , it is the symmetric and alternating parts of a bilinear form decomposition that isolates the positive part. Switching between equivalent norms preserves coercivity, but usually changes its constant.
The infinite-dimensional vector space distinction is explicit on the real l2 sequence space:The Cauchy-Schwarz inequality gives boundedness with , and for every nonzero vector. But with , so no positive works. On the span of , the best lower constant is : each finite restriction is coercive, but the control disappears as grows. Strict positivity is therefore weaker than a uniform lower bound.
The practical payoff is a stability estimate for a weak formulation. Assume is a real Hilbert space, is both a bounded bilinear form and a coercive bilinear form, and the load is a bounded linear functional. The Lax-Milgram theorem gives a unique satisfying for all , including nonsymmetric .[ref]
Introduction to Finite Element Methods by Christian Clason. §2.2, Theorem 2.7, pp. 20–21, equation (2.9): hypotheses, unique solvability and load bound
The dual norm measures load size. Testing with gives the short energy estimateFor the bound holds directly; otherwise divide by . Subtracting the equations for two loads and using the same argument gives . Thus a positive lower constant limits the response to load errors. The upper bound and completeness of the Hilbert space enter the existence theorem; the estimate itself uses the lower bound and the load's dual norm.For the displayed matrix , take . Then for every means , not , with this ordering of the bilinear form. Since ,For , the exact response is and . For , it is , with norm . The actual maximal amplification is the operator norm : the coercivity estimate is valid but need not be sharp for a nonsymmetric bilinear form.
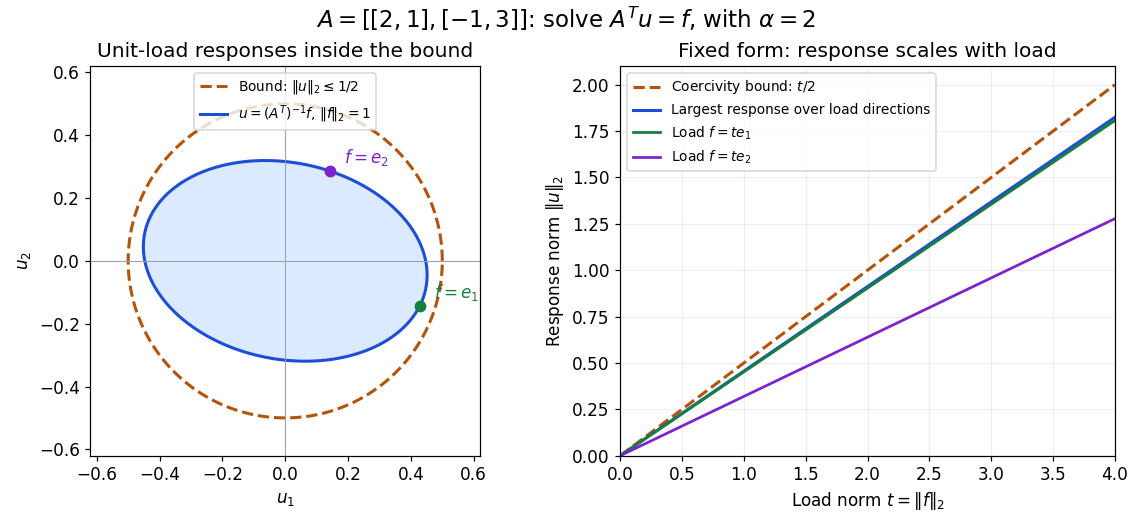
Solutions for unit loads lie inside the coercivity bound, and response grows at most linearly with load norm
. Details. 
Bounded bilinear form Created 2026-09-24 Updated 2026-10-14
A bilinear form on a real normed vector space is bounded when one constant satisfiesThis is an upper bound on the magnitude of every pairing. It says nothing about the sign of and does not require a symmetric bilinear form. The chosen norm is part of the hypothesis. Boundedness is equivalent to joint continuity, as shown by the boundedness criterion for a bilinear form.[ref]
For example, on with the Euclidean norm, the bilinear formsboth satisfy the upper bound with , by the Cauchy-Schwarz inequality. Yet their quadratic forms are and : the former takes negative values and the latter vanishes at the nonzero vector . Thus neither is a coercive bilinear form. The latter is also a degenerate bilinear form, whereas is nondegenerate. Boundedness controls size, not positivity or loss of directions.
Every bilinear form on a real or complex finite-dimensional vector space equipped with any norm is bounded. In coordinates, write using its matrix of a bilinear form. The Cauchy-Schwarz inequality gives , with the spectral norm; finite-dimensional equivalence of norms transfers this to the chosen norm. The conclusion concerns each fixed norm and fixed bilinear form: it does not supply a single constant for an arbitrary family of matrices or changing dimensions.
On an infinite-dimensional vector space, the upper bound is an additional condition. Equip the finitely supported sequences with the norm inherited from the l2 sequence space and setEach pairing is a finite sum, so this is a well-defined bilinear form. For the basis vector , however, and ; no finite works. It is even a coercive bilinear form with , since . Consequently coercivity alone does not imply boundedness on a normed vector space. This example uses , which is not a Hilbert space; it does not define this pairing on all of the l2 sequence space.
A bounded bilinear form defines a bounded linear operator by , where is the continuous dual space. Its operator norm is the smallest admissible :This converts an upper bound for pairings into an upper bound for a linear map taking an unknown vector to a linear functional.
Bifurcation diagram of the 2023 Cambridge quadratic-product system Created 2026-09-24 Updated 2026-09-24
The equilibria of , lie onfor every , and on for . They meet in a subcritical pitchfork bifurcation at ; the positive square-root branch meets the branch and exchanges stability in a transcritical bifurcation at .
Draining time of a uniform tank through a siphon Created 2026-09-24 Updated 2026-10-14
If a tank and siphon tube have areas and , the tube outlet is below an inlet initially submerged by , and both free boundaries are at atmospheric pressure, continuity and Bernoulli's equation givefor the free surface to reach the inlet.
Bernoulli equation over topography Created 2026-09-24 Updated 2026-09-24
For steady potential flow over small hills, linearized Bernoulli pressure combines a hydrostatic term with a dynamic term .
Bernoulli function Created 2026-09-24 Updated 2026-10-06
CHSH inequality Created 2026-09-24 Updated 2026-10-18
For local outcomes , the Clauser–Horne–Shimony–Holt inequality isAn arbitrary no-signalling correlation can reach the algebraic maximum , while quantum correlations are bounded by .
For a short proof of the local bound, fix a deterministic local hidden-variable model assignment. The combination is . Exactly one bracket vanishes and the other is , so every assignment contributes . Averaging with a single setting-independent probability distribution preserves the interval . Mixtures also cover stochastic local hidden-variable theories. Rejecting a different sample at each setting would invalidate precisely that common-average step.
The quantum bound follows just as economically. For Hermitian operators with , the CHSH inequality operator obeys . Each commutator has operator norm at most two, giving . The Polarization CHSH count model attains this bound without allowing either station to control the distant marginal probability distribution.
Local hidden-variable theory Created 2026-09-24 Updated 2026-10-07
Evidence lower bound Created 2026-09-24 Updated 2026-09-24
Bayesian model averaging Created 2026-09-24 Updated 2026-09-24
Bayesian model averaging weights each model-specific posterior by that model's posterior probability.
Markov chain Monte Carlo Created 2026-09-24 Updated 2026-09-24
Markov chain Monte Carlo constructs an ergodic Markov chain whose stationary distribution is the target law and uses its post-burn-in states as approximate dependent samples.
Bayes estimator Created 2026-09-24 Updated 2026-09-24
Bayesian posterior Created 2026-09-24 Updated 2026-10-14
The Bayesian posterior is the conditional probability distribution of an unknown statistical parameter after observing data. Suppose a continuous prior distribution has prior density relative to Lebesgue measure , and is the sampling probability mass function or probability density function of the observed data in the statistical model. Bayes' theorem givesThe Bayesian model evidence is the normalization constant making the posterior density integrate to one. The strict positive, finite condition is essential: a zero or infinite normalizer does not define this posterior distribution, even if the unnormalized expression can be written down. Other reference measures give the corresponding density formula; discrete parameter values replace the integral by a sum. The posterior propriety article gives examples where normalization fails.
With fixed, is a likelihood function of . Its normalization as a sampling distribution is over possible data, not over parameter values. In particular, a likelihood function is not a probability density function for and need not integrate to one over . The prior density supplies the probability weighting, and the Bayesian model evidence normalizes their product. This distinction prevents a tempting mistake: reversing the conditioning merely by exchanging the words “data” and “parameter”.
For eight heads among ten conditionally independent Bernoulli trials, take the observed data to be the heads count . Its binomial distribution likelihood function and the prior density giveUsing the Euler beta function , the Bayesian model evidence and normalized posterior density areThus the posterior distribution is . If the data are instead one particular ordered sequence with eight heads and two tails, its likelihood function omits the factor 45 and its Bayesian model evidence becomes . The factor cancels in Bayes' theorem, leaving the same posterior distribution; these two data descriptions have different sampling probabilities but identical information about here.
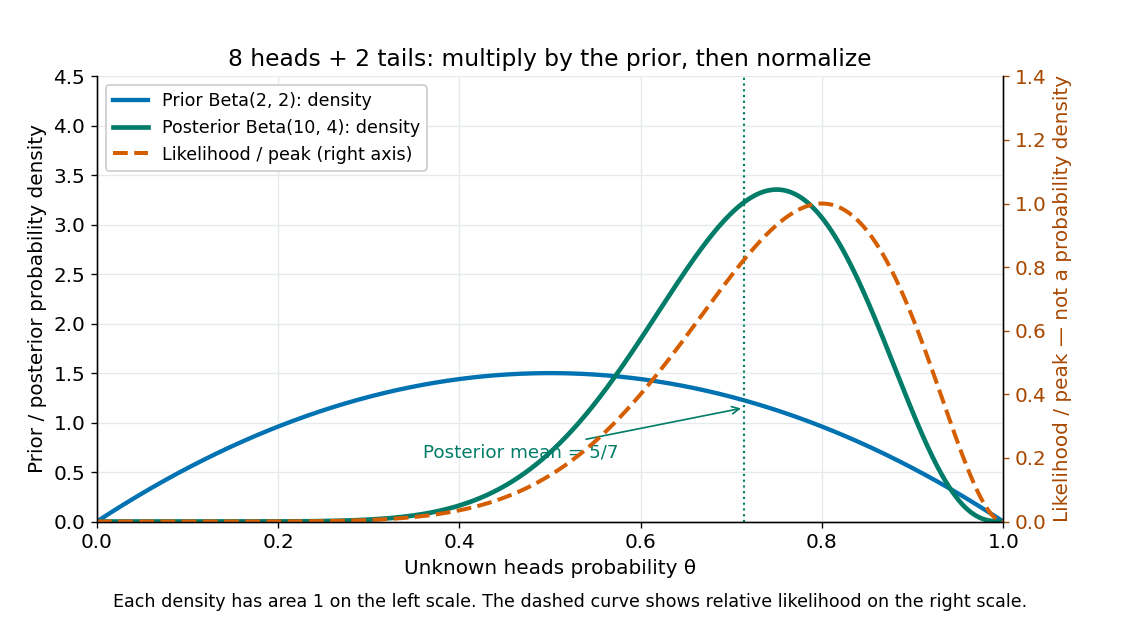
Beta(2,2) prior, peak-normalized Bernoulli likelihood, and Beta(10,4) posterior after eight heads and two tails
. Details. 
The prior density and posterior density use the left axis and each integrate to one. The dashed likelihood function uses the right axis and is divided by its maximum solely to compare its shape; it is not a parameter probability density function. The likelihood function peaks at , while the posterior mode is and the posterior mean is . Multiplying by the prior density shifts the preferred values toward one half while preserving a range of possibilities.
The resulting posterior variance is , compared with prior variance . In this example the update reduces uncertainty. The posterior predictive probability of heads on the next conditionally independent toss is , and the credible interval above reports a 95% range. These are summaries of the same posterior distribution, rather than competing estimates of one density peak.
Prior probability Created 2026-09-24 Updated 2026-10-14
Prior probability describes uncertainty before the current observations are incorporated. For a statistical parameter , a prior distribution assigns probabilities to its possible ranges, conditional on background information and a statistical model. A continuous prior density specifies these probabilities through integration:Here the probability density function is relative to Lebesgue measure ; a discrete prior distribution instead uses a probability mass function and sums. Density at one point is not the probability of that point. A nonnegative kernel with infinite total mass is an improper prior, whose use requires a separate check of posterior propriety.
For the coin model in Bayesian statistics, the beta distribution has prior density on . Its mean is and its variance is . It favors moderate heads probabilities without ruling out values near zero or one. For example,The prior curve in Bayesian posterior makes this preference visible; moment matching for a beta prior explains how to choose a beta distribution from a desired mean and variance.
A prior distribution lets earlier evidence or elicited knowledge contribute to statistical inference when the current sample size is limited. It also exposes assumptions that can be checked by prior elicitation and a prior predictive check. Before the same eight heads and two tails, a uniform prior would give posterior mean , compared with under : the observations do not uniquely determine a Bayesian posterior. Even a uniform prior makes a choice of parameter coordinates; its child article explains why changing coordinates can destroy uniformity.
Klein bottle group Created 2026-09-24 Updated 2026-10-03
There are unlisted articles, also show them or only show them.