Artificial intelligence studies computational systems that perform tasks involving inference, learning, planning, perception or action under uncertainty. A classifier can learn to map measured features to labels; a planning system can search for a sequence of actions satisfying a goal. The capabilities depend on the model, training information and evaluation setting. Success on one benchmark does not by itself establish general competence or human-like understanding. Machine learning, symbolic reasoning and search algorithms offer different, sometimes combined, ways of building such systems.
Optical character recognition converts pictures of written or printed text into encoded text. The input is an image of marks; the output is a sequence of characters that can be searched, copied or processed as text. Merely storing a scanned page as a raster image does not perform this recognition.
A typical system must locate text regions and lines, separate or jointly interpret their marks, and decide which character sequence they represent. Image processing can correct skew or improve contrast; image segmentation can identify regions and candidate boundaries. Recognition can use visual evidence together with constraints from surrounding text. These stages can fail separately: a correct symbol classifier cannot read a line that the layout analysis omitted.[ref]
An Overview of the Tesseract OCR Engine by Ray Smith. §2, printed p. 629, architecture: binary input, connected components and organization into lines and words; §§3–5, line finding and word recognition
For a concrete ambiguity, the final
rn of modern can resemble m in a degraded scan, producing modem. That single visual merge requires two ordinary character edits to repair: substitute the final m with r, then insert n. With six reference characters, the character error rate in this synthetic example isThe edit distance makes the scoring rule explicit; one visual mistake need not count as one character edit.[ref]Quality Assurance in OCR-D by OCR-D. Evaluation Metrics, Levenshtein Distance and Character Error Rate sections
A historical implementation illustrates the engineering choices: the 2007 description of Tesseract starts from a binary image and organizes connected outlines into text lines and words before recognition passes. That is evidence about a particular engine architecture, not a requirement that every recognizer use separate character segmentation. Accuracy depends on the images, writing system, layout and evaluation convention; fluent-looking output can still contain consequential transcription errors.
Character segmentation separates an image of text into regions or hypotheses associated with individual characters. It is a specialized image segmentation problem within optical character recognition. The useful boundaries depend on the writing and imaging process: visible connected ink regions need not correspond one-to-one with characters.[ref]
An Overview of the Tesseract OCR Engine by Ray Smith. §2, outlines, text lines and word organization; §§4.1–4.2, chopping joined characters and associating broken ones
For example, the dot and stem of a lowercase i can be disconnected regions belonging to one character. Two touching characters can instead form a single connected region. Connected-component labeling can locate connected regions, but counting those regions alone therefore cannot reliably count the characters.
A recognizer can compare alternative splits and merges. A degraded image of
rn may admit one merged-region interpretation as m and a two-character interpretation as r followed by n. The choice depends on shape evidence, spacing and recognition context. Incorrectly committing to one region per character too early can make the correct word unavailable to later stages.The historical Tesseract engine described by Ray Smith tests cuts when word recognition is unsatisfactory and can also associate broken pieces. Recognition thus supplies feedback about segmentation hypotheses, rather than merely accepting a fixed partition.[ref]
An Overview of the Tesseract OCR Engine by Ray Smith. §4.1, Chopping Joined Characters; §4.2, Associating Broken Characters
Character segmentation should be evaluated separately from simply matching the final text. A boundary error can cause several character edits, while a correct boundary can still receive the wrong label. Character error rate measures the resulting transcription disagreement; it does not by itself identify which stage caused it.
An adaptive classifier updates its decision rule or parameters using information acquired while processing further data. In statistical classification, this can specialize an initially broad model to the conditions of a particular stream or document. The update may use supplied labels or examples accepted under a stated trust rule; adaptation is not evidence that every accepted label is correct.
In the 2007 description of Tesseract, satisfactory first-pass words provide examples for a more document-sensitive classifier. The paper motivates this by the limited collection of fonts within a document and describes normalization differences between static and adaptive classification. It explicitly does not describe the adaptive classifier as a simple template matcher.[ref]
An Overview of the Tesseract OCR Engine by Ray Smith. §2, two recognition passes; §7, Adaptive Classifier, font sensitivity, features and normalization
A separate toy calculation illustrates parameter adaptation without claiming to reproduce that implementation. Suppose a class is represented by the mean of one measured feature from trusted examples. Accepting another value givesWith , and , the updated mean is . A classifier using that class mean can change its later decisions as a result.
The trust rule matters as much as the arithmetic. If a wrong prediction is accepted as a label, its update can make related wrong predictions more likely. A confidence score can help select examples, but a numerical score is not automatically a calibrated probability of correctness. A useful evaluation compares a frozen baseline and the adaptive system on checked data, including the possibility of degradation as well as improvement.
The character error rate measures disagreement between recognized text and a reference transcription using edit distance. With unit-cost insertions , deletions and substitutions in a minimum-cost alignment, and reference characters, the reference-length convention isThe alignment matters: counting mismatched positions without allowing edits can exaggerate the effect of one omitted character. This convention is used to evaluate optical character recognition against a specified transcription.[ref]
Quality Assurance in OCR-D by OCR-D. Evaluation Metrics, Levenshtein Distance and Character Error Rate: reference-length formula and edit operations
For reference
cat and recognized cut, one substitution gives . For reference a and recognized aaaa, three insertions give , or . The second result is valid: under this denominator, character error rate is not bounded by one. Clipping the result or using the longer string as denominator defines a different metric.[ref]Quality Assurance in OCR-D by OCR-D. Character Error Rate, discussion of rates beyond 100% and alternative normalizations
Aggregation also changes the question. Suppose one one-character sample has one error and a hundred-character sample has none. The unweighted mean of their two rates is , while pooling edits and reference lengths gives . Reporting the aggregation rule prevents a short, difficult sample from being confused with a large fraction of the complete text.
The definition of character must be fixed too. Unicode code points and user-perceived grapheme clusters can give different lengths; Unicode normalization, spaces and punctuation can change both the alignment and its denominator. An empty reference needs an explicit convention because the displayed formula divides by zero. A score is meaningful only together with these evaluation choices.
Tesseract is an open-source engine for optical character recognition. It combines image analysis with trained recognition data to extract text from images. Its documentation describes a command-line interface and a programming interface, with recognition data for different writing systems. A language choice affects the model used; it does not translate the recognized text.[ref]
Tesseract User Manual by the Tesseract project. Introduction and Usage; Command Line Usage, Using One Language
For example, the documented command
tesseract scan.png result -l eng reads an image, selects English recognition data and writes text to result.txt. The output basename is result, so the filename extension is supplied by the selected output format. Adding pdf requests a PDF containing the page image and a searchable text layer. If recognition confuses a letter in the image, searching that text layer can still miss the intended word.[ref]Tesseract User Manual by the Tesseract project. Command Line Usage, Simplest Invocation, Using One Language and Searchable pdf output
The architecture has changed over its history. Ray Smith's 2007 paper describes an engine that groups connected image outlines into lines and words, then recognizes them in successive passes. Version 4 introduced recognition based on long short-term memory neural networks; the 5.x manual documents this engine alongside the legacy option.[ref]
An Overview of the Tesseract OCR Engine by Ray Smith. §2, printed p. 629, architecture and recognition passes
[ref]Tesseract User Manual by the Tesseract project. Tesseract with LSTM; Command Line Usage, Available OCR Engines in Tesseract 5
A useful test compares output with a checked transcription using character error rate, while also inspecting omitted regions and reading order. Recognition accuracy depends on image quality, layout and matching language data. Installing the engine alone does not establish the accuracy of a particular scanned collection.
Natural language processing studies computational methods for analyzing, transforming and generating human language. Tasks include translation, extracting information from text, and predicting a missing or subsequent word. A system must resolve ambiguity from context: “bank” in a sentence about a river and in a sentence about a loan has different meanings.
A neural language model tackles one precise part of the problem by assigning probabilities to word sequences. For example, after “the cat sat on the”, its distribution can rank “mat” above “democracy”, without thereby proving that it understands the scene. Evaluating a specific task and its errors is more informative than treating fluent text as a universal test of language competence.[ref]
A recommender system selects or ranks items for a particular user or context, such as choosing books from a large catalogue. Its prediction target may be a rating, a click or a purchase; these targets need not coincide with what a user ultimately values. A common architecture first retrieves a manageable candidate set, then scores and reranks it.
Content-based filtering uses similarities between items; collaborative filtering uses patterns of interactions between users and items. If two readers overlap strongly in their previous choices, a book enjoyed by one can become a candidate for the other even without matching its description. Learned vectors make this retrieval a nearest neighbor search or related similarity search. A dot product also depends on vector length, so normalizing the vectors can change rankings.[ref]
Candidate generation overview by Google. candidate-generation table, Embedding space, Comparing similarity measures
Computer vision infers information about a scene from digital images or video. Tasks include recognizing objects, image segmentation and estimating three-dimensional geometry. A digital image records pixel measurements after image formation; lighting, viewpoint and occlusion therefore affect what can be inferred. A dark pixel can indicate a dark surface, a shadow or a surface facing away from the light.
For example, in rectified stereo vision with parallel cameras, horizontal disparity is related to depth by , where is focal length in pixel units and is camera separation. similar triangles give the relation; a smaller disparity means greater distance. The relation requires corresponding scene points and calibrated geometry. Since , a fixed disparity error produces much greater depth error for distant points. Camera calibration, correspondence and uncertainty are thus part of the computation, rather than details that can be ignored after acquiring a picture.
OpenCV is a software library for computer vision and image processing. Its camera-geometry tools connect observed pixel coordinates to models of imaging, including camera calibration, correction of lens distortion, stereo rectification and three-dimensional reconstruction.[ref]
Camera Calibration and 3D Reconstruction by OpenCV. Detailed Description and calibration/reconstruction functions; pinned documentation version4.13.0
A checkerboard calibration target supplies known geometry that can be observed from several camera positions. Fitting the model compares detected image points with projected target points. The resulting reprojection error measures agreement in the image, rather than independently confirming every physical dimension of the reconstructed scene.
A simple perspective projection illustrates the distinction: in , replacing and by and for leaves unchanged. This scale ambiguity of perspective projection means that image agreement alone cannot verify a chosen unit of length. A camera baseline or a target of known size supplies additional metric information. Using the library well therefore includes checking geometric assumptions and units, alongside the numerical fit.
- Camera Calibration and 3D Reconstruction by OpenCV
- Camera Calibration in the OpenCV-Python tutorials
- Depth Map from Stereo Images in the OpenCV-Python tutorials
- Disparity map post-filtering in the OpenCV documentation
- Epipolar Geometry in the OpenCV-Python tutorials
- Geometric Image Transformations in the OpenCV documentation
Stereo vision estimates three-dimensional structure from images taken at different viewpoints. After camera calibration and alignment into a common image geometry, a point's horizontal displacement between the two views is its stereo disparity . For parallel ideal cameras with camera baseline and focal length in pixel units, similar triangles giveFor pixels, and pixels, the inferred depth is . Doubling the depth halves the stereo disparity, making distant structure harder to measure accurately.[ref]
What Is Stereo Reconstruction? by MathWorks. How Does Stereo Reconstruction Work?, disparity-to-depth equation
A practical apparatus uses two rigidly mounted cameras, a calibration target and synchronized exposures. Matching the same physical feature is essential: repeated textures, hidden surfaces and motion can give false correspondences. The measurement is therefore geometric inference from matched observations, not an intrinsic depth label stored in each pixel.[ref]
Camera calibration estimates the parameters relating points in a scene to measured image coordinates. In the ideal pinhole model,where contains focal lengths and the principal point, while the rotation matrix and translation locate the camera relative to the scene. Lens distortion requires additional parameters.[ref]
Camera Calibration and 3D Reconstruction by OpenCV. Detailed Description, pinhole model and distortion coefficients
A calibration experiment photographs a flat board with a known grid from several orientations. Detected grid corners provide image measurements; their known spacing supplies geometric constraints and a length scale. Parameters are fitted by minimizing reprojection error. Multiple orientations help separate camera geometry from board pose. For an ideal camera with focal length 1000 pixels, a point displaced sideways at depth projects 50 pixels from the principal point.[ref]
Camera Calibration and 3D Reconstruction by OpenCV. calibrateCamera, planar-pattern initialization and reprojection error
In an ideal camera model, the principal point is the intersection of the optical axis with the image plane, expressed in image pixel coordinates . It supplies the coordinate offset in perspective projection. For a scene point expressed relative to the camera, the model iswhere are focal lengths in pixel units. Thus the principal point belongs to the camera's internal geometry; the camera's position and orientation in the world are separate parameters.[ref]
Camera Calibration and 3D Reconstruction by OpenCV. Detailed Description, intrinsic matrix and pinhole projection equations
For , , metres and metres, the horizontal coordinate is pixels. A point on the optical axis instead has and projects to . The principal point is often near the image center, but camera calibration estimates it rather than establishing that it must be exactly centered. Cropping an image also changes the principal point's coordinate values: removing 20 columns from the left changes to , without physically moving the optical axis.
A checkerboard calibration target is a planar pattern of alternating dark and light squares with known geometry, used to estimate camera calibration parameters. Image measurements of internal corner intersections are paired with known target coordinates. Several tilted views constrain the image projection and distortion model.[ref]
Camera Calibration in the OpenCV-Python tutorials. Code, known checkerboard points, corner detection and calibration
For a board with nine squares across and six down, the internal-corner grid has eight columns and five rows. If square spacing is 20 millimetres, one can assign corner coordinates millimetres for and . Supplying only unit grid spacing instead yields translation estimates in square-size units. A useful experiment varies the target's orientation and image position, then examines reprojection error. Repeated identical views provide less geometric information; a warped board or inaccurate corner measurements can also bias the fitted camera model.
Automated deduction uses an algorithm to construct or check a mathematical proof from explicit assumptions and inference rules. The representation might use propositional logic, first-order logic or a specialized theory such as linear arithmetic. Soundness means the rules preserve truth; finding a proof additionally requires a search strategy.
For a small resolution example, the clauses , and yield and then the empty clause. This is a contradiction, so the original clauses cannot all hold. To prove a conclusion from assumptions, a refutation method adds its negation and searches for such a contradiction. In first-order logic, unification determines which terms can instantiate matching predicates. A procedure that eventually finds every valid proof need not terminate on every invalid claim: this distinction explains why proof search and proof checking have different computational costs.
Candidate generation produces a manageable set of possible answers before a more expensive scoring or verification stage. In a recommender system, retrieving a few hundred items from millions lets a detailed ranking model examine each candidate. Candidates may come from several retrieval rules; their union can combine recent, popular and personally relevant items.[ref]
One mechanism represents a query by a vector and each item by a vector , then retrieves large inner products using nearest neighbor search. If the vectors have unit Euclidean norm, maximizing also minimizes . Without normalization those rankings need not agree. A candidate omitted here cannot be restored by a later stage that only reorders the retrieved set, so retrieval coverage and computational cost must be assessed together.
Computing or comparing sequences of actions using representations of their expected consequences and relevant constraints. A plan can be revised after a goal, transition or inferred state changes. Planning is distinct from merely evaluating one fixed control policy or repeating a cached response.
An internal model of relationships among states, actions, observations and outcomes, used to predict consequences or support inference. It can be incomplete and task-specific. Planning through a mistaken model can produce confident errors, so model accuracy and the choice of abstraction are part of intelligent control.
Approaches combining learned neural representations or computations with explicit structured representations and reasoning. A useful account specifies the interface, uncertainty and learning responsibilities of the components rather than assuming their combination automatically supplies general intelligence.
The problem of connecting internal symbols to what they designate in perception, action or other meaningful relations. Supplying an intelligent agent with perfectly identified objects and relations can conceal this problem rather than solve it.
Computation over quantities such as distributed activation patterns and learned weights, without requiring every meaningful entity to occupy a separate explicit token. Neural networks are common examples. A distributed implementation can nevertheless learn or implement structured operations.
Computation using explicitly structured representations whose elements have identifiable roles, with rules or procedures acting on those structures. Logical planning is an example. This sense concerns symbolic cognitive architectures rather than only computer algebra; it can be implemented by different physical substrates.
A proposal that structured symbolic representation and manipulation provide a basis for general intelligent action. It is a claim about computation to be evaluated empirically, rather than a mathematical theorem equating every particular symbolic program with intelligence.[ref]
Computer science as empirical inquiry: symbols and search by Allen Newell and others. Communications of the ACM 19, pp. 113–126, physical symbol systems and search
A system that uses observations and internal information to choose actions in an environment in pursuit of specified or learned objectives. Assessing intelligence requires stating the tasks, available experience, uncertainty and resource constraints; a useful internal representation is part of the problem, not automatically supplied by the environment.
A fact whose truth can change as actions execute in automated planning. Ground location facts and an empty-container marker are examples. In STRIPS, static facts such as an object's fixed type are never added or deleted, while planning fluents can appear in action effects.
A representation for automated planning in which a state is a set of true ground facts and an action has a positive precondition set , add set and delete set . Under the closed-world assumption, facts absent from are false. The action applies when and producesNegative effects are delete-list entries; they do not require negative preconditions. A movement action must delete an object's old location as well as add its destination. Capacity and safety restrictions require explicit action conditions or auxiliary planning fluents; they do not follow automatically from an intended physical interpretation.
Automated planning with ground actions that are always applicable because their precondition sets are empty. Delete effects are still permitted, so taking the union of all add effects does not decide reachability. With a positive conjunctive goal, the last-achiever algorithm for precondition-free planning gives a polynomial-time algorithm.
Start with required facts . If , the empty prefix suffices. Otherwise choose an action adding a member of and deleting none of , record it as a final action, and remove its add effects from . Repeat and reverse the recorded actions when the residual requirements hold initially. Reject if no permitted action exists.
Soundness follows because each recorded last action supplies its removed requirements without deleting the remaining ones. If a plan satisfies a residual not contained in , its last action affecting cannot delete an -fact and must add one; therefore a candidate exists. Any selected candidate leaves a smaller required set, which is no harder to achieve than . This proves completeness by mathematical induction. Every selection removes a required fact, so there are at most selections and a scan of all effect lists at each step gives polynomial time.
A parameterized action definition with typed parameters, preconditions, add effects and delete effects. Replacing its parameters by type-correct objects yields a ground action. Type restrictions and static inequalities can remove invalid instantiations before the action is considered by a search algorithm or SATPlan.
An action with no unbound object variables. Its precondition and effect sets consist of fixed ground facts. Action grounding an action schema over a finite object universe creates one candidate action for each type-correct parameter tuple, after any static filtering; a time-indexed encoding then creates copies or variables for individual action occurrences.
Substituting object names for all parameters in an action schema, retaining the type-correct tuples and any required static restrictions. The result is a collection of ground actions.
A predicate whose ground facts are unchanged by every action in a planning model. Object types and a fixed adjacency relation are common examples. Static conditions can filter ground actions before search; they need not acquire a separate truth variable at every time layer. A planning fluent can instead be added or deleted by actions.
Constructing a sequence of actions whose successive applications transform a specified initial state into one satisfying a goal. The formal model must specify action preconditions, state changes and the meaning of facts absent from a state. STRIPS represents changes by add and delete lists; planning state invariants explain which physical properties the action definitions preserve.
In deterministic classical planning, a finite sequence of actions applicable successively from the initial state and ending in a state satisfying the goal. A STRIPS plan must respect every action's precondition set and both add and delete effects. A numerical bound on a possible plan's cost does not itself specify the action sequence.
Automated planning with several possible successors for an action and no specified probabilities for choosing between them. A plan must say how to act after observed outcomes. A strong plan guarantees eventual success for every possible outcome history; a favorable outcome on just one branch does not establish that guarantee.
A plan or policy that reaches a goal after finitely many steps under every permitted outcome sequence. In a finite state space with finite outcome sets, a terminating finitely branching plan tree has bounded depth. Strong planning winning-set iteration constructs exactly the states from which such finite guaranteed-success plans exist. A repeated state cannot be accepted merely because repeated attempts might eventually succeed: without a fairness or probability assumption, an unfavorable outcome can recur forever.
For a finite nondeterministic planning problem with goal set , initialize and putA state in has a strong plan reaching within steps. The proof is mathematical induction: an action witnessing admission to has only successors with plans of depth at most . Conversely, the first action of any guaranteed plan of depth has every successor in , again by mathematical induction. Since only grows inside a finite state space, the iteration stabilizes after at most the number of states many strict expansions. Recording a witnessing action at first admission gives a policy whose rank decreases at every nonterminal step.
Automated planning whose result may branch on information revealed during execution. In partially observable search, an AND-OR search chooses an action at each OR node and requires a continuation for each possible observation at its AND branches. A contingent plan can therefore be a conditional tree or a policy on belief states, rather than one fixed action sequence.
Automated planning with a completely specified initial state, deterministic actions and a goal condition. A finite STRIPS model is a common representation. A plan is an action sequence applicable from the initial state, ending in a goal state. Unknown facts about the initial world require an epistemic representation such as a belief state, rather than silently interpreting every unlisted fact as false.
Two subgoals interact when actions needed for one can establish, obstruct or delete facts needed for the other. A plan for each subgoal separately need not combine into a plan for their conjunction. Preparing the world before committing to a subgoal, revising an earlier subplan or temporarily undoing an achieved fact can all be necessary. Goal-by-goal planning may therefore be incomplete.
The Sussman anomaly is a blocks world example in which independently constructing the obvious subplans for two stacking goals gives destructive goal interaction in planning. Clearing a block in advance allows a short joint plan, while prematurely achieving either isolated goal can block the other. It demonstrates the inadequacy of restricted goal-by-goal planning, rather than a prohibition on every possible ordering of final goal achievements. Preparatory actions can make such an ordering succeed. For a concrete instance, start with on and on the table, and require on and on . Moving to the table, then onto , then onto succeeds. The first move is preparation that an isolated shortest subplan for the second stacking goal would omit.
A restricted goal-by-goal planning procedure chooses one subgoal, constructs a subplan for it without preparation motivated by other pending subgoals, then moves on while treating the earlier goal as protected. Destructive goal interaction in planning can defeat either ordering. Merely requiring the final plan to be a concatenation of subplans is a weaker condition: a subplan may already contain preparatory work useful to a later goal. A claimed impossibility must specify the stronger restriction rather than infer it from concatenation alone.
The blocks world is a classical planning model of movable blocks arranged in stacks on an unlimited table. Each block has one support, each block supports at most one other block, and the support relation has no directed cycle. A clear block can move onto another clear block or onto the table. In a direct-transfer STRIPS representation, an action includes the entire pickup-and-placement operation; a separate holding or empty-hand planning fluent is unnecessary unless the action model explicitly splits those operations.
The table has unlimited capacity, so its availability must not be deleted when a block is placed there. Planning state invariants connect the predicate describing a clear block to the absence of any block directly above it. Goal interaction in planning makes this small model useful for testing automated planning methods.
For a positive conjunctive goal , an action with can serve as the final step. Before it executes, the remaining goals and its preconditions must hold, giving the displayed regressed set. For precondition-free STRIPS planning, only deletion of already supplied requirements remains.
A condition specifying when a fact remains unchanged by an action. In STRIPS, facts outside the add and delete lists persist. A successor-state axiom combines these persistence conditions with all action effects that can change the fact.
A logical equivalence characterizing exactly when a planning fluent is true after one step. Here and are disjunctions of selected actions with the respective effects, under a suitable action-conflict policy. The persistence term excludes spontaneous changes and captures the relevant frame axiom. An implication from add effects alone would not constrain all other state changes.
An approach to automated planning that constructs a Boolean satisfiability problem for a bounded planning horizon, solves it and decodes a satisfying assignment into a plan. A typical encoding has time-indexed action occurrences and planning fluents, initial and goal clauses, action precondition axioms, state-transition constraints and action exclusion axioms. Sequential and parallel encodings have different notions of a step.
Henry Kautz and Bart Selman introduced planning as satisfiability in their 1992 paper.[ref]
Planning as satisfiability by Henry Kautz and Bart Selman. ECAI 1992, pp. 359–363; publication listed in the author's Cornell bibliography
A sequential SATPlan encoding has a complete initial assignment of planning fluents, final goal constraints, action precondition axioms, successor-state axioms and action exclusion axioms allowing at most one action per layer. Zero selected actions is an idle step: the successor-state axioms preserve all facts. This encodes an upper bound on plan length rather than forcing exactly physical actions.
For soundness, read selected ground actions in layer order. The initial assignment is the real initial state. By mathematical induction, each selected action has its preconditions in the current state and the successor-state axioms give precisely its add/delete update; an empty layer leaves that state unchanged. The final goal constraint therefore proves that the decoded plan succeeds. Conversely, take any plan of length at most , assign its actual state trajectory to the fluent variables, select its actions in successive layers and pad with idle layers. All encoding components hold. Complete initial negations and persistence conditions are essential: omitting either can introduce unsupported facts and spurious plans.
A condition forbidding a conflicting pair of action occurrences in one layer. A serial SATPlan encoding excludes every distinct pair; parallel encodings exclude the pairs disallowed by their concurrency semantics. Excluding two simultaneous pickups can enforce a one-hand resource restriction even if both individual precondition sets hold.
A clause or formula ensuring a selected action occurrence has all of its preconditions satisfied at the current time. It is one part of a plan encoding; action effects, persistence, initial conditions and goals require additional constraints.
The number of action layers allowed in a bounded automated planning encoding. Sequential layers permit at most one physical action, while a parallel semantics may permit several compatible actions. A sufficiently large horizon guarantees finding a solution only for a solvable input; shorter plans require idle layers or testing the successive smaller horizons.
Expand a concrete state by applying every action whose preconditions hold, and search the resulting state graph for a goal. For STRIPS, the successor is . A valid expansion checks the complete precondition set, including resource markers such as an empty hand, rather than only an action's geometric destination.
Machine learning develops algorithms that use data or experience to improve performance on a specified task. The task, the experience available to the algorithm and the performance criterion must all be stated. A statistical classification system might learn from labelled training data; an unsupervised learning method instead looks for structure without those labels.[ref]
For example, a linear regression model can learn coefficients predicting a numerical outcome from measured inputs. Minimizing its error on the training data determines a fitted model, but does not establish how well it predicts new observations. A separate test set estimates performance on data withheld from fitting. Overfitting occurs when fitting peculiarities of the training data impairs this generalization; data leakage can make the evaluation misleading.[ref]
Statistical learning supplies tools for reasoning about these prediction and uncertainty questions. A useful learned model is therefore assessed through an explicit task and evaluation, alongside the running time and other resources needed to train and use it.
A generative model describes how observations can be produced. It can specify a probability distribution explicitly, or provide a procedure that generates samples whose distribution is determined by parameters . Producing observations and assigning a tractable numerical probability to every observation are separate capabilities.
An original two-bit example defines a joint probability distribution through conditional probabilities. LetGenerate first, then generate using the applicable conditional probability. The four possible outputs have probabilitieswhich sum to one. The procedure generates both complete observations and a dependence between their components. Always outputting the most probable observation,
11, would produce a different distribution: it would discard all the other outcomes rather than sample the stipulated model.A generative adversarial network gives a different implementation. A generator transforms an input random variable into a candidate observation, while a discriminator supplies a training signal by distinguishing generated samples from training examples. The original paper develops this as an adversarial learning procedure.[ref]
Generative Adversarial Nets by Ian Goodfellow and others. Abstract and §2, generator/discriminator framework and sample generation
The model's samples must be assessed against the intended distribution or task. A visually plausible observation alone does not establish that the model represents the full range of observations well; distributional coverage and the probability of different outcomes matter alongside individual sample appearance.
PyTorch is a software framework for numerical tensor operations and machine learning, including automatic differentiation and tools for training neural networks. Its array operations provide the calculations; its differentiation machinery records how a result depends on selected inputs. A computed gradient is distinct from the later optimization step that uses it.[ref]
Automatic Differentiation with torch.autograd in the PyTorch tutorials. Tensors, Functions and Computational graph; Computing Gradients
import torch
x = torch.tensor(2.0, requires_grad=True)
y = x * x + 3 * x
y.backward()
print(x.grad)  # tensor(7.)
The result agrees with . The call to
backward() computes and accumulates derivatives; it does not itself change x to minimize y. In a training loop, parameter updates and clearing old gradients are separate operations.[ref]Optimizing Model Parameters in the PyTorch tutorials. Optimizing with torch.optim; zero_grad, backward and step
A useful consequence of its dynamically constructed computation is that executed control flow determines the recorded graph. Recording a new graph on the next execution makes it possible to differentiate the computation that actually ran. Disabling gradient tracking or detaching a value changes that connection and must be deliberate.[ref]
Automatic Differentiation with torch.autograd in the PyTorch tutorials. More on Computational Graphs; Disabling Gradient Tracking
A feature is an input attribute or computed representation used by a machine learning system. An example can be represented by a vector whose coordinates are individual feature values; a design matrix commonly places examples in rows and these coordinates in columns. A feature can be measured directly or derived from other measurements.[ref]
Deep Learning by Ian Goodfellow and others. §§5.1.1 and5.1.3, example vectors, features and design matrices
For example, classifying manufactured parts might use measured length and width as two feature inputs. Their ratio is another possible feature, exposing a shape relationship to a simple model. Choosing a representation changes which rules are easy to learn. A variable available only after the desired prediction time can introduce data leakage, while a distributed representation can learn useful coordinates without assigning each one a human-readable meaning.
A distributed representation encodes an object through a pattern across several components, with each component reusable across many objects. In contrast to allocating a separate indicator to every object, shared components let related objects share information. For example, three binary attributes can encode eight combinations even though there are only three coordinates.
In machine learning, the coordinates are often learned real-valued features rather than named attributes. A word embedding can encode several aspects of word usage in one vector; no single coordinate needs to have a simple human interpretation. Combinatorial capacity alone does not guarantee useful learning: the training objective must make the representation's geometry relevant to the task.[ref]
Deep Learning by Ian Goodfellow and others. Chapter 15, §15.4, distributed representations
Representation learning learns a transformation of observations into features that make a subsequent task easier. Writing and a prediction as separates the learned representation from the predictor; training may optimize both together. The objective can come from supervised learning or unsupervised learning.
For example, a neural network trained to classify images can learn edge-like and shape-sensitive features instead of receiving a fixed list of hand-measured quantities. The representation can sometimes be reused on a second task with fewer labeled examples. Such transfer is a hypothesis to evaluate: information useful for the original task can omit a distinction essential to the next. A distributed representation describes how information is encoded; representation learning describes how the encoding is obtained.[ref]
Deep Learning by Ian Goodfellow and others. Chapter 15, opening discussion and transfer learning
A neural language model uses a neural network to assign a probability distribution to language sequences. An autoregressive model factorizes the probability of words asTraining by maximum likelihood estimation rewards the observed next words; generation repeatedly samples from the conditional distribution. If a two-word sequence has first-word probability and conditional second-word probability , its joint probability is .
Yoshua Bengio and coauthors' 2003 model jointly learned a distributed representation of words and a neural probability predictor. Sharing representation parameters allowed similar contexts to inform one another, rather than treating every observed word sequence as an unrelated event.[ref]
A Neural Probabilistic Language Model by Yoshua Bengio and others. abstract and §2, model architecture
A word embedding represents a word by a vector, usually learned so that relationships in the data become useful relationships between vectors. A vocabulary of words can be stored as a matrix with rows and columns: selecting a word selects one row. Unlike a separate indicator for each word, a dense representation can share predictive information across words.
For example, training a neural language model can place words occurring in similar contexts near one another, making evidence about “cat” useful when predicting contexts involving “dog”. This is statistical similarity, not a guarantee of synonymy: opposite words can occur in similar contexts too. The 2003 neural probabilistic model learned these vectors jointly with next-word probabilities.[ref]
A Neural Probabilistic Language Model by Yoshua Bengio and others. abstract and §2, shared word-feature matrix
In online learning, a learner chooses before observing the round's loss function . Its external cumulative regret against a fixed action set isNo-regret learning seeks a guarantee , often in expectation for a randomized algorithm, under stated feedback and adversary assumptions. The average excess loss then tends to zero. The comparator is the best single action in hindsight; it does not choose the best action separately on every round.
For example, against two prediction rules, an exponential-weights learner starts with equal weights and multiplies rule 's weight by after seeing all rule losses. Sampling in proportion to the weights gradually shifts probability toward better rules. For losses in , an appropriate learning rate gives an order- expected bound for this fixed two-rule setting. This compares performance even without independent observations from one fixed distribution; it does not guarantee small absolute loss when every rule predicts badly.
Computational learning theory studies what an algorithm can learn under an explicit observation model, accuracy requirement and resource bound. Sample complexity measures how much information is needed; time complexity measures the computation used to turn it into a predictor. A class can admit statistically sufficient samples while presenting a difficult computational Search problem.
In realizable probably approximately correct learning, labelled examples are sampled independently from a fixed but unknown distribution and some hypothesis in the class labels them perfectly. The learner must return a hypothesis whose true error is at most with probability at least . For a finite class , any consistent learner satisfies this guarantee whenIndeed, a fixed hypothesis with error greater than matches all examples with probability at most ; a union bound over proves the claim. The argument bounds information requirements, but does not supply an efficient method for finding a consistent hypothesis.
Sample complexity is the number of training observations needed for a specified learning guarantee. It depends on the allowed prediction error , failure probability , the hypothesis class and assumptions about data generation. It counts observations, whereas computational complexity theory measures the work of processing them.
For a finite class containing the true binary labeling rule, suppose examples are independent and identically distributed. A fixed hypothesis with error greater than fits examples with probability at most . The union bound makes the probability that any such bad hypothesis fits at most . Thus any consistent learner succeeds with probability at least whenThe derivation assumes realizability and establishes an information guarantee; it does not give an efficient search for a consistent hypothesis.
Probably approximately correct learning formalizes learning as a two-parameter guarantee. With probability at least over the training random sample and any learner randomness, the returned hypothesis must have true prediction error at most . In the realizable distribution-free setting, this must hold for every input probability distribution and every target in the specified concept class, using an appropriate polynomial number of examples; efficient PAC learning also requires polynomial running time.
“Probably” refers to the chance of obtaining a good hypothesis; “approximately” refers to that hypothesis's error on a fresh observation. For example, and require a 95% chance of returning a predictor whose error is at most 1%, rather than a claim that 95% of individual predictions are right. For finite realizable classes, the sample complexity bound follows by excluding every high-error rule that could have survived the observations.[ref]
Learning with multiple stages of representation, typically implemented by a neural network. Depth, connectivity, objective, training experience and parameter sharing are distinct design choices; a deep architecture need not be convolutional or supervised.
A generative adversarial network trains a generator to produce samples and a discriminator to distinguish generated samples from training data. The original objective is the minimax problemThe discriminator improves at detecting fakes; the generator improves at fooling it. Both can be neural networks trained by backpropagation.[ref]
For a toy dataset containing two equally frequent types of images, always producing one type gives the discriminator an exploitable imbalance even if each generated image looks plausible. Under the paper's ideal unrestricted-function analysis, the equilibrium matches the data probability distribution and gives . This ideal result does not ensure convergence for finite networks and alternating numerical updates. Ian Goodfellow and coauthors introduced the framework in 2014.[ref]
Generative Adversarial Nets by Ian Goodfellow and others. §4, optimal discriminator and global optimum
Assignment of observations to categories using measured features and a statistical rule. In geological remote sensing, features can be multispectral pixel values or derived spectral reflectance ratios; known field samples provide training labels and independent observations assess errors. Classification boundaries need not coincide with lithological contacts when illumination or cover dominates the signal.
Within-observer agreement versus reference agreement distinguishes consistency of an observer's repeated labels from concordance with a separately defined reference. The first asks whether the observer repeats a decision; the second asks whether that decision matches the comparison standard. In statistical classification, neither quantity can replace the other.
For cases, let and be one observer's labels at two readings, and the reference label. Define the two empirical agreement fractionsAn original binary example has 100 cases, half reference-positive and half reference-negative. An observer reverses every reference label and repeats that reversal on the second reading. Then while . Perfect repeat agreement can coexist with complete reference disagreement. An observer always assigning the negative label also has perfect repeat agreement, but only 50 percent reference agreement in this balanced example.
A confusion matrix shows which categories contribute to disagreement, whereas a single overall percentage can conceal systematic shifts or an imbalanced case mix. Reference agreement is classification accuracy relative to that reference, not proof that the reference is infallible. A consensus panel, a later outcome and an independent molecular test answer different validation questions.
A primary 2017 study made this distinction experimentally by having pathologists interpret skin-biopsy sets twice, at least eight months apart, and comparing their interpretations with an experienced consensus reference. The study started with 240 cases and reported reproducibility separately from reference concordance.[ref]
Pathologists' diagnosis of invasive melanoma and melanocytic proliferations: observer accuracy and reproducibility study by Joann G. Elmore and others. BMJ 357, j2813, Abstract, Participants and outcome definitions
The delayed repeat reduced immediate recall, but did not transform repeated judgments into independent biological truths.A useful evaluation preserves case identity, reading order and the exact reference procedure. If a machine learning classifier learns an observer's systematically shifted labels, it may reproduce that observer well while disagreeing with the external reference. Reporting both comparisons makes that limitation visible. Uncertainty estimates should also account for repeated cases and multiple readings rather than counting every label as an independent subject.
Probability calibration means that reported probabilities agree with the frequencies of the outcomes they describe. For binary classification, let be the true label and let be the predicted positive-class probability. Population calibration is the conditional expectation conditionAmong cases receiving a value near , the positive fraction should therefore be near , with uncertainty in any finite sample.[ref]
Probability calibration in the scikit-learn documentation. Opening definition and section 1.16.1: binary probabilities and observed positive fractions
A simple example separates calibration from discrimination. Suppose the population has a positive fraction of and a predictor always reports . Then , so it is calibrated, although it cannot rank one case above another. Conversely, replacing a useful score by a strictly increasing transformation such as preserves ranking but generally changes the claimed probability. Thus ordering cases and attaching reliable numerical probabilities are different tasks.
A reliability diagram estimates the agreement by grouping predictions and comparing each group's mean prediction with its observed outcomes. Assess it using suitable held-out observations. A calibrator fitted to predictions on the same observations used to fit the original model can inherit an overly optimistic picture of performance; fitting and evaluation need appropriate separation.[ref]
A 2017 study found substantial confidence miscalibration in the evaluated neural networks, even when prediction accuracy improved. It also tested temperature scaling as a compact post-processing adjustment. These were empirical results on specified models and datasets, rather than a theorem that all neural networks are miscalibrated.[ref]
On Calibration of Modern Neural Networks by Chuan Guo and others. Figure 1 and sections 3–4: experimental comparisons and calibration methods
Expected calibration error summarizes how reported confidence differs from observed correctness. For top-label statistical classification, the population quantity compares correctness probability conditional on confidence with that confidence. A commonly reported finite-sample estimate groups predictions into confidence intervals and compares the mean confidence and accuracy in each interval.[ref]
On Calibration of Modern Neural Networks by Chuan Guo and others. §2, Eqs. (2)–(3), population calibration gap and binned estimate
For a nonempty bin among predictions, defineHere is confidence in the selected class, not its numerical label. The empirical statistic isEmpty bins have zero weight and need no undefined bin average. The cited paper uses equal-width bins.[ref]
On Calibration of Modern Neural Networks by Chuan Guo and others. §2, bin definitions and Eq. (3), printed pp.1322–1323
A synthetic example shows why the partition matters. Four predictions have confidences and correctness indicators . With one bin, accuracy and mean confidence are both , so the estimate is zero. With four equal-width bins on , only the last two are populated. Their accuracy/confidence pairs are and , each with half the observations. ThusThis is ten percentage points, despite unchanged predictions and labels.
A zero coarse-bin result can conceal opposing gaps; it does not establish perfect probability calibration or agreement within every subgroup. Report bin boundaries, sample size, confidence convention and scale. Reliability diagrams reveal where the gaps occur, while a scalar expected calibration error supplies their sample-weighted summary. It is distinct from the fraction of incorrect classifications.
Temperature scaling is a method of probability calibration that divides a model's neural network logits by one fitted positive scalar before applying the softmax function. The temperature is selected after model training, using labels in a held-out validation set to minimize the negative log-likelihood. It adjusts reported probabilities without retraining all model weights.[ref]
On Calibration of Modern Neural Networks by Chuan Guo and others. §4.2, Eq. (9), scalar temperature and validation negative log likelihood
For class scores and ,For the synthetic two-class scores , the first-class probability isThe selected class remains the first while its reported confidence decreases.
The preservation of the selected class follows directly: dividing by positive preserves every score ordering and equality, and exponentiation is strictly increasing. Thus the set of classes attaining the largest score is unchanged. This concerns ordering between classes within one example; it does not assert preservation of confidence ordering between different examples.
A motivating measurement in the original study compares reliability diagrams for a 110-layer image-classification network. Its reported expected calibration error changes from before calibration to after temperature scaling. This is a result for that experimental setup and binned metric, not a guarantee for every classifier or input distribution.[ref]
On Calibration of Modern Neural Networks by Chuan Guo and others. §5 and Fig. 4, CIFAR-100 ResNet-110 before/after reliability diagrams
Use separate data for fitting the temperature and for final evaluation. One scalar can improve an overall confidence mismatch but cannot represent every class-specific or input-dependent error. The name refers to this probability transformation; no physical temperature is being measured.
A reliability diagram compares predicted probabilities with observed outcome frequencies to assess probability calibration. For the positive-class version of binary classification, partition observations into bins according to their predicted probabilities . For every nonempty bin, plotwhere is for a positive outcome and otherwise. Agreement places the estimated points near the diagonal . Empty bins have no observed fraction and should not be plotted as zero.[ref]
Probability calibration in the scikit-learn documentation. Section 1.16.1: mean predicted probabilities and fractions of positives
Binning can hide important structure. Consider ten cases each assigned , of which eight are positive, and ten cases each assigned , of which two are positive. Separate bins give and , revealing strong disagreement. Merge all 20 cases into one bin: the mean prediction becomes and the positive fraction is . The single point lies on the diagonal despite the two-group discrepancy.
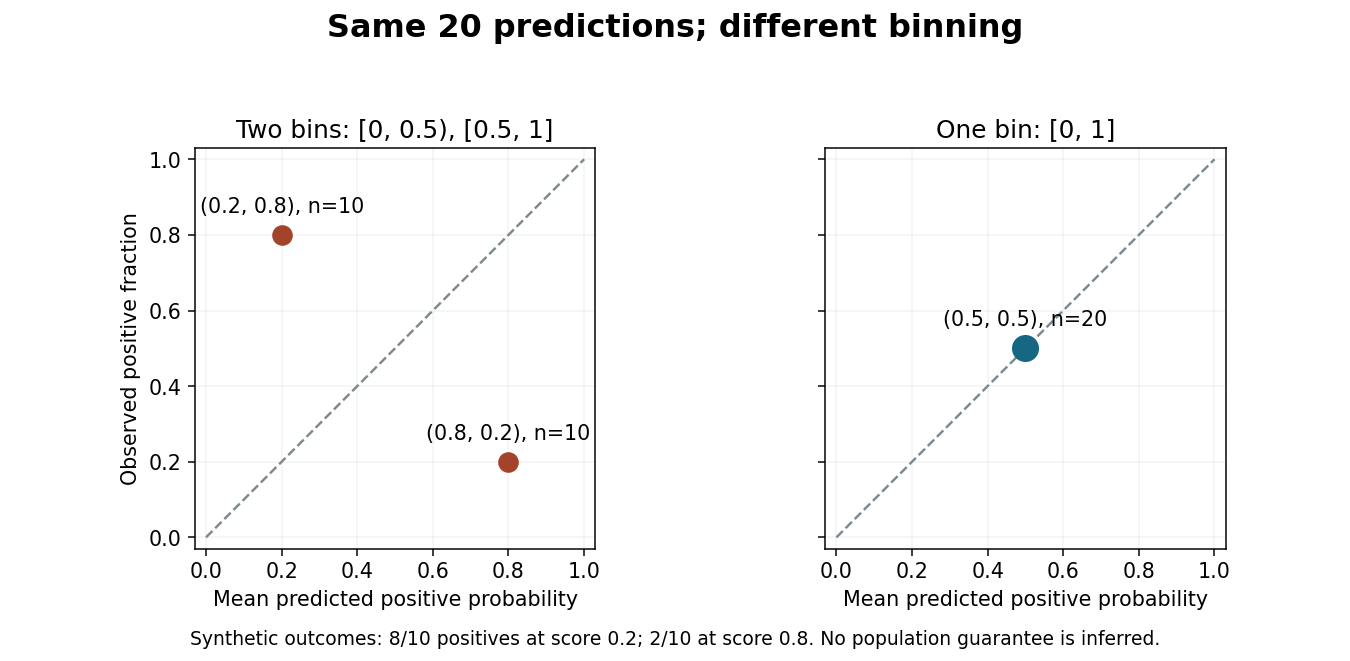
Merging bins can hide disagreement in a reliability diagram.
Original synthetic binary classification example with the same 20 predictions and outcomes in both panels. Points show positive-class frequencies; the diagram does not establish a population guarantee. Details.Report bin definitions and counts, since a point based on ten cases has different sampling uncertainty from one based on thousands. Some classification diagrams instead plot confidence in the selected label against the fraction of correct selections. That convention and the positive-class version answer related but distinct questions, so label the axes and the meaning of the outcome explicitly.[ref]
On Calibration of Modern Neural Networks by Chuan Guo and others. Section 2: selected-label accuracy/confidence convention and limitations of a reliability diagram without bin populations
A confidence score is a numerical output used to express how strongly a system supports a prediction, particularly in statistical classification. Its meaning depends on the system: it may be an estimated probability, a distance from a decision boundary, or another score whose ordering is useful. A number between zero and one does not by itself establish a probability interpretation. Probability calibration concerns whether predicted probabilities agree with observed frequencies.[ref]
Probability calibration in the scikit-learn documentation. §1.16, opening explanation of calibrated classifiers and predict_proba versus decision_function
Consider a synthetic binary statistical classification example. Among independent test cases assigned a positive-class score near , suppose actually belong to that class. Their observed fraction agrees with the average predicted probability. If only belong to the positive class, the same scores overstate the observed positive frequency in this group. A reliability diagram groups predictions by their estimated probability and compares each group's mean prediction with its observed positive fraction. Finite groups have sampling variation, so agreement in one group is evidence to assess with its sample size, rather than a guarantee about each case.[ref]
Probability calibration in the scikit-learn documentation. §1.16.1, Calibration curves: binning, average predicted probabilities and fractions of positives
Ordering and probability calibration answer different questions. For scores in , replacing every score by preserves their order but changes to . Thus an unchanged ranking can accompany very different probability statements. Conversely, a system assigning the overall positive fraction to every case can have useful aggregate probability calibration while failing to distinguish cases.
A confidence score can support a threshold for accepting a prediction or passing it to another process. Select and assess that threshold using examples separate from model fitting and representative of the intended inputs. A threshold does not establish its own error rate; observations on suitable test data supply that evidence. Distinguish a positive-class probability from the score of whichever class was selected: they are different quantities when the selected class changes.
Discriminant analysis constructs statistical rules distinguishing labelled classes from their measured feature values. A common generative approach models the class-conditional probability distribution and applies Bayes' theorem to compare posterior class probabilities. Linear discriminant analysis uses multivariate normal distributions with a shared covariance matrix; allowing a different covariance matrix for each class gives quadratic discriminant analysis.[ref]
Linear and Quadratic Discriminant Analysis in the scikit-learn documentation. §1.2.2, probabilistic model and shared-covariance simplification
For two equally likely one-dimensional classes, suppose and . Their log-likelihood ratio isChoosing the larger posterior therefore selects for , with a tie at one. Different class probabilities move this threshold. Estimating means and covariance from training data supplies a fitted rule, while independent evaluation tests whether its assumptions generalize.
For a binary classifier, the conditional probability of the target condition given a positive classification. If its base rate is , its true-positive probability is , and its false-positive probability is , Bayes' theorem gives . The denominator is positive whenever a positive classification can occur.
Articles by others on the same topic

AI-related lessons can introduce machine learning fundamentals, generative AI, prompt engineering, and intelligent applications. Students can explore these topics through guided activities and suitable projects.

Artificial Intelligence (AI) refers to the simulation of human intelligence processes by machines, particularly computer systems. These processes include learning (the acquisition of information and rules for using it), reasoning (using rules to reach approximate or definite conclusions), and self-correction. AI can be categorized into different types and subfields: 1. **Narrow AI (Weak AI)**: This form of AI is designed and trained for a specific task, such as facial recognition, language translation, or playing chess.

