Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Probability density
Take nonrelativistic quantum mechanics, a short-range interaction, a fixed heavy target, and a common projectile mass . An incoming plane wave in atomic state has unit coefficient. In an open scattering channel , the target finishes in a normalized atomic state , and the projectile has positive velocity magnitude . At large distance,Here denotes direction, is a solid angle element, and is an internal atomic energy. Different are orthogonal. The scattering amplitude has units of length. A closed scattering channel has no propagating outgoing probability current at this total energy.
The incoming probability current density is . The outgoing radial probability current density in channel is . Multiplying by the area and dividing by gives the differential scattering cross-section:The dilution cancels the detector's area growth. The velocity ratio remains: a squared wave coefficient alone is not generally a flux fraction. A differential scattering cross-section has units of area per solid angle, rather than being a normalized directional probability density. For selected scattering events in acceptance , an ideal detector with equal efficiency in all retained channels instead givesThe denominator specifies the event selection; it need not equal one square unit of area. Absolute rates require incident flux, target number and detector efficiency in addition to these relative weights. The next finite-mode model normalizes outgoing probability current to one incoming event and predicts event fractions directly.
Antibonding orbital Created 2026-10-14 Updated 2026-10-20
Occupying an antibonding molecular orbital opposes a chemical bond. For equivalent atomic orbitals of the hydrogen atom, the difference vanishes on the plane halfway between the protons: every point there is equally far from both centres, so the amplitudes cancel. This nodal plane removes the contribution of this molecular orbital to electron density on that plane; it does not make an entire finite region empty. The -derived antibonding molecular orbital lies above its bonding molecular orbital partner in energy. See Field, MIT 5.61, lecture 25, pp. 1–2.
In the minimal model, adds and cancels the bond order contribution of . Opposite signs on the two lobes describe probability amplitudes, while both lobes have nonnegative probability density after squaring. The star is an orbital label, not an extra electron or an electric charge.
Let and be the quantum harmonic oscillator ground-state probability density. Put . The first excited-state density is . Integration by parts, using , gives the first-order differenceThe bracket grows from zero to one, since its derivative is . Thus the first-order predicted level gap for is . For every it becomes negative at sufficiently large .
For the full potential has a central barrier and symmetric minima at . The unperturbed even ground state samples the central barrier more strongly than the odd excited state, whose node reduces its shift. This explains the perturbative tendency, but the negative predicted gap is a failure diagnostic of the first-order truncation. The exact one-dimensional ground state remains nodeless and below the first excited state; in a high symmetric barrier the actual pair has a small positive double-well tunneling splitting.
Atomic orbital Created 2026-10-13 Updated 2026-10-20
An atomic orbital is a one-electron spatial wavefunction used to describe an electron's state in a chemical atom. For a one-electron hydrogen atom, orbitals can be exact energy eigenstates; descriptions of many-electron atoms instead use an orbital approximation. A normalized atomic orbital has , and the Born rule gives the position probability density . It is a function extending through space, not a prescribed classical orbit. [ref]
https://openstax.org/books/chemistry-2e/pages/6-3-development-of-quantum-theory. Flowers et al., Chemistry 2e, 6.3: atomic orbitals and the wavefunction description
The linear combination of atomic orbitals combines these single-centre functions to approximate a molecular orbital. The orbital overlap measures their inner product, and their relative quantum phase controls the interference shown in molecular orbital theory.
Atomic-orbital nodal plane 2026-10-20
A plane on which an atomic orbital wavefunction vanishes. For a real p orbital oriented along , it is the plane . The probability density also vanishes on that plane.
Barton Zwiebach Created 2026-10-13 Updated 2026-11-05
Barton Zwiebach's quantum-physics teaching derives probability current from the Schrödinger equation. Comparing the equation with its complex conjugate converts change of local probability density into the divergence of a flux. A wavefunction's spatial phase therefore determines motion that its magnitude alone does not reveal. The derivation connects a complex amplitude with conservation of total probability when no flux escapes through the boundary.[ref]

Portrait of Barton Zwiebach
. Lubos Motl (Lumidek). Public domain (released worldwide by author Lumidek). Source usage terms, via Wikimedia Commons. Source.
Bonding orbital Created 2026-10-14 Updated 2026-10-20
Occupying a bonding molecular orbital favours a chemical bond. For the two equivalent atomic orbitals of the hydrogen atom, the sum has constructive interference between the protons. The resulting electron density in that region helps stabilize the combined system. Its lower energy in this model follows from the Quantum Hamiltonian, not from the plus sign alone; see Field, MIT 5.61, lecture 25, pp. 1–2.
For example, in molecular hydrogen supplies , hence bond order one when . The sum in the molecular orbital theory toy has midpoint probability density , whereas the difference has zero there. The normalization factors must be included in this comparison.
Born rule Created 2026-09-24 Updated 2026-10-18
The Born rule connects a quantum state to measurement probabilities. Let be a complete orthonormal basis, finite or countably infinite, for a Hilbert space, and letAn ideal measurement distinguishing these basis vectors returns label with probabilityThis assignment is a physical measurement rule. Its compatibility with total probability one follows from orthonormality and normalization:The probabilities are the squared moduli, not the amplitudes themselves or the squares . [ref].
If the basis is an eigenbasis of an observable, the reported numerical value is its eigenvalue. Several vectors can share one eigenvalue; the probability of that value is then the sum over the corresponding basis labels. More generally, a projective measurement with orthogonal projections assignsfor a pure state and a general density matrix , respectively. This also covers mixed states and degenerate eigenspaces. The Born rule determines outcome statistics; the ideal conditional state change is specified separately by the Lüders rule. See projective measurement for that formulation and its assumptions. [ref]
https://quantum.cloud.ibm.com/learning/en/courses/general-formulation-of-quantum-information/general-measurements/formulations-of-measurements. Watrous, IBM Quantum Learning, Mathematical formulations of measurements, Projective measurements
.For a worked example, take the normalized qubit quantum stateThe squared moduli add to . A computational-basis measurement, equivalently a measurement of the Pauli matrix, hasThese probabilities do not depend on the relative quantum phase . Now choose the Hadamard basiswhose vectors are eigenstates of the Pauli matrix, also used by the Pauli X gate. The new probability amplitudes and probabilities areBoth probabilities are nonnegative and their sum is one. The relative quantum phase becomes visible because the two probability amplitudes add before their squared modulus is taken:
- At , and .
- At , .
- At , and .
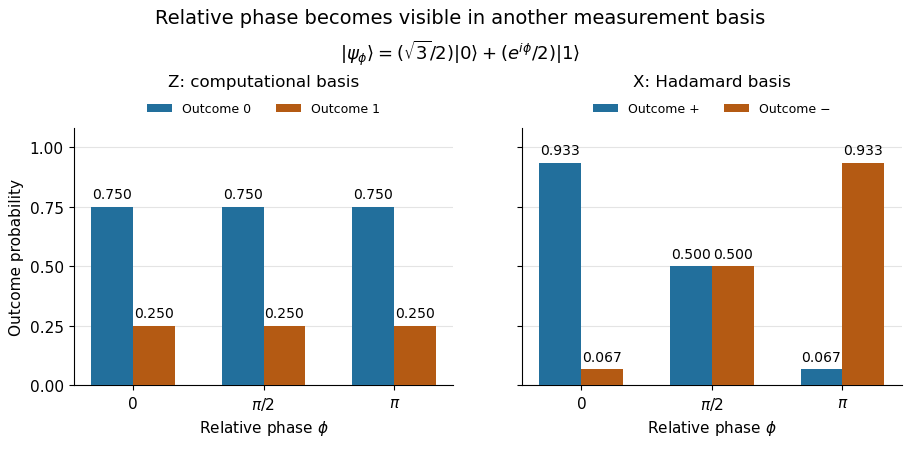
The same qubit preparation has phase-independent Z probabilities and phase-sensitive X probabilities
. Details. 
A Hadamard gate followed by a computational-basis measurement realizes these statistics, since , respectively. Compare the two bases using fresh, identically prepared copies: a preceding measurement may change the state. The quantum superposition section shows why replacing the preparation by the mixed state keeps the statistics but gives for every .
The usefulness of the Born rule is this conversion from linear algebra to experimental predictions: calculate overlaps in the basis actually measured, then take squared moduli. Its appealing geometry is that changing basis redistributes probability while preserving total squared norm. The same rule relates an energy eigenstate expansion to an energy measurement and a position wavefunction to a probability density.
Born's 1926 paper on quantum scattering interpreted the outgoing-wave coefficients in terms of the probabilities of collision outcomes; a corrective footnote specified proportionality to the square of the amplitude. This is a historical scattering formulation, rather than the general density matrix formula above. [ref]
Zur Quantenmechanik der Stoßvorgänge by Max Born. Born, Zur Quantenmechanik der Stoßvorgänge, Zeitschrift für Physik 37, 863–867, 1926
; [ref]https://www.neo-classical-physics.info/uploads/3/0/6/5/3065888/born_-_qm_for_collisions_i.pdf. English translation of Born's paper, p. 3 and footnote 1
. Bosonic coincidence enhancement in two orthogonal orbitals Created 2026-10-18 Updated 2026-11-05
Place one noninteracting spin-zero boson in each of two orthonormal orbitals . Its normalized symmetric spatial wavefunction is . At coincident positions the probability density is , twice the labelled distinguishable-product value. Coincidence at an exact point is understood as a density or the limit of small detector volumes. If both particles occupy the same orbital, the normalized product is already symmetric and this comparison gives factor one instead; the factor two is not a universal property of every two-boson state.
Cauchy approximate identity Created 2026-09-29 Updated 2026-10-03
The Cauchy approximate identity isIt is a probability density of total mass one, and its mass outside every fixed neighbourhood of zero tends to zero as . It therefore converges to the Dirac delta function as a distribution.
Change of variables for probability densities Created 2026-10-18 Updated 2026-11-05
For a random variable with probability density function on an interval, let , where is a diffeomorphism onto another interval. The change of variables formula givesIndeed, integrating the right-hand side over an outcome interval gives the probability that lies in its inverse image. The absolute derivative preserves positive probability when reverses orientation. A gravity deflection of an atomic beam is a physical example: its speed-to-height transformation changes the probability density and its mode.
Charles Alfred Coulson Created 2026-10-20 Updated 2026-11-05
A molecular orbital is a one-electron spatial wavefunction for the combined atomic nuclei of a molecule. For a normalized molecular orbital, the Born rule gives the position probability density , with . The molecular orbital is the amplitude, rather than its squared modulus or a classical trajectory.
Convolution of a Cauchy distribution and a uniform distribution Created 2026-10-18 Updated 2026-10-20
Let have the Standard Cauchy distribution and let , independently, have the uniform distribution on , where . The convolution of probability densities gives the probability density of asThis is an even function. Its derivative isso its unique mode is zero. Its tails satisfy as : multiplying the integral by makes the integrand converge uniformly to on the bounded interval . Consequently both positive and negative parts of the first moment diverge, so its expected value does not exist. The symmetric Cauchy principal value of that moment is zero, which is a different assertion. Adding a bounded independent displacement smooths the probability density without removing the divergent first moment of the Cauchy distribution.
de Broglie wavelength Created 2026-09-28 Updated 2026-10-14
The de Broglie wavelength is the distance over which a matter wave accumulates one full spatial quantum phase cycle in its propagation direction:Here is the Planck constant, is the momentum, and is the angular wavevector. The scalar in means the positive momentum magnitude, not a signed component. Reversing a momentum reverses the wavevector without making the wavelength negative. At zero momentum there is no finite spatial phase period: the limiting wavelength diverges.
This relation makes microscopic diffraction accessible with particles: increasing the momentum shortens the wavelength until it is comparable with the spacings in a crystal scattering problem. The electron accelerating-voltage wavelength gives a practical way to tune this scale, while the Davisson–Germer experiment tests it by comparing electron diffraction directions with independently known crystal geometry. The same relation applies to neutral particles in a neutron interferometer; electric charge is not a requirement for a matter wave.
The wavelength belongs to the wavefunction, not to a sinusoidal path of a particle. A free-particle momentum convention makes the distinction especially clear: a plane wave has a rotating complex quantum phase but a constant probability density. A localized wave packet contains a range of momenta and therefore generally has a range of wavelengths, rather than one exact spatial period.
Detlef Dürr Created 2026-10-24 Updated 2026-11-05
Detlef Dürr, Sheldon Goldstein and Nino Zanghì investigated how the usual quantum measurement rules arise in Bohmian mechanics, where a wave function guides a definite particle configuration. Their analysis connects quantum equilibrium, with configuration probability density , to the statistics of apparatus records. In this account, a self-adjoint operator summarizes a class of experimental procedures; its appearance does not require every quantum observable to be an additional pre-existing particle property.[ref]

Portrait of Detlef Dürr
. Via Wikimedia Commons; credits and usage information are on the linked source file page. Source.
The diagonal matrix element combines the equal-endpoint Euclidean oscillator path with its endpoint-independent Dirichlet oscillator fluctuation determinant. It is not itself a normalized probability density: its integral is the canonical partition function . The normalized position probability density isAt high temperature, the variance approaches as in the classical canonical ensemble. At zero temperature, it approaches , the ground state variance. Dividing by cancels its entire fluctuation prefactor.
Differential entropy Created 2026-10-06 Updated 2026-10-14
Differential entropy describes the spread of a continuous probability distribution relative to the volume scale of its coordinates. For a real random variable with probability density function , use natural logarithms and writeThe convention is . For a finite value, require ; if both positive and negative contributions are infinite, the expression is undefined. Unlike a probability, a probability density can exceed one. Consequently differential entropy can be negative. Base-two logarithms give , in bits instead of nats.[ref]
Chapter 1: Information Measures: Entropy and Divergence. §1.3, Definition 1.5, equation (1.19) and warning, printed p. 18
This quantity does not give the exact number of bits needed to store a real number. A recording device supplies a resolution; equal-width bin entropy connects that resolution to discrete information entropy. The useful continuous quantity is what remains after removing the increasing cost of specifying finer bins. Its dependence on coordinates is visible already in differential entropy of a uniform law.
Take with continuous uniform distribution on and set . This is an increasing invertible transformation on that interval. Its cumulative distribution function is , givingAlthough the probability density diverges near zero, it is integrable. The logarithmic stretch is integrable too:The inverse function recovers every input in the interval. The changed differential entropy records a changed coordinate volume, rather than a failure of recovery.
// Target: probability-and-statistics.bigb
Differential entropy of a uniform law 2026-10-14
For a continuous uniform distribution on an interval of length , the probability density is . Direct integration givesThus a uniform law on an interval of length has differential entropy , while length two gives . Both laws have total probability one. The shorter interval has larger probability density, making negative; this is neither a negative probability nor a negative discrete information entropy.
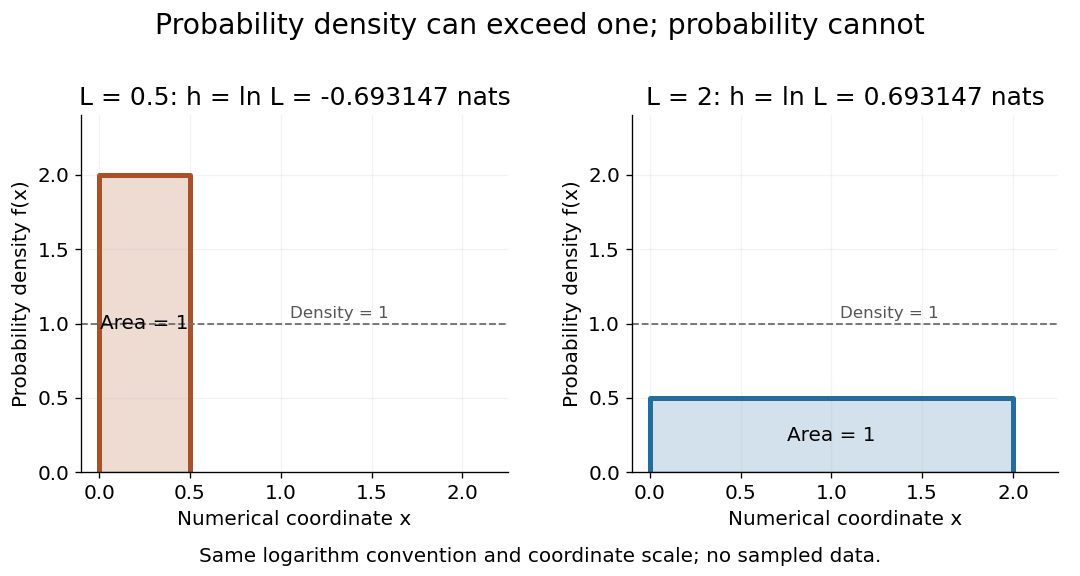
Uniform densities can have negative or positive differential entropy
. The two stipulated continuous uniform distributions have density two on an interval of length and density on an interval of length two. Each rectangle has area one. The reported differential entropy is in nats, using the displayed numerical coordinates. Details.
Let have a probability density function on an open interval, and let be continuously differentiable, strictly increasing there, with . The change of variables formula givesIf the differential entropy and the expected absolute logarithm of are finite, taking the expectation of the negative logarithm proves the displayed formula, for a fixed base . Local stretching reduces probability density; its contribution to differential entropy is the expected logarithmic stretch. The map is invertible, so this change does not mean that the transformation destroyed information about .