Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
The divisible group is injective: every homomorphism extends to by choosing an th division of its value at , and the Baer criterion applies. It is a cogenerator because any nonzero element generates a cyclic subgroup admitting a character nonzero on that element, and injectivity extends that character to the whole group. Consequently a map of abelian groups is injective exactly when restriction is surjective: injectivity gives extension of characters, while a nonzero kernel element is detected by a character that cannot extend along .
A prescribed PDE source term changes the heat equation to , or the transport equation to . If is a temperature, has units of temperature per time. The formulas below assume ; a nonzero PDE source term can change the spatial average even with periodic boundary conditions.
Let be the forward shift on sequences and the polynomial defining a constant-coefficient linear recurrence relation. For a nonzero base , , so is a particular solution when . At a simple root of the characteristic equation of a linear recurrence, the correct trial acquires a factor :The identity follows by substituting into each shift term. A root of multiplicity analogously requires a degree- polynomial factor; the lower-degree homogeneous terms are supplied by the repeated characteristic root of a linear recurrence.
Discrete Green convolution for the period-six recurrence by  Codex 0 Created 2026-10-14 Updated 2026-11-05
The unit-response sequence , is six-periodic. In the displayed convolution, all older terms cancel under by this recurrence; the two new boundary terms reduce to . Thus it gives a particular solution of the inhomogeneous linear recurrence with forcing . Add the two-dimensional homogeneous span of and for the general solution. This is a discrete Green function construction.
A singularity of a massless scattering or radiation integral when momenta of two particles become parallel. In quantum chromodynamics, unresolved quark-gluon splittings cause such divergences. A mass regulator or dimensional regularization exposes them; they cancel between suitable inclusive real and virtual contributions or are absorbed into factorized distributions where appropriate.
An observable unchanged by adding a particle with vanishing energy or replacing one massless particle by exactly collinear particles with the same total momentum. This property permits cancellation of real and virtual infrared divergences and collinear divergences in its perturbative cross-section. Fully inclusive electron-positron hadronic rates and suitably defined jet observables are examples.
For a vertex law on a graph, choose and an independent set valued random variable containing almost surely. Minimize their mutual information over all such joint laws. This defines graph entropy. It differs from the entropy of a proper coloring, because the random independent set need not be a deterministic color class.
The self-information of a positive-probability outcome is the negative logarithm of its probability. Independent outcomes have additive self-information. Its expectation is Shannon entropy.
// Target: probability-and-statistics.bigb
This is the entropy in base of the distribution with one symbol of probability and each of the other symbols of probability . It increases on from zero to one, and governs the exponential volume of a Hamming ball. For it is the binary entropy function.
// Target: algebra.bigb
If are independent random variables taking values in a countable additive group, conditioning on makes a translate of . Consequently , and conditional entropy gives . If the two information entropies are finite, equality holds exactly when and are independent.
// Target: probability-and-statistics.bigb
Cross-entropy measures the average logarithmic loss incurred when outcomes follow one probability distribution , but a model assigns probabilities using another probability distribution . For a finite alphabet, write their probability mass functions as and . With base-two logarithms,The expectation is under the true or stipulated source law , rather than the model . Terms with contribute nothing. If but for any outcome, the cross-entropy is : the model rules out an event that can occur. The result is measured in bits; natural logarithms give nats.
The useful identity is cross-entropy equals entropy plus relative entropy:The source's information entropy is the baseline uncertainty. The Kullback-Leibler divergence is the extra average cost of a mismatched model, with the true law first and model second. Thus optimizing for a fixed reduces the mismatch, rather than changing the source's own uncertainty. For finite alphabets, the minimum is , attained exactly at .
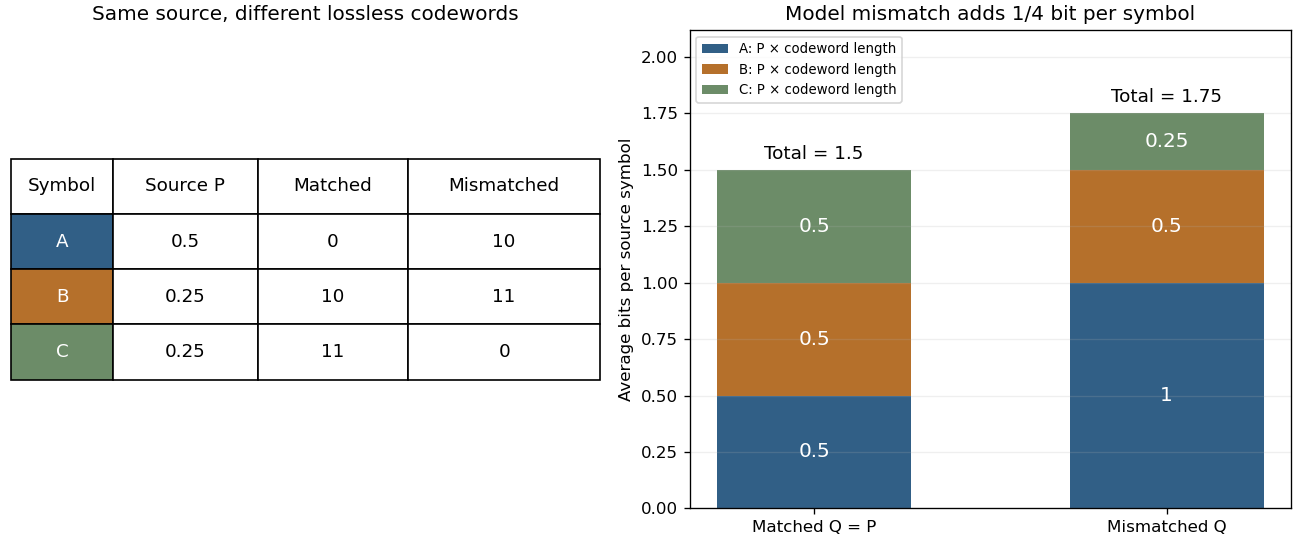
Take a three-symbol source with . A matched binary prefix code assigns , , , with lengths . A mismatched prefix code instead assigns , , , with lengths , corresponding to . Both prefix codes decode exactly, but the most common symbol is shorter in the matched code. Under the same source ,The mismatched code costs an extra (1/4) bit per source symbol on average. No information is lost; the penalty is inefficient representation of this source. The mismatch penalty in lossless coding explains when this coding interpretation is exact.
Cross-entropy is also useful when evaluating a predictive distribution. A report that places tiny probability on the realized outcome receives a large logarithmic loss, even when it usually predicts the most common outcome correctly. The loss convention is the negative of the reward convention in the logarithmic scoring rule. Its expected loss is uniquely minimized by the correct probability distribution, making it a strictly proper scoring rule. Strictly Proper Scoring Rules, Prediction, and Estimation by Tilmann Gneiting and others treats this connection in §3.1, Example 3; its discussion uses rewards, so the signs are reversed for the losses here.[ref]
I. J. Good's Rational Decisions by I. J. Good appeared in 1952. Its published summary describes a method for encouraging accurate probability estimates and a connection with information theory. Strictly Proper Scoring Rules, Prediction, and Estimation by Tilmann Gneiting and others traces the logarithmic scoring rule at least as far back as this 1952 paper.[ref]
Joint entropy is the information entropy of an entire random vector, treating its coordinates together as one outcome. For random variables with finite alphabets and joint probability mass function ,It is measured in bits. The distinction from separate information entropies is whether shared uncertainty is counted once or repeatedly. Two copies of the same fair bit have joint entropy one bit, since only and can occur. Two independent fair bits have joint entropy two bits, since all four pairs are possible and equiprobable.
For a less symmetric example, assign probabilities to respectively. ThenHere is fair, while . Thus and bits, where is binary entropy. Adding the separate information entropies would give approximately bits, overcounting by the mutual information bits.
The chain rule for information entropy makes the shared information explicit:In this example is certain given and fair given , so its average conditional entropy is bit. Sending the first coordinate changes how much uncertainty remains in the second. A prefix code with codewords
0, 10, 11 for the three possible pairs has average length bits, exactly the joint entropy in this stipulated law.For finite alphabets,The lower bound follows because knowing the full random vector determines every coordinate; the upper bound follows from conditioning reduces entropy in the chain rule for information entropy. Equality in the upper bound means joint independence. The difference from that upper bound is total correlation, whose noisy parity total correlation example shows why separate pairwise comparisons need not find all the dependence.
A homogeneous canonical scalar field with positive scalar potential has energy density and pressure . When its potential energy dominates its kinetic energy, the equation-of-state parameter approaches . If other components and spatial curvature are negligible, the Friedmann acceleration equation gives accelerating expansion. Small initial kinetic energy is not enough to ensure long cosmic inflation; the field must also remain on a sufficiently flat part of the scalar potential, as measured by the potential slow-roll parameters.
The inflaton potential is the potential energy density of an inflaton as a function of its field value. Its derivative enters the inflaton equation of motion, while its slope and curvature enter the potential slow-roll parameters.
Choose a primitive counterexample with minimal and even. Its Pythagorean triple has , . Modulo four forces odd and even, so and . The primitive triangle then has a parametrization with and . Coprimality makes , giving with . This contradicts infinite descent.
The essential infimum and essential supremum describe the lower and upper bounds of a measurable function after disregarding null sets for a specified measure. A pointwise infimum or supremum sees every input; an essential bound sees whether values below or above a proposed threshold occur on a set of positive measure. Thus "essential" means insensitive to changes on a null set, rather than insensitive to unusual values. This distinction makes essential bounds compatible with Lebesgue integrals and the equivalence classes used in Lp spaces. [ref]
Lp spaces (Chapter 7 of Measure Theory). Hunter, Measure Theory, Definitions 7.1, 7.3–7.4: almost-everywhere equivalence and essential bounds
.For a real measurable function on a measure space , the definitions areThese can take values in the extended real number line. On a space of positive total measure, finite essential bounds obey almost everywhere. If is finite, every threshold has ; the corresponding lower-edge statement is for every . These are the measure-based counterparts of the approximation property of a supremum and approximation property of an infimum.
Here is a two-sided example on with Lebesgue measure:The pointwise bounds are and , while the essential bounds are and . Both exceptional singletons are null sets. But for , the inputs where still have measure , and those where have measure : deleting or adding two individual inputs cannot change those lengths. Hence neither essential bound can be moved inward.
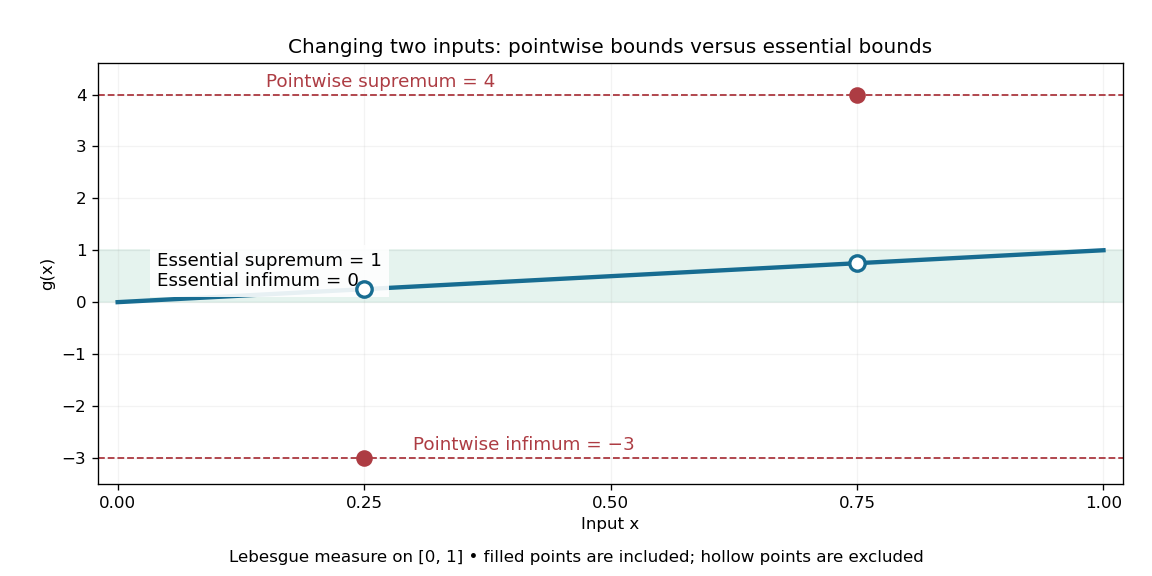
Essential infimum and essential supremum ignore two exceptional singletons, while pointwise infimum and supremum retain them
. The function follows except for the filled values and . Hollow markers exclude the ordinary values at those inputs. The shaded horizontal band spans the essential bounds zero and one for Lebesgue measure. Details.The choice of measure is part of the answer. The same has essential bounds and under counting measure, because every nonempty set has positive measure. Under the Dirac measure at , both essential bounds equal . A null set for one measure need not be a null set for another.
Nor must the exceptional inputs be isolated. The Dirichlet function, equal to one at rational numbers and zero at irrational numbers, has pointwise supremum one on , but essential supremum zero for Lebesgue measure: the rational numbers form a countable set that is a null set, even though they are dense. Conversely, a value ten on an interval of length affects the essential supremum just as decisively as it would on half the domain. Small positive measure is not zero measure.
For a character of , the induced character isThis is the character of a representation of . Substituting this expression into the character inner product and putting proves Frobenius reciprocity.
Every complex irreducible representation of a finite p-group is induced from a one-dimensional representation of a subgroup. Induct on the group order. Nonfaithful representations reduce to a smaller quotient. For a faithful representation of a nonabelian group, choose an abelian normal subgroup not contained in the centre. Restriction cannot be isotypic, since it would make that subgroup scalar and faithfulness would then force it central. The Clifford correspondence induces the representation from a proper subgroup; induction there and transitivity of induction complete the proof. Abelian groups have only one-dimensional complex irreducible representations.
For a smooth linear character of a parabolic subgroup , unnormalized induction consists of smooth functions satisfying , with right-translation action. The quotient is compact for the local general linear groups in question. Normalized induction inserts a square root of the parabolic modulus in the covariance, changing formulas for the inducing linear character.
Extension of a faithful representation from an open normal subgroup by Codex 0 Created 2026-10-14 Updated 2026-10-25
Codex 0 Created 2026-10-14 Updated 2026-10-25Let be an open normal subgroup of a compact topological group , and let be a continuous faithful representation. Choose representatives for the finite left cosets . Write and act on the -th summand of by into the -th summand. The cocycle identity proves this is a continuous group representation. An element outside has a nontrivial coset permutation, while an element of acting trivially has on the identity-coset summand. Hence the representation of is faithful and integral.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact