Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
A real centered random variable is sub-Gaussian random variable with parameter if its moment-generating function satisfiesThe parameter is an upper bound on fluctuation size, not necessarily the standard deviation. For and , exponential Markov inequality gives . Choosing and applying the same argument to yields the Chernoff boundA centered normal distribution of variance attains equality in the moment-generating-function condition. A Rademacher distribution also satisfies it with , since . Products of moment-generating functions show that a sum of independent centered sub-Gaussian random variables with parameters is sub-Gaussian with parameter . Hence the sample mean of independent variables with a common parameter has tail bound . This gives normal-like concentration without assuming a normal distribution. For an uncentered variable, the convention is to apply the condition to .
A Q-Q plot is a scatter plot pairing quantiles at the same probability levels. For a statistical sample of size , sort the observations into order statistics . Choose plotting positions and a reference quantile function , then plotHere the horizontal coordinate is a reference value, and the vertical coordinate is an observed value; neither axis is the probability . The displayed plotting positions are our chosen convention, placing every level strictly between zero and one. They are not a claim that the th order statistic equals that population quantile. For two statistical samples, use sample quantiles at matching levels, with a stated interpolation convention when their sizes differ. [ref]
As a computed example, take and the standard normal quantiles , where is the standard normal cumulative distribution function. Construct the ordered values . At ranks , the plotting positions are , the reference quantiles are approximately , and the constructed values are approximately . Every point lies on by construction. These 19 values are deliberately chosen, not random draws or real measurements.
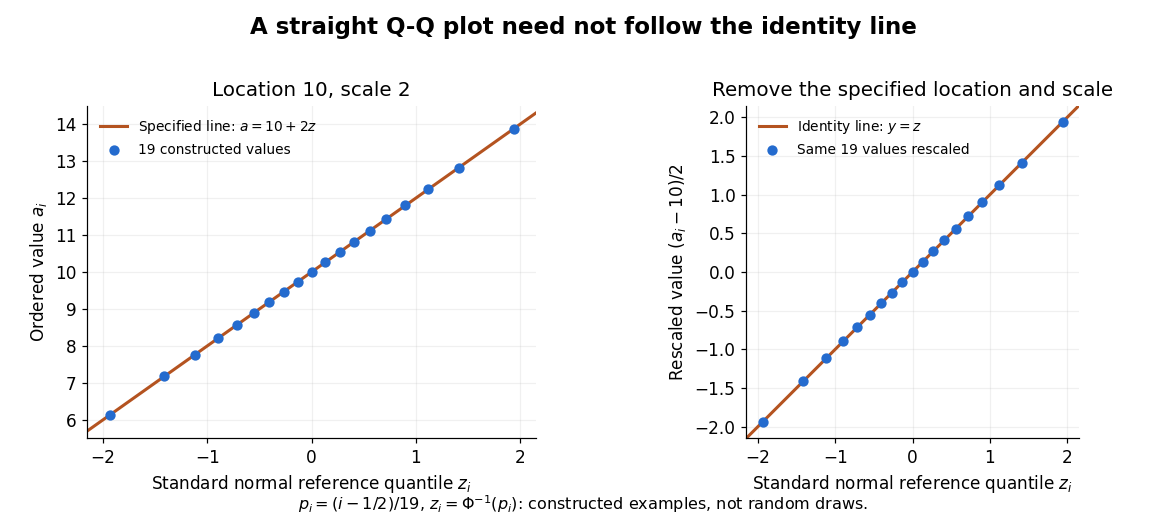
The usefulness of a Q-Q plot is that it turns a comparison of probability distributions into geometry: if a reference random variable is transformed into with , its quantile function satisfies . This follows because a positive scaling preserves ordering. Thus the location-scale family produces a straight population Q-Q plot, and an approximate sample line suggests a compatible shape over the observed range. Its intercept describes location and its slope describes scale. The identity line requires the same location, scale and units on both axes; even then its displayed angle is 45 degrees only with equal axis scales. Curvature is often more informative than a histogram because it shows which quantiles depart from the reference. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/qqplot.htm. NIST/SEMATECH, Quantile-Quantile Plot, location and scale comparisons
The birthday problem asks for the probability that at least two members of a group share a birthday. Use the explicit model of independent random variables taking labels with a uniform distribution on a finite set. Let and be integers. For calendar examples below, stipulate equally likely labels and omit leap days. For , the probability of at least one matching pair isAt , the empty product is one and . At , a repeat is certain by the pigeonhole principle. Count the complement to obtain the formula: the first label has choices, then a distinct second label has , and so forth, out of equally likely label sequences.[ref]
For the stipulated calendar, and . Only 23 people suffice to put the probability above one half. There are possible pairs, each with matching probability . The many comparison opportunities explain why a small group can contain a repeat.
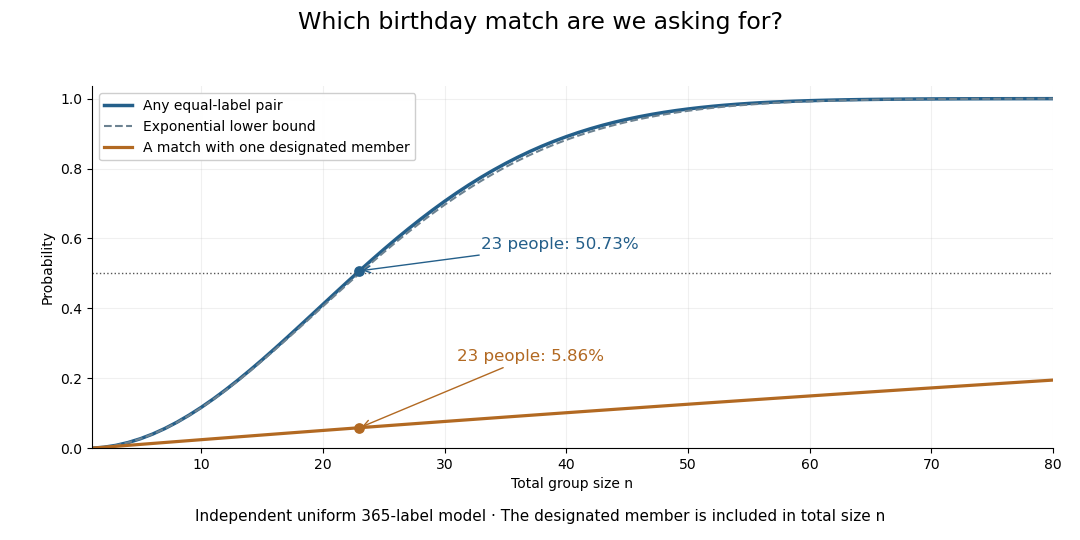
The distinction also matters for hash collisions. If independently generated outputs of a hash function are uniformly distributed over possible labels, the same counting formula governs repeats. The birthday square-root scale explains why looking for any repeated output requires far fewer labels than trying to match one predetermined output. The uniform-independent model is an assumption about those outputs; the birthday problem does not itself establish that a particular implementation meets it.
Descriptive statistics summarizes observed data, for example through location and spread statistics or graphical summaries such as a histogram.
A binary heap represents a priority queue as a complete binary tree obeying a heap order. We use the minimum convention: the priority of every parent in a rooted tree is no greater than the priorities of its children in a rooted tree. Equal priorities are allowed. Each stored entry may be a record carrying a priority key; the numerical example below displays only keys. Reversing the inequalities gives the maximum convention.
The complete binary tree can be stored directly in a zero-indexed array : read its levels from top to bottom, left to right. The root of a tree is at index . The possible children in a rooted tree of index are at and , and an index denotes a present entry only when it is less than . For , its parent in a rooted tree is at , using the floor function. Thus the links of the complete binary tree are determined by arithmetic rather than separately stored pointers.
ConsiderThe children in a rooted tree of index have keys ; those of index have keys ; those of index have keys . The six comparisons , , , , , establish the heap order. At index , the parent in a rooted tree is index , carrying key .
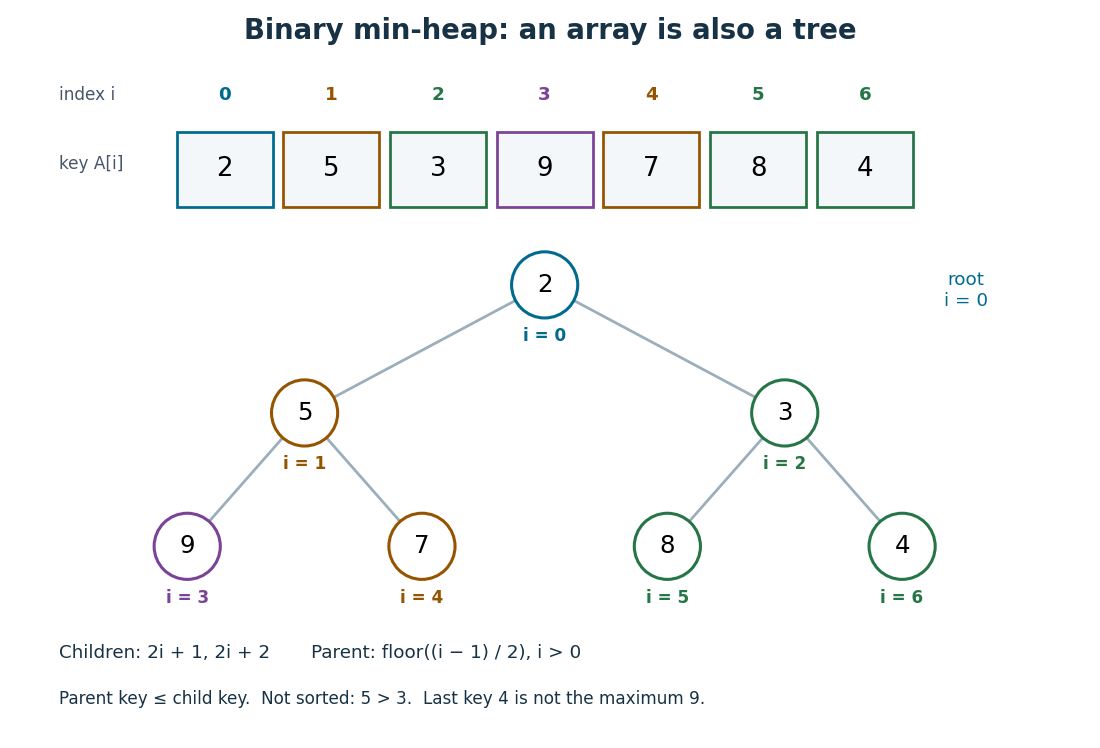
The array is visibly not a sorted array: precedes , and precedes . Nor is the last entry a maximum: it is , whereas the maximum is at index . The heap order compares ancestors and descendants, without imposing an order between separate branches. Nevertheless, following the graph path from the root of a tree to any entry gives a chain of nondecreasing priorities. This short argument proves that
peek can return , a minimum, without inspecting the other entries.Insertion appends an entry to the array, preserving the shape of the complete binary tree, then uses sift up to repair the heap order. Insert key into the displayed binary heap. It is appended at index , and exchanges with indices , , then :The moving key follows ; the keys each move down one level. Only this chain needs repair.
Now apply
extract-min. Save key , move the last key to the root of a tree, and shorten the array to length . Use sift down, always choosing the smaller of the present children in a rooted tree:First exchanges with key at index , since ; then with key at index , since . At index , the possible children in a rooted tree would be indices , both outside the shortened array, so the process stops. The returned key is , and the remaining binary heap is exactly the original one.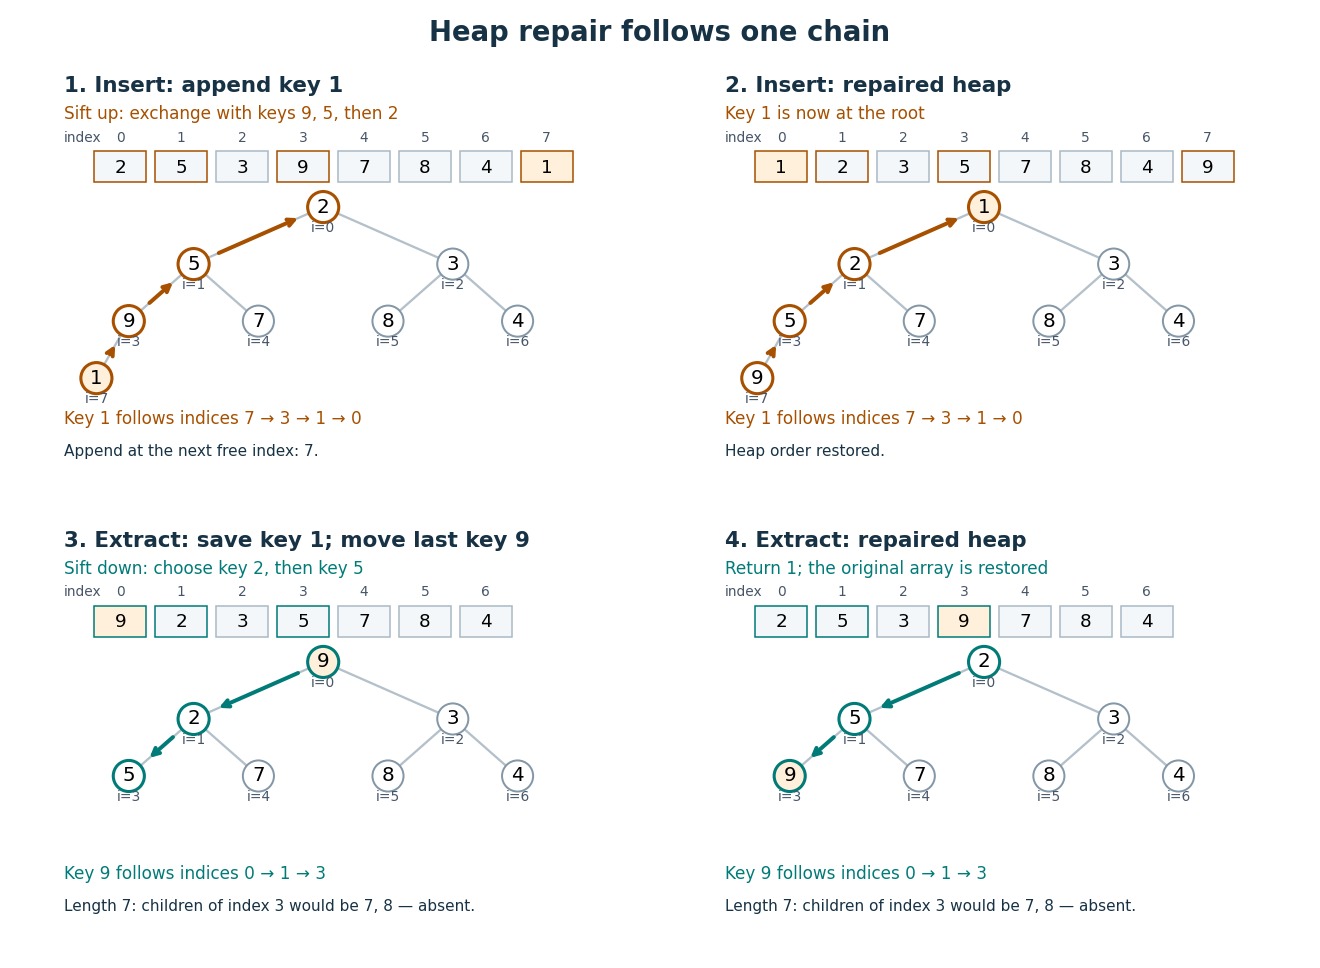
For a nonempty binary heap with entries, the deepest level is , using the floor function and logarithm. Each exchange moves one level and uses only a bounded number of comparisons. The resulting time complexity bounds, expressed in Big O notation, are:
| Operation | Time complexity | Reason |
|---|---|---|
peek | Read the root of a tree. | |
| Insert | for | Append, then sift up through at most the levels of the complete binary tree. |
extract-min | for | Move the last entry, then sift down through at most those levels. |
| Build from an arbitrary array | Apply sift down from the last index with children in a rooted tree back to index . |
These bounds assume constant-cost indexed access, key comparisons and exchanges, and available array capacity for insertion. Allocating and copying a larger array is a separate cost. Empty and one-entry cases take constant work.
To build a binary heap, begin at index and work backwards. Entries without children in a rooted tree already obey the heap order. Each sift down, also called heapify down, starts with every present smaller rooted tree below it already repaired. Most entries are close to the bottom and can move very little; successively longer repair distances occur for geometrically fewer entries. Summing these distances gives work, rather than charging to every entry. MIT's notes give this bottom-up construction and contrast it with repeated insertion.[ref]
https://ocw.mit.edu/courses/6-006-introduction-to-algorithms-spring-2020/40d4851e550507ca14dc778b9b2266cc_MIT6_006S20_lec8.pdf. MIT 6.006, lecture 8: implicit indices, heap repair and linear build, pp. 3–6
The Dijkstra algorithm additionally needs to decrease the priority of an existing vertex when its tentative distance improves. Given its current index, lowering the key followed by sift up takes time for . An indexed binary heap maintains a separate map from item identity to its current index and updates that map after every exchange. For vertices numbered in a fixed range, the map can be another array, giving constant-time index lookup. An ordinary unindexed binary heap supplies no such guarantee: locating an arbitrary item can require scanning entries. Item identity and priority must remain distinct, especially when several vertices have equal tentative distances.
The attractive compromise is local organization with global usefulness. A binary heap maintains only the heap order, yet every
extract-min gives the next smallest key. Repeated extraction of the original example gives , so a priority queue also supplies a sorting algorithm without storing a sorted array between extractions.A simple cell is a visual cortical neuron whose receptive field has spatially separable ON and OFF receptive-field subregions. Elongated neighboring subregions give a preferred orientation and a sensitivity to the location and polarity of visual contrast. “Simple” describes the response organization; it does not describe a simpler cell body or a particular shape of neuron.
Hubel and Wiesel's 1962 classification emphasized four observations: distinguishable ON and OFF receptive-field subregions, summation within each region, antagonism between regions, and qualitative prediction of responses to differently shaped stimuli from those regions' arrangement. A slit fitting an elongated center was more effective than a smaller spot; a larger patch could invade opposing flanks and lose effectiveness. An edge separating bright and dark regions could be effective when its boundary matched the boundary between subregions. These were observations about spike trains, rather than an assertion of exact linearity. [ref]
https://www.gatsby.ucl.ac.uk/teaching/courses/tn1-2020/additional/systems/JPhysiol-1962-Hubel-106-54.pdf. Hubel and Wiesel (1962), pp. 109–112: simple-field criteria and slit/edge experiments
The following deliberately coarse signed spatial filter model of a simple cell makes the geometry easy to count. A centered bright bar contributes positively at five sites. Rotating it preserves its area but mixes positive and negative weights; shifting it preserves its orientation but changes which weights it samples. The model is useful because it predicts distinct effects of these three manipulations instead of treating any bright stimulus as equivalent.
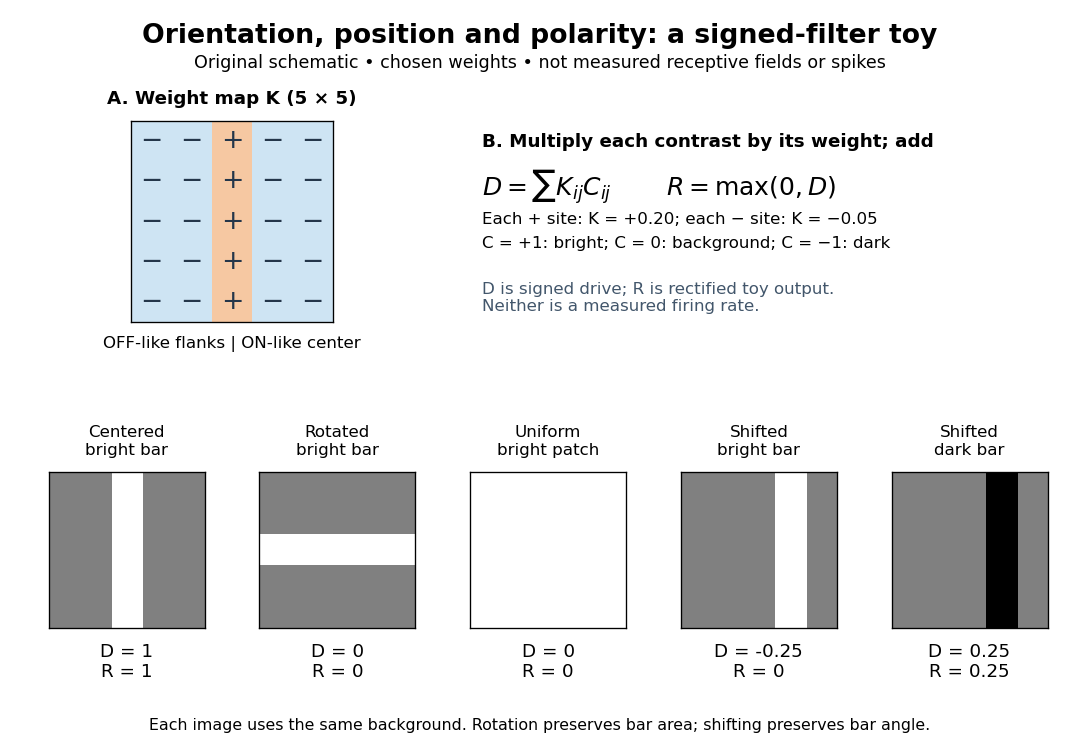
A simple cell is not an ideal linear sensor. Its spike train is nonnegative in event count, and neural adaptation can change responsiveness. The signed spatial filter model of a simple cell supplies a useful approximation to spatial drive and an explicit output rule. Comparing predictions with unseen stimuli is more informative than assuming the rule from the name “simple”. In contrast, the existing complex cell models explore tolerance to phase and local displacement.
Orientation selectivity is a systematic dependence of a visual neuron's response on the axis of a bar, edge or stripe pattern presented in its receptive field, under specified stimulus conditions. Here the angle measures the stripe axis from horizontal: is horizontal and vertical. An axis has no arrow, so and describe the same orientation. A preference for one direction of movement across that axis is an additional property; the 1962 recordings included both equal and unequal responses to opposite movements. [ref]
https://www.gatsby.ucl.ac.uk/teaching/courses/tn1-2020/additional/systems/JPhysiol-1962-Hubel-106-54.pdf. Hubel and Wiesel (1962), p. 112: orientation versus opposite movements
A particularly clear experiment using extracellular single-unit recording appears in the 1959 paper, Figures 2–3. A bright slit was centered on the same receptive field and rotated through successive angles; each presentation lasted one second. The vertical slit strongly increased the extracellularly recorded spike train, whereas the horizontal slit was ineffective. Small-spot tests had identified ON and OFF receptive-field subregions, with a central ON region and opposing flanks: rotation illuminated less of the center and more of the flanks. Geometry and location therefore mattered together. These dimensions belong to that recorded unit, not to every neuron. [ref]
https://xbio-live.s3.amazonaws.com/narratives/57358/Hubel%20and%20Wiesel%201959_Guided%20paper.pdf. Hubel and Wiesel, Receptive fields of single neurones in the cat's striate cortex (1959), pp. 578–579, Figures 2–3: primary recordings
An orientation tuning curve summarizes a controlled angle sweep. Keep location, size and visual contrast fixed; for a stripe pattern also specify spatial frequency and phase. The same signed spatial filter model of a simple cell can produce strong orientation selectivity and strong dependence on phase, as the following original toy illustrates. Its smooth curves are calculated predictions, not digitized or invented biological measurements.
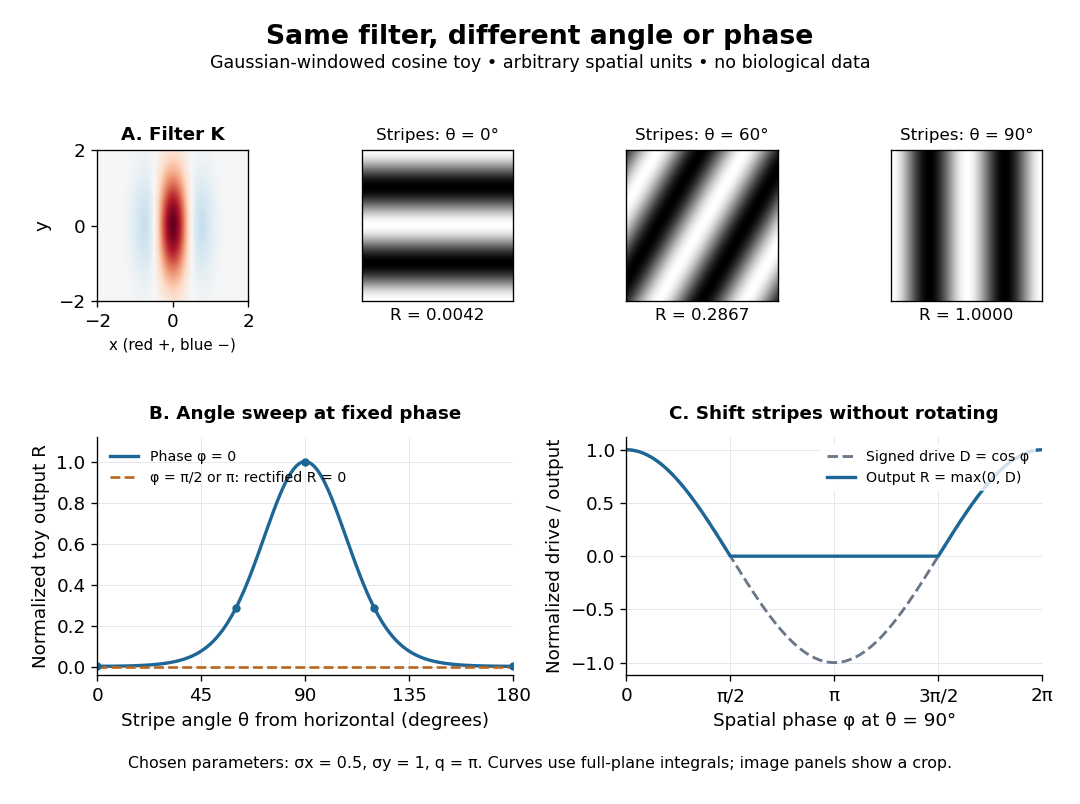
A complex cell typically responds selectively to an oriented edge or bar over a finite spatial region with less dependence on spatial phase and contrast polarity than a simple cell. It need not have the simple cell's separated linear ON and OFF subregions. Phase tolerance is local, not invariance to arbitrary displacement outside its receptive field.
Correlation-based development of visual cortical maps by  Codex 0 Created 2026-10-13 Updated 2026-10-24
Consider afferent activities , cortical activity and a constrained Hebbian learning rule . If , then , where is the input correlation matrix. Thus input correlations and lateral interactions select growing weight modes, while synaptic normalization and bounds stop unlimited growth. The model tests how organization can emerge without assigning every final cortical feature in advance.
A predator is an organism that consumes prey through predation. A predator need not occupy the highest trophic level of an ecosystem, and the label does not specify its size or guarantee that it has no predators of its own. In the illustrative food chain, the small fish is a predator at level 3 and also prey for the large fish at level 4. Separating these relational labels from species names prevents a misleading division of the world into permanent predator and prey categories.
Prey is an organism consumed by a predator in predation. The name describes the receiving end of that interaction: a small fish can be prey for a large fish while being a predator of zooplankton. In a food web drawn with resource-to-consumer arrows, a feeding arrow goes outward from the prey toward its predator. This convention makes the route of food and energy easy to follow.
Linkage disequilibrium means that knowing an allele at one genetic locus changes the probability of an allele at another genetic locus in population haplotypes. It compares their joint probability distribution with the product of their marginal distributions. This is useful because a genetic marker can carry information about another genetic locus: tag SNPs exploit this redundancy, without establishing a causal genetic association.
Consider two genetic loci with alleles and . Sample one haplotype, rather than an unphased diploid genotype. Write its four haplotype frequencies as , summing to one, and set the marginal allele frequencies to and . The linkage disequilibrium coefficient isThe second expression follows by substituting . The entire two-locus joint probability distribution is thenEvery row and column sum is unchanged when varies. Linkage equilibrium means : all four haplotype frequencies equal products of allele frequencies, so the two allele indicators are independent random variables. For , the conditional probability shows directly how positive enriches among copies carrying , while negative depletes it. Positive also enriches ; negative enriches and . Swapping the labels and reverses the sign of , so neither sign is intrinsically favorable.
For example, fix the allele frequencies at . At linkage equilibrium, the haplotype frequencies in the order are . Positive linkage disequilibrium instead gives , with ; negative linkage disequilibrium gives , with . Counting each allele separately would miss the difference.
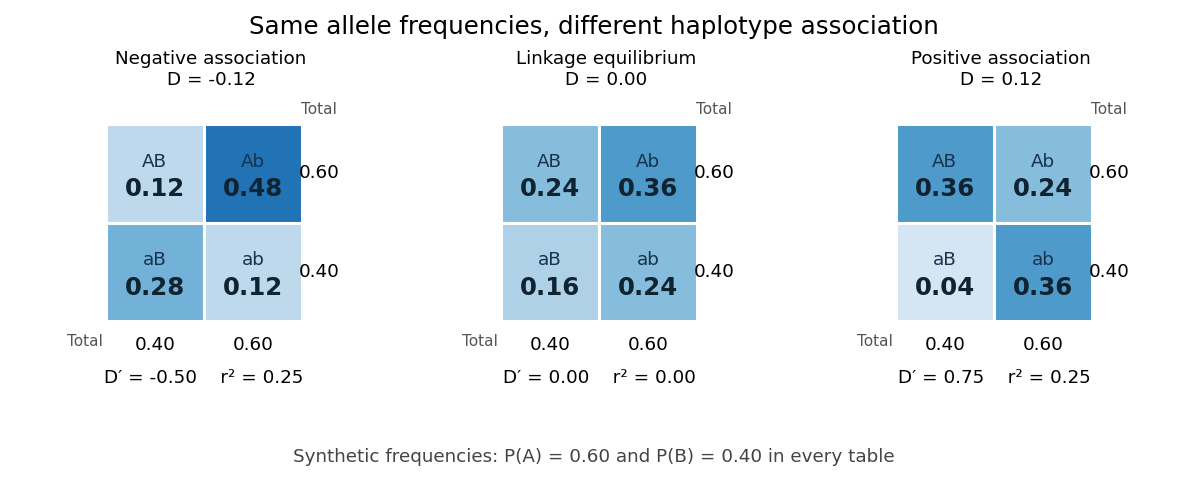
Three haplotype joint probability distributions with identical marginal allele frequencies, showing negative linkage disequilibrium, linkage equilibrium and positive linkage disequilibrium
. Details. Nonnegative haplotype frequencies constrain . Define the nonnegative bounds and . The four entries above giveThus globally, but a particular pair of allele frequencies usually permits a smaller, asymmetric interval. The standardized linkage disequilibrium convention used here retains the sign:This convention requires ; if either genetic locus has only one allele in the population, but normalized measures are undefined. Some presentations report only . At or , at least one of the four haplotypes has zero frequency; this alone does not prove that genetic recombination has never occurred.
For the indicator random variables and , their covariance is , and their variances are and . The allelic correlation measure is their squared correlation coefficient,The subscript distinguishes it from the recombination fraction in linkage-disequilibrium decay under recombination. Squaring loses the association's sign. In the illustrated positive and negative examples, in both, whereas and , respectively. For another original example, take : then , yet . Every carries , but most copies carrying lack . The frequency constraints and the distinction between these normalizations are analyzed in Mathematical properties of the r² measure of linkage disequilibrium by Jenna M. VanLiere and others (sections 2.1 and 2.5, pp. 131–132 and 135–136).
Genetic linkage describes transmission through meiosis; linkage disequilibrium describes a population's haplotype frequencies. Nearby genetic loci on a chromosome can be in linkage equilibrium. Conversely, mixing populations can create linkage disequilibrium even between genetic loci on different chromosomes. For example, mix equal numbers of independently sampled haplotypes from two populations, each internally at linkage equilibrium, with in one and in the other. The pooled allele frequencies are , but , giving . This is a consequence of population stratification, not a measurement of the recombination fraction.
Measured haplotype frequencies also depend on the sample. Finite sample size, related individuals, genetic-study ascertainment, genotyping error and uncertain haplotype estimation can change an estimate. A missing rare haplotype can give empirical without demonstrating its absence from the population. Report the sample definition and allele frequencies alongside the association measure; a nonzero sample estimate alone does not establish nonzero population linkage disequilibrium.
A concrete dataset is the 2005 A haplotype map of the human genome by The International HapMap Consortium. The International HapMap Consortium used genotyping platforms including Illumina BeadArray to obtain SNP genotype calls from 269 DNA samples across four collections: 30 parent–offspring trios from Ibadan, 30 trios from Utah, 45 unrelated individuals from Beijing and 44 from Tokyo. Parent–offspring trios and the PHASE algorithm supplied haplotype estimation, rather than direct observation of every chromosome. In Figure 7, 36 SNPs resolve seven haplotypes in a chromosome 2 region in the Utah panel; seven tag SNPs capture the 36 SNPs at . The readout demonstrates reusable allelic correlation, not causal effects.
Controls required over 80% complete calls, at most one discordance among five duplicate genotypes, at most one Mendelian segregation error per trio panel, and a Hardy-Weinberg equilibrium test with ; blind reassessment checked performance. Minor allele frequencies of at least 0.05 were targeted, the collections were not population-representative, and inferred haplotypes retain phase uncertainty. These limits restrict extrapolation of linkage disequilibrium.[ref]
A haplotype map of the human genome by The International HapMap Consortium. pp. 1300–1302, Table 1; Figure 7, p. 1306; Methods, p. 1316
Inbreeding is reproduction between genetically related individuals. It increases the chance that an offspring's maternal and paternal copies at a locus are identical by descent. Such homozygosity by descent is autozygosity.
The infinite-sites model assumes that every mutation occurs at a previously unmutated site, so each mutation on the sample genealogy produces a distinct segregating site. If mutation rate per lineage is in standard coalescent time units, a tree of total length has a Poisson distribution of mutation count with mean .
A segregating site is a position at which at least two states occur in the sampled chromosomes. Under an infinite sites mutation model, mutations below the sample's common ancestor correspond one-to-one to segregating sites. Their number is commonly denoted .
Effective population size is the size of an idealized biological population giving the relevant rate of genetic drift or ancestral coalescence in the biological population being modeled. In the standard neutral diploid coalescent, time is measured in generations and the population-scaled mutation parameter is .
// Target: biology.bigb
Genetic drift is random variation of allele frequencies due to finite-population reproduction. In the neutral ancestry description, randomly sampled gene copies merge into common ancestors according to Kingman's coalescent.
// Target: probability-and-statistics.bigb
A population bottleneck is a temporary large decrease in biological population size. It changes ancestral coalescence rates and can leave fewer ancestral haplotypes and increased linkage disequilibrium after the biological population expands.
// Target: biology.bigb
An ancestral recombination graph records ancestral coalescences and genetic recombination events for sampled chromosomal material. Backwards in time, each pair of ancestral lineages merges at rate one in standard diploid coalescent units, while a lineage splits at a recombination breakpoint at rate times the genetic span of the material it carries. The breakpoint splits that lineage's ancestral material into two parental contributions. Waiting times are exponential with the sum of the current event rates. At each genomic position, retaining the ancestry at that position gives a marginal phylogenetic tree with the neutral Kingman's coalescent distribution. Different positions have dependent trees because they share parts of the graph.
// Target: biology.bigb
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact