
Numerical linear algebra Created 2026-09-24 Updated 2026-10-14
Stability function Created 2026-09-24 Updated 2026-09-24
Sparse optimization Created 2026-09-24 Updated 2026-09-24
Simplex algorithm Created 2026-09-24 Updated 2026-09-24
Runge-Kutta method Created 2026-09-24 Updated 2026-10-14
A Runge-Kutta method advances an initial value problem , , by sampling its vector field at several trial states within one time step. These samples are Runge-Kutta stages; a weighted combination of their slopes produces the next state. The construction improves on the single tangent line used by the Euler method while requiring evaluations of , rather than explicit higher derivatives of the solution. It applies to scalar equations and systems of ordinary differential equations alike. The coefficient choices distinguish methods such as Heun's method, the classical fourth-order Runge-Kutta method and implicit Runge-Kutta methods.
For stages, write for the stage matrix, for relative time nodes and for output weights. A time step of length computesHere is a slope, with units of state per time; is a state increment. Another common convention writes , so its stage states are and its output is . These are equivalent conventions: including both inside and again in the output would count the time step twice. The textbook formulation uses the increment convention.[ref]
6.4 Runge-Kutta methods. Fundamentals of Numerical Computation, §6.4.3, equations 6.4.10–6.4.11: multistage recipe and tableau
Usually the Butcher tableau obeys , called internal consistency. Stage then combines slopes over an effective time . The second-order conditions with independent Runge-Kutta abscissae explain what changes when time nodes are specified independently. A Runge-Kutta stage is generally an auxiliary approximation, not a separate accepted solution value at its node. Several stages can even have the same time node but different state arguments, as in the classical fourth-order Runge-Kutta method.
The useful idea is to approximate the integral without knowing the intermediate exact trajectory. Trial states provide places to sample , and Butcher order conditions make the resulting combination agree with the exact Taylor expansion. More stages alone do not guarantee a higher order of a numerical method: their coefficients must satisfy the appropriate conditions. Embedded Runge-Kutta pairs reuse these same samples for a second output and a practical local error estimator.
Fourier spectral method for variable-coefficient advection Created 2026-09-24 Updated 2026-09-24
Fourier-Galerkin matrix for a drift-diffusion equation Created 2026-09-24 Updated 2026-09-24
For and Fourier truncation ,whereFor , the nonconstant block has Gershgorin discs in the closed left half-plane, while the constant mode lies in the kernel. Hence every eigenvalue has nonpositive real part and the matrix is singular.
Periodic trapezoidal Fourier aliasing Created 2026-09-24 Updated 2026-09-24
For a two-periodic Fourier series sampled at equally spaced points, discrete averaging retains exactly the modes divisible by :If with , thenwhich is exponentially small.
Peano kernel theorem Created 2026-09-24 Updated 2026-09-24
The Peano kernel theorem represents a linear approximation error that annihilates polynomials below degree as
Gradient descent Created 2026-09-24 Updated 2026-10-18
Gradient descent is an iterative method for minimizing a differentiable function : choose an initial vector and repeatedly move opposite its gradient.[ref]
With a fixed positive step size , the update isThe direction and the step size play different roles: the gradient supplies local information about increase, while determines how far that information is trusted. A varying step size gives instead; exact line search for a positive-definite quadratic chooses it by minimizing along the current direction.
Why is this the steepest direction? For a unit vector in the Euclidean norm, the directional derivative is . The Cauchy-Schwarz inequality bounds it below by , attained by when the gradient is nonzero. This is steepest descent relative to the Euclidean norm; changing the norm can change the steepest direction. A finite step need not decrease , because a directional derivative describes infinitesimal motion.
For the quadratic form with linear term , assuming is a symmetric matrix, the negative gradient is the linear-system residual . Thus gradient descent turns the linear system into repeated residual corrections; a positive-definite matrix makes its solution the unique global minimum. This is useful when applying the linear map is affordable but directly solving the linear system is costly.
The attraction is that a gradient evaluation gives an entire update without solving a new linear system. The difficulty is choosing a step size that progresses along gently curved directions without overshooting steep ones. Fixed-step gradient descent on a positive-definite quadratic makes this tension exact: every eigenvector direction has its own multiplier, determined by its eigenvalue. The resulting condition number dependence explains why a narrow valley can slow even an inexpensive iterative method.
The simplicity of the gradient update and its sensitivity to the condition number of the Hessian matrix are central practical features.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §9.3.1, pp. 466–468, and §9.3.2, p. 475, Conclusions: convergence and conditioning
Givens rotation Created 2026-09-24 Updated 2026-10-14
A Givens rotation eliminates one component of a vector by rotating just two coordinates, preserving its Euclidean norm. For example,The length remains five: elimination moves the component into the retained coordinate rather than discarding it. Applied to a matrix, the same operation mixes two rows; QR decomposition by Givens rotations uses these local operations to build an upper triangular matrix.
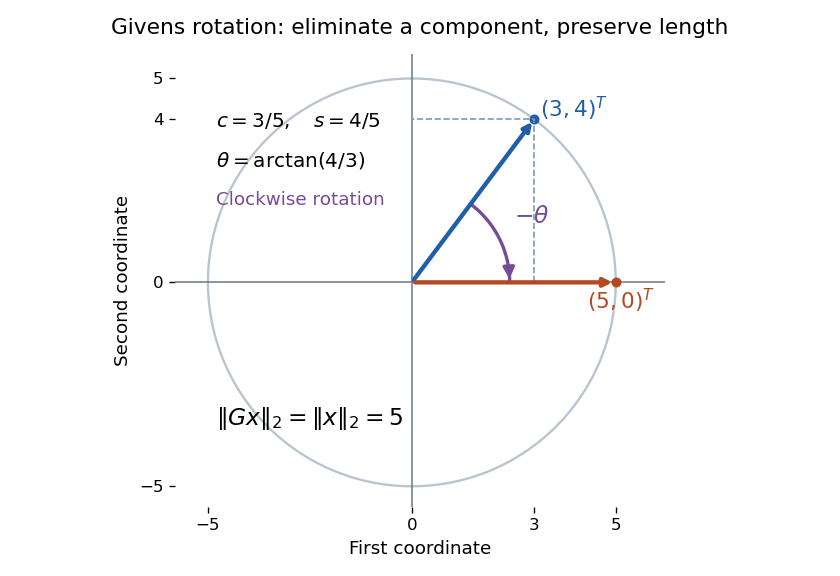
For indices , the matrix is the identity matrix except for its block on coordinates :This article uses left matrix multiplication on column vectors. If and , the block is a rotation matrix through angle : the minus sign belongs in the lower left. Its transpose reverses the rotation. Direct multiplication gives and determinant one, so it is an orthogonal matrix; consequently . Only two coordinates change, but this Euclidean norm identity holds for the entire vector.
Ford-Fulkerson algorithm Created 2026-09-24 Updated 2026-10-14
The Ford-Fulkerson algorithm repeatedly augments a feasible flow along an augmenting path. When no such path remains, the source-reachable vertices in the residual network define a cut of capacity equal to the flow value, proving optimality by the max-flow min-cut theorem.
Equally spaced interpolation Created 2026-09-24 Updated 2026-09-24
Constrained optimization Created 2026-09-24 Updated 2026-09-24
Backward differentiation formula Created 2026-09-24 Updated 2026-09-24
Chebyshev polynomial Created 2026-09-24 Updated 2026-10-18
The first-kind Chebyshev polynomial converts a multiple-angle cosine into a polynomial:The cosine addition formula gives the recurrence relationThis constructs polynomials valid for every real , including outside , where the real-angle description is unavailable. For example,For , has polynomial degree and leading coefficient . On its uniform norm is one, even as its oscillations become more numerous.[ref]
https://dlmf.nist.gov/18.5#i. T. H. Koornwinder and collaborators, NIST Digital Library of Mathematical Functions, §18.5(i), equation 18.5.1: trigonometric representation
[ref]https://dlmf.nist.gov/18.9#i. Koornwinder and collaborators, NIST DLMF, §18.9(i), Table 18.9.1: recurrence coefficients
The polynomial roots of are especially simple:They correspond to equally spaced angles, but their locations in cluster near and . For , the polynomial roots are . For , the positive polynomial roots are approximately , with their negatives completing the set. The distance from the right endpoint to the nearest polynomial root is ; central neighboring polynomial roots are separated on the larger scale . The small change of cosine near angles zero and explains the clustering.
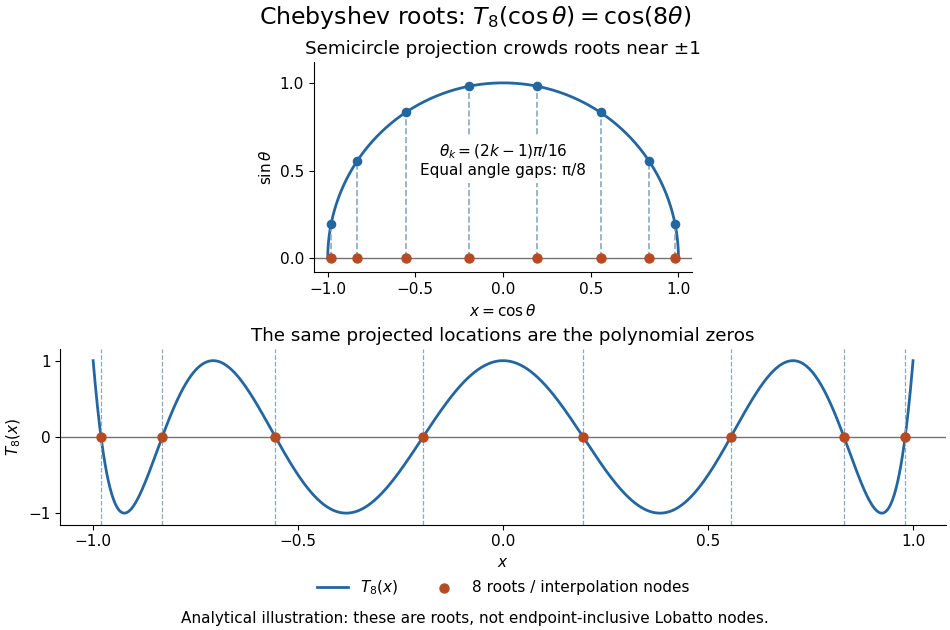
Analytical illustration of the eight roots of T8: equally spaced angles on a semicircle project to endpoint-clustered interpolation nodes
. Details. These polynomial roots supply interpolation nodes for a polynomial interpolation of polynomial degree at most . They differ from the Chebyshev-Lobatto nodes , which include both endpoints. This choice of polynomial roots has nodal polynomialThe monic Chebyshev extremal polynomial minimizes the uniform norm of this product among monic polynomials of polynomial degree on . Consequently, if has continuous derivatives, the usual polynomial interpolation error gives the useful boundThis optimizes the nodal factor in that bound, not the actual error for every function. Endpoint clustering helps control the large endpoint oscillations of equally spaced interpolation associated with Runge's phenomenon. The two node conventions and their geometric construction are discussed in Trefethen's authored text.[ref]
https://people.maths.ox.ac.uk/trefethen/ATAP/ATAPfirst6chapters.pdf. Lloyd N. Trefethen, Approximation Theory and Approximation Practice, Chapters 2–3 and Exercise 2.4: endpoint clustering, first-kind roots and polynomials
The same cosine substitution for polynomial approximation explains the weighted orthogonality:The endpoint singularities of the weight are integrable. Thus the Chebyshev polynomials are orthogonal polynomials for this weight, making coefficients in a least-squares polynomial in an orthogonal-polynomial basis separate cleanly. Their polynomial roots also give Chebyshev–Gauss quadrature, connecting polynomial interpolation to Gaussian quadrature.[ref]
Accuracy still depends on the target function. The absolute value function has a corner at zero, so the hypothesis requiring continuous derivatives in the displayed polynomial interpolation error bound fails. Endpoint clustering cannot remove that corner. A jump poses a stronger obstruction: polynomials are continuous functions, so they cannot converge in the uniform norm to a discontinuous function on the whole interval. Chebfun's documented examples show persistent overshoot for such jumps; these are a limitation of global polynomial interpolation, not a universal promise of rapid accuracy from Chebyshev polynomials.[ref]
https://www.chebfun.org/docs/guide/guide04.html#4.3. Chebfun development team, Chebfun Guide, §4.3: polynomial interpolation of discontinuous functions
Gaussian quadrature Created 2026-09-24 Updated 2026-10-14
Gaussian quadrature is a quadrature rule that chooses both sample locations and coefficients to achieve unusually high polynomial exactness. For a finite interval with , assume the integration weight is integrable and positive almost everywhere. DefineLet be the monic orthogonal polynomial of polynomial degree for the inner product : it satisfies for every polynomial of polynomial degree below . The polynomial roots of are distinct and inside ; take them as the nodes . Integrate the Lagrange cardinal polynomials to obtain . These coefficients are positive, andThe integration weight and the discrete coefficients play different roles: specifies the integral being approximated, while tell us how much each sample contributes.[ref]
https://dlmf.nist.gov/3.5#v. Nico M. Temme, NIST Digital Library of Mathematical Functions, §3.5(v), Gauss quadrature: nodes, coefficients and exactness
A proof outline explains the gain over simply integrating an arbitrary polynomial interpolation. Use polynomial division to write , with and . Orthogonality makes , and sampling at the polynomial roots of makes . The Lagrange cardinal polynomials recover exactly, so both expressions agree. Also , since has polynomial degree . This is the mechanism behind positive weights of Gaussian quadrature.
For a concrete two-node example, set on . The Legendre polynomial has polynomial roots . Its monic polynomial version has zero integral against both and , as required. Symmetry and exactness for the constant polynomial give . Thus the Gauss–Legendre instance of Gaussian quadrature isDirect evaluation on gives , exactly their integrals. For the polynomial , two samples therefore give exactly. But for the rule gives , whereas the integral is : the error is .
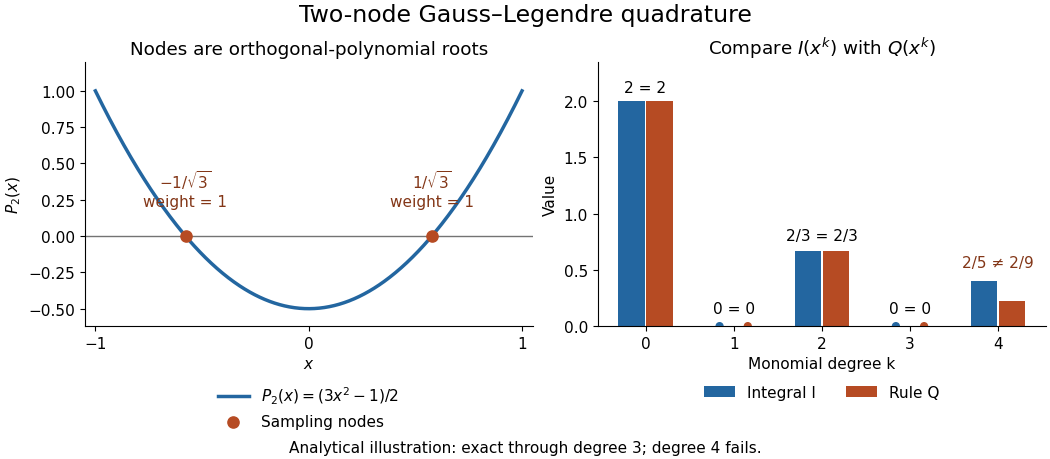
Analytical illustration of two-node Gauss–Legendre sampling: exact monomial integrals through degree three and failure at degree four
. Details. The ceiling is sharp for distinct real nodes under the positive-weight assumptions. Their squared nodal polynomial has polynomial degree , is zero at every sample, and has a strictly positive weighted integral. Thus no such quadrature rule integrates every polynomial of polynomial degree exactly. Nor does Gaussian quadrature integrate every nonpolynomial function exactly: the same two-node example gives , while .
Gaussian quadrature is useful when evaluations are costly and a modest polynomial captures the integrand well. More precisely, for a continuous function and any polynomial of polynomial degree at most , positivity and constant exactness giveThe uniform norm on measures the approximation between samples. This bound connects quadrature rule accuracy to uniform approximation, rather than promising an error from sample count alone. Corners, sharp unresolved features and roundoff error require their own assessment; the absolute value function example already shows why polynomial exactness is a qualified guarantee.
Finite difference method Created 2026-09-24 Updated 2026-10-03
A finite difference method replaces derivatives by algebraic combinations of values on a discrete space-time grid.
Gershgorin circle theorem Created 2026-09-24 Updated 2026-10-18
The Gershgorin circle theorem locates every eigenvalue of a square matrix using only its entries. A diagonal entry supplies a centre in the complex plane, and the sum of the off-diagonal absolute values in its row supplies a radius. Small off-diagonal couplings therefore confine the eigenvalues near the diagonal entries. This turns a global eigenvalue problem into a picture built one row at a time.
Precisely, let , with , and define the closed Gershgorin discsEvery eigenvalue of satisfies , including eigenvalues on the boundaries. No symmetry or diagonalizability is required. Despite the name, the theorem uses filled disks, not just their circular boundaries.[ref]
https://www.stat.uchicago.edu/~lekheng/courses/302/notes2.pdf. Gene H. Golub, CME 302: Numerical Linear Algebra, Lecture 2, §6, 2005; notes by James Lambers, edited by Lek-Heng Lim
The short reason is the triangle inequality. For a nonzero eigenvector with , choose with . The th row givesThus the largest eigenvector coordinate identifies a Gershgorin disc containing , even though that eigenvector need never be computed to use the bound.
This is useful when a full eigenvalue computation would be expensive: forming the Gershgorin discs needs one pass over the nonzero entries of a sparse matrix. If lies outside every Gershgorin disc, then is an invertible matrix, since zero is not an eigenvalue. The condition is exactly in every row, namely strict diagonal dominance. This connects diagonal dominance to solvability of a linear system; the inverse infinity-norm bound from diagonal dominance adds a quantitative bound. It is a sufficient test: failure to exclude zero does not prove singularity.
For a concrete symmetric matrix, takeThe three Gershgorin discs have centres and are pairwise disjoint. The finite-dimensional spectral theorem makes the eigenvalues real, so their possible locations reduce to the intervals , , and . Gershgorin eigenvalue counting gives exactly one eigenvalue in each. Independently, the characteristic polynomial iswhose numerical polynomial roots are , , and , rounded to six decimal places. All are positive, as Gershgorin bounds for symmetric matrices already guarantee without finding those polynomial roots.
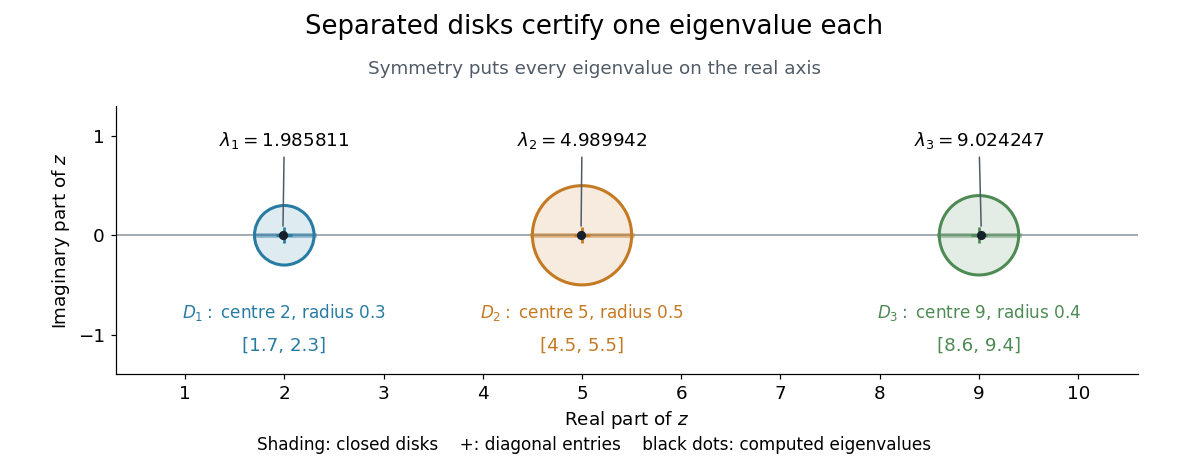
Three separated Gershgorin discs, each containing one real eigenvalue of the symmetric example
. Details. S. Gerschgorin published the result in 1931 in Über die Abgrenzung der Eigenwerte einer Matrix, in the Bulletin de l'Académie des Sciences de l'URSS, issue 6, pages 749–754. The original paper's §2 states both eigenvalue inclusion and counting in separated groups of Gershgorin discs; §3 already discusses column bounds and transformations preserving the eigenvalues. Thus both the localization picture and ways to sharpen it were part of the original development.[ref]
https://www.mathnet.ru/php/getFT.phtml?jrnid=im&paperid=5235&what=fullt&option_lang=eng. S. Gerschgorin, Über die Abgrenzung der Eigenwerte einer Matrix, 1931, pp. 749–754; original German paper in the journal archive
Discrete Fourier transform Created 2026-09-24 Updated 2026-10-18
The discrete Fourier transform turns a finite list of samples into the weights of its discrete Fourier modes. The goal is to reveal a simple oscillatory recipe hidden in complicated-looking data, while retaining enough information to reconstruct every sample exactly. In signal processing, those weights identify sampled frequencies and wave phases; in numerical analysis, they simplify circular convolution and the discrete sine transform Poisson solver.
Start with eight real samples, indexed by :Writing , the actual list isThe discrete Fourier transform recovers the recipe asThe constant contributes ; the cosine contributes ; the half-sized sine contributes and . All other coefficients vanish exactly. The imaginary coefficients carry the sine's wave phase, which a plot of absolute values alone would hide.
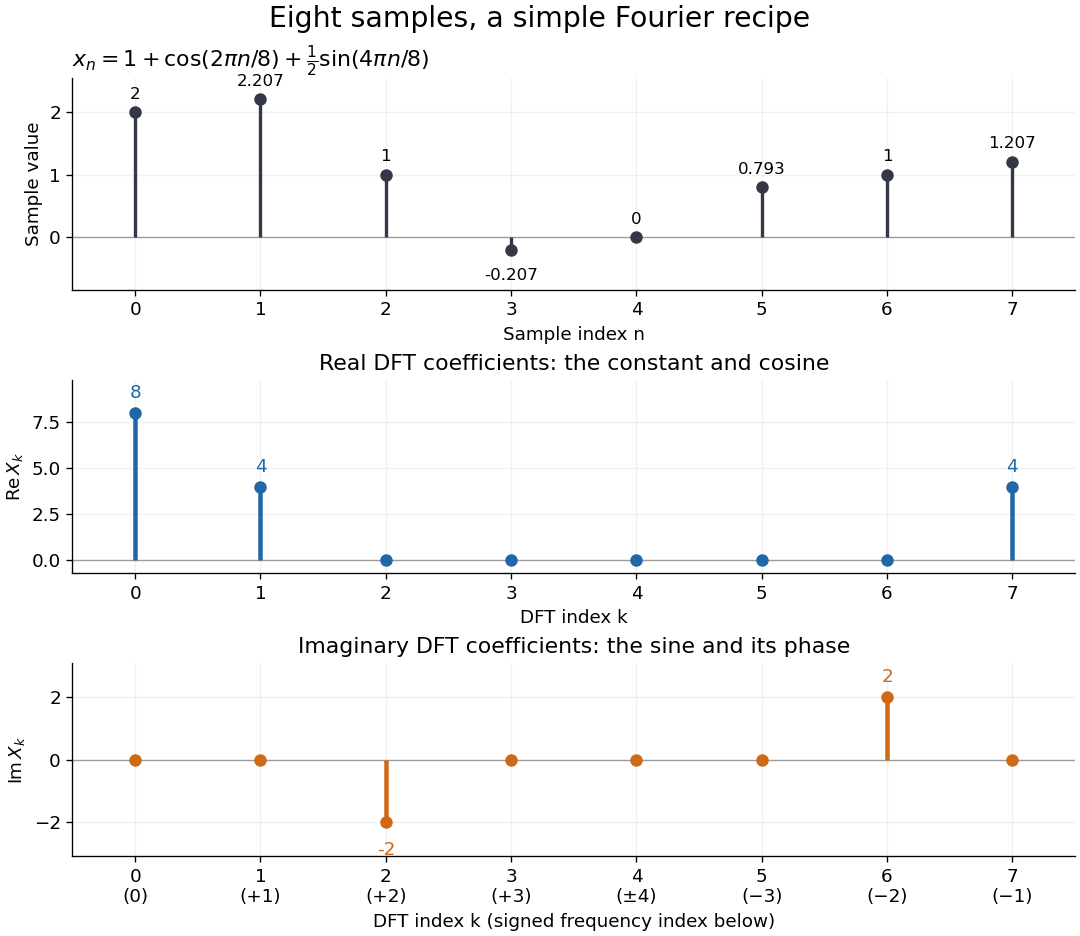


Precisely, for a positive integer and a vector , the forward discrete Fourier transform and inverse discrete Fourier transform used here areThus the forward exponent has a minus sign and no scale factor; the inverse exponent has a plus sign and the factor . The coefficients in the reconstruction are , rather than . In the example, , the pair reconstructs the cosine, and the pair reconstructs the half-sized sine. These conventions agree with the scaled Fourier coefficients in MIT's authored notes.[ref]
https://ocw.mit.edu/courses/6-02-introduction-to-eecs-ii-digital-communication-systems-fall-2012/06d7972059805d20e6a7db3a52ec23f2_MIT6_02F12_chap13.pdf. Hari Balakrishnan, Christopher Terman, and George Verghese, MIT 6.02 notes, Chapter 13, equations (13.15)–(13.16), 2012
The proof idea is orthogonality of roots of unity: for integers ,Distinct discrete Fourier modes cancel in this finite geometric series. Substituting the forward formula into the inverse discrete Fourier transform leaves only the desired sample. The same orthogonality makes the normalized discrete Fourier modes an orthonormal basis and gives the discrete Parseval identity, in the present convention,For the eight-sample example, direct squaring gives , while , so . This identity preserves the squared L2 norm after accounting for normalization. The existing discrete Parseval identity instead scales the forward discrete Fourier transform by , producing a unitary matrix and equal squared L2 norms without the factor .
For real input, discrete Fourier conjugate symmetry pairs positive and negative frequencies. The label is a residue modulo : when represents the same discrete Fourier mode as , since . It therefore represents negative frequency cycles per sample. If samples are seconds apart, the corresponding signed frequency is cycles per second. Similarly, index represents , while index is its own negative modulo .
The discrete Fourier transform is an invertible map between two finite vectors. The continuous Fourier transform instead describes a function on the real line by an integral over a continuous frequency variable. A finite list of samples does not determine the full continuous frequency spectrum: aliasing of discrete Fourier modes already supplies distinct waveforms with identical observations. Applying the inverse formula at arbitrary integer indices gives the periodic extension of a finite sequence, repeating the recorded block every samples. This is a property of that representation, rather than evidence that the physical signal repeats beyond the recording. Laurent Demanet's MIT notes place the discrete Fourier transform alongside the continuous Fourier transform and Fourier series to explain the role of sampling and repetition.[ref]
https://math.mit.edu/icg/resources/teaching/18.330/18.330-Mar21.pdf. Laurent Demanet, Introduction to Numerical Analysis, MIT 18.330, §§6.2–6.3, pp. 57–60, March 22, 2012
The beauty is that a change of basis exposes cancellation and structure without losing data. Direct evaluation needs sums of terms; a Fast Fourier transform computes the same discrete Fourier transform with far less work. Computational speed and the mathematical meaning of the coefficients are separate questions.
There are unlisted articles, also show them or only show them.