
Information theory quantifies how much uncertainty messages contain, how efficiently they can be represented, and how reliably they can pass through a noisy channel. Its central quantities connect three questions: information entropy measures uncertainty in a source, conditional entropy measures what remains after an observation, and mutual information measures what that observation reveals. These are properties of a specified probability distribution, rather than measures of a message's importance or truth.
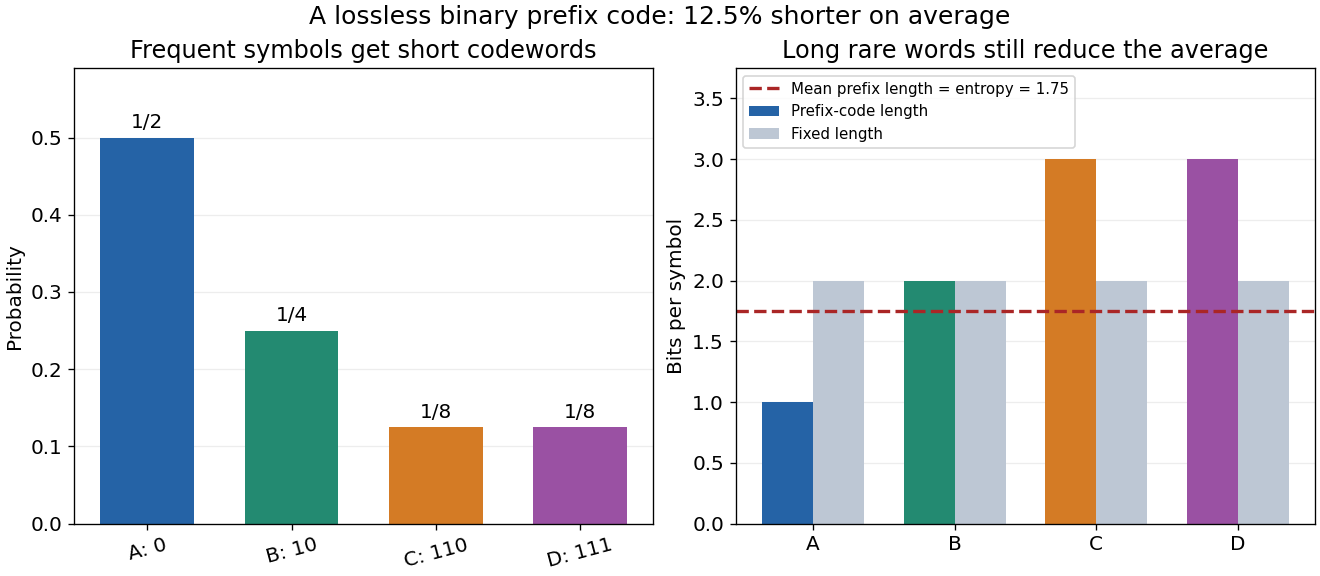
For a concrete source, suppose symbols have probabilities . A fixed-length binary representation needs two bits per symbol. Instead assign the prefix code , , , . Reading from left to right gives an unambiguous decoding because no codeword begins another. The expected value of the length isThis saves an average of of a bit per symbol, or of the fixed-length representation, with no loss of symbols. The lengths are exactly , so the average equals the source's Shannon entropy. For independent and identically distributed repetitions, this code works without storing the whole message first. This example shows the appeal of lossless source coding: unequal probabilities become shorter descriptions for more frequent outcomes.
Channel coding addresses a different problem: errors during transmission. A shorter representation removes predictable structure; an error-correcting representation adds carefully chosen structure that helps recover corrupted symbols. Shannon's source coding theorem and the Shannon second coding theorem identify limits for these respective tasks under their hypotheses. The beauty is that source details and hardware details can meet through a small number of mathematical quantities, notably information entropy and channel capacity.
Claude E. Shannon's A Mathematical Theory of Communication appeared in the Bell System Technical Journal in July and October 1948. Its introduction separates the engineering problem of reproducing messages from their semantic meaning; subsequent sections develop probabilistic source models, noiseless coding, and transmission with noise. It also acknowledges earlier work by Harry Nyquist and Ralph Hartley.[ref]
Probability theory describes uncertainty through a probability space: possible outcomes form a sample space, observable questions are events, and a probability measure assigns them numbers between zero and one. The Kolmogorov axioms make those assignments consistent. They let us combine information about several events, update it through conditional probability, and study random variables without listing every possible outcome separately.
For example, roll two dice whose results are independent random variables, each with a discrete uniform distribution on . There are 36 equally likely ordered outcomes. Only have sum seven, so that event has probability . The sum itself is not uniformly distributed: sum two has only one outcome. Choosing a probability distribution for the elementary outcomes is part of the model; equal likelihood does not follow merely from counting the named possibilities.
The subject becomes especially useful when complete outcome lists are enormous or infinite. Independence turns a joint calculation into simpler pieces, expected value summarizes a random variable, and the law of large numbers explains how averages can become predictable even when individual observations are uncertain. The central limit theorem describes the scale and shape of many remaining fluctuations. These are distinct claims: a small variance of an average does not make every observation close to its expected value.
There is a satisfying unity here: dice, hidden causes, and Brownian motion all use the same rules for events and conditional probability. A model still needs justification. Its exact deductions describe what its assumptions imply; comparison with observations belongs to statistical inference.
Total variation distance asks how much two probability distributions can disagree about the same event. For probability measures on one measurable space , its definition isThe supremum ranges over all measurable sets, so guarantees that every yes-or-no prediction has probability error at most . This metric takes values between zero and one; it is zero exactly when the two probability measures agree. This makes it useful for comparing a sampling algorithm's output with its target probability distribution, and for defining the mixing time of a Markov chain.
On a finite set, add the excess probability mass wherever exceeds . That excess is also half the sum of all absolute differences:The last expression reveals the common probability mass that the two probability distributions can share.[ref]
Markov Chains and Mixing Times, second edition by David A. Levin and others. §4.1, Proposition 4.2 and Remark 4.3, printed p. 48; §4.2, equation (4.13), printed p. 51
The coupling characterization of total variation distance turns this overlap into an actual joint construction; minimum sum of errors in a simple hypothesis test gives it a statistical interpretation. One quantity connects probability bookkeeping, comparison of sampling methods, and the limits of a statistical test.For a convex function satisfying , the f-divergence between probability distributions and iswhere , , and the integrand uses the lower-semicontinuous perspective convention at .
Survival analysis studies the probability distribution of a survival time: how long from a specified starting point until a specified occurrence. The occurrence need not be death. It might be a machine's first breakdown, a customer's first renewal, or a person's recovery. The meaning of "survival" is simply that the chosen occurrence has not happened yet. Both the starting point and the outcome must be defined before interpreting a survival function.
The distinctive difficulty is incomplete observation. A machine still working when observation stops supplies a lower bound on its survival time, rather than an observed breakdown time. Right censoring lets us retain that information. The Kaplan–Meier estimator estimates a survival function using the changing risk sets, without choosing an exponential distribution or another particular survival distribution. A hazard function instead describes the current event rate among those still event-free; its cumulative hazard connects those local rates to the whole survival function.
This framework turns different follow-up lengths into usable evidence about waiting times. It supports questions such as the chance of remaining event-free for another year, or the restricted mean survival time within an observed horizon. Lu Tian's Stanford teaching materials introduce these interpretations in Survival Distributions, Hazard Functions, Cumulative Hazards, Section 1.1.
Causal inference studies effects of interventions by comparing potential outcomes under different treatments.
The Lasso minimizes regression error plus an penalty.
A symmetric function is a positive-semidefinite kernel when every finite Gram matrix is positive semidefinite.
The power spectrum describes how the variance of a random field or stationary process is distributed over spatial wavenumber or temporal frequency.
For equal hoop and bead masses, with the hoop suspended from its circumference, the quadratic mass and stiffness matrices are proportional toThe dimensionless squared frequencies are the roots of , namely and .
A positive integer is a sum of two integer squares exactly when every prime factor congruent to modulo has even exponent in its prime factorization.
For positive integers , the Euclidean algorithm repeatedly performs division with remainder: write with , then replace by until the second entry is zero. The final nonzero entry is their greatest common divisor. A remainder preserves the set of common divisors: an integer divides and exactly when it divides and . The positive remainders strictly decrease, so the calculation terminates.
The complete calculation for and isHence . The fraction reduces to by dividing numerator and denominator by that common factor. The same remainder calculation has a geometric interpretation: remove squares from a -by- rectangle, then repeat on the remaining strip. Each division step records how many equal squares fit and the width of the new strip.
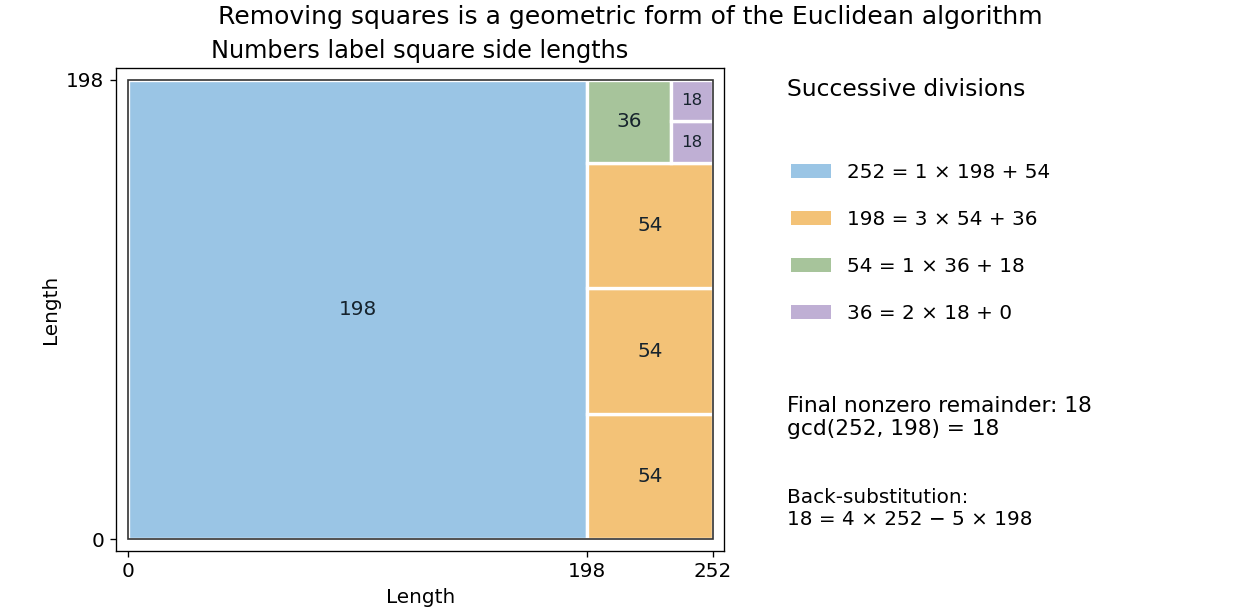
Successive square removals record the Euclidean algorithm for 252 and 198
. Details. The procedure does more than test individual divisors. Each step replaces the whole common-divisor problem by a smaller equivalent one. Euclid's Book VII, Proposition 2 describes the corresponding repeated-subtraction construction; batching those subtractions into division with remainder gives the present formulation. [ref]
https://mathcs.clarku.edu/~djoyce/java/elements/bookVII/propVII2.html. Euclid, Elements VII.2, greatest common measure
For coprime integers with , the multiplicative order is the least positive integer such thatIt counts the distinct powers in the cyclic subgroup generated by the congruence class of . Thus it is an order of a group element in the unit group .[ref]
A Computational Introduction to Number Theory and Algebra by Victor Shoup. pp. 153 and 156–157, Theorem 6.29
For example, the modular exponentiation , starting at , produces . The first return to one takes three steps, so . Starting at the congruence class three and repeatedly multiplying by two instead gives : these are the other three units modulo seven, outside the cyclic subgroup generated by two.
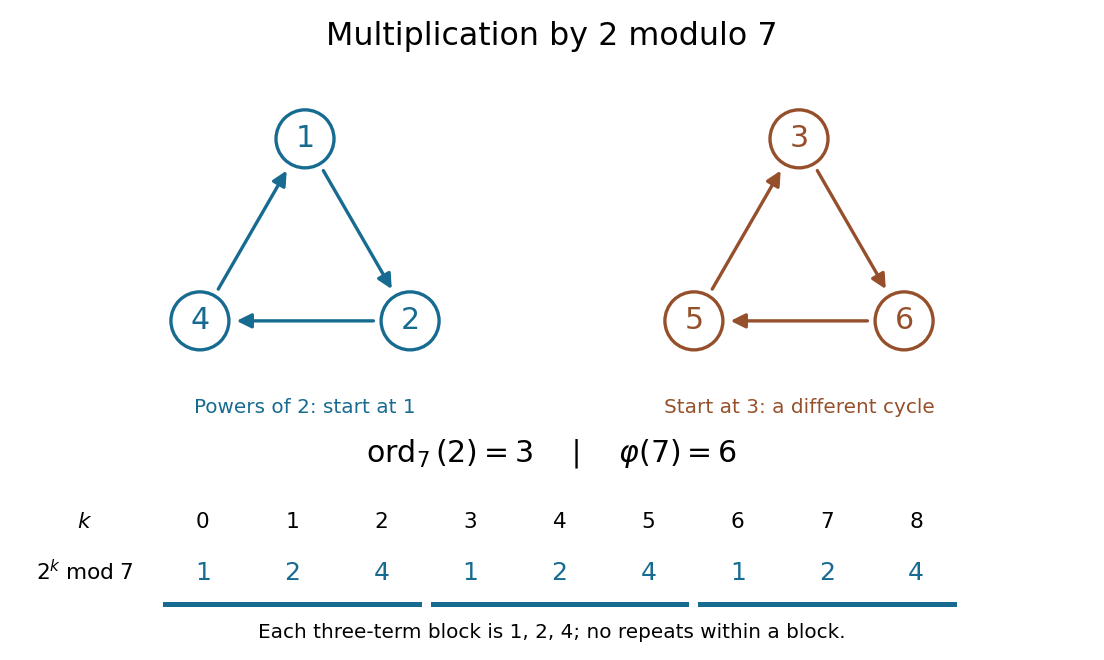


Euler's theorem guarantees a return to one at exponent , where is Euler's totient function. Thus the multiplicative order exists for every unit.[ref]
Euler’s Theorem by Keith Conrad. p. 1, Theorem 1.2; pp. 2–3, permutation of the units and cancellation
In fact,By Lagrange's theorem, the size of the cyclic subgroup divides the size of the unit group, which is Euler's totient function. For two modulo seven, this is ; the multiplicative order need not equal Euler's totient function. If , its multiplicative order is one.The coprime integers hypothesis is necessary: if , any common divisor of and divides one. For instance, powers of two modulo eight give , with no positive-exponent return to one. This sequence eventually settles, but two has no multiplicative order modulo eight.
For an integer , the Carmichael function is the exponent of a finite group for the unit group : the least positive integer for whichHere the greatest common divisor condition selects the units. Euler's totient function counts them; the Carmichael function gives their least common return exponent.[ref]
Modulo eight, the units are , and their squares are all congruent to one. Their multiplicative orders are , so although . Modulo fifteen, the units have multiplicative orders . For example, the powers of two return through . Thus although ; the multiplicative order of four is only two.
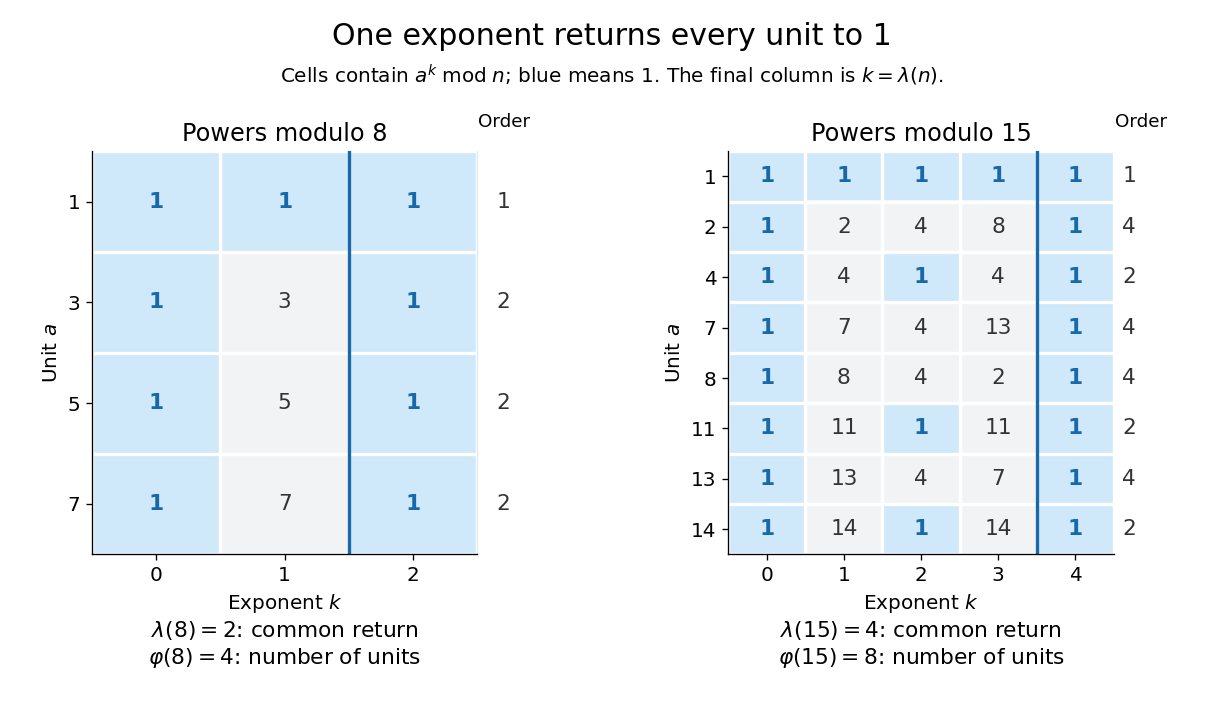
Individual unit orders divide the least common return exponent modulo eight and fifteen
. Details. 
The three quantities are related byA common return exponent must be a multiple of every multiplicative order, hence of their least common multiple. Conversely, that least common multiple makes every unit return to one. Lagrange's theorem makes each multiplicative order divide the group order , proving the final divisibility. The Carmichael function applies to all units at once, while the multiplicative order concerns a chosen unit.
For the prime factorization with distinct prime numbers and , the formulas areThese are least common multiples, rather than products: . The convention handles the trivial case separately.[ref]
The Chinese remainder theorem for unit groups explains the least common multiple: a power returns to one in every prime power component exactly when it is a multiple of each component's exponent of a finite group. For an odd prime power, the unit group is a cyclic group of group order . For , the unit group modulo is a direct product of groups , generated by the classes of and five, so its exponent of a finite group is .[ref]
A Computational Introduction to Number Theory and Algebra by Victor Shoup. Section 7.5, pp. 203–205, Theorem 7.28 and its proof
This gives a uniform reduction for modular exponentiation: for a unit and a nonnegative integer , reduce modulo . For example, because . The unit hypothesis matters: , but . Computing the formula assumes the prime factorization is available. The same common-exponent viewpoint explains Carmichael numbers: a composite number passes the Fermat primality test for every unit base exactly when . For example, .
There are unlisted articles, also show them or only show them.