Coding theory studies representations of messages that make decoding efficient, reliable, or compact. In channel coding, messages are mapped to separated codewords, so a corrupted word can still be recognized as coming from one particular message. In lossless source coding, a prefix code instead assigns short descriptions to frequent symbols. The objectives differ, but both exploit structure in the set of allowed words.
The simplest error-correction example sends as and as . If the receiver sees , at most one bit flip is consistent with , whereas two flips would be needed to obtain it from . A repetition code therefore recovers the original by taking the majority function of the received bits. The Hamming distance between the valid codewords is three: the spaces of one-error outputs around them do not overlap. This turns error correction into geometry in a discrete space.
The central tradeoff is between code rate and minimum distance. Additional separation makes correction possible but leaves fewer words available for messages at a fixed length. The Hamming bound counts disjoint error neighborhoods, while linear codes turn encoding and error detection into computations with matrices over finite fields. These connections explain why combinatorics, linear algebra, and probability theory all enter the subject.
Richard W. Hamming's Error Detecting and Error Correcting Codes appeared in the Bell System Technical Journal in April 1950, pp. 147–160. Its introduction motivates automatic correction through failures in digital computing, and its constructions go beyond detecting an error to identifying and correcting its location.[ref]
https://zoo.cs.yale.edu/classes/cs323/doc/Hamming.pdf. Hamming, Error Detecting and Error Correcting Codes, 1950
List decoding returns all codewords within a specified Hamming distance of a received word, rather than insisting on a single answer. For a block code , a radius- list isThe code is -list-decodable when every received word has at most such codewords. This is a worst-case bound over received words, not an average list size.
For and received , radius one gives the singleton , while radius two gives both codewords. Unique decoding cannot guarantee correction beyond half the minimum distance, but a bounded list can remain informative beyond that radius. An efficient list-decoding algorithm must find the candidates in reasonable time; the combinatorial list bound alone does not supply an algorithm. Extra information or a later check may then choose one candidate.
A list-decoding algorithm takes a received word and a radius , and outputs every codeword of a specified block code with Hamming distance . Correctness requires both completeness and exclusion of more distant words. The running time must also accommodate the output size.
A direct algorithm enumerates all codewords, computes each Hamming distance in symbol comparisons, and retains the qualifying words. For a binary code with codewords, this costs , even if the final list is short. Efficient list decoding exploits algebraic or combinatorial structure instead. For Reed-Solomon codes, polynomial interpolation followed by factorization supplies candidates beyond the unique decoding radius; the candidates are finally checked against the received word.[ref]
Morse code encodes characters using short and long signals, conventionally dots and dashes, together with timed gaps. In International Morse code, a dash lasts three dot units; gaps within a character last one unit, between characters three, and between words seven. Thus character boundaries are part of the encoding.
For example, is three dots and is three dashes. If gaps are erased, the dot-dash strings alone are not a prefix code: the code for , one dot, is a prefix of that for , two dots. This makes Morse code a useful example of how a communication code can rely on timing as well as symbol choices.[ref]
https://www.itu.int/rec/R-REC-M.1677. Recommendation ITU-R M.1677, International Morse code, Annex 1
Error detection and correction adds structured redundancy to messages so that corruption can be noticed or repaired. For a block block code with minimum Hamming distance , all patterns of at most symbol changes are detectable, and all patterns of at most changes are uniquely correctable.
The correction bound follows because radius- Hamming balls around distinct codewords are disjoint when . For example, encoding a bit as or gives distance three, so majority decoding corrects one flipped bit. A single parity bit detects one flipped bit but cannot identify its position; detection and correction require different amounts of information.
Unique decoding recovers a single codeword from a corrupted received word, with a guarantee that the transmitted codeword is the only candidate within the allowed error radius. If a block code has minimum distance , then every pattern of at mostsymbol errors can be corrected in principle. Indeed, if two codewords were both within Hamming distance of , the triangle inequality would put them at distance at most , a contradiction.[ref]
Bridging Shannon and Hamming: List Error-Correction with Optimal Rate by Venkatesan Guruswami. section 1, minimum-distance barrier
The repetition code has , so one error is correctable: identifies . Two errors can produce , which lies closer to ; no decoder can guarantee success for all two-error patterns. The distance bound proves uniqueness, but does not itself give a fast decoding algorithm.
An erasure is a missing or explicitly flagged symbol of a transmitted codeword; its position is known to the decoder. An error instead replaces a symbol by an incorrect value without revealing its location. This distinction changes how much redundancy is needed.
A block code of minimum distance uniquely corrects every erasure pattern of size at most . Indeed, two different codewords agreeing at all unerased positions could differ in at most the erased positions, contradicting their distance of at least . Conversely, erasing all differing positions of a minimum-distance pair makes that pair indistinguishable.
For the binary even-parity code , one erased bit is recovered from the other two: the missing value is their sum modulo two. One arbitrary unflagged error is only detectable, because the minimum distance is two. More generally, errors and erasures are uniquely correctable whenever .
A checksum is a short value calculated from a data block and stored or transmitted with it to help detect corruption. The receiver recomputes the checksum from the received data and compares it with the supplied value. Different data blocks can have the same checksum, so a successful comparison does not prove equality.
For example, summing four bytes modulo gives a one-byte checksum. The bytes give ; changing the first byte to changes the checksum to , whereas exchanging two bytes leaves it unchanged. The particular checksum determines which error patterns are detected.
The Internet checksum groups bytes into 16-bit words, adds them with end-around carry, and complements the result. End-around carry adds an overflow bit back into the low end of the sum. Verification includes the checksum field and expects a sum with all bits set. The covered fields depend on the protocol; IPv6 has no header checksum.[ref]
Computing the Internet Checksum (RFC 1071). Section 1: generation, verification, and end-around carry
[ref]A cyclic redundancy check represents a bit string as a polynomial over the field with two elements and uses a polynomial remainder as checking information. Agree on a monic polynomial of polynomial degree with constant term . Under the basic systematic convention, a message polynomial producesHere , and addition equals subtraction over the field with two elements, so divides the transmitted polynomial . The receiver tests the polynomial remainder on division by the same CRC generator polynomial.
For example, and give and . If an error polynomial changes to , the error is undetected exactly when divides . Thus the CRC generator polynomial controls which bit-error patterns the cyclic redundancy check detects. This basic convention fixes the mathematics; implementations can additionally specify initial register contents and bit-order conventions.
The CRC generator polynomial is the agreed divisor used in a cyclic redundancy check. In the basic binary convention it is a monic polynomial of polynomial degree with . A nonzero error polynomial goes undetected exactly when .
This algebra gives useful detection guarantees. A single changed bit has and cannot be divisible by when . More generally, suppose the first and last changed bits span at most consecutive positions. Write with and . Since and are coprime polynomials, would imply , contradicting the polynomial degree bound. Every such error pattern is therefore detected.
If divides , every error changing an odd number of bits is also detected: its error polynomial satisfies , whereas every multiple of has value zero at .
Error correction recovers a transmitted or stored message despite specified corruption. A decoder uses the redundancy of an error-correcting code to select the original codeword, or reports failure if the available information does not determine one reliably.
For the repetition code , , a received is corrected to by choosing the closest word in Hamming distance. This guarantees recovery after at most one bit flip, but two flips can produce a wrong choice. If corrupted positions are known, they are erasure, which are easier to repair: a code of minimum distance can recover from any erasures.
Channel coding represents messages with codewords chosen to withstand transmission errors. An error-correcting code deliberately supplies redundancy, so a receiver can distinguish nearby corrupted outputs and recover the message. Lossless source coding instead removes predictable redundancy; practical communication can use both operations. The Shannon second coding theorem relates achievable rates on a discrete memoryless channel to its channel capacity.
A deterministic fixed-length channel code consists of a channel encoder and a channel decoder . It represents possible messages by length- input codewords for a communication channel, and estimates the message from the resulting output word. Its code rate is bits per channel use. The maximal decoding error probability requires reliable recovery of every message, while an average error criterion depends on the chosen message probability distribution.
Random coding constructs a channel code by sampling its codewords from a specified probability distribution and bounding the expected decoding error over that ensemble. If the expected average error is at most , at least one deterministic codebook has average error at most ; otherwise every book would exceed the expectation bound. This is the probabilistic method applied to communication codes.
For independently uniform binary codewords, a fixed competing word falls in any received word's radius- Hamming ball with probability . The union bound over competing messages, together with a bound on excessive channel noise, yields the basic random-coding error estimate. Expurgation of a codebook can then convert average-error control to maximal decoding error probability with negligible loss of asymptotic rate.
Expurgation discards messages with unusually high conditional decoding error. If a codebook with equally likely messages has average error at most , at least messages have individual error at most , by Markov's inequality. Retaining those messages and restricting the decoder's candidates gives a codebook with maximal error at most , provided removal of candidates cannot spoil a previously successful decoding. This is the case for bounded-distance decoding with errors on ambiguity, and for a decoder that retains its former decisions whenever the decoded message remains.
For a sequence of block lengths , halving a book changes its logarithmic rate by , which tends to zero. Thus a vanishing average-error bound from a random coding construction can be converted into a vanishing maximal decoding error probability at the same limiting rate. The probabilistic construction first supplies a deterministic book with sufficiently small average error; expurgation is a subsequent deterministic step.
Code encoding maps messages injectively to codewords. For a dimension- linear code with generator matrix , the standard encoder maps to . The redundancy makes error detection and recovery possible; for a Reed-Solomon code, encoding can instead evaluate a message polynomial at the chosen field elements.
A systematic encoder retains the message symbols unchanged in designated coordinates of its codeword and calculates the remaining check symbols. For a linear code, choosing an invertible set of columns of a generator matrix and changing its row basis gives this form.
For a length-, dimension- cyclic code with generator polynomial of degree , let the message polynomial satisfy . Subtracting the remainder upon polynomial division by makes the displayed word divisible by . The remainder has degree less than , so the highest coordinates retain the coefficients of . This gives systematic encoding without losing any message information.
For codes over an alphabet of size , the greedy packing argument gives , where . A maximal distance- code has radius- Hamming balls covering the entire space; counting their union proves the lower bound. The linear refinement is the Varshamov bound for linear codes.
// Target: algebra.bigb
A binary code rate is guaranteed with correction of every error pattern of Hamming weight at most when and . Choose minimum Hamming distance . The Gilbert–Varshamov bound and entropy bound for a Hamming ball give at least codewords. To deduce vanishing error probability for a binary symmetric channel with crossover probability , use strict inequality in the rate condition and a correction radius ; the weak law of large numbers then controls the tail. Correcting exactly the mean number of errors does not by itself ensure reliable transmission.
// Target: algebra.bigb
For , take logarithms of the Gilbert–Varshamov bound and apply the Hamming ball volume exponent. The Varshamov bound for linear codes gives the same achievable lower bound within linear codes for prime-power .
// Target: algebra.bigb
For a prime-power alphabet size , a linear code exists if . Choose parity-check columns successively, avoiding combinations of at most earlier columns. Fewer than vectors are forbidden, so such a choice is possible. No set of at most columns is dependent, and the resulting kernel has dimension at least .
// Target: probability-and-statistics.bigb
A codeword is a member of the specified set of words used to encode messages. For a linear code specified by a parity-check matrix , the codewords are precisely the vectors satisfying . The minimum distance between distinct codewords controls error correction.
The codeword length is the number of alphabet symbols in a codeword. For a binary word it counts bits; in a prefix code, it is the depth of the corresponding leaf in the code tree.
// Target: algebra.bigb
A cipher is a pair of keyed algorithms that maps a plaintext to a ciphertext and recovers the plaintext from the ciphertext when supplied with the appropriate key.
A cryptographic key is a parameter selecting a particular transformation from a family of algorithms in cryptography. For an encryption family, correctness requiresfor every allowed plaintext and appropriate encryption/decryption keys. In symmetric-key cryptography, the communicating parties share a secret key. In public-key cryptography, the public encryption or verification key is paired with a private decryption or signing key.
For a one-bit example, and recover the message because applying exclusive or twice with the same bit cancels it. The one-time pad extends this to a uniformly random independent key as long as the message. Its secrecy depends on the key distribution and use, not on hiding the XOR algorithm. The number of possible keys gives a brute-force search space, but key length alone does not establish the security of a cryptographic construction.
A block code assigns source messages to words of a fixed length over an alphabet. Its codewords form a subset of that fixed-length word space; a binary block code uses the two-symbol finite field .
A binary code is a set of distinct words in whose minimum pairwise Hamming distance is . Here is the block length and is the number of codewords.
An error-correcting code is a set of codewords chosen with enough separation to recover a transmitted message after specified errors. For equal-length words and bit-flip errors, separation is measured by Hamming distance. If the minimum distance is , any nonzero pattern of at most flips changes a valid word into an invalid word and can therefore be detected. Every pattern of at most flips can be corrected by choosing the unique nearby codeword.
The distinction matters. A distance-two code detects a single flip but need not locate it; a distance-three code corrects a single flip. The triangle inequality explains the correction threshold: a received word within distance of two distinct codewords would put those codewords within distance , a contradiction. Actual decoders also need an efficient way to find the nearby word; a parity-check matrix and syndrome decoding exploit the structure of a linear code to do this.
The name Golay code refers to closely related exceptional linear codes. The binary Golay code has parameters : length twenty-three, dimension twelve over , and minimum distance seven. Adding an overall parity coordinate gives the extended binary Golay code . There is also a ternary code, whose extension has parameters ; specifying the alphabet and extension avoids ambiguity.[ref]
Golay codes in the Error Correction Zoo. Binary and ternary Golay code entries, parameters and perfect-code properties
The binary length-twenty-three code corrects three errors. A radius-three Hamming ball contains words. Its disjoint decoding balls therefore cover all received words exactly: this is a perfect code. The extended code has a larger minimum distance, but its radius-three balls do not fill the entire larger word space. These arithmetic properties explain why the codes are useful beyond their historical names.
A binary repetition code represents one bit by repeating it times, using codewords and . Their Hamming distance is , and the code rate is . For odd , the majority function recovers the input whenever fewer than half the positions have flipped. Even allows a tied vote, so a decoder must specify how it handles that case.
For , the received words decode to zero; decode to one. The decoder therefore corrects every single flip. This guarantee concerns the number of flipped positions, independent of any probabilistic model.
If each position passes independently through a binary symmetric channel with crossover probability , a decoded error requires at least two flips. The binomial distribution givesAt , the uncoded error probability is , while the three-bit code's decoded error probability is . This improvement costs three transmitted bits per message bit. For , ; for , one should first exploit the known tendency to invert symbols rather than applying the same majority rule blindly.
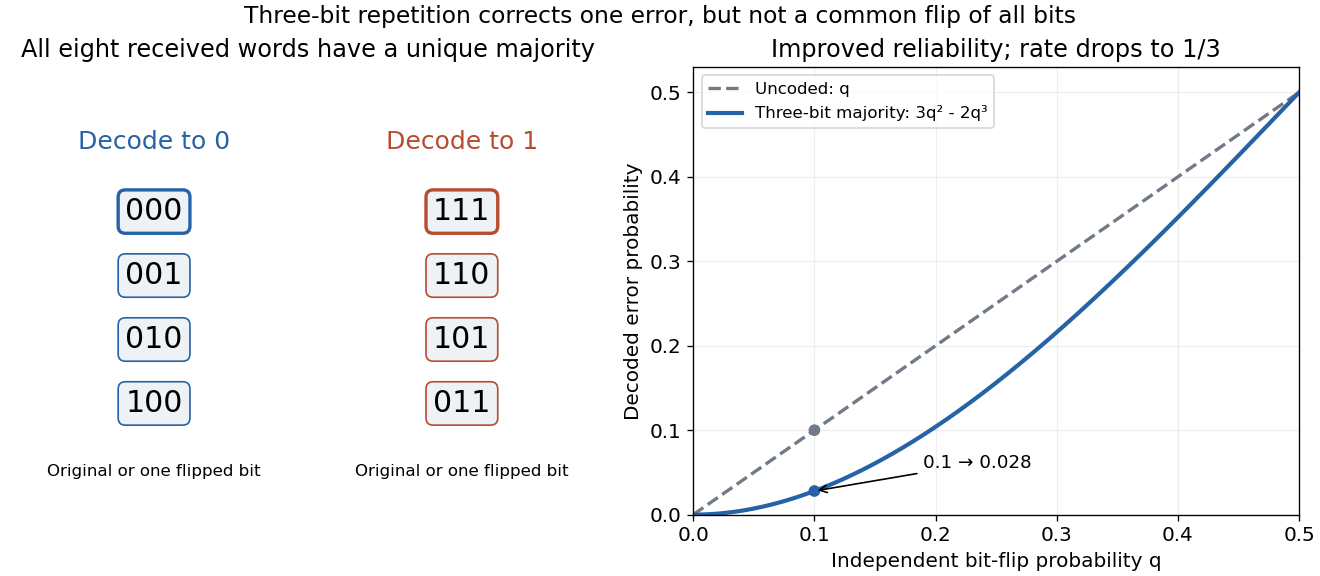
Independent flips are an essential assumption for the displayed formula. If a single common disturbance flips all three positions together with probability , repetition provides no improvement. More efficient error-correcting codes distribute redundancy across larger message blocks; repetition is useful as a transparent example of the geometry and the reliability–rate tradeoff.
The Hamming distance between two equal-length words is the number of coordinates in which they differ.
The Hamming space of length over a finite field is the set equipped with Hamming distance, the number of coordinates at which two words differ. The Hamming weight of a word is its distance from zero.
This is the maximum Hamming distance between the characteristic vectors of members of a set family. In a down-set, one can replace a pair by disjoint subsets with the same union, so the maximum distance equals the largest size of a union of two members. A t-intersecting family has diameter at most .
On binary words of length , normalized Hamming distance is the fraction of differing coordinates. Unlike unscaled Hamming distance, it makes the Hamming cubes a Lévy family under uniform probability measures.
The Hamming cube is , or equivalently , equipped with Hamming distance. Under its uniform probability measure, the distance from a fixed vertex has the binomial distribution with parameters . This converts geometric ball sizes into probability tails.
An inclusion-maximal separated set of separation covers the Hamming cube by strict-radius balls. The Hoeffding lower-tail bound for Hamming balls then gives at least selected vertices. At this yields vertices, all separated by at least .
This Hamming distance on partitions identifies a group with its complement because exchanging the two group names does not change the partition. Complementation is an isometry of the ordinary Hamming distance, so minimizing over this two-element group action gives a quotient metric and preserves the triangle inequality. Negating a zero-one indicator is not complementation; with membership vectors, it is.
Suppose encodes the true partition and is a unit estimated eigenvector. Every coordinate of the wrong sign contributes at least to . Since this is at most , which is the squared Frobenius distance between the rank-one orthogonal projection matrices, the bound follows. Coordinates estimated as zero may be assigned consistently to either group.
The minimum distance of a code is the least Hamming distance between distinct codewords. For a linear code, translation invariance makes this equal to the least Hamming weight of a nonzero codeword.
The relative minimum distance of a length- code of minimum distance is . It expresses the guaranteed separation as a fraction of the block length.
// Target: algebra.bigb
The quantity is the largest cardinality of a length- code over an alphabet of size with minimum Hamming distance at least . The code need not be linear.
// Target: algebra.bigb
The Hamming ball of radius about a word is the set of words whose Hamming distance from is at most .
For , the exponential growth rate of a q-ary Hamming ball is . Stirling's formula gives the exponent of each summand , and the sum lies between its largest term and times that term. Above the entropy-maximizing radius fraction, the exponent is one.
// Target: algebra.bigb
For a uniform vertex of the Hamming cube, distance from a fixed vertex is the sum of independent Bernoulli random variables with parameter . The lower-tail Hoeffding inequality implies that the fraction of vertices at distance at most , , is at most . Strict-radius balls satisfy the same upper bound.
For , the number of binary words within Hamming distance of a fixed word is at most , with the binary entropy function in natural logarithms. In , each summand weight for is at least . Also , so . These two bounds give the approximate-recovery denominator in the list-decoding Fano inequality.
A code of minimum distance is perfect if its Hamming balls of radius partition the ambient word space. Every word then has a unique nearest codeword within the code's error-correction radius.
The length- binary Golay code is the cyclic code over generated byIt has dimension , minimum Hamming distance , and its radius- Hamming balls partition . Its parity extension has length , dimension , and minimum Hamming distance .
// Target: algebra.bigb
The extended binary Golay code is the parity extension of the length- binary Golay code. It is a self-dual code and a doubly even code, with minimum Hamming distance eight. Its radius-three Hamming balls are disjoint but do not cover its Hamming space; it is not a perfect code.
For a binary symmetric matrix with , the syndrome of an error relative to the column parity-check matrix is . An error of total Hamming weight at most three has at most one nonzero bit in one half. Test , each , , and each for weights at most three, two, three and two respectively. These identify , , and . For the extended binary Golay code, minimum Hamming distance eight guarantees that at most one such error exists.
Suppose a binary symmetric matrix satisfies , has one row of Hamming weight eleven and eleven rows of Hamming weight seven, and every sum of two distinct rows has Hamming weight six. Then generates a self-dual code. Its rows have weights twelve or eight; their mutual orthogonality makes every generated word doubly even. A weight-four word would have left-half weight one, two, three or four. The first two cases are excluded by the stated row weights; weight three would force to be a unit vector and hence to be a row of ; weight four would force . Thus weight four is impossible and the minimum Hamming distance is eight.
A root of the binary Golay generator polynomial has order , and the Frobenius endomorphism shows that are roots: . The BCH bound gives minimum Hamming distance at least five. The circular autocorrelation of the binary Golay generator makes its parity extension doubly even, excluding original weights five and six. The generator itself has Hamming weight seven, proving that the distance is exactly seven.
// Target: algebra.bigb
The polynomial identity , where , impliesEvery coefficient is the binary inner product of the coefficient vector of with one cyclic shift. Thus every such inner product is one. Appending a parity bit to the cyclic shifts gives mutually orthogonal weight-eight vectors, so orthogonal generators of doubly even codes applies.
// Target: algebra.bigb
For a code of length , size , and minimum distance over an alphabet of size , puncturing coordinates gives the Singleton bound
The Plotkin bound limits a code whose minimum distance is more than the average distance between unrestricted words. For a binary code with and even ,
Puncturing deletes specified coordinate positions from every codeword of a block block code. Puncturing one coordinate changes a length- code into a length- code; each pairwise Hamming distance decreases by at most one.
If the original minimum distance is at least two, deleting one position cannot merge distinct codewords, so their number is preserved and the new minimum distance is either or . For example, puncturing gives . For a linear code, one may puncture its generator matrix by deleting the corresponding column, though the dimension can fall if the original distance was only one. This differs from shortening, which first restricts a coordinate value and then deletes it.
Puncturing a code at one coordinate deletes that coordinate from every codeword. For a code of minimum distance , puncturing preserves its number of words and gives minimum distance or .
For messages in a finite additive group, a one-time pad encrypts as , where the key is uniform and independent of , as long as the message, and never reused. Then is uniform and independent of , giving perfect secrecy.
If two plaintexts are encrypted by adding the same one-time-pad key, subtracting the ciphertexts cancels the key and reveals the difference of the plaintexts. Redundancy in natural language or another structured message space can then reveal both messages, so a one-time pad must never reuse key material.
An encryption scheme has perfect secrecy when the ciphertext and plaintext are independent random variables, so observing the ciphertext does not change the plaintext's probability distribution.
If an interceptor knows that an additive one-time-pad ciphertext encrypts plaintext and wants it to decrypt as , replacing it byworks without knowing the key, since .
A secret-sharing scheme distributes shares of a secret so that authorized collections can reconstruct it while unauthorized collections reveal no information about it.
An threshold secret-sharing scheme issues shares: every collection of at least shares reconstructs the secret, while every collection of fewer than shares has a distribution independent of the secret.
Shamir's secret sharing distributes a secret in a finite field so that any of shares recover it, while fewer than shares reveal no information about it. Choose , distinct nonzero field elements , and independent uniformly distributed coefficients , independent of . Setand give participant the pair . Any shares determine by polynomial interpolation, hence determine . Fewer than shares have a distribution independent of ; this is Perfect secrecy of Shamir's threshold scheme.[ref]
How to Share a Secret by Adi Shamir. Pages 612–613: polynomial construction and threshold property
For example, over the finite field , a two-share threshold with secret and coefficient gives . The shares and recover and . Either share alone is compatible with every secret, and the uniform choice of makes its distribution independent of that secret.
In Shamir's secret sharing, observing any shares leaves the secret's prior distribution unchanged. In particular, the posterior distribution is uniform if the prior distribution was uniform; uniformity of the secret is not required for perfect secrecy.
To prove this, fix distinct nonzero evaluation points and a candidate secret . The evaluations impose independent linear equations on the random coefficients. The evaluation matrix has rank : its first columns form a Vandermonde matrix multiplied by a nonsingular diagonal matrix of nonzero evaluation points. Every observed share tuple therefore has exactly compatible coefficient tuples. Since the coefficients were independently uniform, its conditional probability isindependent of . Thus the shares and the secret are independent random variables, which proves perfect secrecy.[ref]
How to Share a Secret by Adi Shamir. Pages 612–613: interpolation argument for fewer than the threshold number of shares
A discrete memoryless channel models transmission through finite input and output alphabets using fixed conditional probabilities . For each input , these nonnegative numbers sum to one over the output symbols. Discrete refers to the symbols, and memoryless means that the noise of one use does not remember earlier uses.
For a fixed input word sent without feedback, the output law isThis is conditional independence of the outputs given the prescribed input word. It does not require an encoder to choose independent input symbols: the codewords of a block code deliberately impose relationships among them. Those relationships let a decoder distinguish possible messages after noise.
The binary symmetric channel and binary erasure channel make two different memoryless noise models with a binary input. One hides flipped bits; the other marks missing bits. Their different channel capacities show why the whole transition matrix matters, as the flips versus erasures in a binary channel demonstrate.
Let the input alphabet be and let the output be , where independent noise is uniform on two distinct integers. Translating the output alphabet reduces the noise to , . The reachable output alphabet has size : it is the union of two three-element intervals shifted by .
For , every row of the transition matrix has conditional information entropy one bit, so . Input probabilities make the output uniform and attain one bit per use. For , the two translated input alphabets are disjoint and every output identifies its input. A uniform input then attains bits per use.
For , reflection symmetry and concavity of information entropy permit restricting to input probabilities . Conditional on output parity, outputs whose labels are even integers have probabilities and outputs whose labels are odd integers have probabilities . Consequently . Its strictly negative second derivative and stationary equation give and channel capacity . All three values follow from overlap of translated input alphabets, rather than from output alphabet size alone.
For deterministic block transmission without feedback, a channel encoder maps each message label to an input word of length over an alphabet . These words are the codewords of a block code. Distinct messages should have distinct codewords: if two labels give the same word, even a noiseless communication channel cannot tell them apart. The channel encoder may add redundancy, so the transmitted word can be longer than the message representation.
A deterministic channel decoder maps a received length- word over the output alphabet to an estimated message label. Given message , successful decoding means , where is the random received word after the communication channel acts on the channel encoder's word . The channel decoder can recover a message despite changed symbols because it uses the relationships among complete codewords. The Shannon second coding theorem concerns choosing both maps so that the decoding-error probability becomes small at a specified rate.
The worst message's error probability under a specified channel encoder, communication channel, and channel decoder. It upper-bounds the average error probability under every message probability distribution. In particular, a uniform bound on maximal decoding error probability remains valid after restricting to any nonempty subset of messages. This distinguishes it from an average-only error guarantee in channel coding.
A finite-alphabet erasure channel transmits the input symbol unchanged with probability and replaces it by a distinct erasure flag with probability , independently of the symbol. Given the flag, the posterior remains the input distribution; otherwise the input is known. Thus its mutual information is .
For a finite-alphabet erasure channel with input symbols, . Maximizing Shannon entropy at the uniform input gives channel capacity bits per use, by the Shannon second coding theorem.
A binary erasure channel transmits each input bit correctly with probability and replaces it by an erasure symbol with probability . Its channel capacity is bits per use.
With channel feedback, resend each message bit through a binary erasure channel until a non-erased copy arrives, then move to the next bit. The channel decoder deletes erasure symbols, giving the message without error whenever transmission completes. For , the waiting times have an independent and identically distributed geometric distribution with expectation , so every finite message completes almost surely. The strong law of large numbers gives forward code rate , matching channel capacity. At , transmission never completes. Independent erasure indicators, rather than independent message bits, are the essential hypothesis.
For a deterministic length- channel code with messages on a binary erasure channel of erasure probability , exclude the message decoded from the all-erased output. Under a uniform choice of the other messages, success probability is at least . Conditional on an erasure pattern with unerased positions, there are at most output words, so average success is at most . With no unerased positions it is zero.
Put . The scalar bound is immediate for . Otherwise set . Since for ,The inequality follows because equality holds at and the derivative of is for . Averaging the scalar bound over the number of unerased positions, with , proves the displayed claim. Thus implies code rate . The cases satisfy this rate bound directly.
Deterministic decoding is essential to this version: on an always-erased channel, a randomized uniform guess has maximal decoding error probability despite receiving no information. The usual deterministic channel decoder has maximal error one when on that channel.
A Z-channel transmits one binary input without error while the other can change into the first. Unlike a binary symmetric channel, its errors are one-sided.
For a discrete memoryless channel, operational capacity equalsRates below admit codes whose error tends to zero, while rates above cannot have vanishing error.
A rate is reliably achievable through a channel when there is a sequence of length- channel codes with messages such thatand their decoding-error probability tends to zero.
A binary linear-feedback shift register of degree updates a -bit state by shifting and inserting a fixed linear combination over . With recurrenceits feedback polynomial is .
Under the convention that a register emits each shifted-out symbol, its first output symbols are exactly its initial fill. Thus a binary register of length has distinct outputs from nonzero fills. For lengths , at least one longer-register output is absent from the shorter register, guaranteeing a pair of unequal nonzero outputs. The two sets need not be disjoint: recurrences and both generate constant ones. Nor must they intersect: the length-one recurrence and have no common nonzero output, since constant ones fail the second recurrence.
A feedback shift register updates a finite state by shifting its stored symbols and inserting the value of a feedback function of the previous state. The feedback function need not be linear.
The Berlekamp-Massey algorithm finds a shortest linear recurrence consistent with a finite sequence over a field. It returns a register length and a connection polynomial such thatMissing coefficients are zero; for a finite prefix the polynomial degree of can be less than . The output describes the shortest recurrence for the observed prefix, rather than proving how an unknown infinite sequence continues.
Initialize , , , and . At index , compute the discrepancy . If , increase by one. Otherwise save and replace by . If , also set , , , and ; if , only increase . The saved discrepancy cancels the current failure of the linear recurrence, while the update of accounts for the extra memory it requires.[ref]
Shift-Register Synthesis and BCH Decoding by James L. Massey. Sections II–III: register length, discrepancy, and synthesis algorithm
For the binary prefix , the result is and , corresponding to over the field with two elements. This is useful both in analyzing a linear-feedback shift register and in constructing a BCH code error-locator polynomial.
Suppose a connection polynomial of degree at most , with recurrence span gives zero recurrence discrepancies through index but a nonzero discrepancy at . If a polynomial of span successfully explains the prefix through and , evaluate the coefficient at in the convolution . Applying first makes it zero. Applying first leaves its nonzero discrepancy at , because the earlier discrepancies vanish and has constant coefficient one. This contradiction gives the displayed lower bound. It is the minimality step used by the Berlekamp-Massey algorithm; the algorithm cancels the new discrepancy with a shifted earlier failed polynomial.
The shortest binary linear recurrence producing the prefix has length three:Its connection polynomial is .
A degree- binary register has states. The zero state is fixed, so a nonzero periodic orbit has length at most .
For a binary linear-feedback shift register of length , a feedback polynomial with maximal period cannot have as a polynomial root. A root at would make the nonzero all-one state fixed, whereas maximal period requires all nonzero states to lie in one cycle of length greater than one.
Writing the monic polynomial as , this givesOver the field with two elements, an even number of the feedback coefficients must therefore equal one, and has an odd number of nonzero coefficients. This is a necessary condition, not a sufficient test for a primitive polynomial. The restriction matters: for , has maximal nonzero-state period despite having as a polynomial root.
If an output prefix contains consecutive zeros followed by a one, no register of degree at most can generate it: the all-zero state would have been reached and would remain zero forever.
The seven consecutive zeros followed by one force degree at least eight. Degree eight is attained by , with initial state and feedback polynomial .
Let , let generate , and let be nonzero linear with nondegenerate bilinear form . If the minimal polynomial of is , then satisfiesso it is produced by an LFSR of length at most . Its period is exactly : any period would imply for every , hence by nondegeneracy.
A linear code over a finite field is a linear subspace . Its parameters record word length, dimension, and minimum Hamming distance. For a nonzero code, is the least Hamming weight of a nonzero word, because the difference of two words is another word.
For example, is a binary code, the kernel of the parity-check matrix . Linearity lets a generator matrix encode messages and lets the parity-check syndrome detect corruption. The zero code needs a separate convention for its minimum distance, since it has no nonzero word.
Two linear codes are monomially equivalent if a permutation of coordinates followed by multiplication of individual coordinates by nonzero field elements takes one to the other. This preserves dimension and Hamming distance. Choosing different representatives for projective parity-check columns produces this equivalence.
A nonzero length-, dimension- linear code is maximum distance separable if its minimum Hamming distance equals , attaining the Singleton bound. Reed-Solomon codes and generalized Reed-Solomon codes provide examples because a nonzero polynomial of degree at most has at most distinct polynomial roots.
Let and let be distinct elements of a finite field . The Reed-Solomon code consists of evaluation vectors for polynomials of polynomial degree less than . It is a linear code with parameters and therefore a maximum distance separable code.
Indeed, evaluation is an injective linear map: a nonzero polynomial of polynomial degree at most cannot vanish at all evaluation points. The same polynomial root bound shows that every nonzero codeword has at least nonzero coordinates. Equality is attained by a polynomial vanishing at any chosen evaluation points. Thus the minimum Hamming distance is exactly , allowing correction of up to unknown symbol errors.
Primitive cyclic Reed-Solomon codes use all nonzero field elements, ordered as powers of a primitive root of unity. An arbitrary evaluation set need not give a cyclic code.
Let and let be a primitive root of unity in . The length- cyclic code with consecutive zeros of a cyclic code has dimension . It equals the generalized Reed-Solomon code of vectors , . The choice is the unweighted Reed-Solomon code on these evaluation points; allowing other offsets makes this family closed under dual codes.
With syndromes and distinct error-location values , form and the error locator polynomial . There is an error evaluator polynomial of degree less than the number of errors satisfying the key equation. When the number of errors is at most , the Berlekamp-Massey algorithm or extended Euclidean algorithm recovers these polynomials, normalized by .
For and , the two evaluation forms are and , with and . Their dot product is , since every appearing exponent is between one and and the sums of those powers of vanish. Comparing dimensions proves equality with the dual code. In particular, the dual of the unweighted evaluation code has multipliers ; it need not be an unweighted evaluation code on the same ordered points.
For , choose distinct evaluation points in a finite field and nonzero coordinate multipliers . The generalized Reed-Solomon code isMultiplying coordinates by nonzero field elements preserves Hamming weight, so this is a linear code with parameters , just as for a Reed-Solomon code. In particular it is a maximum distance separable code.
Its dual code is , where one may takeA common nonzero multiplier on all gives the same dual code. For the dual code is the zero code, interpreted as having no nonzero evaluation polynomials.
Articles were limited to the first 100 out of 223 total.
Articles by others on the same topic


Coding theory is a branch of mathematics and computer science that focuses on the design and analysis of error-correcting codes for data transmission and storage. The primary goals of coding theory are to ensure reliable communication over noisy channels and to efficiently store data. Here are some key concepts and components of coding theory: 1. **Error Detection and Correction**: Coding theory provides methods to detect and correct errors that may occur during the transmission or storage of data.