Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Vector space
Lie algebra Created 2026-09-24 Updated 2026-10-14
A Lie algebra over a field is a vector space with a bilinear map , called the Lie bracket, that is alternating and satisfies the Jacobi identity. Explicitly, for all ,This definition applies in every characteristic of a field, including characteristic two; the distinction between an Alternating Lie bracket and antisymmetry of a Lie bracket matters there. See Pavel Etingof, Lie Groups and Lie Algebras, Definition 8.4 and Remark 8.5.
The motivating question is how to describe very small symmetries. For a real Matrix Lie group , the Lie algebra of a matrix Lie group is its tangent space at the identity element. An element specifies the initial velocity of the one-parameter subgroup , using the matrix exponential. The Lie bracket records the first nonzero effect of changing the order of two small transformations. Even when first-order motions cancel, a second-order motion can remain: the small rotation commutator below leaves a rotation about a third axis.
This turns local symmetry questions into computations with linear maps. A basis and its structure constants of a Lie algebra determine every Lie bracket by bilinearity. For example, three matrices suffice for the sl2 matrix commutator example, while the familiar cross product describes the SO(3) Lie algebra. These descriptions help calculate rotations in three dimensions and build Lie algebra representations; the same bracket structure underlies angular momentum commutation relations. The striking feature is that a nonlinear family of motions has a local description by a vector space and one product. Global information still needs care: the Lie algebra alone does not distinguish the circle group from the additive real line.
Historically, the connection with differential equations is visible in Sophus Lie's Theorie der Transformationsgruppen, volume I (1888), prepared with Friedrich Engel. Chapter 6 interprets first-order differential operators as infinitesimal transformations, linking their action on functions to the transformations those functions admit. See Lie and Engel, Chapter 6, §27, in Joël Merker's English translation; the original volume is available at the [ref]
https://gdz.sub.uni-goettingen.de/id/PPN585383391. Göttingen digitization
. Lie algebra representation Created 2026-09-24 Updated 2026-10-06
Linear algebra Created 2026-09-24 Updated 2026-10-13
Linear algebra studies vector spaces and linear maps: operations that preserve vector addition and scalar multiplication. For a linear map , the defining rule is , where are vectors and belong to the underlying field. The vectors might be arrows, lists of measurements, or polynomials. What matters is that their linear combinations make sense and that the same rule governs their transformation.
A concrete linear map is . Its two outputs record a sum and a difference. Since and , we immediately obtain . Knowing the outputs of the basis vectors determines the output of every vector; a matrix stores exactly that information in its columns.
The attraction of linear algebra is that one small collection of ideas answers several different questions. A system of linear equations asks which inputs produce a prescribed output. The image of a linear map describes the attainable outputs, while the kernel describes the invisible input changes. A basis gives every vector an address, and change of basis lets us choose addresses that make a linear map easier to understand. This shared language turns a collection of separate calculations into a picture of what is possible and how much freedom remains. Gilbert Strang's MIT course emphasizes these connections and their usefulness across other disciplines.[ref]
https://ocw.mit.edu/courses/18-06-linear-algebra-spring-2010/. Strang, MIT 18.06: Linear Algebra
Linear combination Created 2026-09-24 Updated 2026-10-14
Let be a vector space over a specified field , and let . A linear combination is a finite sumThe coefficients are scalars from that same field; each term uses scalar multiplication, and the terms are joined by vector addition. For coefficients in the real numbers, negative values reverse arrows and fractional values scale them by fractional amounts. The collection of attainable vectors is the linear span. The column picture in Strang's MIT notes interprets solving a linear system as choosing coefficients to reach a target vector.[ref]
https://ocw.mit.edu/courses/18-06sc-linear-algebra-fall-2011/6913aa2f37dada8fdda334168b30339b_MIT18_06SCF11_Ses1.1sum.pdf. MIT 18.06SC, Strang lecture summary 1, pp. 2–3: the column picture
For a concrete calculation over the real numbers, takeThen . More generally, solving and givesEvery vector in the Euclidean plane is therefore a linear combination of , so their linear span is all of . The target has coefficients ; the target has coefficients , since . The displayed formula also makes the coefficients unique. Consequently is an ordered basis, with coordinate vector .
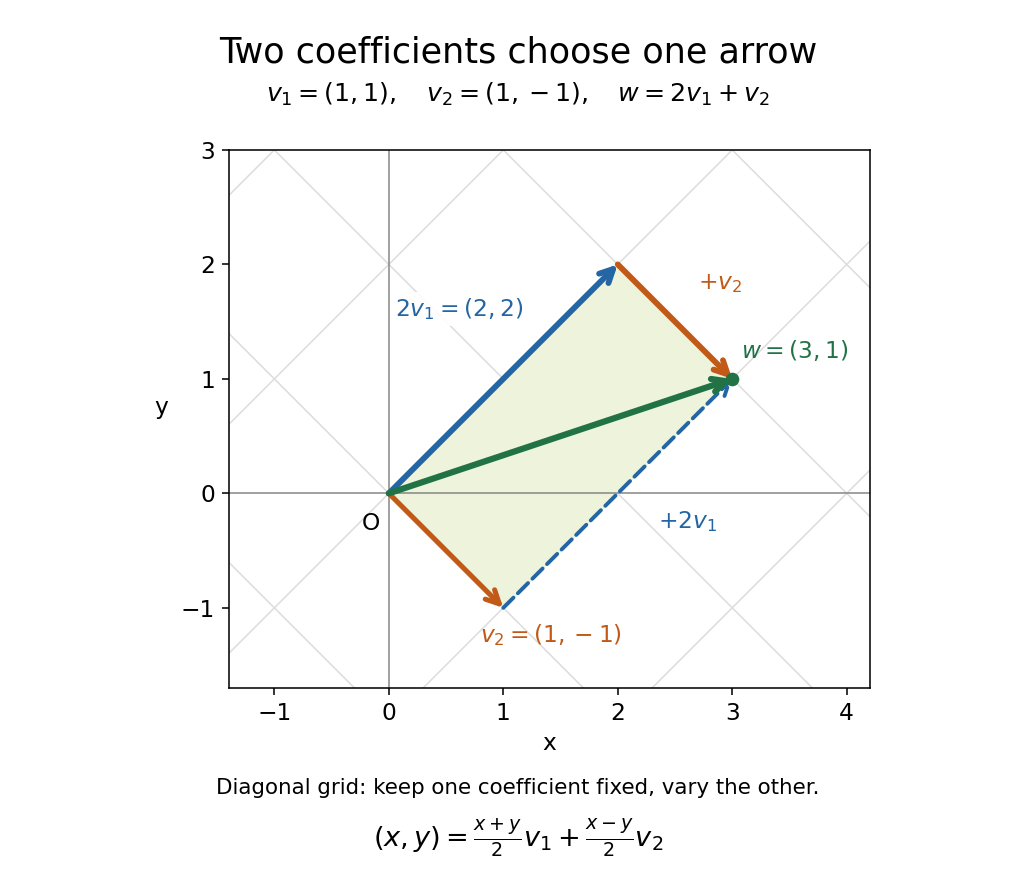
The payoff is a reusable language for synthesis: linear combinations build vectors from chosen ingredients, linear span decides which targets are reachable, and linear independence decides whether the coefficients are unique. The ingredients can also be polynomials or functions, as long as they belong to a vector space over the specified field.
Linear dependence Created 2026-09-24 Updated 2026-10-14
A finite family of vectors in a vector space over a specified field is linearly dependent if it has a nontrivial linear relation: with and at least one coefficient nonzero. One can then solve for a vector whose coefficient is nonzero as a linear combination of the others; removing that entry preserves the linear span. Repeated vectors in a list give linear dependence: for example has the linear relation . A list keeps both entries even though the set has only one element. Strang's notes illustrate redundant columns by expressing one as the sum of two others.[ref]
https://ocw.mit.edu/courses/18-06sc-linear-algebra-fall-2011/0bbc30e3f1d7933ea07a2d2e9ab050d9_MIT18_06SCF11_Ses1.9sum.pdf. MIT 18.06SC, Strang lecture summary 9, pp. 2–3: dependent columns
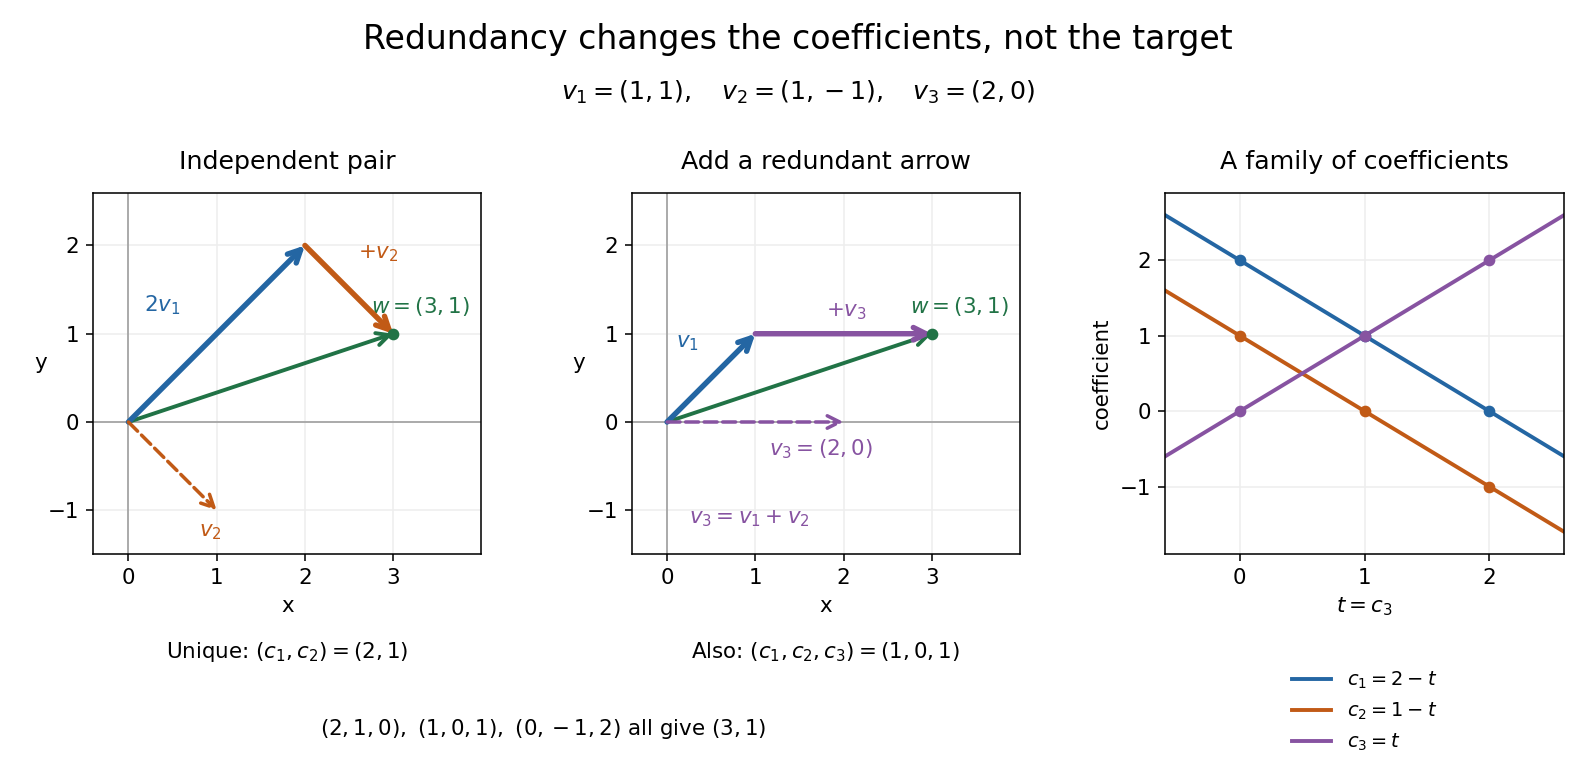
Keep and , and add . The three vectors still have linear span , but nowThe two coefficient triples and differ by the nontrivial linear relation . In fact all linear combination representations of this target areTo check both completeness and correctness, use . Linear independence of forces and , giving exactly the displayed family. Redundancy therefore preserves attainable targets while allowing their coefficients to move. For solving a linear system, these alternatives matter; for assigning unique coordinate vectors, one instead chooses a basis.
The following example shows why linear independence depends on the scalar field.
Linear differential equation Created 2026-09-24 Updated 2026-10-14
A scalar linear differential equation of order has the formHere the coefficients and the forcing term are prescribed functions of the independent variable . A classical solution of a differential equation is an -times differentiable function satisfying the identity at every point of its interval. The unknown function and its derivatives enter to the first power, without products between them or coefficients depending on . Equivalently, the differential operator is a linear map: for constant scalars ,The forcing term may be zero, giving a homogeneous linear differential equation, or nonzero, giving an inhomogeneous linear differential equation. Linearity of does not mean that every function graph of a solution of a differential equation is a straight line.
To use the usual order- initial value problem theory on an interval , assume that throughout and that all and are continuous functions there. Dividing by normalizes the highest derivative; specifying at then selects one solution of a differential equation throughout . A zero of needs separate analysis: one cannot divide through it and retain these conclusions. The first-order normalization appears in OpenStax's definition and standard form of linear equations; the corresponding system theorem is in MIT's existence and uniqueness notes for linear systems.
The coefficients need not be linear functions of . For example, is a linear differential equation on , although is quadratic. Its solution of a differential equation with initial condition is : its derivative is , so substitution gives , and . The zero of the highest coefficient at explains the domain restriction. In contrast, , and are nonlinear ordinary differential equations because of their dependence on the unknown function. Variable coefficients and nonlinear ordinary differential equations are different issues; see MIT's definitions and examples of first-order linear equations.
The practical benefit of linearity is that it separates the effect of the initial condition from the effect of the forcing term. Once one particular solution satisfies , every solution of a differential equation isHere is the kernel of a linear map, consisting of solutions of a differential equation to the associated homogeneous linear differential equation. Indeed, , and conversely . Thus the family for a fixed forcing term is an affine space obtained by translating . If is not identically zero, the zero function is absent, so this family is not a vector space under the usual operations on functions. This short argument explains why a general solution is a particular solution plus a homogeneous solution.
Linear endomorphism 2026-10-14
A linear endomorphism is a linear map from a vector space to itself. In a finite-dimensional basis it is represented by a square matrix. It need not be invertible; an invertible linear endomorphism is an automorphism of the vector space.
Linear functional Created 2026-09-24 Updated 2026-10-14
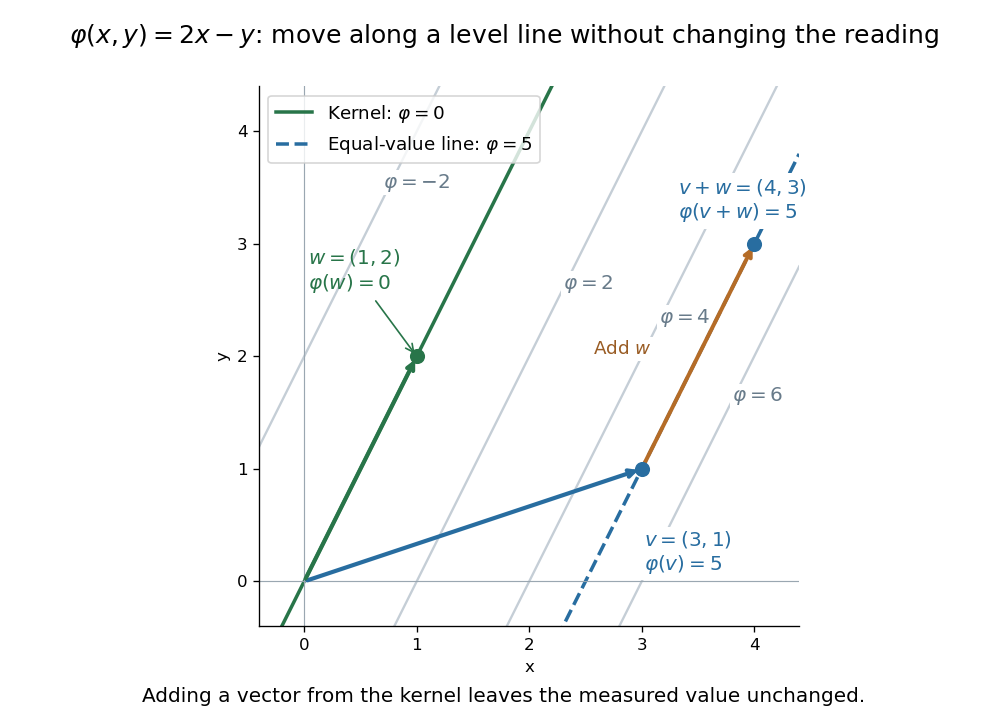
A linear functional is a linear map from a vector space to its scalar field :Its output is one scalar, rather than an arbitrary vector in another space. In , gives , , and : adding the two inputs adds their measured values.
The level sets visualize what the measurement retains and discards. For this example they are parallel straight lines . Moving parallel to changes the input but leaves unchanged. The zero level set is its kernel of a linear map, while the other level sets are translates of that vector subspace.
Inputs need not be geometric arrows. On the vector space of polynomials of polynomial degree at most two, evaluating at zero is a linear functional, as is taking the definite integral from zero to one. For , they give and . Thus polynomial evaluation and integration are two different measurements of the same polynomial. Coordinate extraction is another measurement, developed under dual basis.
A linear functional is defined by linearity, not by continuity. In finite-dimensional real or complex normed vector spaces it is automatically continuous; in infinite dimension it need not be. The continuous dual space adds this requirement when small changes in the input should give small changes in the output.
Linear independence Created 2026-09-24 Updated 2026-10-14
In a vector space over a specified field , a finite family of vectors is linearly independent when, for coefficients ,Here the left-hand zero is the zero vector, while the right-hand zeros belong to the field . Thus linear independence excludes every nontrivial linear relation. For an infinite family, require this condition for every finite subfamily.[ref]
https://ocw.mit.edu/courses/18-06sc-linear-algebra-fall-2011/0bbc30e3f1d7933ea07a2d2e9ab050d9_MIT18_06SCF11_Ses1.9sum.pdf. MIT 18.06SC, Strang lecture summary 9, p. 1: linear independence
For and over the real numbers, the linear relation gives and . Adding and subtracting yields , hence . This verifies linear independence directly and explains why the linear combination giving has exactly the coefficients .
A linearly independent family cannot contain the zero vector: a coefficient of on that entry and on every other entry would be a nontrivial linear relation. The empty family is linearly independent, because its empty sum is the zero vector and there are no coefficients that could be nonzero. Linear independence identifies a collection without redundant vectors; combined with a spanning set, it gives a basis. The uniqueness of linear combination coefficients makes its representations unambiguous.
Linear matroid 2026-10-14
A linear matroid has a finite ground set indexing a family of vectors in a vector space over a specified field. A subset of labels is a matroid independent set precisely when its vectors are linearly independent. Labels distinguish repeated vectors; the ground set is not required to consist of distinct numerical vectors. The matroid bases correspond to bases for the linear span of all the supplied vectors.
Exchange outline. The linear span of linearly independent vectors has dimension . If , not all the linearly independent vectors indexed by can lie in that linear span. A vector outside it can be added to . Heredity follows because a linear dependence in a subset would also be a linear dependence in the full selection.
Linear operator Created 2026-09-24 Updated 2026-10-03
Linear space (geometry) 2026-10-14
A linear space is a structure in incidence geometry with a set of points and a collection of subsets called lines: any two distinct points lie on exactly one line, and every line contains at least two points. The lines here are incidence-theoretic objects, without a required coordinate realization. A finite linear space imposes finiteness; its nontrivial form excludes a line containing all points. This is distinct from a vector space, whose structure involves addition and scalar multiplication.
Linear span Created 2026-09-24 Updated 2026-10-14
The linear span of a subset of a vector space is the set of all finite linear combinations of elements of . It is the smallest vector subspace containing : every vector subspace containing the original vectors must contain their sums and scalar multiples.
In , the linear span of is a line, the linear span of is the plane , and adding gives all of . Adding to the first set changes none of its attainable vectors, because it is already a scalar multiple of . Thus a spanning set can contain redundant generators; linear independence identifies when this redundancy is absent. In an infinite-dimensional space, an algebraic linear span still uses finite sums; a closed linear span can also include limits in a specified norm.
Mathematics Created 2026-09-24 Updated 2026-10-14
Mathematics studies patterns in quantity, structure, space, and change by giving objects precise mathematical definitions and examining what follows from them. Arithmetic starts with operations on numbers; algebra organizes relations and transformations; geometry and topology studies shapes and the structures preserved by maps; analysis studies limits and continuous change. These fields connect because the same structure can appear in different forms.
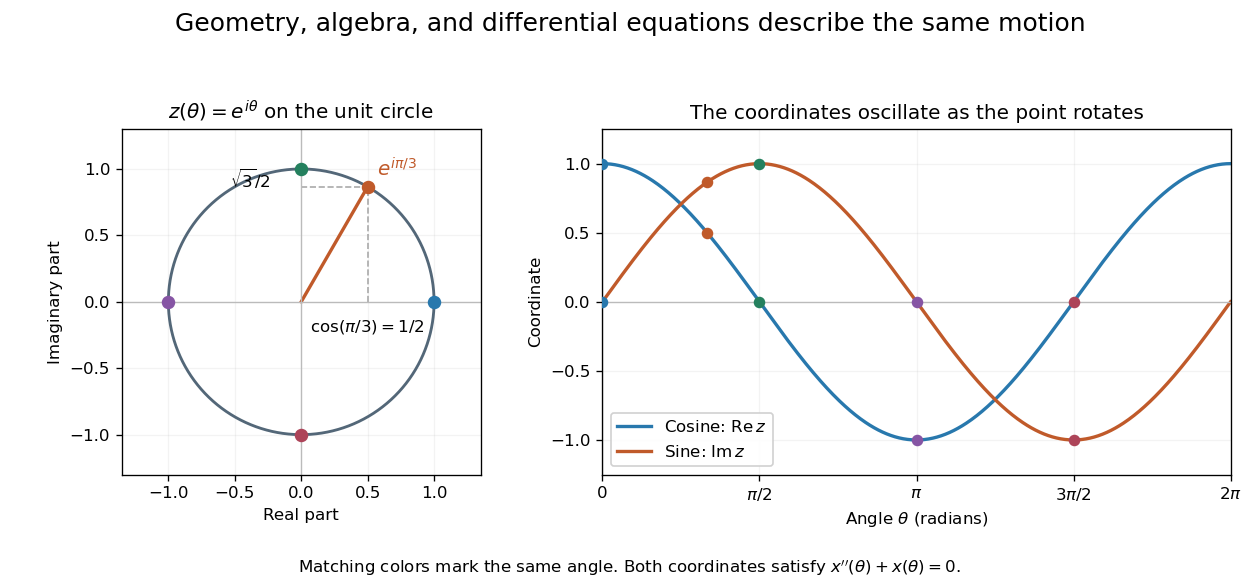
A small example shows the value of changing viewpoint. A point moving around the unit circle has coordinates , . Regard the plane as complex numbers and the same point is , by Euler's formula. Adding two angles now corresponds to multiplying their complex exponentials: . A geometric rotation has become an algebraic operation.
The connection reaches calculus too. Differentiating twice gives and , so the two coordinates solve the harmonic oscillator equation. At angle , ; one point supplies an exact cosine, an exact sine, and the state of an oscillation. The Pythagorean trigonometric identity records that the modulus stays one. Seeing these as descriptions of one object makes each formula easier to remember and reuse.


This is why a useful mathematical explanation provides both a reliable mathematical proof and a way to see what the result is doing. In his 1994 essay, William Thurston discusses mathematical progress in terms of advancing understanding, and uses the many interpretations of a derivative to illustrate this aim. [ref] A diagram, a computed example, and a concise argument can make different parts of the same idea accessible.
Applications ask us to select a mathematical model of a physical or other system. Its assumptions determine which conclusions transfer to that system. Within mathematics, the same practice of making assumptions explicit lets a result about groups, vector spaces, or probability distributions apply to many concrete examples. The beauty is the combination of precision and reuse: an argument can reveal more than the particular case that first suggested it.
Matrix norm 2026-10-14
A matrix norm is a norm on a vector space of matrices; common choices include induced operator norms and the Frobenius norm. A submultiplicative matrix norm additionally satisfies . The matrix 2-norm is the norm induced by Euclidean norms and equals the largest singular value.
Matrix trace Created 2026-09-24 Updated 2026-10-14
For an -by- square matrix over a field, its matrix trace is the sum of its diagonal entries:For example, has trace . Adding corresponding diagonal entries immediately proves linearity:Thus matrix trace is a linear functional on the vector space of -by- matrices.[ref]
Linear Algebra Done Right by Sheldon Axler (4th edition). Axler, Linear Algebra Done Right, fourth edition, §8D, definition 8.47 and result 8.56
The surprising point is that the sum is intrinsic to a linear operator, even though individual diagonal entries depend on the basis. The cyclic property of the trace gives, for any invertible matrix ,Hence matrix similarity preserves trace. For the example above, choose the change-of-basis matrix . ThenThe diagonal entries have changed but their sum has not. This makes trace useful for extracting a feature of the underlying linear operator without finding a preferred basis.
Over the complex numbers, or over the real numbers after allowing complex eigenvalues, the trace equals their sum with algebraic multiplicity:No diagonalizable matrix hypothesis is needed.[ref]
Linear Algebra Done Right by Sheldon Axler (4th edition). Axler, Linear Algebra Done Right, fourth edition, §8D, results 8.50–8.52
To see why, use triangularization over an algebraically closed field: an upper triangular matrix similar to has the eigenvalues on its diagonal, counted with algebraic multiplicity, because its characteristic polynomial is . Similarity preserves trace, so summing that diagonal proves the formula.For instance,There is only one independent eigenvector, since , so is not a diagonalizable matrix. Nevertheless its repeated eigenvalue contributes twice. For our earlier , the characteristic polynomial is , its eigenvalues are and , and their sum is . An inexpensive diagonal sum therefore gives spectral information before solving the characteristic polynomial.
The trace of a real matrix does not give that linear map's volume factor: that factor is the absolute value of its determinant. For example, has trace and area factor , but has trace and volume factor . Their occasional numerical agreement in two dimensions is a coincidence. The connection between trace and local volume change gives a geometric interpretation near the identity matrix, and describes the volume rate of a flow map generated by a linear system of differential equations.
Matrix unit Created 2026-09-24 Updated 2026-09-24
The matrix unit has entry one in row , column , and zero in every other position. The matrix units form the standard basis of the vector space of matrices of a fixed size.